

The release of version 0.9.0 of the library for C++ (C++20 standard) has taken place. libunicode. The project is being developed by a team of terminal emulator developers. Contour and shell Endo (under active development), and is distributed under the Apache 2.0 license.
- support for standards Unicode 17.0:
- API for obtaining Unicode properties;
- SIMD optimization of certain functions (using std::simd or std::experimental::simd if available);
- optimized conversion UTF-8 UTF-16/UTF-32;
- equivalent to the wcwidth function (int unicode::width(char32_t));
- text segmentation by graphemes, characters, emojis, and scripts;
- case conversion and string comparison;
- high-level API for text segmentation suitable for implementation text shaping.
- test coverage for most capabilities of the library (character width and segmentation).
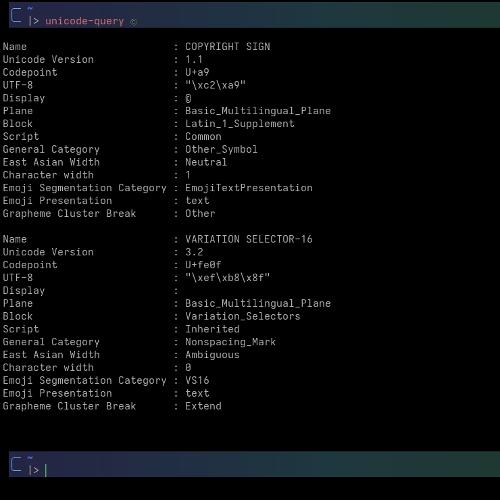
Also included is the console utility unicode-query for detailed information about strings.
Changes:
- added grapheme_cluster_width API;
- enhancements in working with Unicode versions ("Age");
- full support UAX #15 Unicode Normalization Forms with support for streaming processing:
normalizer norm(Normalization_Form::NFC); // Feed decomposed e + combining acute, then a new starter to trigger emission auto result = norm.feed(U’e’); CHECK(result.empty()); // still buffering result = norm.feed(U’u0301′); CHECK(result.empty()); // still buffering (combining mark) result = norm.feed(U’x’); // starter triggers emission of previous segment REQUIRE_FALSE(result.empty()); CHECK(result == U"u00E9"); // e + acute composed to e-acute result = norm.flush(); CHECK(result == U"x"); // final segment
- the script_extensions function now returns std::optional<std::span>;
- implemented GB9c rule for grapheme group breaking for character combinations in Indic languages;
- in grapheme_segmenter corrected rules for GB11 and GB4/GB5; deprecated API removed;
- implemented SIMD-optimized conversion from UTF-8 to UTF-16/UTF-32;
- the width of Hangul V/T combining characters is now zero;
- implemented word boundary segmentation;
- fixes in the C API;
- refactored the build system and auxiliary table generator for C++;
- added comprehensive tests for UTF-16/UTF-32 conversion;
- static build of the unicode-query utility added in CI.
Source: linux.org.ru
