

Why is it necessary to make backups? After all, hardware is quite reliable, and there are also 'clouds' that are more reliable than physical servers: with the right configuration, a 'cloud' server can easily withstand the failure of a physical infrastructure server, and from the users' perspective, there will be a small, barely noticeable increase in service time. Moreover, duplicating information often incurs costs for 'extra' CPU time, disk load, and network traffic.
The perfect program works quickly, does not leak memory, has no vulnerabilities, and does not exist.
—Unknown
Since programs are still being written by human developers, and the testing process is often absent, plus software is rarely delivered using 'best practices' (which are themselves programs and thus imperfect), system administrators frequently have to tackle tasks that are succinct but loaded: 'restore to previous state', 'bring the database to normal operation', 'it's running slowly – we roll back', and my favorite, 'I don't know what, but fix it.'
In addition to logical errors that arise from careless work by developers or unfortunate circumstances, as well as incomplete knowledge or understanding of the subtle details of software construction – including linking and system components, such as operating systems, drivers, and firmware – there are also other errors. For example, most developers rely on runtime, completely forgetting about the physical laws that cannot yet be circumvented through programming. This includes the infinite reliability of the disk subsystem and any storage subsystem (including RAM and CPU cache!), zero processing time on the CPU, no errors during network transmission and processing on the CPU, and network delays that equal zero. One should not neglect the infamous deadline, as failing to meet it can lead to issues that are cleaner than the nuances of network and disk operations.
How do we deal with problems that loom large over valuable data? Living developers cannot be replaced, and there's no guarantee that it will be possible to do so in the near future. On the other hand, so far only a few projects have been able to completely prove that a program will work as intended, and it’s far from certain that evidence can be readily applied to other similar projects. Additionally, such proofs take a significant amount of time and require specific skills and knowledge, which practically minimizes the chance of their application given tight deadlines. Moreover, we still do not possess ultra-fast, inexpensive, and infinitely reliable technologies for storing, processing, and transmitting information. Such technologies, if they exist, are often found only in the form of concepts or, more frequently, exclusively in science fiction books and movies.
Good artists copy; great artists steal.
—Pablo Picasso.
The most successful solutions and surprisingly simple things usually occur where absolutely incompatible concepts, technologies, knowledge, and fields of science meet at first glance.
For instance, birds and airplanes both have wings; however, despite functional similarities — the principles of operation coincide in certain regimes, and technical problems are solved similarly: hollow bones, use of strong and lightweight materials, etc. — the results are absolutely different, even though they are quite similar. The best examples we observe in our technology are largely borrowed from nature: airtight compartments in ships and submarines are a direct analogy to segmented worms; RAID arrays and data integrity checks resemble the duplication of DNA sequences; as well as paired organs, the independence of different organs from the Central Nervous System (the automated functioning of the heart), and reflexes — autonomous systems in the Internet. Of course, taking and applying ready-made solutions directly is fraught with problems, but who knows, there may be no other solutions.
If only I knew where I'd fall — I would have laid down some straw!
—Belarusian folk proverb
This means that backups are critically necessary for those who wish to:
- Have the ability to restore their systems with minimal downtime, or even without it at all.
- Act boldly, because in case of an error, there is always the option to roll back.
- Minimize the consequences of intentional data corruption.
Here is a bit of theory.
Any classification is arbitrary. Nature does not classify. We classify because it is more convenient for us, using data that we also take arbitrarily.
—Jean Bruler
Regardless of the physical method of storage, logical data storage can conditionally be divided into two ways to access this data: block and file. Such a division has become rather blurred lately, as there are no purely block or purely file logical storages. However, for simplicity, we will consider that they exist.
Block data storage implies that there is a physical device where data is written in fixed portions, called blocks. Access to blocks is done by a certain address, with each block corresponding to its own address within the device.
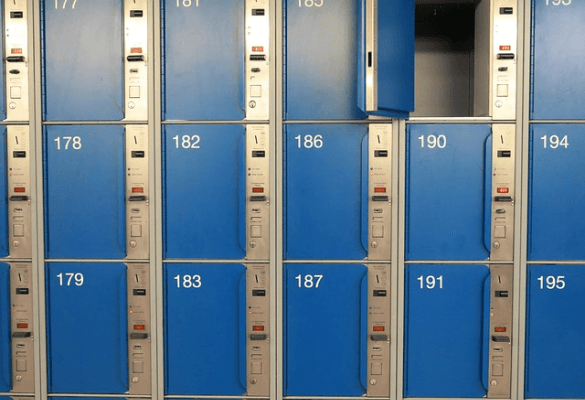
A backup is usually made by copying blocks of data. To ensure data integrity at the time of copying, the recording of new blocks is paused, as well as modification of existing ones. An analogy from the ordinary world would be a cabinet with uniformly numbered compartments.
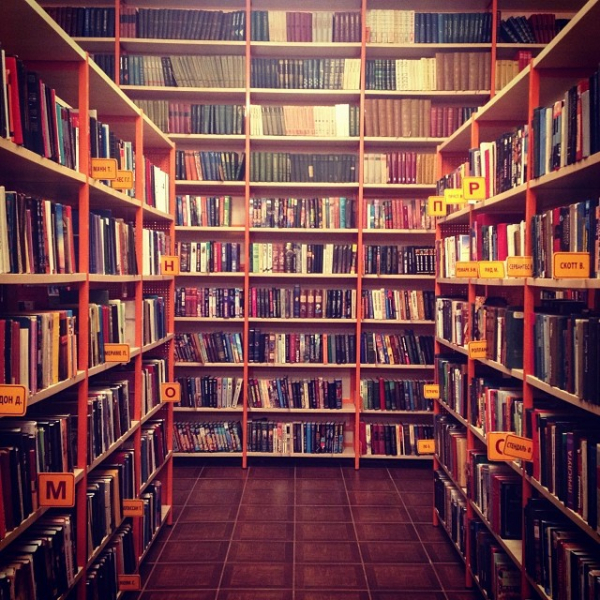
File data storage, as a logical device, is close to block storage and is often organized on top of it. Important differences include the presence of a storage hierarchy and human-readable names. There is an abstraction in the form of a file—a named area of data—as well as a directory—a special file that contains descriptions and access to other files. Files may be supplemented with additional metadata: creation time, access flags, etc. Typically, backups are performed by searching for modified files, then copying them to another file storage with the same structure. Data integrity is usually realized by not having files that are being written to. File metadata is backed up similarly. The closest analogy is a library that has sections with different books, along with a catalog containing human-readable names of the books.
Recently, another option has been described, which essentially marks the beginning of data file storage and shares the same archaic features: object storage.
It differs from file storage in that it does not have more than one level of nesting (a flat schema), and while file names are human-readable, they are primarily optimized for machine processing. When backing up, object storage is often handled similarly to file storage, although there are occasional alternatives.
— There are two types of system administrators: those who do not make backups and those who ALREADY do.
— In fact, there are three types: there are also those who verify that backups can be restored.—Unknown
It is also important to understand that the backup process itself is carried out by programs, so it shares all the same drawbacks as other software. To mitigate (not eliminate!) the dependence on human factors, as well as on specifics that may not significantly affect individually but can collectively have a noticeable impact, the so-called 3-2-1 rule is applied. There are many interpretations of this rule, but I prefer the following explanation: you should store 3 sets of the same data, 2 sets need to be stored in different formats, and 1 set should be kept at a geographically remote location.
Storage format should be understood as follows:
- If there is a dependence on the physical storage method, we change the physical method.
- If there is a dependence on the logical storage method, we change the logical method.
To achieve the maximum effect of the 3-2-1 rule, it is recommended to change the storage format using both methods.
From the perspective of backup readiness for its intended purpose—restoring functionality—there are "hot" and "cold" backups. Hot backups differ from cold backups in only one way: they are immediately ready for use, whereas cold backups require additional actions for restoration, such as decryption, extraction from an archive, etc.
It is important not to confuse hot and cold copies with online and offline copies, which imply physical data isolation and are essentially a different classification of backup methods. An offline copy—one that is not directly connected to the system where it needs to be restored—can be either hot or cold (in terms of readiness for recovery). An online copy may be directly accessible where it needs to be restored and is most often hot, though cold copies can also occur.
Furthermore, it should not be forgotten that the backup creation process typically does not end with just a single backup; there may be a considerable number of copies. Therefore, it is necessary to distinguish between full backups, which can be restored independently of other backups, and differential (incremental, differential, decremental, etc.) copies—those that cannot be restored on their own and require prior restoration of one or more other backups.
Differential incremental copies attempt to save storage space for backups. Thus, only the modified data since the last backup is written into the backup.
Differential decremental copies are created for the same purpose but in a slightly different way: a full backup is made, but only the difference between the fresh copy and the previous one is actually stored.
It is worth examining the backup process over a storage solution that supports deduplication. Thus, when creating full backups over it, only the differences between backups will be actually recorded; however, the restoration process will occur similarly to restoring from a full copy and will be completely transparent.
Quis custodiet ipsos custodes?
(Who watches the watchers? — Latin)
It is quite unpleasant when there are no backups, but it is even worse if a backup seems to have been made, yet it turns out during restoration that it cannot be restored because:
- The integrity of the original data has been compromised.
- The storage with backups is damaged.
- Recovery works rather slowly, and data that has been partially restored cannot be used.
A properly constructed backup process must take such remarks into account, especially the first two.
The integrity of the original data can be guaranteed in several ways. The most commonly used methods are: a) snapshots of the file system at the block level, b) 'freezing' the state of the file system, c) special block devices with versioning, d) sequential writing of files or blocks. Checksums are also used to verify data during recovery.
Storage damage can also be detected using checksums. An additional method is the use of specialized devices or file systems where written data cannot be altered, but new data can still be appended.
To speed up recovery, data restoration is performed with multiple processes, provided there is no bottleneck in the form of a slow network or a sluggish disk system. To address the issue of partially restored data, the backup process can be divided into relatively small subtasks, each of which is executed separately. This way, it becomes possible to restore functionality sequentially while predicting recovery time. This issue often lies in the organizational aspect (SLA), so we won’t dwell on it in detail.
The one who knows how to use spices is not the one who adds them to every dish, but the one who never adds anything unnecessary.
—V. Sinyavsky
The practice regarding the software used by system administrators can vary, but the general principles are still the same, in particular:
- It is strongly recommended to use ready-made solutions.
- Programs should work predictably, meaning there should be no undocumented features or bottlenecks.
- The configuration of each program should be simple enough that it doesn't require reading the manual or a cheat sheet every time.
- The solution should ideally be universal, as servers can vary greatly in their hardware characteristics.
For backing up block devices, the following common programs are available:
- dd, known to veterans of system administration, along with similar programs (such as dd_rescue, for example).
- Utilities embedded in certain file systems that create a snapshot (dump) of the file system.
- Versatile utilities; for example, partclone.
- Proprietary solutions, often private, such as NortonGhost and its later versions.
For file systems, the backup task can be partially addressed with methods applicable to block devices; however, it can also be solved more effectively by using:
- Rsync, a versatile program and protocol for synchronizing the state of file systems.
- Built-in archiving tools (ZFS).
- Third-party archiving tools; the most popular is tar. There are others, such as dar — a replacement for tar focused on modern systems.
It's worth mentioning software tools that ensure data consistency when creating backups. The following options are often used:
- Mounting the file system in read-only mode (ReadOnly) or freezing the file system (freeze) — this method has limited applicability.
- Creating snapshots of the file system or block device (LVM, ZFS).
- Using third-party tools for snapshot organization, even in cases where the previous points cannot be fulfilled for any reason (hotcopy-type programs).
- Copy-on-write techniques, although they are most often tied to the used FS (BTRFS, ZFS).
Therefore, for a small server, it's essential to ensure a backup scheme that meets the following requirements:
- Easy to use — it requires no special additional actions during operation, with minimal steps for creating and restoring copies.
- Universal — works on both large and small servers; this is important as the number of servers grows servers or during scaling.
- Installed via a package manager, or with one or two commands like 'download and unpack'.
- Stable – uses a standard or long-established storage format.
- Fast in operation.
Candidates that meet the requirements reasonably well:
- rdiff-backup
- rsnapshot
- burp
- duplicati
- duplicity
- deja dup
- dar
- zbackup
- restic
- borgbackup
A virtual machine (based on XenServer) will be used as a test stand with the following specifications:
- 4 cores at 2.5 GHz,
- 16 GB of RAM,
- 50 GB hybrid storage (storage area network with 20% SSD caching of virtual disk size) as a separate virtual disk without partitioning,
- 200 Mbps internet channel.
The backup server will use a virtually identical machine, but with a 500 GB hard drive.
Operating system – CentOS 7 x64: standard partitioning, an additional partition will be used as a data source.
The source data will be a WordPress site with media files totaling 40 GB and a MySQL database. Since virtual servers specifications can vary quite significantly, and for better reproducibility, here are
the server test results using sysbench.sysbench –threads=4 –time=30 –cpu-max-prime=20000 cpu run
sysbench 1.1.0-18a9f86 (using bundled LuaJIT 2.1.0-beta3)
Running the test with the following options:
Number of threads: 4
Initializing random number generator from current time
Prime numbers limit: 20000
Initializing worker threads…
Threads started!
CPU speed:
events per second: 836.69
Throughput:
events/s (eps): 836.6908
time elapsed: 30.0039s
total number of events: 25104
Latency (ms):
min: 2.38
avg: 4.78
max: 22.39
95th percentile: 10.46
sum: 119923.64
Threads fairness:
events (avg/stddev): 6276.0000/13.91
execution time (avg/stddev): 29.9809/0.01
sysbench –threads=4 –time=30 –memory-block-size=1K –memory-scope=global –memory-total-size=100G –memory-oper=read memory run
sysbench 1.1.0-18a9f86 (using bundled LuaJIT 2.1.0-beta3)
Running the test with the following options:
Number of threads: 4
Initializing random number generator from current time
Running memory speed test with the following options:
block size: 1KiB
total size: 102400MiB
operation: read
scope: global
Initializing worker threads…
Threads started!
Total operations: 50900446 (1696677.10 per second)
49707.47 MiB transferred (1656.91 MiB/sec)
Throughput:
events/s (eps): 1696677.1017
time elapsed: 30.0001s
total number of events: 50900446
Latency (ms):
min: 0.00
avg: 0.00
max: 24.01
95th percentile: 0.00
sum: 39106.74
Threads fairness:
events (avg/stddev): 12725111.5000/137775.15
execution time (avg/stddev): 9.7767/0.10
sysbench –threads=4 –time=30 –memory-block-size=1K –memory-scope=global –memory-total-size=100G –memory-oper=write memory run
sysbench 1.1.0-18a9f86 (using bundled LuaJIT 2.1.0-beta3)
Running the test with the following options:
Number of threads: 4
Initializing random number generator from current time
Running memory speed test with the following options:
block size: 1KiB
total size: 102400MiB
operation: write
scope: global
Initializing worker threads…
Threads started!
Total operations: 35910413 (1197008.62 per second)
35068.76 MiB transferred (1168.95 MiB/sec)
Throughput:
events/s (eps): 1197008.6179
time elapsed: 30.0001s
total number of events: 35910413
Latency (ms):
min: 0.00
avg: 0.00
max: 16.90
95th percentile: 0.00
sum: 43604.83
Threads fairness:
events (avg/stddev): 8977603.2500/233905.84
execution time (avg/stddev): 10.9012/0.41
sysbench –threads=4 –file-test-mode=rndrw –time=60 –file-block-size=4K –file-total-size=1G fileio run
sysbench 1.1.0-18a9f86 (using bundled LuaJIT 2.1.0-beta3)
Running the test with the following options:
Number of threads: 4
Initializing random number generator from current time
Extra file open flags: (none)
128 files, 8MiB each
1GiB total file size
Block size 4KiB
Number of IO requests: 0
Read/Write ratio for combined random IO test: 1.50
Periodic FSYNC enabled, calling fsync() each 100 requests.
Calling fsync() at the end of test, Enabled.
Using synchronous I/O mode
Doing random r/w test
Initializing worker threads…
Threads started!
Throughput:
read: IOPS=3868.21 15.11 MiB/s (15.84 MB/s)
write: IOPS=2578.83 10.07 MiB/s (10.56 MB/s)
fsync: IOPS=8226.98
Latency (ms):
min: 0.00
avg: 0.27
max: 18.01
95th percentile: 1.08
sum: 238469.45
This note marks the beginning of a large
series of articles about backup
- Backup, part 1: Why backup is necessary, overview of methods and technologies
- Backup, part 2: Overview and testing of rsync-based backup solutions
- Backup, Part 3: Overview and Testing of duplicity, duplicaty, deja dup
- Backup, Part 4: Overview and Testing of zbackup, restic, borgbackup
- Backup, Part 5: Testing Bacula and Veeam Backup for Linux
- Backup, Part 6: Comparison of Backup Solutions
- Backup, Part 7: Conclusions
Source: habr.com
