

Happy Friday to everyone! Friends, today we continue our series of publications dedicated to the course , as the classes in the new group for the course will start at the end of next week. So, let’s get started!
Monitoring is simply. This is a well-known fact. Spin up Nagios, run NRPE on the remote system, configure Nagios on TCP port 5666 and you have monitoring.
It's so easy that it’s not interesting. Now you have the basic metrics for CPU time, disk subsystem, and RAM, coming by default in Nagios and NRPE. But actually, this isn’t ‘monitoring’ per se. This is just the beginning.
(Usually, you install PNP4Nagios, RRDtool, and Thruk, configure notifications in Slack, and go straight to nagiosexchange, but we’ll skip this for now.)
Good monitoring is actually quite complex; you really need to know the ins and outs of the application you are observing.
Is monitoring complicated?
Any server, whether Linux or Windows, will serve some purpose by definition. Apache, Samba, Tomcat, file storage, LDAP – all these services are unique in one or more ways. Each has its own function and characteristics. There are different ways to obtain metrics, key performance indicators (KPIs) that matter to you when the server is under load.
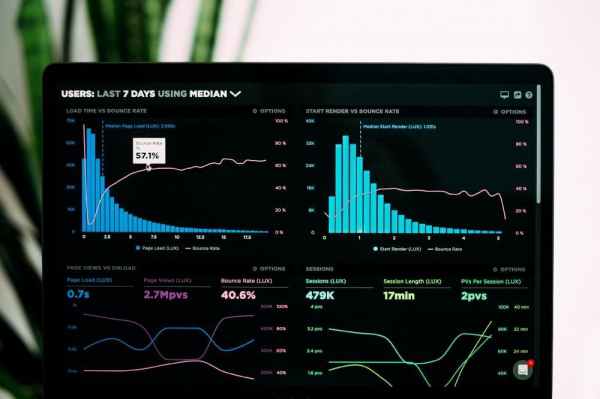
Photo by to
(I would love for my dashboards to be painted in neon blue colors — dreamily sighing — … hmm…)
Any software providing services should have a mechanism for collecting metrics. Apache has the module mod-status, which displays the server status page. Nginx has stub_status. Tomcat has JMX or special web applications that show key metrics. MySQL has the command ‘show global status’ etc.
So why don’t developers embed such mechanisms in the applications they create?
Do only developers do this?
A certain level of indifference to embedding metrics is not limited to developers. I have worked in companies where applications were developed using Tomcat and no metrics were provided, nor any service activity logs, apart from the general Tomcat error logs. Some developers generate a plethora of logs that mean nothing to the system administrator unfortunate enough to read them at 3:15 AM.
Photo by to
System engineers who enable such products to be released must also bear certain responsibilities regarding the situation. Few system engineers have the time or care to extract meaningful metrics from logs, without the context of those metrics and the ability to interpret them in light of the application's activity. Some do not understand what benefits they could derive from this, aside from indicators like 'something is currently (or will soon be) wrong.'
The mindset change regarding the necessity of metrics must occur not only among developers but also among system engineers.
For any system engineer, who needs to not only react to critical events but also ensure their absence, the lack of metrics is often an obstacle to this.
However, system engineers typically do not delve into the code, earning money for their company. They need lead developers who understand the importance of the system engineer’s responsibility in detecting issues, raising awareness of performance problems, and so on.
This devops thing
The devops mentality describes the synergy between the thinking of developers (dev) and operations (ops). Any company claiming to 'do devops' should:
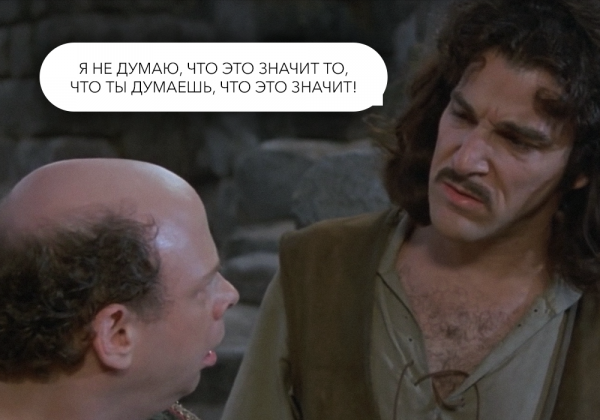
- say things that they probably do not do (a nod to the meme from the movie 'The Princess Bride' — 'I don’t think that means what you think it means!')
- encourage a position of continuous product improvement.
You cannot improve a product and know that it has been improved if you do not understand how it currently works. You won't be able to learn how the product operates unless you understand how its components, the services it relies on, its main pain points, and bottlenecks work.
If you are not monitoring potential bottlenecks, you will not be able to follow the 'Five Whys' technique when writing Postmortems. You cannot gather everything on one screen to see how the product works or to know how it looks 'normal and happy.'
Shift left, LEFT, I SAID, LEEEEEEEE—
For me, one of the key principles of Devops is 'Shift Left'. Shift left in this context means shifting the focus on the capability (not responsibility, but rather the capabilities) to do what system engineers usually care about, such as creating performance metrics, utilizing logs more efficiently, etc., earlier in the Software Delivery Life Cycle.
Photo by to
Software developers should be able to use and know the monitoring tools that the company employs to monitor in all its forms, metrics, logging, monitoring interfaces, and most importantly, to observe how their product performs in production.. You cannot compel developers to invest effort and time into monitoring unless they can see metrics and influence how they appear, as the product owner presents them to the CTO at the next briefing, etc.
In short,
- Lead the horse to water. Show developers how many issues they can avoid for themselves, help them identify the right KPIs and metrics for their applications, so there’s less shouting from the product owner at the technical director (CTO). Bring them to light, gently and calmly. If that doesn’t work, then bribe, threaten, and persuade either them or the product owner to implement the collection of these metrics from the applications as soon as possible, and then create charts. This will be challenging, as it will not be seen as a priority, and there will be many projects in the product roadmap awaiting implementation that generate revenue. Therefore, you will need a business case to justify the time and resources spent on integrating monitoring into the product.
- Help system engineers get a good night's sleep. Show them that using a release checklist for any product launch is a good practice. Ensuring that all applications in production are monitored with metrics will lead to healthier nights, allowing developers to see what is not working and where. However, the best way to annoy and frustrate any developer, product owner, or technical director is to stubbornly throw obstacles in their way and resist. Such behavior will impact the product release date if you wait until the last minute again, so shift left and incorporate these issues into the project plan as soon as possible. If necessary, sneak into product meetings. Wear fake mustaches and a felt hat or something similar; it never fails. Address your concerns, demonstrate the clear benefits, and evangelize.
- Make sure both developers (dev) and operations (ops) understand the significance and implications of metrics entering the product's "red zone." Do not leave operations as the sole guardian of product functionality; ensure that developers are also involved in this (#productsquads).
- Logs are great, but metrics are too. Combine them and don’t let your logs become trash in a massive ball of uselessness. Explain and show developers why no one but them will understand their logs, and illustrate what it’s like to sift through useless logs at 3:15 AM.
Photo by to
That's all for now. New material will be released next week. If you want to learn more about the course, we invite you to , which will take place this Monday. And now, we traditionally await your comments.
Source: habr.com
