

Until recently, around 50 TB of real-time processed data in Odnoklassniki was stored in SQL Server. Providing fast, reliable, and fault-tolerant access to such a volume using SQL DBMS is practically impossible. Typically, one of the NoSQL storage solutions is used in such cases, but not everything can be transferred to NoSQL: some entities require ACID transaction guarantees.
This led us to the use of a NewSQL storage solution, which is a database management system that offers the fault tolerance, scalability, and speed of NoSQL systems while preserving the familiar ACID guarantees of traditional systems. There are few operational industrial systems of this new class, so we implemented such a system ourselves and launched it into production.
How it works and what we achieved—read more below.
Today, the monthly audience of Odnoklassniki exceeds 70 million unique visitors. We largest social networks in the world and one of the top twenty websites where users spend the most time. The infrastructure of OK handles very high loads: over a million HTTP requests per second at the front. Parts of the server park, totaling more than 8000 units, are located close to each other—in four data centers in Moscow, allowing us to maintain network latency of less than 1 ms between them.
We have been using Cassandra since 2010, starting with version 0.6. Today, several dozen clusters are in operation. The fastest cluster processes over 4 million operations per second, and the largest stores 260 TB.
However, all of these are ordinary NoSQL clusters used for storing data. We wanted to replace the main consistent storage, Microsoft SQL Server, which has been in use since the founding of Odnoklassniki. The storage consisted of more than 300 SQL Server Standard Edition machines, containing 50 TB of data—business entities. This data is modified within the framework of ACID transactions and requires .
For data distribution across SQL Server nodes, we employed both vertical and horizontal (sharding). Historically, we used a simple data sharding scheme: each entity was assigned a token—a function of the entity ID. Entities with the same token were placed on the same SQL server. The master-detail relationship was implemented such that the tokens of the main and derived records always matched and resided on the same server. In the social network, almost all records are generated on behalf of a user—meaning that all user data within one functional subsystem is stored on a single server. Thus, business transactions almost always involved tables from a single SQL server, allowing us to ensure data consistency using local ACID transactions, without the need for distributed ACID transactions.
Thanks to sharding and to speed up SQL operations:
- We do not use Foreign key constraints, as entity IDs may reside on different servers when sharding.
- We do not use stored procedures and triggers due to the additional CPU load on the DBMS.
- We avoid JOINs because of the above reasons and numerous random disk reads.
- Outside of transactions, to reduce deadlocks, we use the Read Uncommitted isolation level.
- We only perform short transactions (averaging less than 100 ms).
- We do not use multi-row UPDATE and DELETE statements due to excessive deadlocks—updating only one record at a time.
- Queries are always executed only by indexes—a query with a full table scan plan signifies database overload and potential failure.
These measures have allowed us to extract nearly maximum performance from SQL servers. However, problems have continued to escalate. Let's examine them.
SQL Issues
- Since we used a custom sharding approach, adding new shards was performed manually by the administrators. During this time, scalable data replicas did not handle requests.
- As the number of records in the table grows, the speed of insertion and modification decreases; adding indexes to an existing table results in a significant slowdown, and creating and recreating indexes incurs downtime.
- Having a limited number of Windows instances for SQL Server in production complicates infrastructure management.
But the main problem is—
Fault tolerance
A traditional SQL server has poor fault tolerance. Suppose you have only one database server, and it fails once every three years. During that time, the site is down for 20 minutes, which is acceptable. If you have 64 servers, the site is down once every three weeks. And if you have 200 servers, the site is down every week. This is a problem.
What can be done to improve the fault tolerance of an SQL server? Wikipedia suggests building a : where, in the event of failure of any component, there is a backup.
This requires an expensive infrastructure: extensive duplication, fiber optic cables, shared storage, and the activation of backup systems is unreliable: about 10% of activations result in the backup node failing along with the primary node.
But the main drawback of such a high-availability cluster is zero availability in case of a failure of the data center where it is housed. Classmates has four data centers, and we need to ensure operation during a complete failure in one of them.
To address this, we could apply replication, built into SQL Server. This solution is significantly more expensive due to software costs and suffers from well-known replication issues—unpredictable transaction delays with synchronous replication and delays in applying replications (and consequently, lost modifications) with asynchronous replication. The implied makes this option completely unfeasible for us.
All these issues required a radical solution, and we began a detailed analysis of them. Here we need to understand what SQL Server primarily does—transactions.
A simple transaction
Let’s consider the simplest transaction from an application SQL programmer's perspective: adding a photo to an album. Albums and photos are stored in different tables. An album has a counter for the number of public photos. Therefore, this transaction can be broken down into the following steps:
- Lock the album by key.
- Create a record in the photos table.
- If the photo has a public status, increment the album's public photo counter, update the record, and commit the transaction.
Or in pseudocode:
TX.start("Albums", id);
Album album = albums.lock(id);
Photo photo = photos.create(…);

if (photo.status == PUBLIC) {
    album.incPublicPhotosCount();
}
album.update();

TX.commit();
We see that the most common scenario for a business transaction is to read data from the database into the application server's memory, make some changes, and save the new values back to the database. Usually, in such a transaction, we update several entities, several tables.
During a transaction, concurrent modification of the same data from another system may occur. For example, an Anti-Spam system might decide that a user is suspicious, and therefore all photos belonging to that user should no longer be public; they need to be sent for moderation, which means changing photo.status to some other value and rolling back the corresponding counters. Clearly, if this operation occurs without guarantees of atomicity and isolation of competing modifications, as in , the result will not be as needed — either the photo counter will show an incorrect value, or not all photos will be sent for moderation.
A lot of such code manipulating various business entities within a single transaction has been written over the entire existence of Odnoklassniki. From the experience of migrating to NoSQL with , we know that the biggest challenges (and time costs) arise from the necessity to develop code aimed at maintaining data consistency. Thus, the main requirement for the new storage was to ensure true ACID transactions for application logic.
Other equally important requirements were:
- In the event of a data center failure, both reading and writing to the new storage must be possible.
- Maintaining the current development speed. That is, when working with the new storage, the amount of code should be approximately the same; there should be no need to write additional code for storage, develop conflict resolution algorithms, maintain secondary indexes, etc.
- The performance of the new storage must be sufficiently high for both data reads and transaction processing, which effectively meant the inapplicability of academically rigorous, universal, yet slow solutions, such as .
- Automatic scaling on the fly.
- Using ordinary cheap servers without the need to purchase exotic hardware.
- The ability for developers within the company to enhance storage. In other words, the priority was given to in-house or open-source solutions, preferably in Java.
Solutions, solutions
Analyzing potential solutions, we arrived at two possible architectural choices:
The first option is to take any SQL server and implement the necessary fault tolerance, scaling mechanisms, a fault-tolerant cluster, conflict resolution, and distributed, reliable, and fast ACID transactions. We assessed this option as quite non-trivial and labor-intensive.
The second option is to take a ready-made NoSQL storage solution with implemented scaling, a fault-tolerant cluster, conflict resolution, and implement transactions and SQL ourselves. At first glance, even the task of implementing SQL, not to mention ACID transactions, seemed like a multi-year project. But then we realized that the set of SQL capabilities we use in practice is far from ANSI SQL as far as is from ANSI SQL. Upon closer inspection of CQL, we found that it is sufficiently close to what we need.
Cassandra and CQL
So, what makes Cassandra interesting, what features does it have?
Firstly, it allows the creation of tables that support various data types, and you can perform SELECT or UPDATE by the primary key.
CREATE TABLE photos (id bigint KEY, owner bigint,…);
SELECT * FROM photos WHERE id=?;
UPDATE photos SET … WHERE id=?;
To ensure the consistency of replica data, Cassandra uses In the simplest case, this means that when placing three replicas of the same row on different nodes of the cluster, the write is considered successful if the majority of nodes (i.e., two out of three) have confirmed the success of this write operation. The row data is considered consistent if the majority of nodes were polled during reading and confirmed it. Thus, with three replicas, full and immediate data consistency is guaranteed in the event of one node failure. This approach allowed us to implement an even more reliable scheme: always send requests to all three replicas, waiting for responses from the two fastest. The delayed response from the third replica is discarded in such cases. The delayed node may have serious issues — throttling, garbage collection in the JVM, direct memory reclaim in the Linux kernel, hardware failure, or network disconnection. However, this does not impact client operations or data in any way.
The approach where we query three nodes and receive responses from two is called : the request for the extra replicas is sent even before things 'drop out'.
Another advantage of Cassandra is the Batchlog — a mechanism that guarantees either full application or full rejection of the batch of changes you make. This allows us to achieve A in ACID — atomicity out of the box.
The closest thing to transactions in Cassandra is the so-called ''. However, they are far from 'true' ACID transactions: in fact, it allows making a on the data of only a single record, using consensus by the heavyweight Paxos protocol. Therefore, the speed of such transactions is not high.
What we lacked in Cassandra
So, we had to implement true ACID transactions in Cassandra. With which we could easily implement two other convenient features of traditional DBMS: consistent fast indexes that would allow us to retrieve data not only by primary key and a standard monotonic auto-increment ID generator.
C*One
Thus, a new DBMS was born C*One, consisting of three types of server nodes:
- Storage — (almost) standard Cassandra servers responsible for storing data on local disks. As the load and volume of data grow, their number can be easily scaled to dozens and hundreds.
- Transaction coordinators ensure the execution of transactions.
- Clients are application servers that implement business operations and initiate transactions. There can be thousands of such clients.
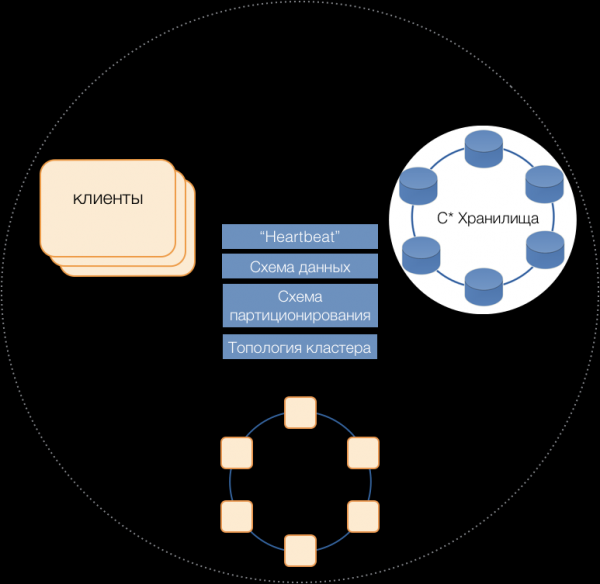
Servers of all types are part of a common cluster, using the internal Cassandra messaging protocol to communicate with each other and to exchange cluster information. Through Heartbeat, servers learn about mutual failures, maintain a consistent data schema — tables, their structure and replication; partitioning schema, cluster topology, etc.
Clients
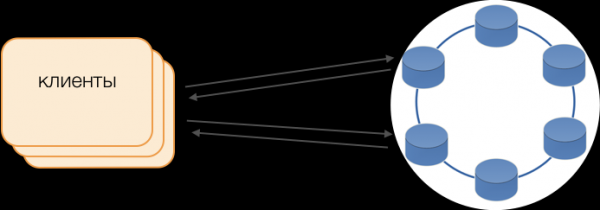
Instead of standard drivers, a Fat Client mode is used. Such a node does not store data but can act as a request execution coordinator, meaning the Client itself performs the role of coordinating its requests: it queries storage replicas and resolves conflicts. This is not only more reliable and faster than a standard driver that requires communication with a remote coordinator, but it also allows for managing request transmission. Outside of an open transaction on the client, requests are directed to the storages. However, if the client has opened a transaction, all requests within the transaction are directed to the transaction coordinator.
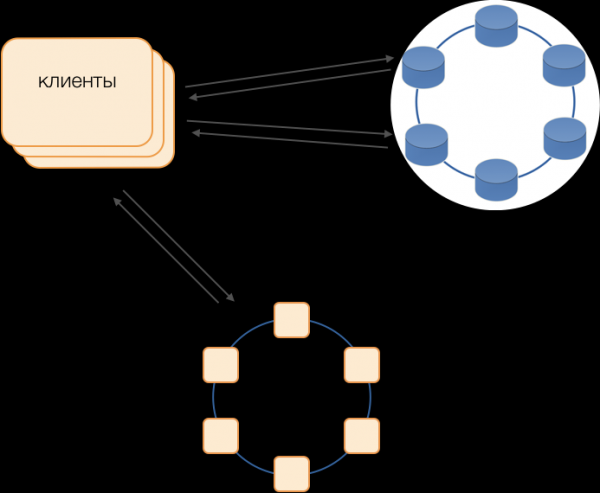
Transaction coordinator C*One
The coordinator is what we implemented for C*One from scratch. It is responsible for managing transactions, locks, and the order of transaction applications.
For each serviced transaction, the coordinator generates a timestamp: each subsequent one is greater than the previous transaction. Since in Cassandra the conflict resolution system is based on timestamps (out of two conflicting records, the one with the later timestamp is considered valid), the conflict is always resolved in favor of the subsequent transaction. Thus, we have implemented — a cheap way to resolve conflicts in a distributed system.
Locks
To ensure isolation, we decided to use the simplest method — pessimistic locks by the primary key of the record. In other words, in a transaction, a record must first be locked, then read, modified, and saved. Only after a successful commit can the record be unlocked so competing transactions can use it.
Implementing such a lock is simple in a non-distributed environment. In a distributed system, there are two main approaches: either implementing a distributed lock across the cluster or distributing transactions so that transactions involving a single record are always handled by the same coordinator.
Since in our case the data is already distributed across groups of local transactions in SQL, it was decided to assign coordinators to groups of local transactions: one coordinator handles all transactions with tokens from 0 to 9, the second handles tokens from 10 to 19, and so on. As a result, each instance of the coordinator becomes the master of its transaction group.
Then, locks can be implemented as a basic HashMap in the coordinator's memory.
Coordinator Failures
Since a single coordinator exclusively serves a group of transactions, it is very important to quickly identify the fact of its failure so that the transaction's retry fits within the timeout. To achieve this quickly and reliably, we applied a fully connected quorum heartbeat protocol:
At least two coordinator nodes are placed in each data center. Periodically, each coordinator sends heartbeat messages to the other coordinators, reporting on its functioning and the last heartbeat messages received from which coordinators in the cluster.
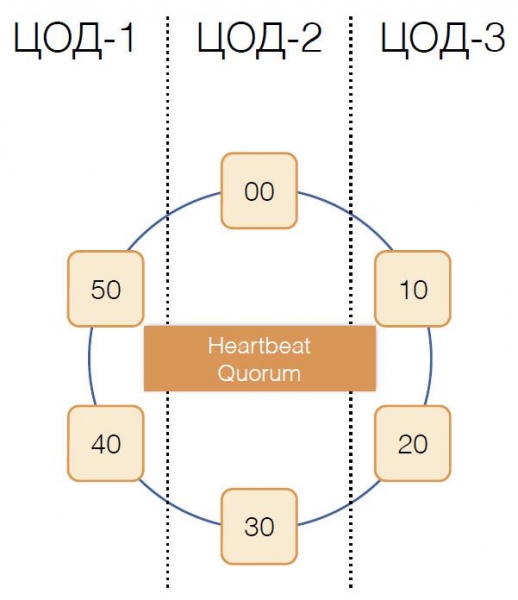
By receiving similar information from the others in their heartbeat messages, each coordinator determines for itself which nodes in the cluster are functioning and which are not, following the quorum principle: if node X receives information about normal message receipt from node Y from the majority of the nodes in the cluster, then Y is operational. Conversely, as soon as the majority reports that messages from node Y have been lost, then Y has failed. Interestingly, if the quorum informs node X that it is no longer receiving messages from it, then node X will consider itself failed.
Heartbeat messages are sent frequently, about 20 times per second, with a period of 50 ms. In Java, it's challenging to guarantee an application response within 50 ms due to comparable pause durations caused by the garbage collector. We managed to achieve such response times using the G1 garbage collector, which allows setting a target for GC pause durations. However, occasionally, although rarely, garbage collector pauses exceed 50 ms, which can lead to false failure detection. To prevent this, the coordinator does not report a remote node as failed upon missing the first heartbeat message from it, but only after several consecutive ones are missed. This way, we managed to achieve failure detection of the coordinator node in 200 ms.
But it's not enough to quickly understand which node has stopped functioning. Something needs to be done about this.
Failover
The classic scheme suggests initiating the election of a new master in case of the master’s failure using one of the algorithms. However, such algorithms have well-known issues with convergence over time and the duration of the election process itself. We managed to avoid such additional delays using a coordinator replacement scheme in a fully connected network:
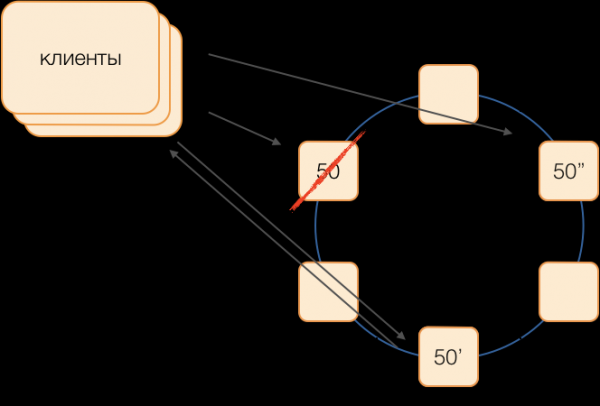
Suppose we want to execute a transaction in group 50. We will predefine the replacement scheme, meaning which nodes will carry out transactions for group 50 in case of the main coordinator's failure. Our goal is to maintain system functionality in the event of a data center failure. We will identify that the first backup will be a node from another data center, and the second backup will be a node from a third one. This scheme is chosen once and does not change until the cluster topology changes, that is, until new nodes join it (which happens very rarely). The order of selecting a new active master upon the failure of the old one will always be as follows: the first backup will become the active master, and if it also stops functioning, the second backup will take over.
This scheme is more reliable than a universal algorithm since it only requires determining the fact of the old master's failure to activate a new master.
But how will clients know which master is currently working? It's impossible to send information to thousands of clients in 50 ms. A situation may arise where a client sends a request to open a transaction, not yet knowing that this master is no longer operational, and the request may time out. To prevent this from happening, clients speculatively send requests to open transactions to both the group master and its backups, but only the one who is the active master at that moment will respond to this request. All subsequent communication regarding the transaction will be carried out only with the active master.
Backup masters place requests for transactions that are not theirs into a queue of unborn transactions, where they remain for a while. If the active master dies, a new master processes the requests to open transactions from its queue and responds to the client. If the client has already opened a transaction with the old master, then the second response is ignored (and, obviously, such a transaction will not complete and will be retried by the client).
How a transaction works
Suppose a client sends a request to the coordinator to open a transaction for a certain entity with a certain primary key. The coordinator locks this entity and places it in the lock table in memory. If necessary, the coordinator reads this entity from the storage and saves the retrieved data in the transaction state in the coordinator's memory.
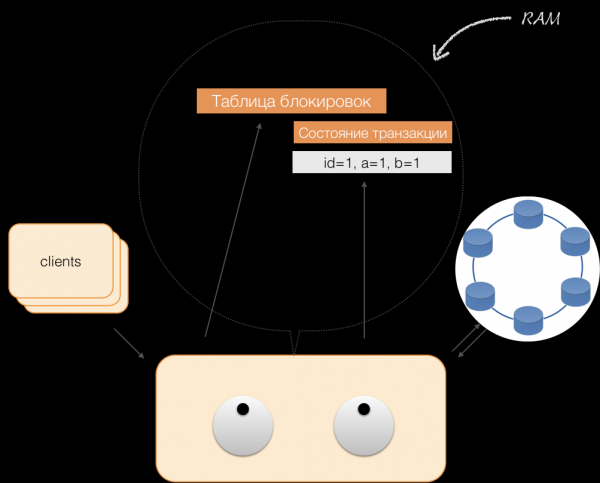
When a client wants to modify data in the transaction, they send a modification request for the entity to the coordinator, who places the new data in the transaction state table in memory. At this point, the recording is complete—no write to the storage is performed.
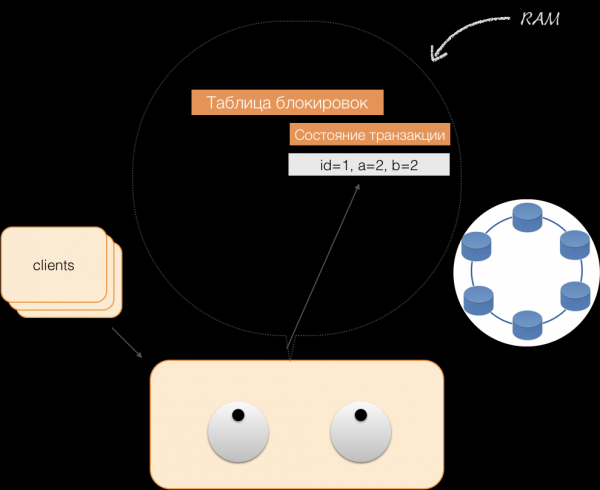
When a client requests their modified data within an active transaction, the coordinator acts as follows:
- if the ID already exists in the transaction, data is taken from memory;
- if the ID is not in memory, the missing data is read from the node storages, combined with the existing data in memory, and the result is given to the client.
Thus, the client can read their own changes, while other clients do not see these changes because they are only stored in the coordinator's memory; they are not yet present in the Cassandra nodes.
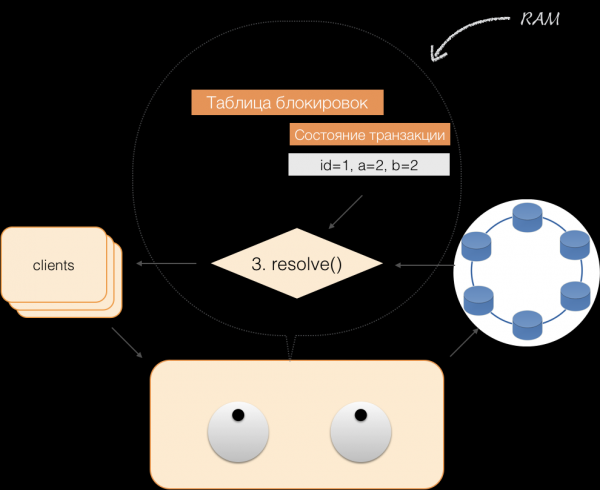
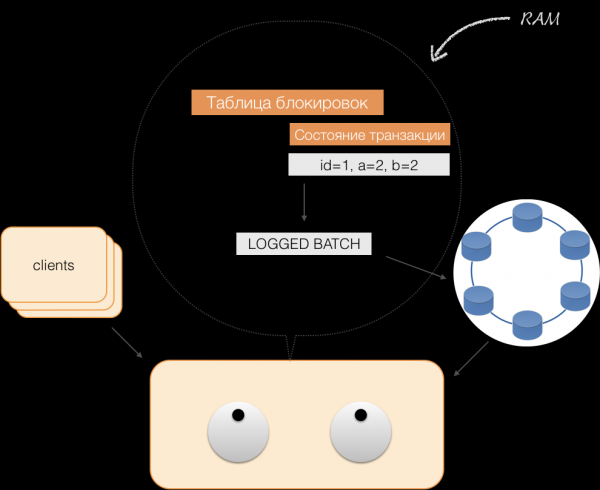
When a client sends a commit, the state maintained in the service's memory is saved by the coordinator in a logged batch, which is then sent to Cassandra storage as a logged batch. The storage takes all necessary actions to ensure that this batch is applied atomically (completely), and returns a response to the coordinator, which then releases locks and confirms the transaction's success to the client.
For rollback, the coordinator only needs to free the memory occupied by the transaction's state.
As a result of the above improvements, we have implemented the principles of ACID:
- Atomicity. This guarantees that no transaction will be partially committed in the system; all its sub-operations will either be executed or none will be executed at all. We ensure this principle through the logged batch in Cassandra.
- Consistency. Each successful transaction only commits permissible results by definition. If it is found that the result is invalid after opening the transaction and performing part of the operations, a rollback is performed.
- Isolation. During the execution of a transaction, parallel transactions should not affect its result. Competing transactions are isolated using pessimistic locks at the coordinator. For reads outside the transaction, the principle of isolation at the Read Committed level is observed.
- Durability. Regardless of issues at lower levels—such as power loss or hardware failure—changes made by a successfully completed transaction must remain saved after normal functioning resumes.
Reading by indexes
Let's take a simple table:
CREATE TABLE photos (
id bigint primary key,
owner bigint,
modified timestamp,
…)
It has an ID (primary key), an owner, and a modified date. We need to make a very simple query—to select data by owner with a modification date 'within the last day.'
SELECT *
WHERE owner=?
AND modified>?
For such a query to run quickly, a classic SQL database needs to create an index on the columns (owner, modified). We can do this quite easily now that we have ACID guarantees!
Indexes in C*One
There is an original table with photographs where the record ID is the primary key.
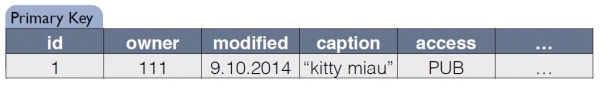
For C*One, a new table is created, which is a copy of the original. The key matches the indexed expression, and it also includes the primary key of the record from the original table:
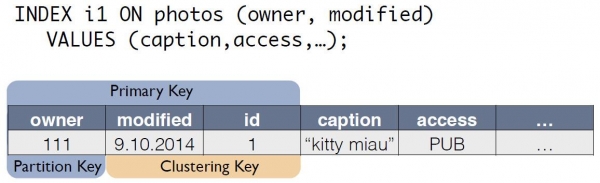
Now the query for "owner over the last day" can be rewritten as a select from another table:
SELECT * FROM i1_test
WHERE owner=?
AND modified > ?
The consistency of the original photos table and the indexed i1 is automatically maintained by the coordinator. Based solely on the data schema, when changes are detected, the coordinator generates and remembers changes not only for the primary table but also for the copies. No additional actions are performed on the index table, logs are not read, and locks are not used. This means that adding indexes consumes almost no resources and has little impact on the speed of applying modifications.
With ACID, we managed to implement indexes "like in SQL." They are consistent, scalable, fast, can be composite, and integrated into the CQL query language. No changes are needed in the application code to support indexes. It's as simple as in SQL. And most importantly, indexes do not affect the execution speed of modifications in the original transaction table.
What we achieved
We developed C*One three years ago and launched it into production.
So, what did we get as a result? Let's evaluate this using the example of the photo processing and storage subsystem, one of the most important types of data in a social network. We're not talking about the actual photo bodies, but about various metadata. Currently, there are about 20 billion such records in “Odnoklassniki”, the system processes 80,000 read requests per second, and up to 8,000 ACID transactions per second related to data modifications.
When we used SQL with a replication factor of 1 (but in RAID 10), the photo metadata was stored on a high-availability cluster of 32 machines with Microsoft SQL Server (plus 11 backups). Additionally, 10 servers were allocated for backup storage. In total, 50 expensive machines. At the same time, the system operated under nominal load, without any reserve.
After migrating to the new system, we achieved a replication factor of 3 — with one copy in each data center. The system consists of 63 Cassandra storage nodes and 6 coordinator machines, totaling 69 servers. However, these machines are significantly cheaper, with a total cost amounting to about 30% of the SQL system's cost. Meanwhile, the load remains at 30%.
With the implementation of C*One, latencies have decreased: in SQL, the write operation took about 4.5 ms. In C*One, it’s around 1.6 ms. The average transaction duration is less than 40 ms, with commits completed in 2 ms, and read/write durations averaging 2 ms. The 99th percentile is merely 3-3.1 ms, and the number of timeouts has decreased by 100 times — all thanks to extensive speculation.
By now, most of the SQL Server nodes have been decommissioned; new products are being developed solely using C*One. We have adapted C*One to work within our cloud. , which has accelerated the deployment of new clusters, simplified configuration, and automated operations. Achieving this without the source code would have been considerably more complicated and hacky.
We are currently working on migrating our other storage systems to the cloud — but that's a completely different story.
Source: habr.com
