

In 2010, the company had 50 servers and a simple network model: backend, frontend, and firewall. The number of servers grew, the model became more complex: staging, isolated VLANs with ACLs, then VPNs with VRFs, VLANs with ACLs on L2, VRFs with ACLs on L3. Feeling overwhelmed? It gets more interesting.
When the number of servers reached 16,000, it became impossible to work without tears with such a diverse array of segments. So, another solution was devised. They took the Netfilter stack, added Consul as a data source, resulting in a fast distributed firewall. This replaced ACLs on routers and was used as both an external and internal firewall. To dynamically manage the tool, they developed the BEFW system, which was applied everywhere: from managing user access in the product network to isolating network segments from one another.
How all this works and why you should take a closer look at this system will be explained by Ivan Agarkov () — head of the infrastructure security group in the Maintenance division at the Minsk development center of the company. Ivan is a fan of SELinux, loves Perl, and writes code. As the head of the security group, he regularly works with logs, backups, and R&D to protect Wargaming from hackers and ensure the operation of all gaming servers in the company.
Historical Background
Before explaining how we did this, I will recount how we got here in the first place and why this was necessary. To do this, let’s go back 9 years: 2010, when World of Tanks had just launched. Wargaming had about 50 servers.
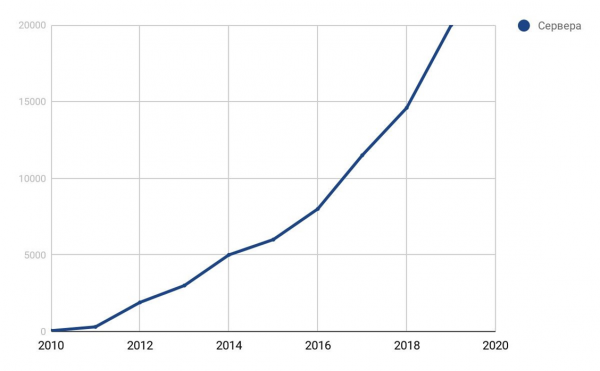
The growth chart of the company’s servers.
We had a network model. For that time, it was optimal.
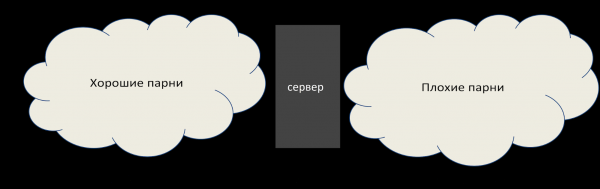
The network model in 2010.
The bad guys who want to break us live on the frontend, but there’s a firewall in place. There’s no firewall on the backend, but there are 50 servers, and we know all of them. Everything works well.
Within 4 years, the server park grew 100 times, to 5,000. The first isolated networks appeared — staging: they cannot access production, and they often ran potentially dangerous content.
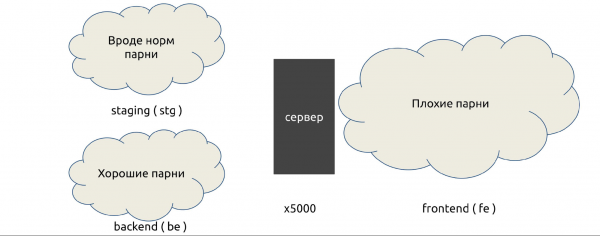
The network model in 2014.
By inertia, we continued to use the same hardware, and all work was conducted on isolated VLANs: ACLs were written to the VLANs that allow or deny certain connections.
In 2016, the number of servers reached 8,000. Wargaming acquired other studios, and additional partner networks emerged. They seem to be ours, but not quite: the VLAN often doesn’t work for partners, requiring the use of VPNs with VRF, complicating isolations. The mix of ACL isolations grew.
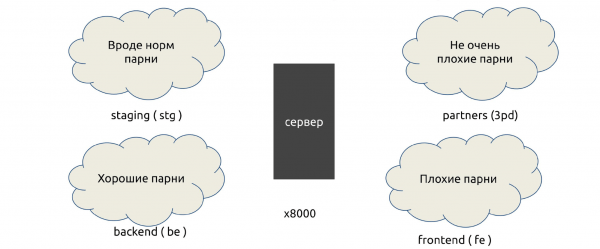
The network model in 2016.
By early 2018, the fleet had grown to 16,000 machines. There were 6 segments, and we didn't count the others, including those holding financial data. Container networks (Kubernetes), DevOps, and cloud networks connected via VPN, like from IVS, appeared. There were too many rules—it was painful.
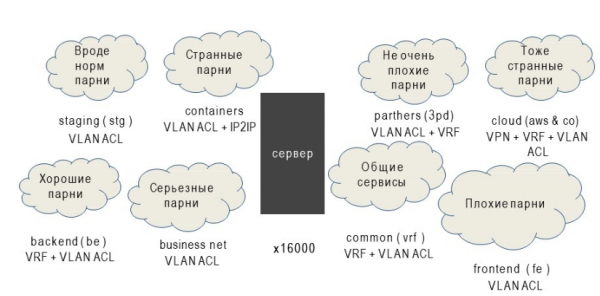
The network model and isolation methods in 2018.
For isolation, we used: VLANs with ACLs at L2, VRF with ACLs at L3, VPNs, and much more. Too much.
Issues
Everyone operates with ACLs and VLANs. What’s the problem? Harold, hiding the pain, will answer this question.
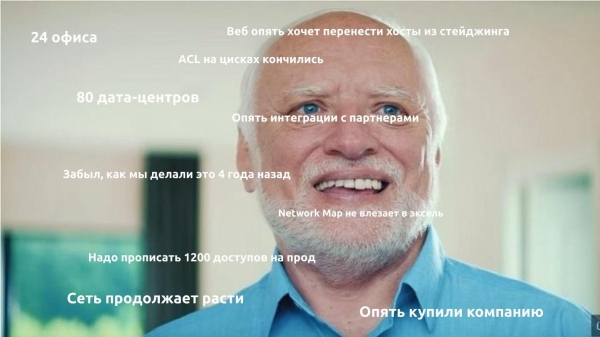
There were many issues, but only five were widespread.
- Exponential price increase for new rules.. Each new rule took longer to add than the previous one since we needed to check if such a rule already existed.
- No firewall within the segments.. The segments were somehow separated from each other, but internally resources were lacking.
- Rules were applied slowly. Operators could write one local rule by hand in an hour. Global rules took several days.
- Challenges with rule auditing.. More precisely, it was impossible. The first rules were written back in 2010, and most of their authors no longer worked at the company.
- Low level of control over the infrastructure.. This is the main issue—we poorly understood what was really happening.
This is what a network engineer looked like in 2018 when he heard: 'We need a bit more ACL.'
Solutions
At the beginning of 2018, it was decided that something needed to be done about this.
The cost of integrations is continuously rising. The starting point was that large data centers stopped supporting isolated VLANs and ACLs because the devices ran out of memory.
Solution: eliminate the human factor and automate access provision to the maximum.
New rules take a long time to be applied. Solution: accelerate rule application, making it distributed and parallel. A distributed system is needed for rules to be delivered autonomously, without rsync or SFTP to a thousand systems.
Absence of a firewall within segments. Firewalls within segments started affecting us when different services emerged within a single network. Solution: use host-based firewalls. Almost everywhere we have Linux, and iptables is available, so it’s not an issue.
Challenges with auditing rules. Solution: store all rules in one place for review and management, enabling us to audit everything.
Low level of infrastructure control. Solution: conduct an inventory of all services and the accesses between them.
This is more of an administrative process than a technical one. Sometimes we have 200-300 new releases a week, particularly during promotions and holidays. This is just for one of our DevOps teams. With that many releases, it's impossible to know which ports, IPs, and integrations are required. Therefore, we needed specially trained service managers to interview the teams: 'What is out there and why did you deploy this?'
After everything we launched, the network engineer looked like this in 2019.
Consul
We decided that everything we discovered with the help of service managers would be placed in Consul, from which we would write iptables rules.
How did we decide to do this?
- We will gather all services, networks, and users.
- We will create iptables rules based on them.
- We will automate control.
- ….
- PROFIT.
Consul is not a remote API; it can operate on each node and write to iptables. We just need to devise automated control tools that will clean up the extras, and most of the problems will be resolved! The rest we will refine in the process.
Why Consul?
It has proven itself well. In 2014-2015, we used it as a backend for Vault, where we store passwords.
Does not lose data.. Throughout the usage of Consul, it has not lost data during any incidents. This is a huge plus for the firewall management system.
P2P connections accelerate the dissemination of changes.. With P2P, all changes arrive quickly, no need to wait for hours.
Convenient REST API. We also considered Apache ZooKeeper, but it lacks a REST API, so we would need to add workarounds.
Works as both a key-value store (KV) and a directory (Service Discovery).. You can store services, catalogs, and data centers at once. This is convenient not only for us but also for adjacent teams, as we think on a large scale when building a global service.
Written in Go, which is part of the Wargaming tech stack. We love this language; we have many Go developers.
Powerful ACL system. In Consul, ACL can control who can write and to what. We ensure that the firewall rules will not overlap with anything else, and we won't have issues with that.
However, Consul has its drawbacks.
- It doesn’t scale within a data center unless you have the business version. It only scales through federation.
- It is highly dependent on network quality and server load. Consul will not function properly as a server on a busy server if there are any lags in the network, for example, unstable speeds. This is related to P2P connections and update propagation models.
- Challenges with availability monitoring. The status of Consul might indicate that everything is fine while it has actually crashed a long time ago.
Most of these problems were resolved during the operation of Consul, which is why we chose it. The company has plans for an alternative backend, but we have learned to tackle the issues and are currently living with Consul.
How Consul works
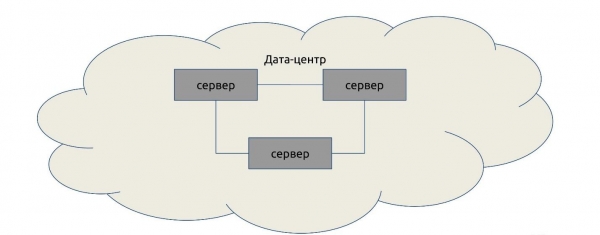
In a hypothetical data center, we will set up servers — from three to five. One or two servers will not suffice: they will not be able to establish quorum and determine who is right when data does not match. More than five is pointless, as performance will decline.
Clients connect to the servers in any order: the same agents, just with the flag server = false.
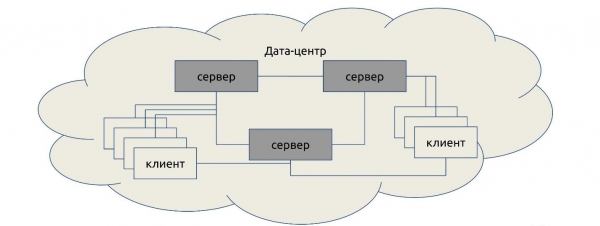
After that, clients receive a list of P2P connections and establish relationships between themselves.
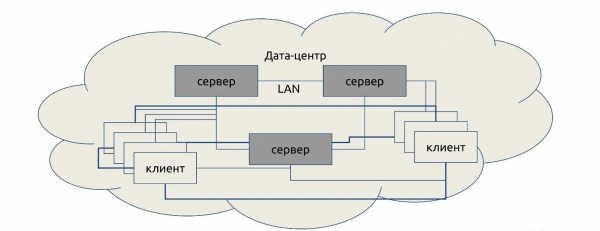
At a global level, we connect several data centers together. They are also connected via P2P and communicate.
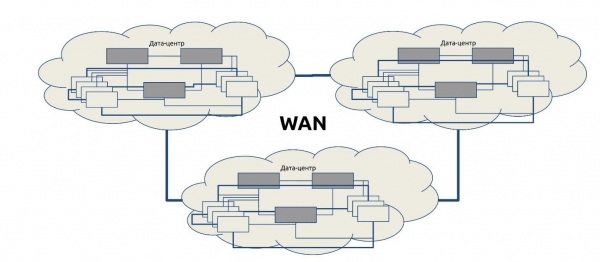
When we want to retrieve data from another data center, the request goes from server to server. This is called the Serf protocol. The Serf protocol, like Consul, was developed by HashiCorp.
Several important facts about Consul
Consul has documentation describing its operation. I will provide only selected facts that are worth knowing.
Consul servers elect a master from among the voters. Consul selects a master from the list of servers for each data center, and all requests go only to it, regardless of the number of servers. If the master hangs, it does not lead to re-elections. If no master is elected, requests are served by no one.
Did you want horizontal scaling? Sorry, no.
The request to another data center goes from master to master, regardless of which server it came to. The selected master receives 100% of the load, except for the load on forwarding requests. An updated copy of the data is available on all servers in the data center, but only one responds.
The only way to scale is to enable stale mode on the client.
In stale mode, responses can be given without quorum. This is a mode in which we give up on data consistency but read slightly faster than usual, and any server can respond. Naturally, writes can only go through the master.
Consul does not replicate data between data centers. When gathering federations, each server will only have its own data. For others, it will always refer to someone else.
Atomicity of operations is not guaranteed outside of transactions. Remember that changes can be made not only by you. If you want to do it differently, conduct a transaction with locking.
Blocking operations do not guarantee locking. The request goes from master to master, not directly, so there are no guarantees that the lock will work when you try to apply a lock, for example, in another data center.
ACL also does not guarantee access (in many cases). ACL may fail, as it is stored in one data center of the federation — in the ACL data center (Primary DC). If the DC does not respond, the ACL will not work.
One hung master will lead to the hanging of the entire federation. For example, in a federation of 10 data centers, if one has poor network connectivity and one master crashes, everyone communicating with it will hang in a loop: a request is made, there is no response, the thread hangs. It won't be possible to know when this will happen; in an hour or two, the entire federation will crash. There is nothing you can do about it.
Status, quorum, and elections are handled by a separate thread. Re-elections won’t happen, the status will show nothing. You think you have a live Consul, you request it, and nothing happens — there’s no response. Meanwhile, the status indicates everything is fine.
We have encountered this problem, and we had to rebuild specific parts of the data centers to avoid it.
In the business version of Consul Enterprise, some of the above drawbacks are absentIt has many useful features: voter selection, distribution, scaling. There's just one catch — the licensing system for a distributed setup is very expensive.
Life hack: rm -rf /var/lib/consul — a cure for all the agent's ailments. If something isn't working, just delete your data and load it from a backup. Most likely, Consul will start working again.
BEFW
Now, let's talk about what we've added to Consul.
— it's an acronym for BackEndFireWall. I had to come up with a name for the product when I created the repository to store the first test commits. That name stuck.
Rule templates
The rules are written in iptables syntax.
- -N BEFW
- -P INPUT DROP
- -A INPUT -m state --state RELATED,ESTABLISHED -j ACCEPT
- -A INPUT -i lo -j ACCEPT
- -A INPUT -j BEFW
Everything flows into the BEFW chain, except for ESTABLISHED, RELATED and localhost. The template can be anything; this is just an example.
What is the benefit of BEFW?
Services
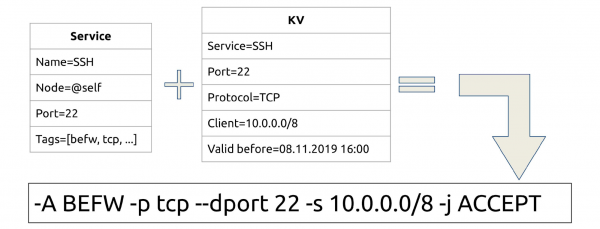
We have a service, it always has a port, and the node on which it runs. From our node, we can locally query the agent and find out we have some service. We can also assign tags.
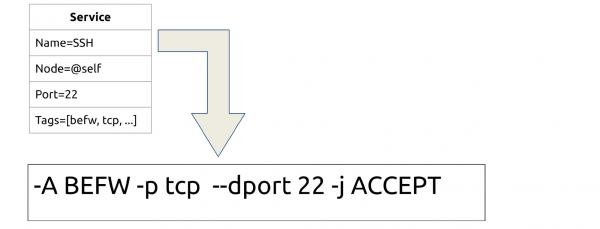
Any service that is running and registered in Consul becomes an iptables rule. We have SSH — let's open port 22. The bash script is simple: curl and iptables, nothing more is needed.
Clients
How to grant access selectively, not to everyone? Store IP lists in the KV store by service name.
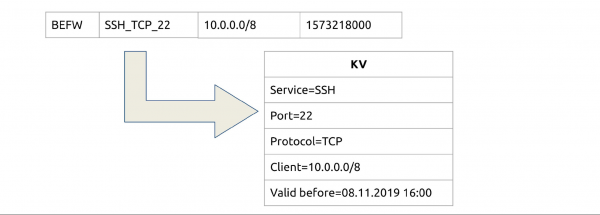
For example, we want everyone from the tenth network to be able to access the SSH_TCP_22 service. We add a small TTL field? and now we have temporary permissions, for example, for a day.
Accesses
Connecting services and clients: we have a service with a KV store ready for each. Now we grant access selectively, not to everyone.
Groups
If we keep writing thousands of IPs for access, we'll get tired. Let's think of groupings — a separate subset in the KV. We'll call it Alias (or groups) and store those groups there following the same principle.
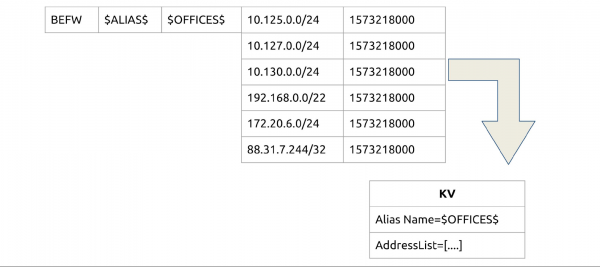
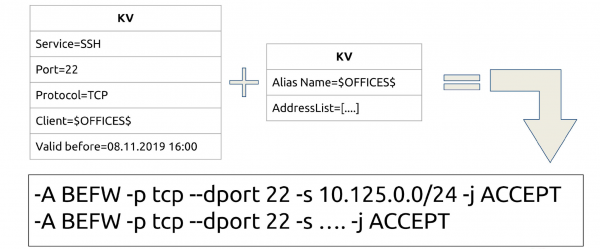
Connecting: now we can open SSH not specifically on P2P, but to an entire group or several groups. Similarly, there’s TTL — we can add to or remove from the group temporarily.
Integration
Our problem is the human factor and automation. So far, we've solved it this way.
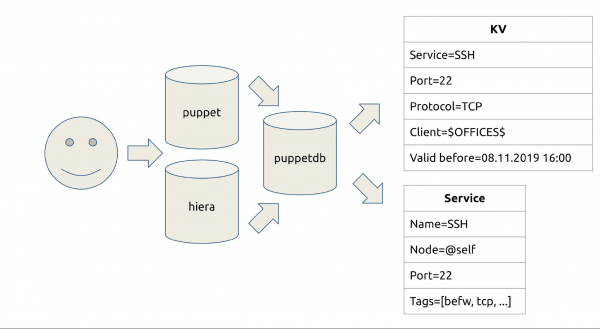
We work with Puppet and transfer everything related to the system (application code) to it. In puppetdb (a standard PostgreSQL), there is a list of services that are running there, which can be found by resource type. You can also see who is accessing what. Additionally, we have a pull request and merge request system for this.
We created befw-sync— the simplest solution that helps transfer data. First, sync cookies query puppetdb. There, an HTTP API is set up: we request what services we have and what needs to be done. Then, it makes a request to Consul.
Is there integration? Yes: we wrote rules, allowed Pull Requests. Is a port needed or adding a host to a group? Pull Request, review—no more 'Find 200 other ACLs and try to do something with this.'
Optimization
Pinging localhost with an empty chain of rules takes 0.075 ms.
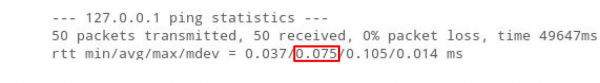
We will add 10,000 addresses to iptables in this chain. As a result, ping will increase 5 times: iptables is completely linear, processing each address takes some time.
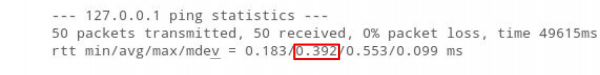
For the firewall to which we are migrating thousands of ACLs, we have many rules, which causes delays. This is bad for gaming protocols.
But if we place 10,000 addresses in ipset ping will even decrease.
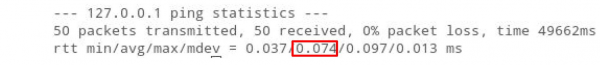
The point is that 'O' (algorithm complexity) for ipset is always 1, no matter how many rules there are. However, there is a limitation—there cannot be more than 65,535 rules. For now, we live with this: we can combine them, expand, and make two ipsets in one.
Storage
A logical continuation of the iteration process is storing information about clients for the service in ipset.
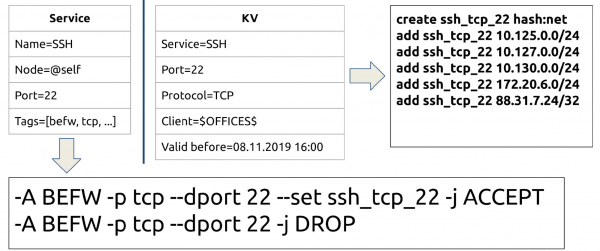
Now we have the same SSH, and we don’t write 100 IPs immediately, but specify the name of the ipset to interact with, and the next rule DROP. It can be reworked into a single rule 'Who isn’t here should DROP,' but this way it is more visually clear.
Now we have rules and sets. The main task is to create the set before writing the rule because otherwise iptables will not record the rule.
Overall Scheme
In schematic form, everything I've described looks like this.
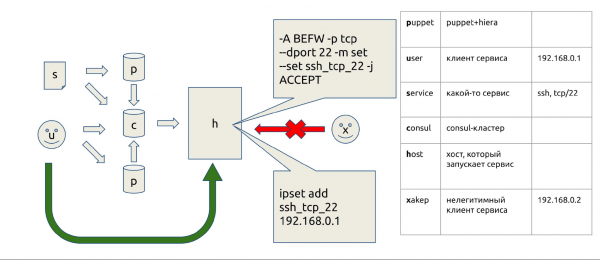
We commit to Puppet, everything is sent to the host, services are here, ipset is there, and whoever is not specified there is not allowed.
Allow & deny
To quickly save the world or quickly disconnect someone, at the beginning of all chains we created two ipsets: rules_allow and rules_deny. How does this work?
For example, someone creates a load on our Web using bots. Previously, it was necessary to find their IP through the logs, report it to the network engineers so they could locate the traffic source and ban it. Now it works differently.
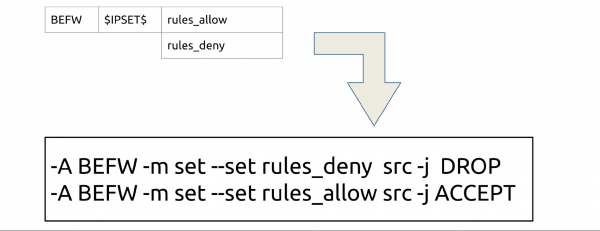
We send it to Consul, wait 2.5 seconds, and it's done. Since Consul quickly distributes through P2P, it works everywhere, in any part of the world.
Once, I completely stopped WOT due to an error with the firewall. rules_allow — this is our insurance against such cases. If we mistakenly misconfigure the firewall and something gets blocked, we can always send a conditional 0.0/0, to restore everything quickly. Later, we will fix everything manually.
Other sets
You can add any other sets in the space $IPSETS$.
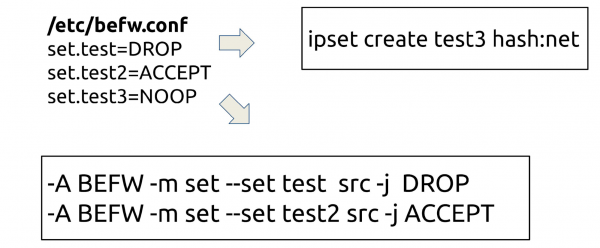
Why? Sometimes someone needs ipset, for example, to emulate the disconnection of a certain part of the cluster. Everyone can bring any sets, name them, and they will be pulled from Consul. At the same time, sets can either participate in iptables rules or act as a NOOP command. NOOP: consistency will be maintained by the daemon.
Users
It used to be this way: a user would connect to the network and receive parameters via a domain. Before the advent of next-generation firewalls, Cisco could not understand where the user was and where the IP was. Therefore, access was granted only through the hostname of the machine.
What did we do? We intervened at the moment of address acquisition. Usually, this is dot1x, Wi-Fi, or VPN—all through RADIUS. For each user, we create a group named after the user and place the IP in it with a TTL equal to their dhcp.lease—once it expires, the rule disappears.
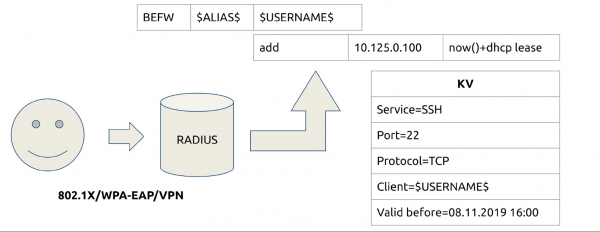
Now we can grant access to services just like in other groups, by username. We eliminated the hassle with hostnames when they change and relieved the network engineers from the burden, as they no longer need Cisco. Now engineers can configure access on their servers themselves.
Isolation
At the same time, we started examining isolation. Service managers conducted an inventory, and we analyzed all our networks. We will categorize them into similar groups, and on the required servers, we added groups, for example, in deny. Now the same staging isolation falls into rules_deny in production, but not directly into production.
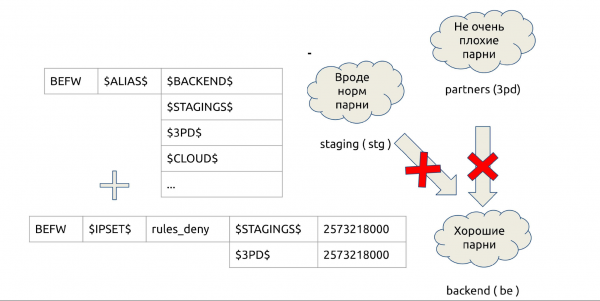
The scheme works quickly and simply: we remove all ACLs from servers, lighten the hardware load, and reduce the number of isolated VLANs.
Integrity control
Previously, we had a special trigger that alerted us when someone manually changed a firewall rule. I wrote a large linter to check firewall rules, which was complicated. Now, integrity is monitored by BEFW. It diligently ensures that the rules it creates are not altered. If someone changes the firewall rules, it will revert everything back. "I quickly set up a proxy to work from home" — options like this are no longer available.
BEFW monitors ipset from services and the list in befw.conf; service rules are in the BEFW chain. However, it does not monitor other chains, rules, or ipsets.
Fault Protection
BEFW always saves the last successful state directly in the binary structure state.bin. If something goes wrong, it always reverts to this state.bin.
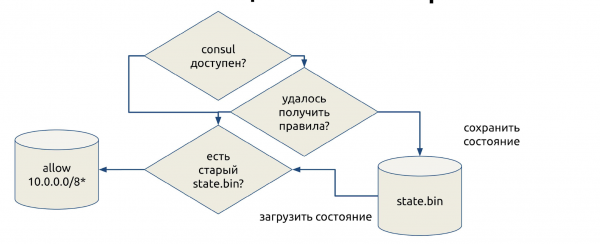
This acts as insurance against unstable Consul operation when it fails to send data or someone mistakenly uses rules that cannot be applied. To ensure we are not left without a firewall, BEFW will revert to the last state if an error occurs at any point.
In critical situations, this guarantees that we will remain with a functioning firewall. We open all gray networks in the hope that an admin will come and fix them. Someday, I will incorporate this into the configs, but right now we only have three gray networks: 10/8, 172/12, and 192.168/16. Within our Consul, this is an important feature that helps us progress further.
Demo: during the presentation, Ivan demonstrates the demo mode of BEFW. The demonstration is easier to view on . The source code for the demo is available .
Pitfalls
I will discuss the bugs we encountered.
ipset add set 0.0.0.0/0. What happens if you add 0.0.0.0/0 to ipset? Do all IPs get added? Is internet access opened?
No, we will encounter a bug that cost us two hours of downtime. Notably, this bug has not worked since 2016, is listed in RedHat Bugzilla under number #1297092, and we found it accidentally — from a developer's report.
Now, there is a strict rule in BEFW that 0.0.0.0/0 turns into two addresses: 0.0.0.0/1 and 128.0.0.0/1.
ipset restore set < file. What does ipset do when you tell it to restore? Вы думаете, он работает также, как iptables? Восстановит данные?
Nothing of the sort — it performs a merge, and the old addresses remain; you do not close access.
We discovered the bug while testing isolation. Now, there is quite a complex system — instead of restore a temp is conducted create temp, then restore flush temp and restore temp. In the end, swap: for atomicity, because if conducted first flush And at that moment, if a package comes in, it will be discarded and something will go wrong. That's why there's a bit of black magic involved.
consul kv get -datacenter=other. As I mentioned earlier, we think we are requesting some data, but we will either get data or an error. We can do this through Consul locally, but even then both will freeze.
The local Consul client is a wrapper around the HTTP API. However, it just hangs and does not respond to Ctrl+C, Ctrl+Z, or anything else, only to kill -9 the adjacent console. We encountered this when building a large cluster. But we still have no solutions; we are preparing to fix this error in Consul.
Consul leader is unresponsive. The master in the data center is unresponsive; we think, 'Maybe the election algorithm will kick in now?'
No, it won't, and monitoring won't show anything: Consul will say that the commitment index exists, the leader is found, everything is fine.
How do we deal with this? service consul restart in cron every hour. If you have 50 servers, it's not a big deal. When you have 16,000, you'll understand how it works.
Conclusion
As a result, we gained the following advantages:
- 100% coverage of all Linux machines.
- Speed.
- Automation.
- Freed hardware and network engineers from servitude.
- Integration capabilities have become almost limitless: with Kubernetes, Ansible, or Python.
Cons: Consul, which we now have to live with, and the cost of errors is very high. For example, once at 6 PM (prime time in Russia), I was adjusting the network lists. We were just building isolation on BEFW then. I made a mistake somewhere, I think, I specified the wrong mask, and everything crashed in two seconds. The monitoring lights up, the on-call support rushes in: 'Everything is down!' The department head turned gray when explaining to the business why it happened.
The cost of errors is so high that we developed our own complex prevention procedure. If you're going to implement this in a large production environment, don't give the master token over Consul to everyone. It will end badly.
Cost. I wrote code for 400 hours alone. My team of 4 spends 10 hours a month supporting everyone. Compared to the cost of any next-gen firewall, this is free.
Plans. The long-term plan is to find an alternative transport to replace or supplement Consul. It might be Kafka or something similar. But in the coming years, we'll be living with Consul.
Upcoming plans include integration with Fail2ban, monitoring, nftables, and possibly other distributions, metrics, enhanced monitoring, and optimization. Support for Kubernetes is also on the horizon, as we currently have several clusters and a desire for this capability.
Additional plans include:
- anomaly detection in traffic;
- network map management;
- Kubernetes support;
- package builds for all systems;
- Web-UI.
We are continuously working on expanding configurations, increasing metrics, and optimizing.
Join the project. It’s become amazing, but unfortunately, it’s still a one-person project. Come to and try to contribute: commit, test something, make suggestions, or provide your feedback.
In the meantime, we are preparing for , which will take place on April 6 and 7 in Saint Petersburg, and we invite developers of high-load systems . Experienced speakers already know what to do, while beginners are advised to at least . Being a speaker at the conference has several advantages. You can read about them, for instance, at the end of .
Source: habr.com
