

Developers of the Netfilter packet filtering and modification subsystem have released a set of patches that significantly accelerate the processing of large matching lists (nftables set), where checks for subnet combinations, network ports, protocol, and MAC addresses are required. The patches have already been accepted into the branch , which will be proposed for inclusion in the Linux 5.7 kernel. The most notable acceleration has been achieved due to AVX2 instructions (similar optimizations based on NEON instructions for ARM are planned for future publication).
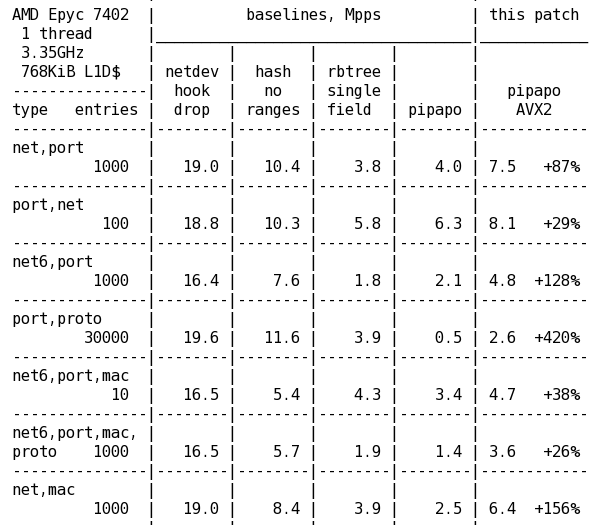
Optimizations have been made in the module (PIle PAcket POlicies), which addresses the task of matching packet content with arbitrary value ranges defined in filtering rules, such as ranges of IP and network ports (nft_set_rbtree and nft_set_hash handle interval matching and direct value mirroring). The vectorized version of pipapo using 256-bit AVX2 instructions on an AMD Epyc 7402 processor showed a performance increase of 420% when parsing 30,000 entries that included port-protocol pairs. The increase for matching subnet-port pairs when parsing 1,000 entries was 87% for IPv4 and 128% for IPv6.
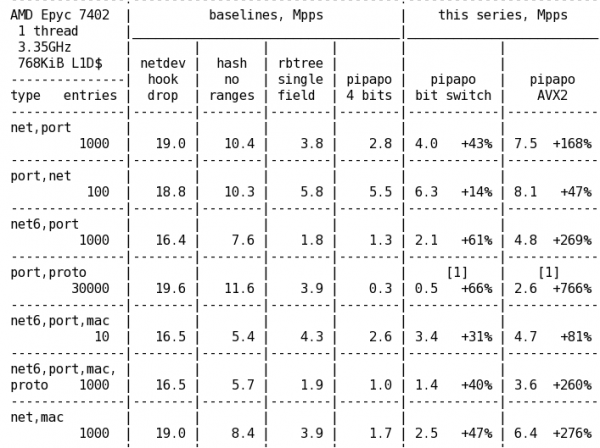
Another optimization that allows the use of 8-bit matching groups instead of 4-bit ones also showed a significant performance gain: 66% when parsing 30,000 port-protocol entries, 43% for subnet_IPv4-port, and 61% for subnet_IPv6-port. In total, considering the AVX2 optimizations, the performance of pipapo increased in the specified tests by 766%, 168%, and 269% respectively. The characteristics obtained for complex matchings outperform single field checks in (except for the port+protocol pair test), but still lag behind direct checks using and drop handlers based on netdev.
Source: opennet.ru
