

Let me explain the title of the article right away. Initially, the plan was to provide good, reliable advice on speeding up reflection usage with a simple, yet realistic example. However, during benchmarking, it turned out that reflection doesn’t work as slowly as I thought, while LINQ works slower than I had dreamed in nightmares. Moreover, I made a mistake in the measurements... Details of this life story are below and in the comments. Since the example is quite ordinary and implemented as it usually is done in enterprise, it turned into an interesting demonstration of life: the influence on the speed of the primary subject of the article was not noticeable due to external logic: Moq, Autofac, EF Core, and other
I started working under the impression of this article:
As you can see, the author suggests using compiled delegates instead of direct calls to reflection type methods as an excellent way to significantly speed up application performance. There is also IL emission mentioned, but I would like to avoid it, as it is the most labor-intensive way to accomplish the task, fraught with errors.
Considering that I have always held a similar opinion on the speed of reflection, I didn’t intend to seriously question the author’s conclusions.
I often encounter naive use of reflection in enterprise applications. A type is taken. Information about a property is retrieved. The SetValue method is called, and everyone is happy. The value has been set to the target field, and everyone is satisfied. The people involved are quite smart—seniors and team leads—writing their own extensions on object, based on such naive implementations of 'universal' mappers from one type to another. The essence is usually this: we take all fields, we take all properties, we iterate over them: when names of members match, we perform SetValue. Occasionally, we catch exceptions on misses where a certain property was not found in one of the types, but even here there is a solution to boost performance: Try/catch.
I have seen people reinventing parsers and mappers without being fully armed with information about how previously invented bicycles work. I have witnessed people hiding their naive implementations behind strategies, interfaces, and injections as if that would excuse the ensuing chaos. I turned my nose up at such implementations. In fact, I never measured any real performance leak, and whenever possible, I simply switched to a more 'optimal' implementation if I had the time. So, the first measurements discussed below seriously puzzled me.
I think many of you, while reading Richter or other ideologists, have encountered the entirely fair statement that reflection in code is a phenomenon that negatively impacts the performance of the application.
The reflection call forces the CLR to traverse assemblies in search of the necessary ones, pulling in their metadata, parsing them, and so on. Additionally, reflection during sequence traversal leads to the allocation of a large amount of memory. We consume memory, the CLR uncovers the GC, and then the stutters begin. This should be noticeably slow, believe me. Huge amounts of memory on modern production servers or cloud machines do not save you from high latency in processing. In fact, the more memory available, the higher the chance that you will NOTICE how the GC operates. Reflection is, in theory, just an unnecessary red flag for it.
Nevertheless, we all use both IoC containers and data mappers, the principles of which are also based on reflection, yet questions about their performance usually do not arise. No, not because dependency injection and abstraction from models in a restrictive external context are such essential things that we have to sacrifice performance regardless. It's simpler than that – they truly do not significantly impact performance.
The fact is that the most common frameworks based on reflection technology use various tricks for more optimal operation. Typically, this involves caching. Usually, it includes Expressions and delegates compiled from expression trees. The same automapper maintains a concurrent dictionary that maps types to functions that can convert one to another without calling reflection.
How is this achieved? Essentially, it's not different from the logic that the platform itself uses for JIT code generation. Upon the first invocation of a method, it gets compiled (and yes, this process is not fast), and on subsequent calls, control is passed to the already compiled method, resulting in no significant performance drops.
In our case, we can also utilize JIT compilation and then employ the compiled behavior with the same performance as its AOT counterparts. Expressions will aid us in this matter.
The principle being discussed can be briefly summarized as follows:
It is advisable to cache the final result of reflection work in the form of a delegate containing the compiled function. All necessary objects with type information should also be cached in fields external to your type's objects – the worker.
There is logic in this. Common sense tells us that if something can be compiled and cached, it should be done.
To jump ahead, it should be noted that caching in reflection work has its advantages, even without using the proposed expression compilation method. Here, I will simply reiterate the points of the article I refer to above.
Now about the code. Let's consider an example based on my recent challenges faced in a serious production environment of a significant credit organization. All entities are fictional to prevent any guesses.
There is a certain entity. Let's call it Contact. There are emails with a standardized body, from which the parser and hydrator create these contacts. An email arrives, we read it, parse it into key-value pairs, create a contact, and save it to the database.
This is straightforward. Suppose a contact has properties like Full Name, Age, and contact phone number. This data is passed in the email. The business also wants support teams to be able to quickly add new keys for mapping entity properties to pairs in the email body. This is in case someone made a typo in the template, or if there's a need to urgently launch new mapping from a new partner before the release, adapting to a new format. Then we can add a new mapping correlation as a simple data fix. In other words, a real-life example.
We implement and create tests. It works.
I won't provide the code: there are many source files, and they are available on GitHub via the link at the end of the article. You can download them, torture them unrecognizably, and measure how it would affect your case. I'll just provide the code for two template methods, which distinguish the hydrator that was supposed to be fast from the one that was supposed to be slow.
The logic is as follows: the template method receives pairs formed by the base logic of the parser. The LINQ level is the parser and the basic logic of the hydrator, which queries the database context and matches keys with pairs from the parser (there is code without LINQ for comparison for these functions). Then the pairs are passed to the main hydration method, and the property values are set to the corresponding entity properties.
“Fast” (Fast prefix in benchmarks):
 protected override Contact GetContact(PropertyToValueCorrelation[] correlations)
        {
            var contact = new Contact();
            foreach (var setterMapItem in _proprtySettersMap)
            {
                var correlation = correlations.FirstOrDefault(x => x.PropertyName == setterMapItem.Key);
                setterMapItem.Value(contact, correlation?.Value);
            }
            return contact;
        }
As we can see, a static collection with property setters is used – compiled lambdas calling the entity setter. They are created with the following code:
        static FastContactHydrator()
        {
            var type = typeof(Contact);
            foreach (var property in type.GetProperties())
            {
                _proprtySettersMap[property.Name] = GetSetterAction(property);
            }
        }

        private static Action GetSetterAction(PropertyInfo property)
        {
            var setterInfo = property.GetSetMethod();
            var paramValueOriginal = Expression.Parameter(property.PropertyType, "value");
            var paramEntity = Expression.Parameter(typeof(Contact), "entity");
            var setterExp = Expression.Call(paramEntity, setterInfo, paramValueOriginal).Reduce();

            var lambda = (Expression<Action>)Expression.Lambda(setterExp, paramEntity, paramValueOriginal);

            return lambda.Compile();
        }
In general, it's clear. We go through the properties, create delegates that call setters, and save them. Then we invoke them when needed.
“Slow” (Slow prefix in benchmarks):
        protected override Contact GetContact(PropertyToValueCorrelation[] correlations)
        {
            var contact = new Contact();
            foreach (var property in _properties)
            {
                var correlation = correlations.FirstOrDefault(x => x.PropertyName == property.Name);
                if (correlation?.Value == null)
                    continue;

                property.SetValue(contact, correlation.Value);
            }
            return contact;
        }
Here we immediately iterate through the properties and directly call SetValue.
To illustrate and as a benchmark, I implemented a naive method that directly writes the values of their correlation pairs into the entity fields. The prefix is – Manual.
Now let's take BenchmarkDotNet and examine performance. And suddenly… (spoiler – this is not the correct result, details below)
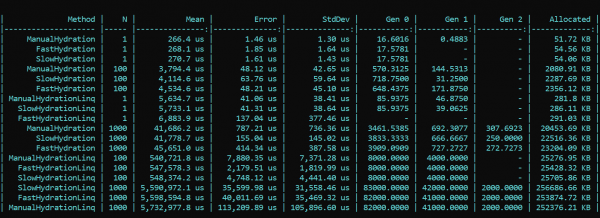
What do we see here? The methods triumphantly bearing the Fast prefix turn out to be slower than the methods with the Slow prefix in almost all runs. This holds true for both allocation and execution speed. On the other hand, a beautiful and elegant mapping implementation using LINQ methods wherever possible significantly drains performance. The difference is substantial. The trend does not change with different numbers of passes. The difference is only in scale. With LINQ, it is 4 – 200 times slower, and garbage is produced in roughly the same proportions.
UPDATED
I couldn't believe my eyes, but more importantly, neither could our colleague — . After double-checking my solution, he brilliantly identified the error that I missed due to various changes in the implementation from start to finish. After fixing the bug found in the configuration of Moq, all results fell into place. According to the retest results, the main tendency remains unchanged — LINQ still affects performance more significantly than reflection. However, it is nice that working with Expression compilation is not in vain, and the result is evident in both allocation and execution time. The first run, when static fields are initialized, is understandably slower for the 'fast' method, but the situation changes afterward.
Here are the retest results:
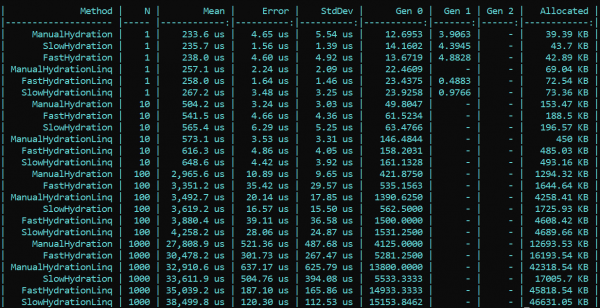
Conclusion: When using reflection in the enterprise, there is no need for special tricks — LINQ will consume performance more significantly. Nevertheless, in highly loaded methods requiring optimization, you can retain reflection in the form of initializers and delegate compilers that will later provide 'fast' logic. This way, you can maintain both the flexibility of reflection and the speed of application performance.
The code with the benchmark is available here. Everyone interested can verify my claims:
PS: The code in tests uses IoC, while in benchmarks, it uses an explicit construct. The thing is, in the final implementation, I removed all factors that could affect performance and cloud the results.
PPS: Thanks to the user for pointing out my mistake in Moq configuration, which affected the initial measurements. If any of the readers have enough karma, please give him a like. He took the time, he dove into it, he double-checked, and pointed out the error. I believe this deserves respect and appreciation.
PPPS: Thanks to that meticulous reader who critiqued the style and formatting. I'm for uniformity and convenience. The diplomacy of the presentation leaves much to be desired, but I have taken the criticism into account. Onward!
Source: habr.com
