

In SQL, you describe 'what' you want to get, not 'how' it should be executed. Therefore, the problem of developing SQL queries in a 'write as you hear' style holds its honored place, alongside .
Today, through very simple examples, we will see what this can lead to in the context of using GROUP/DISTINCT and LIMIT along with them.
If you wrote in the query 'first join these tables, and then discard all duplicates, only one instance per key should remain' — that's exactly how it will work, even if the join wasn't necessary at all.
And sometimes you get lucky, and it 'just works'; other times, it negatively impacts performance, and sometimes it yields completely unexpected effects from a developer's perspective.
Well, perhaps not as spectacular, but…
'The sweet pair': JOIN + DISTINCT
SELECT DISTINCT
  X.*
FROM
  X
JOIN
  Y
    ON Y.fk = X.pk
WHERE
  Y.bool_condition;
It's pretty clear that you want to select those records of X for which there are related Y entries that meet the condition. You wrote the query using— you got some pk values multiple times (exactly as many as there are matching records in Y). How do you remove them? Of course, JOIN especially 'delights' when each X record finds several hundred related Y records, and then duplicates are heroically removed… DISTINCT!
How to fix it? First, realize that the task can be modified to
'select those X records for which there is AT LEAST ONE related Y record that meets the condition' — after all, we don't need anything from the Y record itself. Nested EXISTS
SELECT * FROM X WHERE EXISTS( SELECT NULL FROM Y WHERE fk = X.pk AND bool_condition LIMIT 1 );
Some versions of PostgreSQL understand that in EXISTS, finding the first matching record is enough; older versions do not. Therefore, I prefer always to specify LIMIT 1 LATERAL JOIN inside EXISTS.
SELECT X.* FROM X , LATERAL ( SELECT Y.* FROM Y WHERE fk = X.pk AND bool_condition LIMIT 1 ) Y WHERE Y IS DISTINCT FROM NULL;
This version also allows you to return some data from the found related Y record if needed. A similar option is discussed in the article'PostgreSQL Antipatterns: a rare record will make it halfway through the JOIN' .
"Why pay more": DISTINCT [ON] + LIMIT 1
An additional advantage of such query transformations is the ability to easily limit the iteration of records if only one/several of them are needed, as in the following case:
SELECT DISTINCT ON(X.pk)
  *
FROM
  X
JOIN
  Y
    ON Y.fk = X.pk
LIMIT 1;
Now let's read the query and try to understand what the DBMS is being asked to do:
- we're joining tables
- uniquing by X.pk
- from the remaining records, we're selecting one
So what do we have? "Some record" from the unique ones — but if we take this one from the non-unique ones, will the result change in any way?.. "If there’s no difference, why pay more?"
SELECT
  *
FROM
  (
    SELECT
      *
    FROM
      X
    -- here we can add suitable conditions
    LIMIT 1 -- +1 Limit
  ) X
JOIN
  Y
    ON Y.fk = X.pk
LIMIT 1;
And the same topic with GROUP BY + LIMIT 1.
"I just need to ask": implicit GROUP + LIMIT
Such things arise during various non-emptiness checks of a table or CTE during query execution:
...
CASE
  WHEN (
    SELECT
      count(*)
    FROM
      X
    LIMIT 1
  ) = 0 THEN ...
Aggregate functions (count/min/max/sum/...) work successfully over the entire set, even without explicit indication GROUP BY. However, they do not work well with LIMIT .
The developer might think "If there are records, I just need a LIMIT not larger than that."But you shouldn't think that way! Because for the database, it means:
- calculate what is needed return as many rows as requested
- Depending on the target conditions, one of the following substitutions would be appropriate:
(count + LIMIT 1) = 0
NOT EXISTS(LIMIT 1)to(count + LIMIT 1) > 0EXISTS(LIMIT 1)tocount >= N(SELECT count(*) FROM (... LIMIT N))to"How much to weigh in grams": DISTINCT + LIMIT
SELECT DISTINCT pk FROM X LIMIT $1
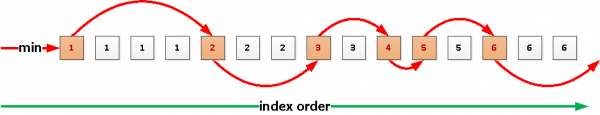
An inexperienced developer may sincerely believe that the query execution will stop,as soon as we find $1 first different values. In the future, it may indeed work this way thanks to a new node,.
Index Skip Scan, the implementation of which is currently being worked on, but for now — it does not.Currently, first
all records will be extracted, uniqued, and only then will the requested amount be returned. It's especially disappointing if we wanted something like, but there are hundreds of thousands of records in the table... $1 = 4To avoid unnecessary disappointment, we can use a recursive query
"DISTINCT for the impoverished" from PostgreSQL Wiki. :
Source: habr.com
