

by St-Pete
Hello everyone! I am Mons Anderson, platform architect, , and I will tell you how we built our S3 storage, how it works, what solutions worked well, and what we would change if we started the same project from scratch today.
This article is based on a presentation at the by Mail.ru Cloud Solutions & Tarantool. In this article, we will discuss:
- how Mail.ru's storage was structured, on top of which we built the S3 storage;
- what we added to create Mail.ru Cloud Storage;
- how the object storage model works and what steps were taken to go into production;
- the improvements to the production system: failover and scaling;
- how we implemented sharding and resharding;
- as well as working with SSL certificates.
If you do not want to read, you can .
How Mail.ru's storage was structured, on top of which we built the S3 storage
The development of our S3 began on top of Mail.ru's cloud storage, so it is important to first explain how it is structured and what it can do.
Mail.ru's cloud storage consists of servers with disks. On average, a modern storage server has 36 disks of 12-14 terabytes each. Previously, the disks were smaller, but in three years, disk volumes have increased, and today it is almost half a petabyte of raw data.
Disks from different storage servers are combined into so-called 'pairs'. A pair is a single unit for storing files. Essentially, it is a disk mounted in a specific partition with a specific path, where files identified by hashes can reside.
The term pair is a historical name that has persisted to this day, although now a pair does not necessarily consist of only two disks. There can be three disks, and hybrid storage can also be used, for example, 3/2.
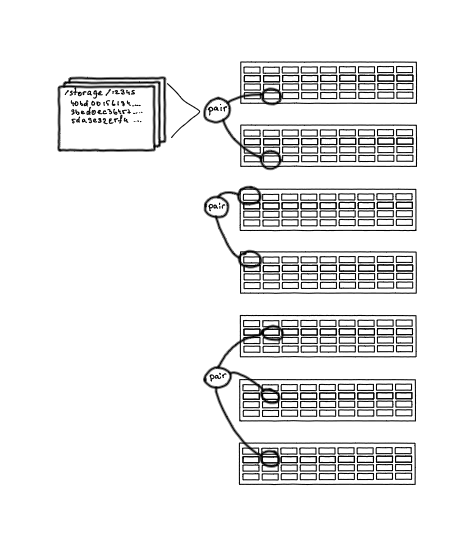
Pairs (pair) are units of object storage
All pairs are stored in PairDB — an application based on Tarantool. All databases in our storage, starting from the earliest ones, are Tarantool; we do not use other databases.
PairDB stores all pairs, their states, free space, failover capabilities, and the latest errors. It can also independently query pairs, update their status, and check whether they are operational. In other words, PairDB provides an overall snapshot of the state of all disks in our system.
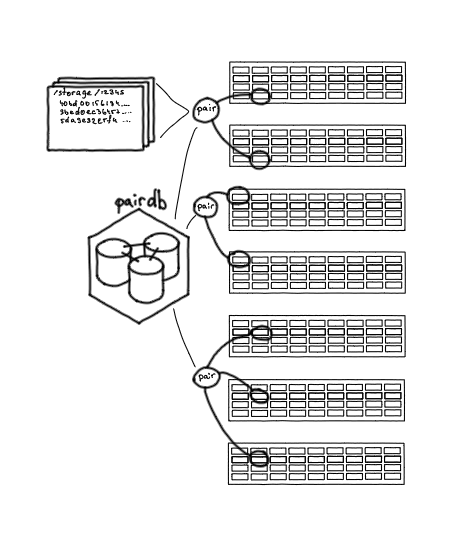
Pair DB: a database with the state of pairs
Pairs store files, and to know which file is located on which pair, another database is needed — FileDB. It stores the mapping, defining the correspondence: this particular file is stored on this particular pair, along with a small number of necessary attributes.
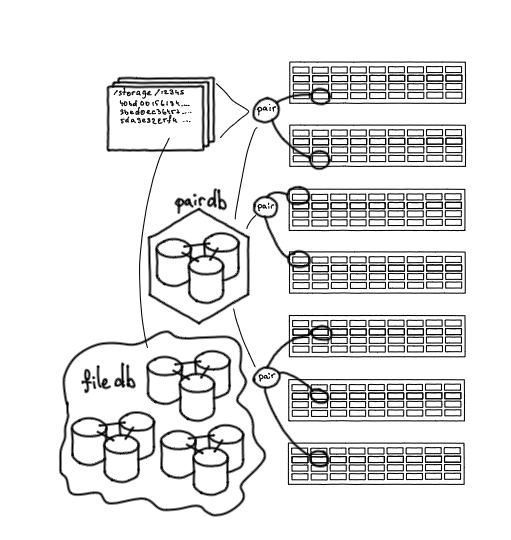 File DB: the place where the file is stored
Another important link is the Nylon service, a router for working with databases. It serves as a single entry point, allowing operations through a single interface with both PairDB and FileDB. It is a stateless service that balances requests, understands which shard of FileDB to access, and knows which pairs are active and which are not.
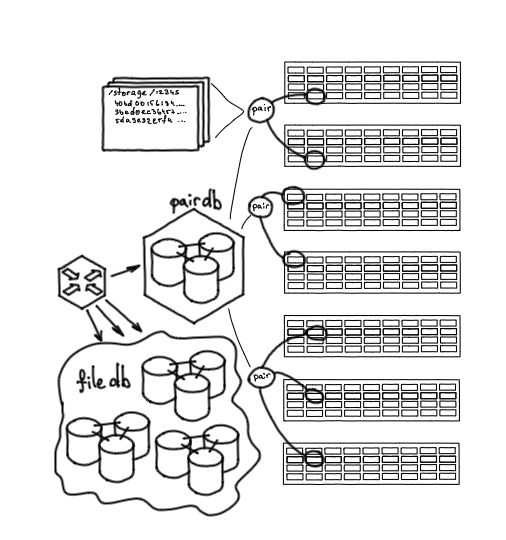
Nylon: router for working with databases
Content also needs to be placed in the storage somehow. For this, there is a service called Streamer. It provides two HTTP methods: the PUT method to upload content to the storage, and the GET method to retrieve it. HTTP is a quite popular and convenient protocol for data transmission.
When we query Streamer, it accesses PairDB through Nylon, determines which pair can hold the file, and then sends the data via WebDAV to that pair.
Essentially, any storage server is nginx plus disks mounted at specified paths. We can upload a file to the storage using Streamer, delete it, rename it, or check its integrity. This means it's a convenient interface for low-level interaction with the storage.
Streamer: entry point to the storage
What we've added to create S3 storage
So, we reviewed the general basic structure of the storage at the moment we planned to launch S3 storage. Using the PUT method, we could place arbitrary content there and receive a hash as an identifier for that data. With this identifier, one could later come and retrieve the original file. But this is not enough for S3 implementation. In the S3 protocol, in addition to storing objects, there are:
- metadata storage — additional properties of objects;
- organization of access to objects via HTTP;
- grouping objects into collections — buckets;
- HTTP-S3 Endpoint. S3 organizes data into specific structures — buckets, each of which provides an entry point for storing files.
To implement this logic, a separate service was needed. We also wanted to immediately consider an architecture for the future growth of the service with linear scalability.
The first components
A daemon implementing the S3 API. This is the standard Amazon S3 API, which supports XML for metadata and allows direct content transfer. We didn’t have to invent anything; it’s all described and documented.
We also put Nginx in front of the service. We used it for SSL termination, load balancing, as well as for some logic in Lua (metrics, logging, and tracing).
For storing S3 metadata, we also chose Tarantool. In the first version, the S3 daemon accessed this database for metadata, while the actual content was stored in a large repository via Streamer.
Nginx + S3 API + metadata
Object storage model
Let’s look at how S3 works. A user can create a bucket — a collection of objects. The bucket is addressed by the hostname and is a subdomain of the service. Within a bucket, a user can create objects. The object identifier will be the URL. The content of the object is a blob, an array of binary data that we will store in the repository. The object also has attributes: a name — the URL itself, ACL (access control list), and other additional or arbitrary attributes — all of this is stored in metadata.
The normalized schema of this data might look like this: there are projects that own buckets, which, in turn, own objects, and objects can be composite. Since one of the ways to upload an object is in parts, there are two auxiliary tables for uploading: uploads and chunks. Projects also have credentials for access and billing.
Data schema
Since we were creating a B2B service with paid access, this schema required billing.
We also implemented the billing service on Tarantool.
Improvements to the S3 storage: steps to production
We already have a functioning model that can be used: objects and metadata were stored, but a few aspects were missing for production release.
Firstly, the rate-limiting system. If we launch the service without it, we could unpredictably overload some part of the system during peak stress. The rate limit should work as follows: any S3 request comes to a specific host, this host is the identifier of the bucket, and the bucket belongs to a specific client. We need to define a function based on the bucket that would allow us to calculate the rate limit.
Moreover, the rate-limiting system must be efficient enough to handle the load that comes to S3.
Here, we used Tarantool again. The rate limits are a cluster of 21 instances, with instances divided into groups, spread across three physical nodes, and combined into a large topological cluster. Configuration changes automatically propagate across it: rate limits are set, defaults are configured, and configurations are established. Each bucket is served strictly by one instance. When a request comes to a specific bucket, the instance responsible for that bucket is computed. Within this node, the current request rate is calculated using an algorithm similar to Token Bucket. Then the rate-limiting system, based on current load indicators and properties set for the specific bucket, decides whether the request can be executed or not. Limit checks are performed at the earliest stage of S3 request execution, protecting all other system components from excessive load.
Additionally, it's quite difficult to manage under load without a cache. S3 assumes multiple accesses to the same objects, making it a hot storage. Normally, accessing a single file involves a full chain: Streamer, FileDB, PairDB, Storage. However, with multiple accesses to a file, we optimize access to this content with the help of a local cache.
The cache is multi-layered and implemented using nginx, local SSDs, and RAM disks. Here, we didn't use Tarantool because serving objects from the file system is more convenient, allowing us to perform cache tiering. Additionally, we have large objects with a maximum size of 32 gigabytes, and in Tarantool, you can only cache small objects.
This is the first system we launched, which had some calculated capacity, enough for exploring and understanding the product and ensuring its functionality.
Enhancements to the operational system: failover and scaling
The system was already in action, but at the start we missed something — we needed to add failover and scaling.
Our S3 daemon fetched metadata using the Tarantool protocol. We replaced the original database with Tarantool, which served as a proxy router for metadata requests. From the application's perspective implementing the API, nothing changed — it continued to communicate with the database via the Tarantool protocol, but the router was able to provide active failover. This allowed us to check node availability, manage delays during switches and failures, and so on. We did not modify the application itself.
More about how we implemented sharding
The next issue we had to address was sharding. The system was growing, the number of objects was increasing, and we needed to ensure capacity for further growth.
Returning to the data schema: there are projects, buckets, credentials, and billing. These are objects that are unlikely to exceed a single instance in volume or requests in the foreseeable future. Therefore, there’s no point in sharding them, and we moved them to a separate instance, which will remain unsharded. This allows for more consistent management of projects and buckets, as there is a single unsharded point.
There are also objects in the schema that grow linearly — initially there were hundreds of thousands, and now their number is measured in billions. Such objects and their parts needed to be moved to a sharded cluster.
We separated the schema, but objects need to work with buckets: each object always belongs to a specific bucket, and an ACL operates on the bucket. Therefore, for each shard with objects, we maintain a shadow copy of each bucket. Additionally, during object modifications and request processing, we need to count the volume for billing purposes, so each shard has billing counters.
We also added several more tables and components:
- a trash bin for deleting old projects that are removed or frozen;
- a queue for background tasks, meaning the main storage can perform background tasks that need to be done on the cluster;
- lifecycle support — a mechanism that allows you to work with objects and manage their lifecycle.
Since part of the data was moved to shards, a sharding proxy was needed. While we could have reused the router for this role, a separate sharding proxy that only handles data sharding allows the router to fetch data as a whole without worrying about sharding.
I'll explain separately why we didn't choose a ready-made solution, but wanted to create a custom sharding function.
Let's see how it works. We have 256 available shards. For each bucket, we allocate a range using a consistent function. This is straightforward — just as you determine the membership of a shard using a consistent function, you define the starting shard and allocate a range:
f(bucket, shards) = subset
This means that if you take a bucket, you can say that it and its data will always reside in a specific subset of all shards. This reduces the impact of one bucket on another and simplifies the operation of map-reduce queries, when you need to, for example, list bucket objects. For this, you need to poll all the shards where these objects are stored. If the objects were on all shards, any listing would impact the entire system, while here it only affects a specific subset.
Next — each object belongs to a specific bucket, so when we request an object, we are requesting an object by name in a specific bucket. This means we can define a function for an object not across the entire available shard range, but only from the subset of its bucket:
f(object, subset) = shard
We take a specific object, pass not all shards as function arguments, but a subset of its bucket — and get the specific shard.
Thus, sharding is implemented, and there is a sharding proxy. Next, we just need to make the router and the metadata database access the sharding proxy. For example, for creating shadow copies of objects — when we create a bucket, the main storage should create a representative of this bucket on all shards where it should be present.
How we implemented reshaping
The biggest challenge of sharding is resharding. It was crucial for us to implement it without downtime since the system was already in production. I'll demonstrate how we solved the problem using a similar task of live data migration from one project to another.
Below is the diagram of our cluster that emerged after implementing sharding. We have nginx, S3 API, a router, a primary database with projects, a sharding proxy, and the shards themselves.
Earlier, I overlooked the fact that at a certain stage of the project, there was a product task: "Launch another storage, Icebox, similar to Hotbox, but for cold data." Essentially, it's the same storage, but under different URLs and without caches.
Icebox was used less than Hotbox, so it went quite a long time without any sharding. Ultimately, we decided to eliminate it and combine Hotbox and Icebox into one service by simply separating the storage classes.
The buckets in the storages did not overlap; they could be easily merged and moved. However, clients used both storages, so we needed to solve the issue of maintaining zero downtime. We couldn't just turn off and copy. We carried out migration in several stages.
Initially, we synchronized the primary storages. We had Tarantool, and when creating an object, we could do the following:
- A request comes to the database to create a bucket, for example in Hotbox;
- Tarantool checks in another database (in this case, Icebox) to ensure that such a bucket doesn't already exist;
- If the bucket exists, the database indicates that it cannot be created, and it is synchronized as an existing bucket.

Bucket Synchronization
In the storage that was supposed to receive all the data, we introduced a label for projects and buckets that indicated where this object was stored. It could be stored locally, meaning in Hotbox, in Icebox—then no data exists from it in the new storage—or it could be in a state of migration.
If a project or bucket was marked as Migrating, during migration, the request was first executed in the new storage where the data should reside. If it was not there, the requests were redirected to the alternative storage.
Next, we switched the traffic. Since the API could serve requests for both Icebox and Hotbox, we managed to switch the traffic without downtime by simply moving the hosts and adding the corresponding records in Nginx.
After the traffic was redirected, Nginx and the Icebox API could be removed.
Then we removed Icebox nginx and S3 API — and everything worked:
Next, we launched a background migration process that runs inside the database — it iterates over all projects and their buckets, marking them as Migrating, transferring data, and upon completion of the transfer, marking them as Local.
After the data transfer, we no longer need the old storage, and we remove the remaining parts of the old system, as well as remove support for migration status from the code.
The resharding from the old storage to the sharded one was done on the same principles:
- All buckets were marked as
Non-sharded. All requests to them went to the original, non-sharded storage. - New buckets were created immediately in the status of
Sharded. - Buckets were taken one by one, marked as
Migrating, and data was transferred.
Requests were serviced with the principle:
- First read from the new, then from the old.
- Create only in the new.
- We update in two phases: if the new one doesn’t have it, transfer from the old to the new, then update.
Working with SSL certificates
On the front end, we use Nginx. In our case, this is not regular Nginx, but OpenResty, Nginx with LuaJIT support.
Another part of the system is working with SSL certificates. In S3 storage, you can set your own domain to access a specific bucket, simply using CNAME. But HTTPS is essential today: your own domain implies your own SSL certificate.
As I mentioned, Nginx is responsible for load balancing and SSL termination. In our case, this is not regular Nginx, but OpenResty, Nginx with LuaJIT support.
This allowed us to easily teach our Nginx to serve arbitrary certificates. Moreover, it was necessary to serve certificates dynamically (without needing to specify them in the configuration file). We used the extension ssl_certificate_by_lua, which allows reading the certificate from an arbitrary source directly during the TLS handshake. For the certificate storage, we also used Tarantool: this allows managing certificates externally and ensures extremely fast delivery.
A separate daemon was also implemented, tasked with regularly updating certificates that were issued using Let’s Encrypt.
What I would have kept and what I would have done differently if I were to develop the storage from scratch
What should have been used from the very beginning
Sharding right away. Resharding caused quite a few problems. It’s easy to do, but nevertheless, if starting projects that need to scale, it’s better to use a sharded cluster from the start, even with minimal nodes. Implementing sharding at the outset is almost free compared to introducing sharding into a working system.
Working with Tarantool through load balancers. Now we connect all new databases directly through load balancers. This allows us to expand functionality and achieve higher fault tolerance.
Auto-failover. I would have installed all the tools required for auto-failover, as the first failures after launch were related to its absence. After the experience with S3, all subsequent products were launched with this in mind.
S3 feature 'Versioning'. Initially, it seemed that this was not a highly demanded feature. Integrating this capability into the architecture of a working system is extremely challenging.
Separate billing. The way we integrated billing into our system worked well at first, but later it became a hindrance; it would have been better to implement it as a completely separate service.
What was a successful solution
Data model. History has shown that as the service evolved, we matched Amazon's data model quite accurately, allowing us to implement features that exist there.
Sharding scheme. I would support similar range sharding by buckets, as this allows for good distribution of requests from different buckets across a large cluster.
Using Tarantool. Tarantool greatly assisted in the development and modification of the service; we worked easily with data, transformed it, and sharded the storage without needing to elevate to the application layer.
This presentation was first given at by Mail.ru Cloud Solutions&Tarantool. See other presentations and subscribe for event announcements on Telegram .
You can also check out my old presentation on S3 or read my colleague's article on block storage.
- .
- .
Source: habr.com
