

Note: translation.: the authors of this article are engineers from a small Czech company called pipetail. They have managed to compile a remarkable list of [sometimes trivial, yet still] highly relevant issues and misconceptions associated with the operation of Kubernetes clusters.
Over the years of using Kubernetes, we have had the opportunity to work with a large number of clusters (both managed and unmanaged — on GCP, AWS, and Azure). Over time, we began to notice that some mistakes keep repeating themselves. However, there is nothing to be ashamed of: we have made most of them ourselves!
This article compiles the most common mistakes and discusses how to fix them.
1. Resources: Requests and Limits
This point definitely deserves the closest attention and the top spot on the list.
CPU requests are usually either not set at all or set to very low values (to fit as many pods as possible on each node). As a result, the nodes become overloaded. During high loads, the processing power of the node is fully utilized, and a specific workload only gets what it has 'requested' through CPU throttling. This results in increased latency in the application, timeouts, and other unpleasant consequences. (For more details on this, read another recent translation of ours: '” — ed. note)
BestEffort (highly do not recommended):
resources: {}Extremely low CPU requests (highly do not recommended):
   resources:
      Requests:
        cpu: "1m"
On the other hand, having a CPU limit can lead to unnecessary throttling of pods, even if the node's CPU is not fully loaded. Again, this can lead to increased latency. There are ongoing debates regarding the CPU CFS quota in the Linux kernel and CPU throttling depending on set limits, as well as disabling the CFS quota… Unfortunately, CPU limits can cause more problems than they solve. More information can be found at the link below.
Excessive allocation (overcommitting) of memory can lead to larger problems. Hitting the CPU limit results in throttling, while reaching the memory limit results in the 'killing' of a pod. Have you ever observed OOMkill? Да, речь идет именно о нем.
Want to minimize the likelihood of this event? Do not allocate excessive memory and use Guaranteed QoS (Quality of Service) by setting the memory request equal to the limit (as shown in the example below). Read more about this in (lead engineer at Zalando).
Burstable (higher chance of getting OOM killed):
   resources:
      requests:
        memory: "128Mi"
        cpu: "500m"
      limits:
        memory: "256Mi"
cpu: 2Guaranteed:
   resources:
      requests:
        memory: "128Mi"
        cpu: 2
      limits:
        memory: "128Mi"
        cpu: 2
What can potentially help when configuring resources?
Using metrics-server can show the current CPU consumption and memory usage of pods (and containers within them). You are likely already using it. Just execute the following commands:
kubectl top pods
kubectl top pods --containers
kubectl top nodes
However, they only show current usage. They can give a rough idea of the order of magnitudes, but in the end, you will need historical metric changes over time (to answer questions like: "What was the peak CPU load?", "What was the load yesterday morning?" — etc.). For this, you can use Prometheus, DataDog and other tools. They simply retrieve metrics from the metrics-server and store them, allowing users to request them and build corresponding graphs.
, rather than taking focus. automate this process. It tracks the history of CPU and memory usage and adjusts requests and limits based on that information.
Effectively utilizing computing resources is a challenging task. It's like constantly playing Tetris. If you are overpaying for computing power with low average consumption (say, around 10%), we recommend looking into products based on AWS Fargate or Virtual Kubelet. They are built on a serverless/pay-per-usage billing model, which can be cheaper under such conditions.
2. Liveness and readiness probes
By default, liveness and readiness checks in Kubernetes are not enabled. And they are sometimes forgotten to be turned on...
But how else can you trigger a service restart in case of a non-recoverable error? And how does the load balancer know that a pod is ready to accept traffic? Or that it can handle more traffic?
Often, these probes are confused with each other:
- Liveness — the liveness check, which restarts the pod in case of failure;
- Readiness — readiness checks are performed, and upon failure, they detach the pod from the Kubernetes service (this can be verified with
kubectl get endpoints) and no traffic is sent to it until the next check succeeds.
Both of these checks ARE PERFORMED THROUGHOUT THE ENTIRE LIFECYCLE OF THE POD. This is very important.
There is a common misconception that readiness probes are only initiated at startup so that the load balancer can determine that the pod is ready (Ready) and can start processing traffic. However, this is just one way to use them.
Another use case is to determine that the traffic to the pod is too high and overloading it (or the pod is performing resource-intensive computations). In this case, the readiness check helps reduce the load on the pod and 'cool' it down. A successful completion of the readiness check in the future allows to increase the load on the pod again. In this case (when the readiness probe fails), failing the liveness check would be quite counterproductive. Why restart a pod that is healthy and working hard?
Therefore, in some cases, the complete absence of checks is better than enabling them with incorrectly configured parameters. As mentioned earlier, if the liveness check mirrors the readiness check, then you are in big trouble. A possible solution is to configure , and aside.
Both types of checks should not fail when common dependencies crash, or else this will lead to a cascading (avalanche-like) failure of all pods. In other words, .
3. LoadBalancer for each HTTP service
Most likely, you have HTTP services in your cluster that you would like to expose to the outside world.
If you expose the service as type: LoadBalancer, its controller (depending on the service provider) will provision and negotiate an external LoadBalancer (not necessarily operating on L7, more likely on L4), and this may impact costs (external static IPv4 address, compute power, per-second billing) due to the need to create a large number of such resources.
In this case, it is much more logical to use a single external load balancer, exposing services as type: NodePort. Or, even better, deploy something like nginx-ingress-controller (or traefik), which will serve as the sole NodePort an endpoint connected to an external load balancer that will route traffic within the cluster using ingress-Kubernetes resources.
Other inter-cluster (micro)services interacting with one another can 'communicate' using services of type ClusterIP and the built-in service discovery mechanism via DNS. Just do not use their public DNS/IP as this can affect latency and lead to increased cloud costs.
4. Cluster autoscaling without considering its specifics
When adding or removing nodes from the cluster, do not rely on basic metrics such as CPU utilization on those nodes. Pod scheduling should take into account many limits, such as pod/node affinity, taints and tolerations, resource requests, QoS, etc. Using an external autoscaler that ignores these nuances can lead to problems.
Imagine a pod needs to be scheduled, but all available CPU capacity has been requested/taken, and the pod is stuck in the state Here are possible reasons (assuming that the scheduler is functioning normally):. The external autoscaler sees the average current CPU load (rather than requested) and does not trigger scaling (scale-out) — it does not add another node. As a result, this pod will not be scheduled.
At the same time, the reverse scaling (scale-in) — removing a node from the cluster — is always more challenging to implement. Imagine you have a stateful pod (with attached persistent storage). Persistent volumes are typically tied to a specific availability zone and are not replicated across the region. Thus, if the external autoscaler removes a node with this pod, the scheduler will not be able to schedule this pod on another node, as this can only be done in the availability zone where the persistent storage resides. The pod will get stuck in the state Here are possible reasons (assuming that the scheduler is functioning normally):.
Within the Kubernetes community, there is significant popularity in . It operates within the cluster, supports APIs from major cloud providers, takes into account all limitations, and can scale in the aforementioned scenarios. It is also capable of performing scale-in while preserving all set limitations, thereby saving costs (that would otherwise be spent on unused capacity).
5. Ignoring IAM/RBAC capabilities
Be cautious when using IAM users with permanent secrets for machines and applications.Organize temporary access using roles and service accounts (service accounts).
We often encounter situations where access keys (and secrets) are hardcoded in application configurations and where there is a neglect of secret rotation despite having access to Cloud IAM. Use IAM roles and service accounts instead of users where appropriate.
Forget kube2iam and go directly to IAM roles for service accounts (as described in the Štěpán Vraný):
apiVersion: v1
kind: ServiceAccount
metadata:
  annotations:
    eks.amazonaws.com/role-arn: arn:aws:iam::123456789012:role/my-app-role
  name: my-serviceaccount
  namespace: default
One annotation. Not too difficult, right?
Additionally, do not grant service accounts and instance profiles privileges admin and cluster-admin, unless they need them. This is a bit more complex to implement, especially in RBAC K8s, but definitely worth the effort.
6. Do not rely on automatic anti-affinity for pods
Imagine you have three replicas of a certain deployment on a node. The node fails, taking all replicas with it. Not an ideal situation, is it? But why were all replicas on one node? Isn't Kubernetes supposed to ensure high availability (HA)?!
Unfortunately, the Kubernetes scheduler does not inherently adhere to separation rules (anti-affinity) for pods. They need to be explicitly defined:
// опущено для краткости
      labels:
        app: zk
// опущено для краткости
      affinity:
        podAntiAffinity:
          requiredDuringSchedulingIgnoredDuringExecution:
            - labelSelector:
                matchExpressions:
                  - key: "app"
                    operator: In
                    values:
                    - zk
              topologyKey: "kubernetes.io/hostname"
That's it. Now pods will be scheduled on different nodes (this condition is checked only during scheduling, not during their operation — hence the requiredDuringSchedulingIgnoredDuringExecution).
Here we're talking about podAntiAffinity on different nodes: topologyKey: "kubernetes.io/hostname", — not across different availability zones. To achieve true HA, you’ll need to dive deeper into this topic.
7. Ignoring PodDisruptionBudgets
Imagine you have a production workload in a Kubernetes cluster. Periodically, nodes and the cluster itself must be updated (or decommissioned). PodDisruptionBudget (PDB) serves as a kind of guarantee agreement between cluster administrators and users.
PDB helps avoid service interruptions caused by a lack of nodes:
apiVersion: policy/v1beta1
kind: PodDisruptionBudget
metadata:
  name: zk-pdb
spec:
  minAvailable: 2
  selector:
    matchLabels:
      app: zookeeper
In this example, as a cluster user, you inform the administrators: "Hey, I have a zookeeper service, and no matter what you do, I want at least 2 replicas of this service to always be available."
You can read more about this .
8. Multiple users or environments in a shared cluster
Kubernetes namespaces (namespaces) do not provide strong isolation.
It is a common misconception that if you deploy a non-prod load in one namespace and a prod load in another, they will not affect each other… However, some level of isolation can be achieved through resource requests/limits, setting quotas, and defining priorityClasses. Some "physical" isolation in the data plane is provided by affinities, tolerations, taints (or node selectors), but this kind of separation is quite challenging to implement.
Those who need to run both types of workloads in one cluster will have to deal with the complexity. If such a need does not exist, and you can afford to set up another cluster (say, in a public cloud), it is better to do so. This will allow you to achieve a significantly higher level of isolation.
9. externalTrafficPolicy: Cluster
We often observe that all traffic into the cluster comes through a NodePort type service, for which the policy is set to externalTrafficPolicy: Cluster. This means that NodePort it is open on every node in the cluster, and any of them can be used to interact with the desired service (set of pods).
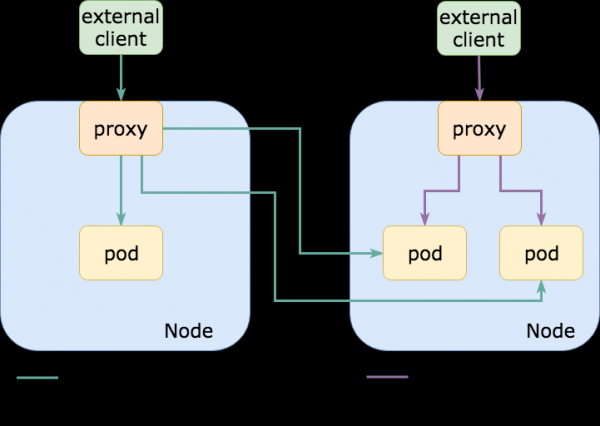
Meanwhile, the actual pods associated with the aforementioned NodePort service are usually only present on a certain subset of these nodes.In other words, if I connect to a node that doesn't have the required pod, it will redirect traffic to another node, adding a transit hop and increasing latency (if the nodes are in different availability zones/data centers, the latency can be quite high; moreover, egress traffic costs will increase).
On the other hand, if a Kubernetes service is specified with the policy externalTrafficPolicy: Local, then the NodePort is only opened on those nodes where the required pods are actually running. When using an external load balancer that checks the health (healthchecking) of endpoints (as does AWS ELB), it will send traffic only to the necessary nodes., which will positively affect latency, computational needs, egress costs (and common sense dictates the same).
There is a high probability that you are already using something like traefik or nginx-ingress-controller as an endpoint NodePort (or LoadBalancer, which also uses NodePort) for routing HTTP ingress traffic, and enabling this option can significantly reduce latency for such requests.
In you can learn more about externalTrafficPolicy, its advantages and disadvantages.
10. Do not get attached to clusters and do not abuse the control plane.
In the past, servers were commonly named after people: , HAL9000, and Colossus… Today, they have been replaced by randomly generated identifiers. However, the habit remains, and now proper names are assigned to clusters.
A typical story (based on real events): it all started with a proof of concept, and thus the cluster bore the proud name testing… Years have passed, and it is STILL used in production, and everyone is afraid to touch it.
There is nothing amusing about clusters becoming pets, so we recommend periodically deleting them while practicing disaster recovery (this can be aided by - translator's note)). Additionally, it wouldn't hurt to focus on the management layer (control plane). Being hesitant to touch it is not a good sign. Is Etcd down? Guys, you are in real trouble!
On the other hand, do not get too carried away with manipulations. Over time, the management layer can become slow.This is likely due to the large number of objects created without rotation (a common situation when using Helm with default settings, which causes its state in configmaps/secrets not to update — as a result, thousands of objects accumulate in the management layer) or constant editing of kube-api objects (for auto-scaling, for CI/CD, for monitoring, event logs, controllers, etc.).
Additionally, we recommend checking the SLA/SLO agreements with your managed Kubernetes provider and paying attention to the guarantees. The vendor may guarantee the availability of the management layer (or its subcomponents), but not the p99 latency of the requests you send to it. In other words, you can input kubectl get nodes, and you will only receive a response in 10 minutes, and this will not be considered a violation of the service agreement.
11. Bonus: using the latest tag
Now, this is already classic. Recently, we encounter this technique less often, as many, having learned from bitter experience, have stopped using the :latest and have begun to pin versions. Hooray!
ECR ; we recommend familiarizing yourself with this notable feature.
Summary
Don't expect everything to work with a wave of a magic wand: Kubernetes is not a panacea. A bad application (and may even get worse). Carelessness can lead to excessive complexity, slow, and strained operation of the control layer. Moreover, you risk lacking a disaster recovery strategy. Don't expect Kubernetes to ‘out of the box’ ensure isolation and high availability. Take some time to make your application truly cloud native.
You can learn about the unfortunate experiences of various teams in by Henning Jacobs.
Those wishing to contribute to the list of mistakes mentioned in this article can contact us on Twitter (, ).
P.S. from the translator
Also read in our blog:
- «»;
- «»;
- «» (overview and video presentation);
- «».
Source: habr.com
