

Hello, readers of Habr! In the previous article, we discussed a simple means of disaster recovery in AERODISK ENGINE storage systems—replication. In this article, we will delve into a more complex and interesting topic—the metro cluster, which is an automated disaster protection solution for two data centers, allowing them to operate in an active-active mode. We will explain, show, break, and fix.
As usual, we start with the theory
A metro cluster is a cluster distributed across several sites within a city or region. The word "cluster" clearly suggests that the complex is automated, meaning that failover occurs automatically in the event of node failures.
This is where the main distinction between a metro cluster and standard replication lies: automation of operations. In the event of various incidents (data center failure, link breakage, etc.), the storage system will autonomously perform the necessary actions to maintain data availability. In contrast, standard replicas require these actions to be performed wholly or partially manually by the administrator.
What is it needed for?
The primary goal that clients aim to achieve by using various implementations of a metro cluster is to minimize RTO (Recovery Time Objective). This means minimizing the downtime for IT services following a failure. When using standard replication, the recovery time will always exceed that of a metro cluster. Why? Quite simply. The administrator must be on site to manually switch the replication, while the metro cluster does this automatically.
If you do not have a dedicated on-call admin who doesn’t sleep, eat, smoke, or get sick, but is available 24/7 to monitor the state of the storage system, then there is no guarantee that the administrator will be available for manual switching during a failure.
Consequently, the RTO in the absence of a metro cluster or an immortal level 99 on-call administrator will be equal to the sum of the time taken to switch all systems and the maximum interval after which the administrator is guaranteed to begin working with the storage system and related systems.
Thus, we arrive at the obvious conclusion that a metro cluster should be used when the requirement for RTO is minutes, not hours or days. This means that in the event of the worst scenario with a data center outage, the IT department must ensure business access to IT services is restored within minutes, or even seconds.
Initially, a check is performed: does the client device support power via PoE? A voltage of 2.8 to 10 volts is supplied, and the input resistance is determined. If the results obtained are satisfactory for powering via PoE, the power device proceeds to the next stage.
At the lowest level, a metro cluster uses a synchronous data replication mechanism, which we described in the previous article (see ). Since the replication is synchronous, the requirements for it are accordingly strict, specifically:
- fiber optic as the physical medium, 10-gigabit Ethernet (or higher);
- a distance between data centers of no more than 40 kilometers;
- the optical channel latency between the data centers (between storage systems) must be up to 5 milliseconds (optimally 2).
All these requirements are advisory in nature, meaning the metro cluster will operate even if these criteria are not met. However, it’s important to understand that failure to comply with these requirements leads to reduced performance of both storage systems in the metro cluster.
So, for data transmission between storage systems, synchronous replication is used. How do replicas automatically switch, and most importantly, how do we avoid split-brain scenarios? For this, a higher-level entity—a quorum—is used.
How does the quorum work, and what is its role?
The quorum is a small virtual machine or hardware cluster that needs to be launched at a third site (for example, at the office) and must have access to the storage systems via ICMP and SSH. After launch, the quorum should establish an IP address, and then the storage systems should specify its address, along with the addresses of the remote controllers participating in the metro cluster. After that, the quorum is ready for operation.
The quorum continuously monitors all storage systems in the metro cluster, and in the event of any storage system becoming unavailable, it, after confirming the unavailability from another cluster participant (one of the 'live' storage systems), makes a decision to initiate the replication switch procedure and mapping.
A very important point. The quorum must always be located at a site different from those where the storage systems are located; that is, not in Data Center 1, where Storage System 1 is, nor in Data Center 2, where Storage System 2 is installed.
Why? Because this is the only way the arbiter, using one of the surviving storage arrays, can unambiguously and accurately determine the failure of either of the two sites where the storage arrays are installed. Any other placement of the arbiter may lead to split-brain scenarios.
Now let's delve into the details of the arbiter's operation.
Several services are running on the arbiter, which constantly poll all storage array controllers. If the polling result differs from the previous one (available/unavailable), it is recorded in a small database that also operates on the arbiter.
Let's examine the logic of the arbiter's operation in more detail.
Step 1. Determining unavailability. The signal event indicating the failure of a storage array is the absence of a ping from both controllers of one storage array for 5 seconds.
Step 2. Initiating the failover procedure. Once the arbiter realizes that one of the storage arrays is unavailable, it sends a request to the 'live' storage array to verify that the 'dead' storage array is indeed gone.
Upon receiving such a command from the arbiter, the second (live) storage array further checks the availability of the first failed storage array, and if it is not available, it sends confirmation back to the arbiter that its assumption was correct. The storage array is indeed unavailable.
After receiving such confirmation, the arbiter initiates a remote failover procedure for replication and raises the mapping on those replicas that were active (primary) on the failed storage array, and sends a command to the second storage array to make those replicas primary and raise the mapping. The second storage array then performs these procedures, after which it ensures access to the lost LUNs.
Why is additional verification needed? For quorum. That is, the majority of the total odd (3) number of participants in the cluster must confirm the failure of one of the cluster nodes. Only then will this decision be entirely correct. This is necessary to avoid erroneous failover and, consequently, split-brain scenarios.
Step 2 takes approximately 5 to 10 seconds, thus, considering the time required for determining unavailability (5 seconds), within 10 to 15 seconds after the failure, the LUNs from the failed storage array will be automatically available for operation with the live storage array.
It is clear that to avoid connection interruptions with hosts, one must also take care of properly configuring timeouts on the hosts. The recommended timeout is at least 30 seconds. This will prevent the host from breaking the connection with the storage system during load switching in case of a failure and ensure there are no disruptions in input-output operations.
Just a moment, if everything is so good with the metro cluster, why is ordinary replication even needed?
In fact, it’s not that simple.
Let’s consider the pros and cons of the metro cluster.
So, we understand that the obvious advantages of the metro cluster over regular replication are:
- Complete automation, ensuring minimal recovery time in case of a disaster;
- And that’s it :-).
And now, attention to the drawbacks:
- Cost of the solution. Although the metro cluster in Aerodisk systems does not require additional licensing (the same license as used for the replica is applied), the overall cost will still be higher than with synchronous replication. All requirements for the synchronous replica must be met, plus the requirements for the metro cluster that relate to additional switching and an additional site (see metro cluster planning);
- Complexity of the solution. The metro cluster is significantly more complex than a regular replica and requires much more attention and effort in planning, setup, and documentation.
In conclusion. The metro cluster is undoubtedly a very technological and good solution when you really need to ensure RTO in seconds or minutes. But if such a task is not there, and RTO in hours is acceptable for the business, then there is no sense in overkill. Regular workhorse replication is sufficient, as the metro cluster will cause additional costs and complicate the IT infrastructure.
Metro cluster planning
This section does not claim to be a comprehensive guide to designing a metro cluster, but simply highlights the main areas to be worked on if you decide to build such a system. Therefore, in the actual implementation of the metro cluster, make sure to involve the storage system manufacturer (that is us) and other related systems for consultations.
Sites
As mentioned above, a metro cluster requires a minimum of three sites: two data centers where the storage systems and related systems will operate, and a third site where the arbitrator will function.
The recommended distance between the data centers is no more than 40 kilometers. A greater distance will likely cause additional delays, which are highly undesirable in a metro cluster. Note that delays should be up to 5 milliseconds, though ideally, they should be within 2.
Delays should also be checked during the planning process. Any reasonably established provider that offers fiber optics between data centers can organize a quality check fairly quickly.
Regarding delays to the arbitrator (i.e., between the third site and the first two), the recommended delay threshold is up to 200 milliseconds, which means a standard corporate VPN connection over the Internet will suffice.
Switching and Network
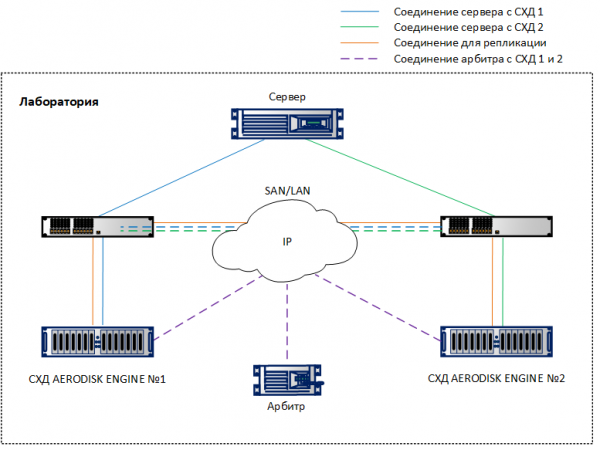
Unlike the replication scheme, where it suffices to connect storage systems from different sites, the metro cluster scheme requires connecting hosts to both storage systems at different sites. To clarify the difference, both schemes are illustrated below.
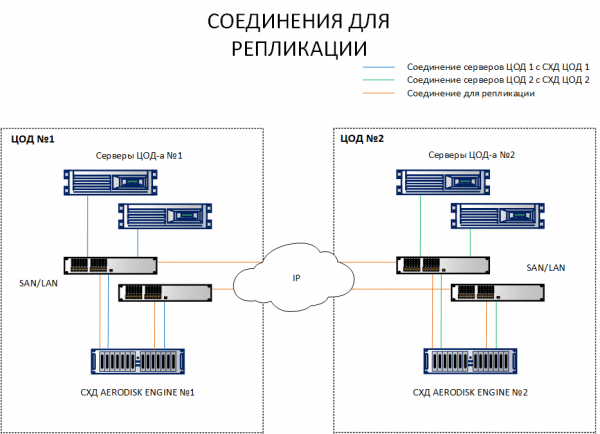
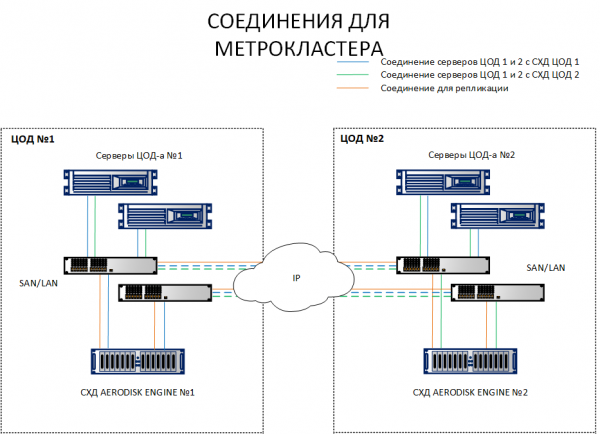
As shown in the diagram, hosts from Site 1 connect to both Storage System 1 and Storage System 2. Likewise, hosts from Site 2 connect to both Storage System 2 and Storage System 1. Thus, each host sees both storage systems. This is a mandatory condition for the operation of the metro cluster.
Of course, there is no need to connect each host with a fiber optic cable to another data center; there won't be enough ports and cables. All these connections must occur through 10G+ Ethernet switches or 8G+ FibreChannel (FC is only for connecting hosts to storage systems for I/O; replication channels are currently only available over IP (10G+ Ethernet).
Now a few words about network topology. An important aspect is the proper configuration of subnets. Several subnets need to be defined immediately for the following types of traffic:
- Subnet for replication, which will synchronize data between storage systems. There can be several of these, depending on the current (already implemented) network topology. If there are two, then routing between them must clearly be established.
- Storage subnets through which hosts will access SAN resources (if it’s iSCSI). There should be one such subnet in each data center;
- Management subnets, meaning three routable subnets across three sites, from which SAN management is carried out, and where the arbitrator is located.
We won't consider subnets for host resource access here, as they depend heavily on specific tasks.
It is crucial to separate different traffic into different subnets (especially important to separate replication from input/output), as mixing all traffic into one 'thick' subnet makes it impossible to manage traffic, and in the context of two data centers, this can lead to various networking collisions. We won't delve deeply into this issue in this article, as planning a network stretched between data centers can be read about on the resources of network equipment manufacturers, where it is described in detail.
Arbitrator configuration
The arbitrator must ensure access to all management interfaces of the SAN via ICMP and SSH protocols. Additionally, consideration should be given to the arbitrator's fault tolerance. There’s a nuance here.
Fault tolerance of the arbitrator is highly desirable but not mandatory. What happens if the arbitrator goes down unexpectedly?
- The metro cluster's operation in normal mode will not change, as the arbitrator does not affect the operation of the metro cluster at all (its task is to switch the load between data centers in a timely manner).
- However, if the arbitrator falls for whatever reason and 'sleeps through' an emergency in the data center, no switching will occur, because there will be no one to issue the necessary commands for switching and organize a quorum. In this case, the metro cluster will turn into a normal replication scheme that will have to be switched manually during a disaster, affecting the RTO.
What follows from this? If it is genuinely necessary to ensure a minimal RTO, it is essential to provide for the fault tolerance of the arbitrator. There are two options for this:
- Run a virtual machine with the arbitrator on a fault-tolerant hypervisor, as all mature hypervisors support fault tolerance;
- If at the third site (in a hypothetical office) it’s too much effort to set up a normal cluster for hypervisors, and there’s no existing cluster, we have provided a hardware option for the arbiter, which is designed in a 2U box housing two standard x-86 servers and can withstand a localized failure.
We strongly recommend ensuring the arbiter’s fault tolerance, even though it isn’t necessary for the metro cluster under normal operations. However, both theory and practice show that when building a truly reliable disaster recovery infrastructure, it’s better to be cautious. Protecting yourself and your business from the ‘law of meanness,’ that is, from a simultaneous failure of both the arbiter and one of the sites where the storage system is deployed, is advisable.
Solution Architecture
Considering the above requirements, we arrive at the following overall architecture of the solution.
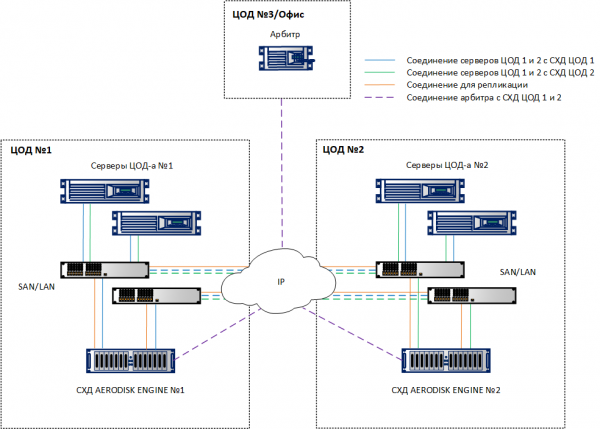
LUNs should be evenly distributed across the two sites to avoid significant overload. Additionally, when sizing in both data centers, not only should we account for double the volume (necessary for storing data simultaneously on two storage systems), but also double the performance in IOPS and MB/s to prevent application degradation in case one of the data centers fails.
It is important to note that with proper sizing (that is, assuming we accounted for the necessary upper limits of IOPS and MB/s, as well as the required CPU and RAM resources), there will be no significant performance drop in the metro cluster if one of the storage systems fails while operating on a single storage system.
This is explained by the fact that when both sites are operational, the synchronous replication consumes half the write performance since each transaction must be written to both storage systems (similar to RAID-1/10). Thus, if one of the storage systems fails, the impact of replication temporarily disappears (until the failed storage system is restored), and we achieve a twofold increase in write performance. Once the LUNs from the failed storage system are restarted on the operational storage system, this twofold gain dissipates due to the load from the LUNs of the other storage system, and we return to the same performance level we had before the ‘crash,’ but only within the confines of a single site.
With proper sizing, it is possible to create conditions under which users will not feel the failure of an entire storage system at all. But let’s reiterate, this requires very careful sizing, for which you can actually contact us for free :-).
Metrocluster Configuration
Metrocluster configuration is very similar to the configuration of regular replication, which we described in . Therefore, we will focus only on the differences. We set up a lab environment based on the architecture above, but in a minimal version: two storage systems connected via 10G Ethernet to each other, two 10G switches, and one host that sees both storage systems through the switches via 10G ports. The arbitrator runs on a virtual machine.
When configuring virtual IPs (VIP) for the replica, you should select the type of VIP for the metrocluster.
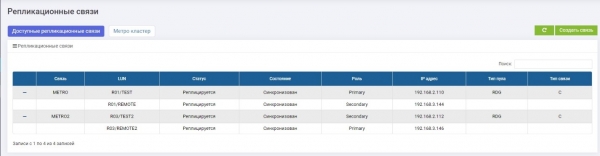
We created two replication links for two LUNs and distributed them across two storage systems: LUN TEST Primary on Storage1 (link METRO), LUN TEST2 Primary for Storage2 (link METRO2).
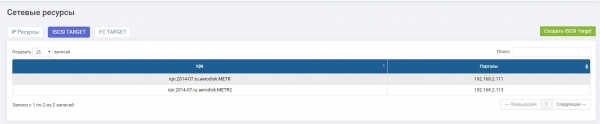
For them, we configured two identical targets (in our case, iSCSI, but FC is also supported, the configuration logic is the same).
Storage1:
Storage2:
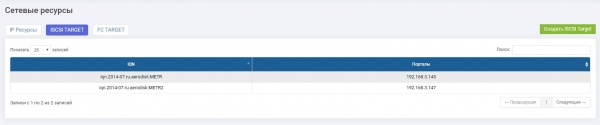
For the replication links, we made mappings on each storage system.
Storage1:
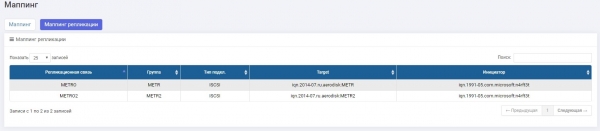
Storage2:
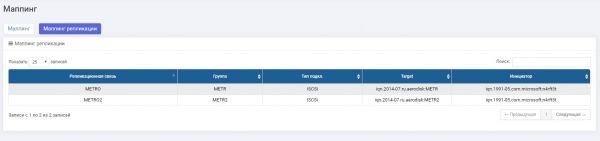
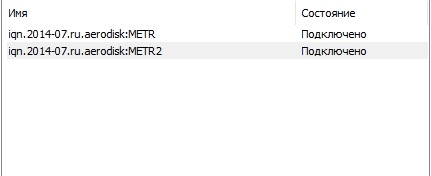
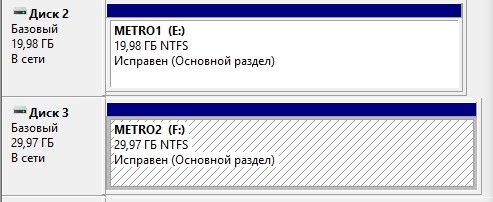
We configured multipath and presented it to the host.
Configuring the Arbitrator
There is not much to do with the arbitrator itself, you just need to turn it on at the third location, assign it an IP address, and configure access to it via ICMP and SSH. The actual configuration is done from the storage systems themselves. At the same time, the configuration of the arbitrator only needs to be performed once on any of the storage controllers in the metrocluster, and these settings will be automatically applied to all controllers.
In the Remote Replication >> Metrocluster section (on any controller) >> click the 'Configure' button.
Enter the IP address of the arbitrator and the management interfaces of the two controllers of the remote storage system.
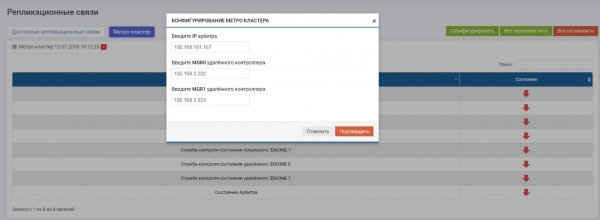
After that, all services need to be enabled (click the 'Restart All' button). If reconfiguration happens in the future, services must be restarted to apply the settings.
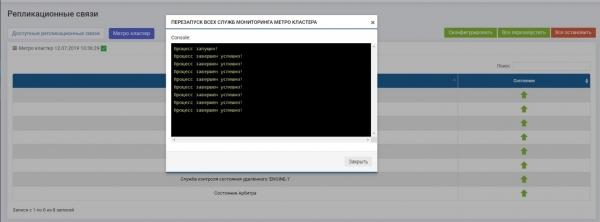
Check that all services are running.
The metrocluster configuration is now complete.
Crash Test
The crash test in our case will be quite simple and quick, since the replication functionality (failover, consistency, etc.) has been addressed in Therefore, to test the reliability of the metro cluster, it is sufficient to check the automation of failure detection, switching, and ensure there are no losses during writing (I/O shutdown).
To do this, we emulate a complete failure of one of the storage systems by physically turning off both of its controllers while simultaneously starting the copying of a large file to a LUN that should activate on another storage system.
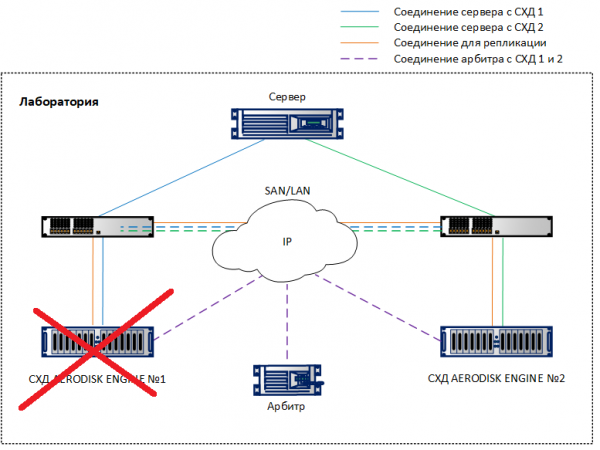
We disconnect one storage system. On the second storage system, we see alerts and messages in the logs indicating that the connection with the neighboring system has been lost. If SMTP or SNMP monitoring alerts are configured, the admin will receive the corresponding notifications.
Exactly 10 seconds later (as seen in both screenshots), the replication link METRO (the one that was Primary on the failed storage system) automatically became Primary on the functioning storage system. Utilizing the existing mapping, LUN TEST remained accessible to the host, with a slight decrease in write performance (within the promised 10 percent), but it did not interrupt.
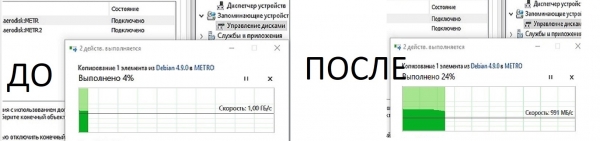
The test was successfully completed.
In summary
The current implementation of the metro cluster in AERODISK Engine N-series storage systems fully allows for addressing tasks where minimizing downtime of IT services is crucial, ensuring their operation in a 24/7/365 mode with minimal labor costs.
One might say that this is all theory, ideal laboratory conditions, and so on... BUT we have a number of implemented projects where we delivered disaster recovery functionality, and the systems work excellent. One of our well-known clients, who uses two storage systems in a disaster recovery configuration, has already given consent to publish information about the project, so in the next part, we will share details about the live implementation.
Thank you, we look forward to a productive discussion.
Source: habr.com
