

Typically, commercial products or ready-made open-source alternatives, such as Prometheus + Grafana, are used for monitoring and analyzing Nginx performance. This is a good option for monitoring or real-time analytics, but not very convenient for historical analysis. On any popular resource, the volume of data from Nginx logs quickly grows, making it logical to use something more specialized for analyzing large volumes of data.
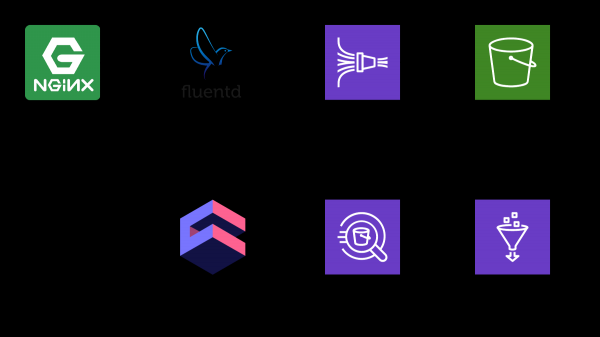
In this article, I will explain how to use for log analysis, taking Nginx as an example, and I will show how to create an analytical dashboard from this data using the open-source framework cube.js. Here is the complete architecture of the solution:
TL;DR;
.
To collect information, we are using , for processing — and , for storage — . With this combination, you can store not only Nginx logs but also other events, as well as logs from other services. You can replace some parts with equivalents for your stack; for example, you can write logs directly to Kinesis from Nginx, bypassing Fluentd, or use Logstash for this.
Collecting Nginx logs
By default, Nginx logs look like this:
4/9/2019 12:58:17 PM 1.1.1.1 - - [09/Apr/2019:09:58:17 +0000] "GET /sign-up HTTP/2.0" 200 9168 "https://example.com/sign-in" "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_14_4) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/73.0.3683.86 Safari/537.36" "-"
4/9/2019 12:58:17 PM 1.1.1.1 - - [09/Apr/2019:09:58:17 +0000] "GET /sign-in HTTP/2.0" 200 9168 "https://example.com/sign-up" "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_14_4) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/73.0.3683.86 Safari/537.36" "-"
They can be parsed, but it is much easier to adjust the Nginx configuration to output logs in JSON format:
log_format json_combined escape=json '{ "created_at": "$msec", '
            '"remote_addr": "$remote_addr", '
            '"remote_user": "$remote_user", '
            '"request": "$request", '
            '"status": $status, '
            '"bytes_sent": $bytes_sent, '
            '"request_length": $request_length, '
            '"request_time": $request_time, '
            '"http_referrer": "$http_referer", '
            '"http_x_forwarded_for": "$http_x_forwarded_for", '
            '"http_user_agent": "$http_user_agent" }';

access_log  /var/log/nginx/access.log  json_combined;
S3 for storage
To store logs, we will use S3. This allows storing and analyzing logs in one place, as Athena can work with data in S3 directly. Later in the article, I will explain how to organize and process logs correctly, but first, we need a clean bucket in S3 where nothing else will be stored. It's important to think in advance about which region you will create the bucket in, as Athena is not available in all regions.
Creating a schema in the Athena console
We will create a table in Athena for the logs. It is needed for both writing and reading if you plan to use Kinesis Firehose. Open the Athena console and create a table:
SQL for creating the table
CREATE EXTERNAL TABLE `kinesis_logs_nginx`(
  `created_at` double,
  `remote_addr` string,
  `remote_user` string,
  `request` string,
  `status` int,
  `bytes_sent` int,
  `request_length` int,
  `request_time` double,
  `http_referrer` string,
  `http_x_forwarded_for` string,
  `http_user_agent` string)
ROW FORMAT SERDE
  'org.apache.hadoop.hive.ql.io.orc.OrcSerde'
STORED AS INPUTFORMAT
  'org.apache.hadoop.hive.ql.io.orc.OrcInputFormat'
OUTPUTFORMAT
  'org.apache.hadoop.hive.ql.io.orc.OrcOutputFormat'
LOCATION
  's3://'
TBLPROPERTIES ('has_encrypted_data'='false');
Creating a Kinesis Firehose Stream
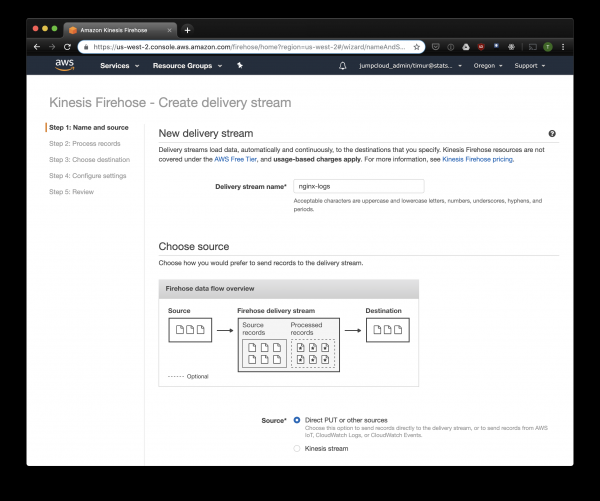
Kinesis Firehose will write the data received from Nginx to S3 in the selected format, breaking it down by directories in the format YYYY/MM/DD/HH. This will be useful when reading the data. You can write directly to S3 from fluentd, but in that case, you will have to write JSON, which is inefficient due to the large file sizes. Moreover, when using PrestoDB or Athena, JSON is the slowest data format. So, we open the Kinesis Firehose console, click 'Create delivery stream', and select 'direct PUT' in the 'delivery' field:
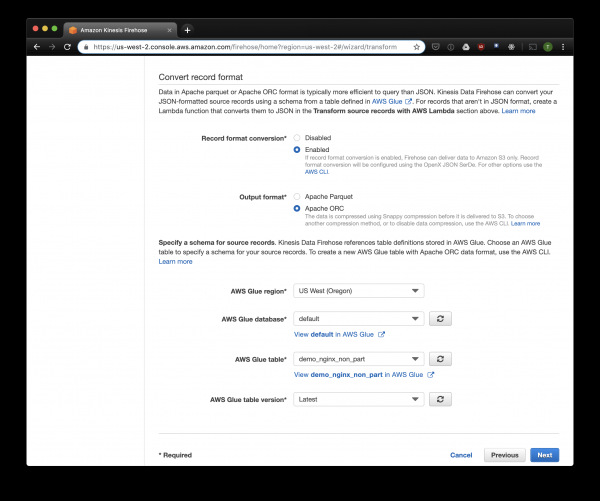
In the next tab, select 'Record format conversion' — 'Enabled' and choose 'Apache ORC' as the format for writing. According to research by some , this is the optimal format for PrestoDB and Athena. For the schema, indicate the table we created earlier. Note that the S3 location can be any in kinesis; only the schema from the table is used. But if you specify a different S3 location, you won't be able to read those records from this table.
Choose S3 for storage and the bucket that we created earlier. The AWS Glue Crawler, which I will discuss later, cannot work with prefixes in the S3 bucket, so it is important to leave it empty.
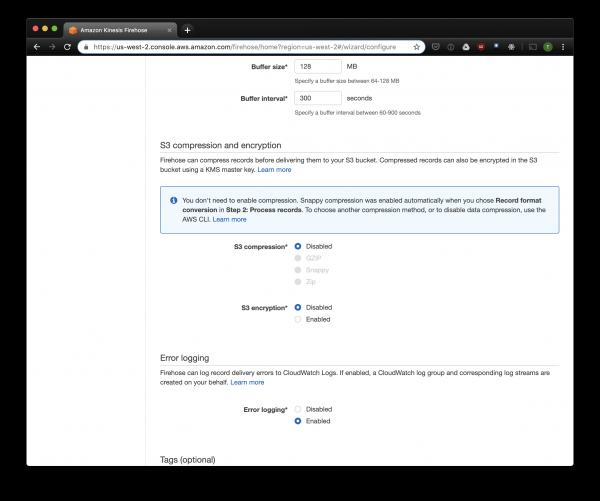
The other options can be modified depending on your load; I usually use the default settings. Note that S3 compression is not available, but ORC uses its own compression by default.
Fluentd
Now that we have configured storage and retrieval for the logs, we need to set up the sending. We will use , because I love Ruby, but you can use Logstash or send logs to kinesis directly. The fluentd server can be started in several ways; I will discuss Docker because it is simple and convenient.
First, we need a fluent.conf configuration file. Create it and add the source:
forward
port 24224
bind 0.0.0.0
You can now start the Fluentd server. If you need a more advanced configuration, there's a detailed guide, including how to build your own image.
$ docker run
  -d
  -p 24224:24224
  -p 24224:24224/udp
  -v /data:/fluentd/log
  -v :/fluentd/etc fluentd
  -c /fluentd/etc/fluent.conf
  fluent/fluentd:stable
This configuration uses the path /fluentd/log for caching logs before sending. You can do without it, but then you might lose all the cached efforts when restarting. You can also use any port; 24224 is the default port for Fluentd.
Now that we have the Fluentd running, we can send Nginx logs there. We usually run Nginx in a Docker container, and in this case, Docker has a native logging driver for Fluentd:
$ docker run
--log-driver=fluentd
--log-opt fluentd-address=
--log-opt tag="{{.Name}}"
-v /some/content:/usr/share/nginx/html:ro
-d
nginx
If you are running Nginx differently, you can use log files; Fluentd has a .
Let's add to the Fluent configuration a log parser set up previously:
@type parser
  key_name log
  emit_invalid_record_to_error false

    @type json
And send logs to Kinesis using the :
@type kinesis_firehose
    region region
    delivery_stream_name
    aws_key_id
    aws_sec_key
Athena
If you have set everything up correctly, after a while (by default, Kinesis records received data every 10 minutes), you should see log files in S3. In the "monitoring" menu of Kinesis Firehose, you can see how much data has been recorded in S3 and any errors. Don't forget to grant write access to the S3 bucket for the Kinesis role. If Kinesis fails to parse something, it will log the errors in the same bucket.
Now you can view the data in Athena. Let's find the recent queries that returned errors:
SELECT * FROM "db_name"."table_name" WHERE status > 499 ORDER BY created_at DESC limit 10;Scanning all records for each query
Now our logs have been processed and stored in S3 in ORC format, compressed and ready for analysis. Kinesis Firehose even organized them into directories for each hour. However, while the table is not partitioned, Athena will load data for all time for each query, with rare exceptions. This is a major issue for two reasons:
- The data volume is continuously growing, slowing down queries;
- The billing for Athena is based on the volume of data scanned, with a minimum of 10 MB per query.
To fix this, we use the AWS Glue Crawler, which will scan the data in S3 and write information about the partitions to the Glue Metastore. This will allow us to use the partitions as a filter in Athena queries, scanning only the directories specified in the query.
Setting Up Amazon Glue Crawler
Amazon Glue Crawler scans all data in the S3 bucket and creates tables with partitions. Create a Glue Crawler from the AWS Glue console and add the bucket where you store your data. You can use one crawler for multiple buckets; in this case, it will create tables in the specified database with names matching the bucket names. If you plan to continuously use this data, make sure to set a schedule for the crawler's execution according to your needs. We use one crawler for all tables, running every hour.
Partitioned Tables
After the first crawler run, tables for each scanned bucket should appear in the database specified in the settings. Open the Athena console and look for the table with Nginx logs. Let's try to read something:
SELECT * FROM "default"."part_demo_kinesis_bucket"
WHERE(
  partition_0 = '2019' AND
  partition_1 = '04' AND
  partition_2 = '08' AND
  partition_3 = '06'
  );
This query will select all records received from 6 to 7 AM on April 8, 2019. But how much more efficient is this compared to just reading from a non-partitioned table? Let's find out and select the same records, filtering them by timestamp:
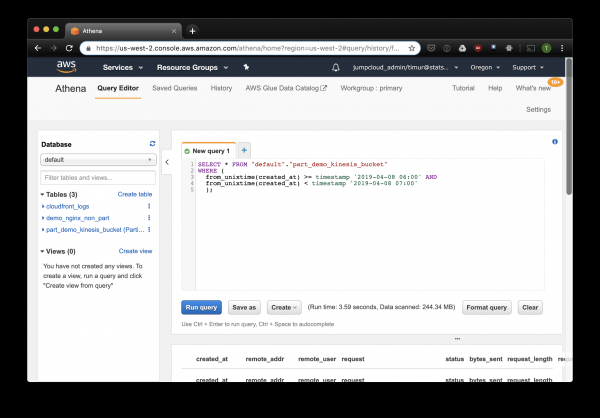
3.59 seconds and 244.34 megabytes of data on a dataset that has only a week of logs. Let's try partition filtering:
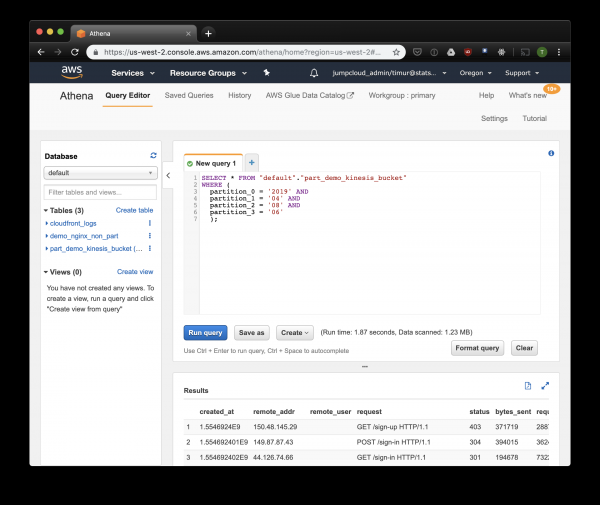
A little faster, but the most important thing — just 1.23 megabytes of data! It would be much cheaper if not for the minimum 10 megabytes per query in the pricing. But it's still much better, and on larger datasets, the difference would be even more impressive.
Собираем дэшборд с помощью Cube.js
To build a dashboard, we use the Cube.js analytic framework. It has quite a few features, but we are interested in two: the ability to automatically use partition filters and pre-aggregate data. It uses a data schema , written in JavaScript, to generate SQL and execute queries against the database. All we need to do is specify how to use the partition filter in the data schema.
Let's create a new Cube.js application. Since we are already using the AWS stack, it makes sense to use Lambda for deployment. You can use the express template for generation if you plan to host the Cube.js backend on Heroku or Docker. The documentation describes other .
$ npm install -g cubejs-cli
$ cubejs create nginx-log-analytics -t serverless -d athena
To configure access to the database in cube.js, environment variables are used. The generator will create a .env file where you can specify your keys for .
Now we will need , in which we will specify how our logs are stored. You can also define how to calculate metrics for dashboards there.
In the directory schema, create a file Logs.js. Here is an example data model for nginx:
Model code
const partitionFilter = (from, to) => `
    date(from_iso8601_timestamp(${from})) = date_parse(partition_0 || partition_1 || partition_2, '%Y%m%d')
    `

cube(`Logs`, {
  sql: `
  select * from part_demo_kinesis_bucket
  WHERE ${FILTER_PARAMS.Logs.createdAt.filter(partitionFilter)}
  `,

  measures: {
    count: {
      type: `count`,
    },

    errorCount: {
      type: `count`,
      filters: [
        { sql: `${CUBE.isError} = 'Yes' }`
      ]
    },

    errorRate: {
      type: `number`,
      sql: `100.0 * ${errorCount} / ${count}`,
      format: `percent`
    }
  },

  dimensions: {
    status: {
      sql: `status`,
      type: `number`
    },

    isError: {
      type: `string`,
      case: {
        when: [{
          sql: `${CUBE}.status >= 400`, label: `Yes`
        }],
        else: { label: `No` }
      }
    },

    createdAt: {
      sql: `from_unixtime(created_at)`,
      type: `time`
    }
  }
});
Here we use the variable , to generate an SQL query with a partition filter.
We also specify the metrics and parameters we want to display on the dashboard and indicate pre-aggregations. Cube.js will create additional tables with pre-aggregated data and will automatically update the data as it comes in. This not only speeds up queries but also reduces costs when using Athena.
Let's add this information to the data schema file:
preAggregations: {
  main: {
    type: `rollup`,
    measureReferences: [count, errorCount],
    dimensionReferences: [isError, status],
    timeDimensionReference: createdAt,
    granularity: `day`,
    partitionGranularity: `month`,
    refreshKey: {
      sql: FILTER_PARAMS.Logs.createdAt.filter((from, to) =>
        `select
           CASE WHEN from_iso8601_timestamp(${to}) + interval '3' day > now()
           THEN date_trunc('hour', now()) END`
      )
    }
  }
}
In this model, we specify that we need to pre-aggregate data for all used metrics and use partitioning by month. can significantly speed up data collection and updates.
Now we can create the dashboard!
The Cube.js backend provides and a set of client libraries for popular frontend frameworks. We will use the React version of the client to build the dashboard. Cube.js only provides data, so we will need a library for visualizations — I prefer , but you can use any.
The Cube.js server accepts requests in , which specifies the required metrics. For example, to count how many errors Nginx returned by days, you need to send the following request:
{
  "measures": ["Logs.errorCount"],
  "timeDimensions": [
    {
      "dimension": "Logs.createdAt",
      "dateRange": ["2019-01-01", "2019-01-07"],
      "granularity": "day"
    }
  ]
}
Let's install the Cube.js client and the React component library via NPM:
$ npm i --save @cubejs-client/core @cubejs-client/reactWe import the components cubejs and QueryRenderer, to fetch the data, and assemble the dashboard:
Dashboard code
import React from 'react';
import { LineChart, Line, XAxis, YAxis } from 'recharts';
import cubejs from '@cubejs-client/core';
import { QueryRenderer } from '@cubejs-client/react';

const cubejsApi = cubejs(
  'YOUR-CUBEJS-API-TOKEN',
  { apiUrl: 'http://localhost:4000/cubejs-api/v1' },
);

export default () => {
  return (
     {
        if (!resultSet) {
          return 'Loading...';
        }

        return (


        );
      }}
    />
  )
}
The dashboard sources are available at .
Source: habr.com
