

Hello, I'm Dmitry Logvinenko — Data Engineer in the Analytics Department of the 'Vezyot' Group.
I'll tell you about a wonderful tool for developing ETL processes — Apache Airflow. However, Airflow is so versatile and multi-dimensional that you should take a look at it even if you're not working with data streams but need to periodically run certain processes and monitor their execution.
And yes, I will not only talk but also show: the program includes a lot of code, screenshots, and recommendations.
What you typically see when you Google the word Airflow / Wikimedia Commons
Table of Contents
Introduction
Apache Airflow — it's just like Django:
- written in Python,
- has an excellent admin interface,
- infinitely extendable,
— only better, and it's made for entirely different purposes, namely (as stated before):
- launching and monitoring tasks on an unlimited number of machines (as many as Celery/Kubernetes and your conscience allow)
- with dynamic workflow generation from very easy-to-write and comprehend Python code
- and the ability to connect any databases and APIs with both ready-made components and custom plugins (which is done extremely easily).
We use Apache Airflow like this:
- we gather data from various sources (multiple instances of SQL Server and PostgreSQL, various APIs with application metrics, even 1C) into DWH and ODS (for us, this is Vertica and Clickhouse).
- like an advanced
cron, which launches data consolidation processes in ODS and also monitors their maintenance.
Until recently, our needs were met by a small server with 32 cores and 50 GB of RAM. In Airflow, we have:
- more than 200 dags (actual workflows into which we fit tasks),
- with an average of 70 tasks,
- this stuff launches (on average) once an hour.
And about how we scaled, I'll write below, but for now, let's define the über-task that we will solve:
There are three source SQL Servers, each with 50 databases — instances of one project, which means they have the same structure (almost everywhere, muah-ha-ha), and therefore each has an Orders table (thankfully, a table with such a name can be shoved into any business). We extract the data, adding metadata fields (source server, source database, ETL task identifier) and naively throw them into, say, Vertica.
Let's go!
Main part, practical (and somewhat theoretical)
Why do we need this (and you too)
When the trees were big, and I was just a simple guy SQL-er in one Russian retail, we were cranking out ETL processes aka data flows using the two tools available to us:
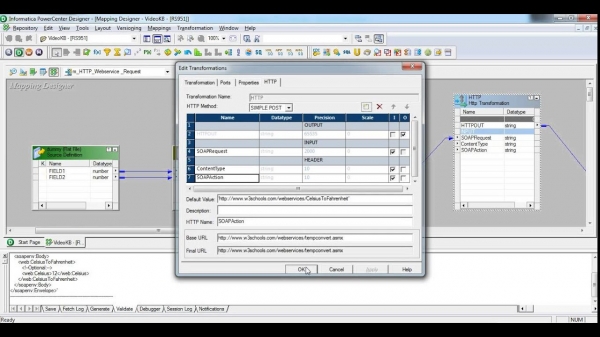
- Informatica Power Center — an extremely sprawling system, highly productive, with its own hardware and versioning. I used maybe 1% of its capabilities. Why? Well, first of all, that interface, somewhere from the nineties, mentally pressured us. Secondly, this gadget is designed for extremely complex processes, fierce component reuse, and other very-important-enterprise-features. Let's not even mention its price, which is akin to the cost of an Airbus A380 per year.
Caution, a screenshot may cause some pain to people under 30

- SQL Server Integration Server — we used this fellow in our internal project flows. Well, really: we are already using SQL Server, and ignoring its ETL tools would be somewhat unreasonable. Everything is nice about it: the interface is beautiful, and the execution reports… But that’s not why we love software products, oh no, not for that. We can version it
dtsx(which is an XML with nodes mixing up when saved), but what’s the benefit? To create a task package that transfers a hundred tables from one server to another? Forget a hundred; your index finger will fall off after clicking the mouse button for twenty. But it definitely looks more stylish:
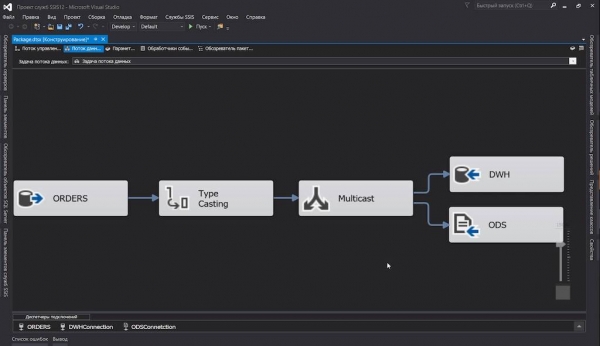
We were definitely looking for solutions. It even almost came down to a custom SSIS package generator...
... and then a new job found me. And there, Apache Airflow caught up with me.
When I discovered that describing ETL processes is just simple Python code, I nearly danced with joy. Suddenly, those data flows were subjected to versioning and diffusion, and stuffing tables with a uniform structure from a hundred databases into one target became a matter of Python code on a one and a half to two 13” screens.
Building a cluster
Let's not create a complete children's playground and talk about completely obvious things like installing Airflow, your chosen database, Celery, and other matters described in the documentation.
So that we can get started with experiments right away, I've sketched out docker-compose.yml in which:
- Let's set up Airflow: Scheduler, Webserver. Flower will also run there for monitoring Celery tasks (since it's already included in
apache/airflow:1.10.10-python3.7, and we don't mind); - PostgreSQL, where Airflow will write its operational information (scheduler data, execution statistics, etc.), and Celery will mark completed tasks;
- Redis, which will act as the task broker for Celery;
- Celery worker, which will handle the actual execution of tasks.
- In the folder
. /dags, we will place our files describing the DAGs. They will be picked up on the fly, so there's no need to restart the entire stack after every little change.
Somewhere the code in the examples is not shown in full (to avoid cluttering the text), and in some cases, it is modified during the process. You can view complete working code examples in the repository. .
docker-compose.yml
version: '3.4'

x-airflow-config: &airflow-config
  AIRFLOW__CORE__DAGS_FOLDER: /dags
  AIRFLOW__CORE__EXECUTOR: CeleryExecutor
  AIRFLOW__CORE__FERNET_KEY: MJNz36Q8222VOQhBOmBROFrmeSxNOgTCMaVp2_HOtE0=
  AIRFLOW__CORE__HOSTNAME_CALLABLE: airflow.utils.net:get_host_ip_address
  AIRFLOW__CORE__SQL_ALCHEMY_CONN: postgres+psycopg2://airflow:airflow@airflow-db:5432/airflow

  AIRFLOW__CORE__PARALLELISM: 128
  AIRFLOW__CORE__DAG_CONCURRENCY: 16
  AIRFLOW__CORE__MAX_ACTIVE_RUNS_PER_DAG: 4
  AIRFLOW__CORE__LOAD_EXAMPLES: 'False'
  AIRFLOW__CORE__LOAD_DEFAULT_CONNECTIONS: 'False'

  AIRFLOW__EMAIL__DEFAULT_EMAIL_ON_RETRY: 'False'
  AIRFLOW__EMAIL__DEFAULT_EMAIL_ON_FAILURE: 'False'

  AIRFLOW__CELERY__BROKER_URL: redis://broker:6379/0
  AIRFLOW__CELERY__RESULT_BACKEND: db+postgresql://airflow:airflow@airflow-db/airflow

x-airflow-base: &airflow-base
  image: apache/airflow:1.10.10-python3.7
  entrypoint: /bin/bash
  restart: always
  volumes:
    - ./dags:/dags
    - ./requirements.txt:/requirements.txt

services:
  # Redis as a Celery broker
  broker:
    image: redis:6.0.5-alpine

  # DB for the Airflow metadata
  airflow-db:
    image: postgres:10.13-alpine

    environment:
      - POSTGRES_USER=airflow
      - POSTGRES_PASSWORD=airflow
      - POSTGRES_DB=airflow

    volumes:
      - ./db:/var/lib/postgresql/data

  # Main container with Airflow Webserver, Scheduler, Celery Flower
  airflow:
    <<: *airflow-base

    environment:
      <<: *airflow-config

      AIRFLOW__SCHEDULER__DAG_DIR_LIST_INTERVAL: 30
      AIRFLOW__SCHEDULER__CATCHUP_BY_DEFAULT: 'False'
      AIRFLOW__SCHEDULER__MAX_THREADS: 8

      AIRFLOW__WEBSERVER__LOG_FETCH_TIMEOUT_SEC: 10

    depends_on:
      - airflow-db
      - broker

    command: >
      -c " sleep 10 &&
           pip install --user -r /requirements.txt &&
           /entrypoint initdb &&
          (/entrypoint webserver &) &&
          (/entrypoint flower &) &&
           /entrypoint scheduler"

    ports:
      # Celery Flower
      - 5555:5555
      # Airflow Webserver
      - 8080:8080

  # Celery worker, will be scaled using `--scale=n`
  worker:
    <<: *airflow-base

    environment:
      <<: *airflow-config

    command: >
      -c " sleep 10 &&
           pip install --user -r /requirements.txt &&
           /entrypoint worker"

    depends_on:
      - airflow
      - airflow-db
      - broker
Notes:
- In the Docker Compose setup, I relied heavily on the well-known image – definitely take a look. It might be all you need in life.
- All Airflow configurations are accessible not only through
airflow.cfg, but also through environment variables (kudos to the developers), which I made extensive use of. - Naturally, it's not production-ready: I intentionally did not configure heartbeats on the containers and did not focus on security. But I created a minimum suitable for our experiments.
- Please note that:
- The folder containing the DAGs must be accessible to both the scheduler and the workers.
- The same applies to all third-party libraries—they must all be installed on the machines with the scheduler and workers.
Now simply run:
$ docker-compose up --scale worker=3Once everything is up, you can check the web interfaces:
- Airflow:
- Flower:
Basic concepts
If you didn't understand anything about all these 'dags', here is a brief glossary:
- Scheduler — the main guy in Airflow, making sure that robots do the work, not humans: he monitors the schedule, updates dags, and launches tasks.
In fact, in older versions, it had memory issues (no, not amnesia, but leaks) and a legacy parameter remained in the configs.
run_duration— the interval for its restart. But now everything is fine. - DAG (also 'dag') — 'directed acyclic graph', but such a definition doesn't really mean much to most people; essentially, it's a container for interconnected tasks (see below) or analogous to Package in SSIS and Workflow in Informatica.
In addition to dags, there can also be subdags, but we probably won't get to those.
- DAG Run — an initialized dag that has its own
execution_date. Dag runs of a single dag can indeed operate in parallel (if, of course, you've made your tasks idempotent). - Operator — these are pieces of code responsible for performing a specific action. There are three types of operators:
- action, like our favorite
PythonOperator, which is capable of executing any (valid) Python code; - transfer, which move data from one place to another, for example,
MsSqlToHiveTransfer; - sensor will allow reacting or pausing further execution of the dag until a certain event occurs.
HttpSensorcan hit the specified endpoint, and when it gets the desired response, it will start the transferGoogleCloudStorageToS3Operator. A curious mind might ask, 'Why? After all, one could implement retries right in the operator!' And then, to avoid clogging the task pool with hanging operators. The sensor starts, checks, and then dies until the next try.
- action, like our favorite
- Task — declared operators regardless of type attached to the dag are elevated to the rank of task.
- Task instance — when the general scheduler decides it's time to send tasks into battle on worker executors (right on the spot if we are using
LocalExecutoror on a remote node in the case ofCeleryExecutor), it assigns them context (i.e., a set of variables — execution parameters), unwraps command or query templates, and places them in the pool.
Generating tasks
First, we will outline the general scheme of our dag, and then delve deeper into the details, as we will apply some non-trivial solutions.
So, in its simplest form, such a dag would look like this:
from datetime import timedelta, datetime

from airflow import DAG
from airflow.operators.python_operator import PythonOperator

from commons.datasources import sql_server_ds

dag = DAG('orders',
          schedule_interval=timedelta(hours=6),
          start_date=datetime(2020, 7, 8, 0))

def workflow(**context):
    print(context)

for conn_id, schema in sql_server_ds:
    PythonOperator(
        task_id=schema,
        python_callable=workflow,
        provide_context=True,
        dag=dag)
Let's figure this out:
- First, we import the necessary libs and a few more things;
sql_server_ds— this isList[namedtuple[str, str]]with the connection names from Airflow Connections and the databases from which we will be pulling our table;dagis the declaration of our DAG, which must reside inglobals(), otherwise Airflow won't find it. The DAG also needs to be told:- that it is called
ordersthis name will appear in the web interface, - that it will work starting from midnight on July 8th,
- and that it should run approximately every 6 hours (for the cool kids, instead of
timedelta()a string is allowed,cronfor the less cool — an expression like0 0 0/6 ? * * *@dailyworkflow());
- that it is called
will do the main job, but not right now. For now, we will just dump our context into the log.And now the simple magic of creating tasks:- we iterate over our sources;
- initializing
- , which will execute our placeholder
PythonOperator. Don't forget to specify a unique task name (within the DAG) and associate it with the DAG itself. The flagwill do the main job, but not right now. For now, we will just dump our context into the log.provide_contextwill in turn pass extra arguments to the function, which we will carefully collect using**contextThat's all for now. What have we obtained:.
a new DAG in the web interface,
- one hundred fifty tasks that will run in parallel (if Airflow, Celery, and server capabilities allow it).
- Well, almost obtained.
Who will set the dependencies?
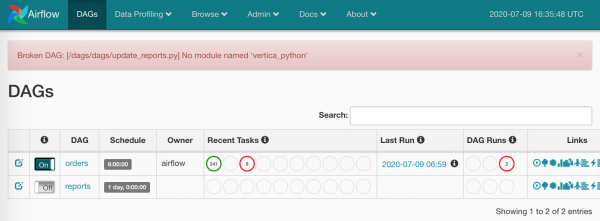
To simplify this, I integrated it into
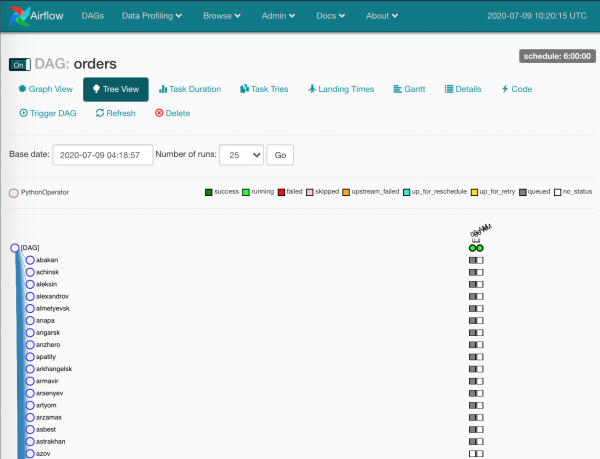
processing docker-compose.yml requirements.txt on all nodes. Now we are really rolling:
Gray squares are task instances handled by the scheduler.
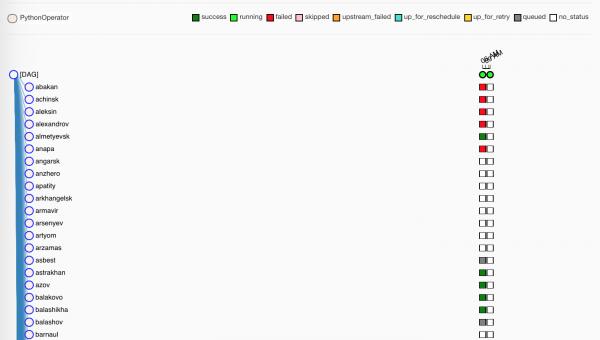
We wait a bit, and the tasks are grabbed by the workers:
Green ones, naturally, are those that completed successfully. Red ones — not so much.
By the way, on our production server, there is no folder
, synchronized between machines — all DAGs are stored in
. /dagsour Gitlab, and Gitlab CI deploys updates to the machines upon merging ingitWhile the workers are pounding away at our placeholder tasks, let's remember another tool that can show us something — Flower.master.
A bit about Flower
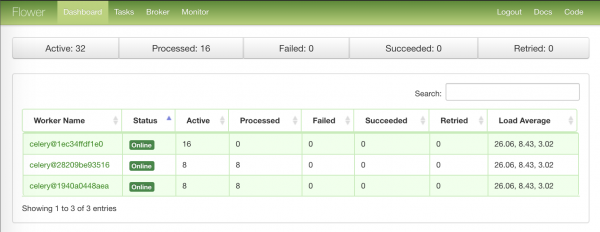
The very first page with summary information about the worker nodes:
The very first page with summary information about worker nodes:
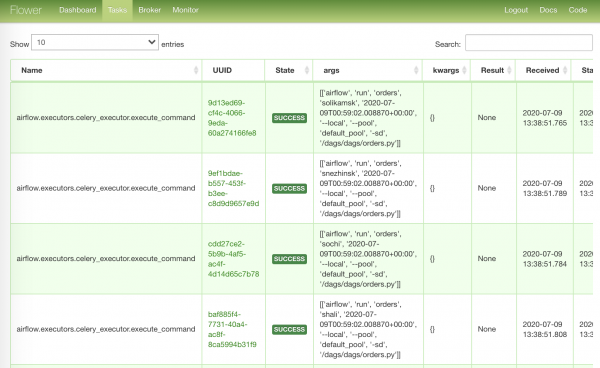
The most engaging page with tasks that have gone into work:
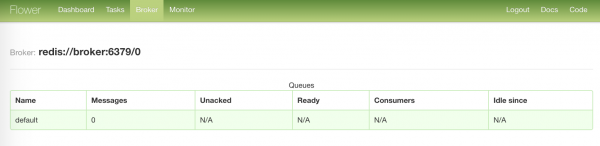
The dullest page with the status of our broker:
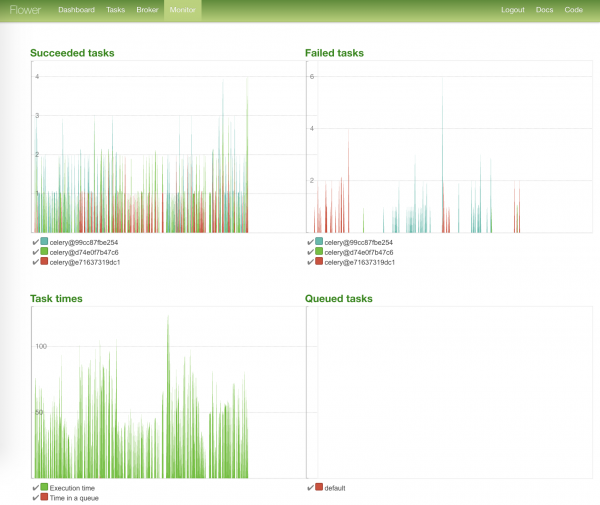
The brightest page — with graphs showing task status and their execution time:
Loading what wasn’t loaded
So, all tasks have finished, we can carry out the wounded.
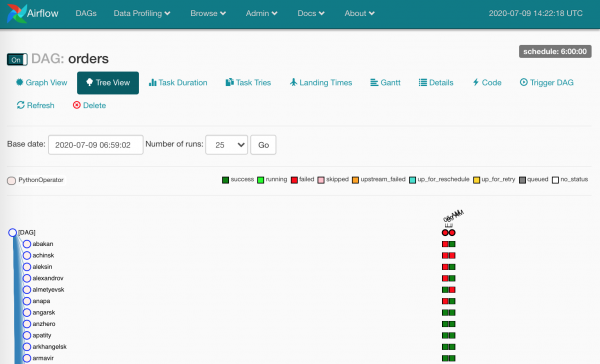
And there were quite a few wounded — for various reasons. If Airflow is used correctly, these squares indicate that the data definitely did not arrive.
We need to check the log and restart the failed task instances.
By clicking on any square, we will see the actions available to us:
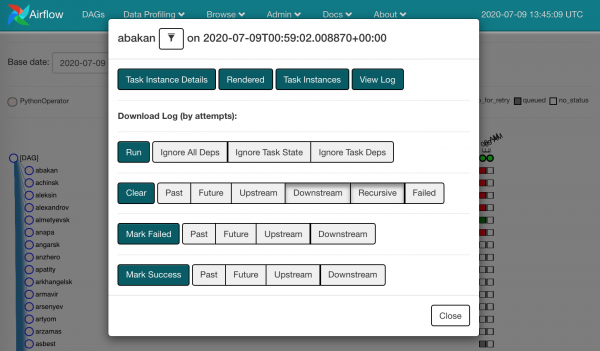
We can take and clear the failed one. That is, we forget that something went wrong, and the same task instance will go to the scheduler.
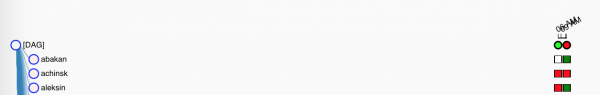
Of course, doing this with all the red squares using the mouse is not very humane — this is not what we expect from Airflow. Naturally, we have a weapon of mass destruction: Browse/Task Instances
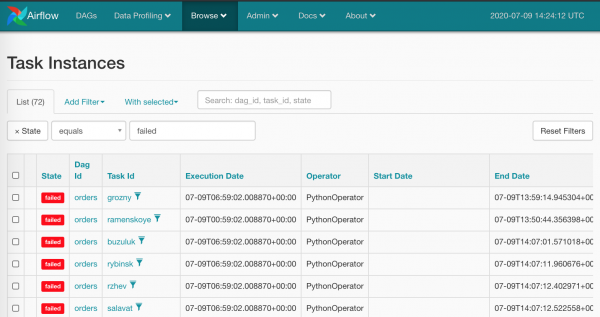
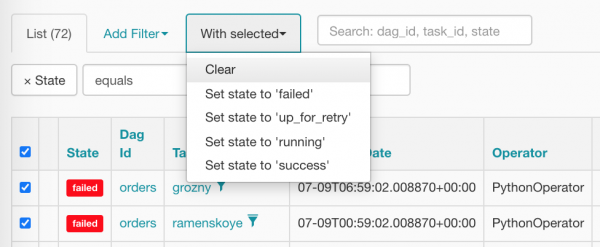
Let's select everything at once and reset, clicking the right option:
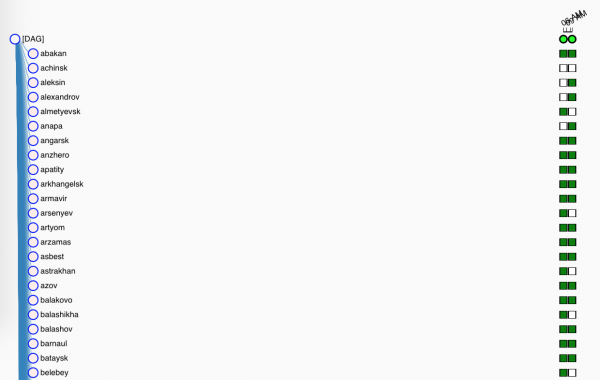
After clearing, our tasks look like this (they are eagerly waiting for the scheduler to plan them):
Connections, hooks, and other variables
It's time to look at the next DAG, update_reports.py:
from collections import namedtuple
from datetime import datetime, timedelta
from textwrap import dedent

from airflow import DAG
from airflow.contrib.operators.vertica_operator import VerticaOperator
from airflow.operators.email_operator import EmailOperator
from airflow.utils.trigger_rule import TriggerRule

from commons.operators import TelegramBotSendMessage

dag = DAG('update_reports',
          start_date=datetime(2020, 6, 7, 6),
          schedule_interval=timedelta(days=1),
          default_args={'retries': 3, 'retry_delay': timedelta(seconds=10)})

Report = namedtuple('Report', 'source target')
reports = [Report(f'{table}_view', table) for table in [
    'reports.city_orders',
    'reports.client_calls',
    'reports.client_rates',
    'reports.daily_orders',
    'reports.order_duration']]

email = EmailOperator(
    task_id='email_success', dag=dag,
    to='{{ var.value.all_the_kings_men }}',
    subject='DWH Reports updated',
    html_content=dedent("""Dear Gentlemen, the reports have been updated"""),
    trigger_rule=TriggerRule.ALL_SUCCESS)

tg = TelegramBotSendMessage(
    task_id='telegram_fail', dag=dag,
    tg_bot_conn_id='tg_main',
    chat_id='{{ var.value.failures_chat }}',
    message=dedent("""
         Natasha, wake up, we dropped {{ dag.dag_id }}
        """),
    trigger_rule=TriggerRule.ONE_FAILED)

for source, target in reports:
    queries = [f"TRUNCATE TABLE {target}",
               f"INSERT INTO {target} SELECT * FROM {source}"]

    report_update = VerticaOperator(
        task_id=target.replace('reports.', ''),
        sql=queries, vertica_conn_id='dwh',
        task_concurrency=1, dag=dag)

    report_update >> [email, tg]
We've all done report updates at some point, right? Here it is again: there's a list of sources to pull data from; there's a list to place it into; and don't forget to signal when everything happens or breaks (well, that's not us, right?).
Let's go through the file again and take a look at the new puzzling items:
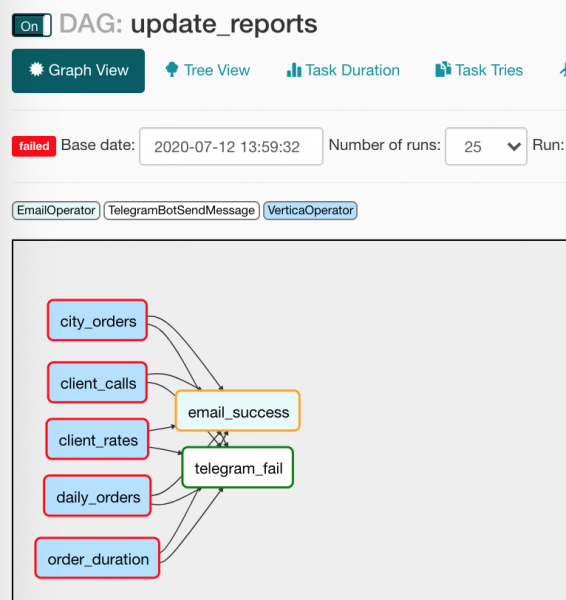
from commons.operators import TelegramBotSendMessage— there's nothing stopping us from creating our own operators, which we utilized by making a small wrapper for sending messages in Unblocked. (We'll talk about this operator further below);default_args={}— the DAG can distribute the same arguments to all its operators;to='{{ var.value.all_the_kings_men }}'— fieldtowill not be hardcoded but rather formed dynamically using Jinja and a variable with a list of emails, which I carefully placed inAdmin/Variables;trigger_rule=TriggerRule.ALL_SUCCESS— operator trigger condition. In our case, the letter will be sent to the bosses only if all dependencies have completed successfully;tg_bot_conn_id='tg_main'— argumentsconn_idtake connection identifiers, which we create inAdmin/Connections;trigger_rule=TriggerRule.ONE_FAILED— messages in Telegram will only be sent if there are any failed tasks;task_concurrency=1— we prohibit simultaneous execution of multiple task instances of a single task. Otherwise, we might end up with concurrent executions of severalVerticaOperator(looking at one table);report_update >> [email, tg]— allVerticaOperatorwill converge in sending the email and message, like this:

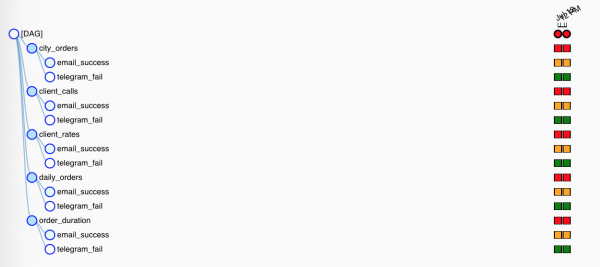
But since the notification operators have different trigger conditions, only one will work. In the Tree View, it looks somewhat less clear:

Let me say a few words about macros and their friends — of variables.
Macros are Jinja placeholders that can substitute various useful information into operator arguments. For example, like this:
SELECT
    id,
    payment_dtm,
    payment_type,
    client_id
FROM orders.payments
WHERE
    payment_dtm::DATE = '{{ ds }}'::DATE
{{ ds }} will expand to the contents of the context variable execution_date in the format YYYY-MM-DD: 2020-07-14. The nicest thing is that context variables are pinned to a specific task instance (the square in the Tree View), and when restarted, the placeholders will reveal the same values.
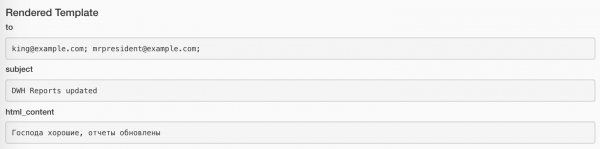
Assigned values can be viewed using the Rendered button on each task instance. This is how it looks for the task that sends the email:
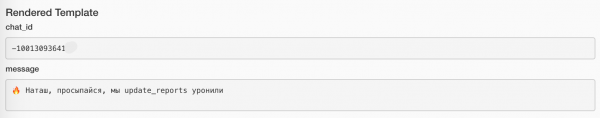
And this is how it looks for the task that sends the message:
A complete list of built-in macros for the latest available version can be found here:
Moreover, with plugins, we can declare our own macros, but that's a whole different story.
In addition to predefined items, we can substitute the values of our variables (which I already used above in the code). Let's create a couple of items: Admin/Variables That's it, ready to use:
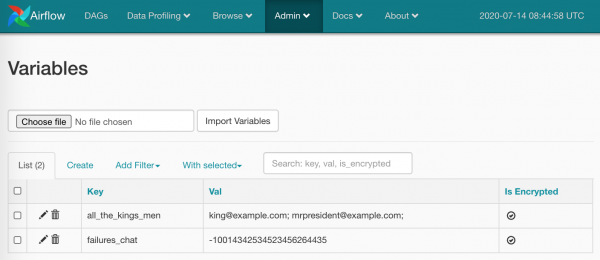
TelegramBotSendMessage(chat_id='{{ var.value.failures_chat }}')
The value can be scalar, or it can also be JSON. In the case of JSON:bot_config{ "bot": { "token": 881hskdfASDA16641, "name": "Verter" }, "service": "TG" }
just use the path to the desired key:{{ var.json.bot_config.bot.token }} I'll say literally one word and show one screenshot about.
connections . It's all elementary here: on the pagewe create a connection, putting our logins/passwords and more specific parameters there. Like this: Admin/Connections Passwords can be encrypted (more thoroughly than in the default option), and you can omit specifying the connection type (as I did for
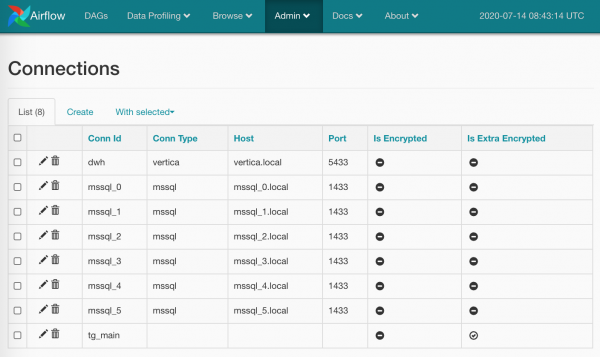
tg_main ) — the thing is, the list of types is hardcoded in the Airflow models and cannot be extended without digging into the source code (if I missed something, please correct me), but obtaining credentials simply by name is not a problem.Also, you can create multiple connections with the same name: in such cases, the method
BaseHook.get_connection() , which retrieves connections by name, will returna random one from several aliases (it would be more logical to implement Round Robin, but let's leave that to the developers of Airflow). Variables and Connections are undoubtedly great tools, but it's important to maintain a balance: which parts of your workflows you keep in the code, and which you delegate to Airflow. On one hand, it might be convenient to quickly change a value, like a mailing address, through the UI. On the other hand, this is still a return to mouse clicking, which we (I) wanted to get rid of.
Working with connections is one of the tasks
of hooks . In general, Airflow hooks are the connection points to external services and libraries. For example,JiraHook will open a client for interacting with Jira (you can move tasks back and forth), and with SambaHook you can push a local file to smb -share.And we are getting close to looking at how the
Breaking down a custom operator
TelegramBotSendMessage commons/operators.py
Code works with the operator: with the operator itself:
from typing import Union

from airflow.operators import BaseOperator

from commons.hooks import TelegramBotHook, TelegramBot

class TelegramBotSendMessage(BaseOperator):
    """Send message to chat_id using TelegramBotHook

    Example:
        >>> TelegramBotSendMessage(
        ...     task_id='telegram_fail', dag=dag,
        ...     tg_bot_conn_id='tg_bot_default',
        ...     chat_id='{{ var.value.all_the_young_dudes_chat }}',
        ...     message='{{ dag.dag_id }} failed :(',
        ...     trigger_rule=TriggerRule.ONE_FAILED)
    """
    template_fields = ['chat_id', 'message']

    def __init__(self,
                 chat_id: Union[int, str],
                 message: str,
                 tg_bot_conn_id: str = 'tg_bot_default',
                 *args, **kwargs):
        super().__init__(*args, **kwargs)

        self._hook = TelegramBotHook(tg_bot_conn_id)
        self.client: TelegramBot = self._hook.client
        self.chat_id = chat_id
        self.message = message

    def execute(self, context):
        print(f'Send "{self.message}" to the chat {self.chat_id}')
        self.client.send_message(chat_id=self.chat_id,
                                 message=self.message)
Here, like everything else in Airflow, it’s really simple:
- Inherited from
BaseOperator, which implements quite a lot of Airflow-specific features (take a look at your leisure) - Declared the fields
template_fields, where Jinja will look for macros to process. - Organized the appropriate arguments for
__init__(), set defaults where needed. - Also didn’t forget about the parent initialization.
- Opened the corresponding hook
TelegramBotHook, obtained a client object from it. - Overrode the method
BaseOperator.execute(), which Airflow will invoke when it’s time to run the operator — this is where we implement the main action, not forgetting to log. (We log, by the way, directly instdoutandstderr— Airflow will intercept everything, neatly wrap it up, and place it where needed.)
Let’s see what we have in commons/hooks.py. The first part of the file, with the hook itself:
from typing import Union

from airflow.hooks.base_hook import BaseHook
from requests_toolbelt.sessions import BaseUrlSession

class TelegramBotHook(BaseHook):
    """Telegram Bot API hook

    Note: add a connection with empty Conn Type and don't forget
    to fill Extra:

        {"bot_token": "YOuRAwEsomeBOtToKen"}
    """
    def __init__(self,
                 tg_bot_conn_id='tg_bot_default'):
        super().__init__(tg_bot_conn_id)

        self.tg_bot_conn_id = tg_bot_conn_id
        self.tg_bot_token = None
        self.client = None
        self.get_conn()

    def get_conn(self):
        extra = self.get_connection(self.tg_bot_conn_id).extra_dejson
        self.tg_bot_token = extra['bot_token']
        self.client = TelegramBot(self.tg_bot_token)
        return self.client
I don’t even know what can be explained here, I’ll just note some important points:
- We inherit, think about the arguments — in most cases, there will be just one:
conn_id; - Override standard methods: I limited myself to
get_conn(), in which I obtain connection parameters by name and simply extract the sectionextra(this field for JSON), where I (following my own instruction!) placed the Telegram bot token:{"bot_token": "YOuRAwEsomeBOtToKen"}. - Creating an instance of our
TelegramBot, giving it a specific token.
That's it. You can get the client from the hook using TelegramBotHook().client or TelegramBotHook().get_conn().
And here is the second part of the file, in which I created a micro-wrapper for the Telegram REST API, so I don't have to carry the same for just one method sendMessage.
class TelegramBot:
    """Telegram Bot API wrapper

    Examples:
        >>> TelegramBot('YOuRAwEsomeBOtToKen', '@myprettydebugchat').send_message('Hi, darling')
        >>> TelegramBot('YOuRAwEsomeBOtToKen').send_message('Hi, darling', chat_id=-1762374628374)
    """
    API_ENDPOINT = 'https://api.telegram.org/bot{}/'

    def __init__(self, tg_bot_token: str, chat_id: Union[int, str] = None):
        self._base_url = TelegramBot.API_ENDPOINT.format(tg_bot_token)
        self.session = BaseUrlSession(self._base_url)
        self.chat_id = chat_id

    def send_message(self, message: str, chat_id: Union[int, str] = None):
        method = 'sendMessage'

        payload = {'chat_id': chat_id or self.chat_id,
                   'text': message,
                   'parse_mode': 'MarkdownV2'}

        response = self.session.post(method, data=payload).json()
        if not response.get('ok'):
            raise TelegramBotException(response)

class TelegramBotException(Exception):
    def __init__(self, *args, **kwargs):
        super().__init__((args, kwargs))
The right way is to combine all this:
commons/operators.py,TelegramBotHook,TelegramBot— into a plugin, place it in a public repository, and hand it over to Open Source.
While we were studying all this, our report updates successfully managed to get stuck and sent me a message about an error in the channel. I’ll go check what’s wrong again…
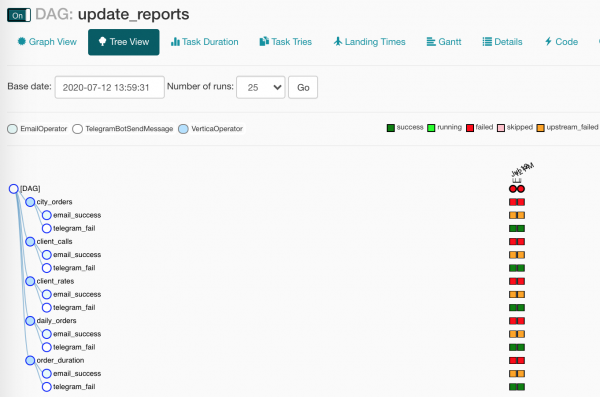
Something is broken in our DAG! Isn’t this what we were waiting for? Exactly!
Are you going to pour?
Do you feel that I missed something? I promised to transfer data from SQL Server to Vertica, and here I went off-topic, what a rascal!
This wrongdoing was intentional, I simply had to clarify some terminology for you. Now we can move on.
Our plan was this:
- Create a DAG
- Generate tasks
- See how beautiful everything looks
- Assign session numbers to the uploads
- Retrieve data from SQL Server
- Place data into Vertica
- Collect statistics
So, to run all this, I made a small addition to our docker-compose.yml:
docker-compose.db.yml
version: '3.4'

x-mssql-base: &mssql-base
  image: mcr.microsoft.com/mssql/server:2017-CU21-ubuntu-16.04
  restart: always
  environment:
    ACCEPT_EULA: Y
    MSSQL_PID: Express
    SA_PASSWORD: SayThanksToSatiaAt2020
    MSSQL_MEMORY_LIMIT_MB: 1024

services:
  dwh:
    image: jbfavre/vertica:9.2.0-7_ubuntu-16.04

  mssql_0:
    <<: *mssql-base

  mssql_1:
    <<: *mssql-base

  mssql_2:
    <<: *mssql-base

  mssql_init:
    image: mio101/py3-sql-db-client-base
    command: python3 ./mssql_init.py
    depends_on:
      - mssql_0
      - mssql_1
      - mssql_2
    environment:
      SA_PASSWORD: SayThanksToSatiaAt2020
    volumes:
      - ./mssql_init.py:/mssql_init.py
      - ./dags/commons/datasources.py:/commons/datasources.py
There we set up:
- Vertica as host
dwhwith the most default settings, - three SQL Server instances,
- filling the databases with some recent data (definitely don’t peek into
mssql_init.py!)
We start everything with a command that’s slightly more complex than last time:
$ docker-compose -f docker-compose.yml -f docker-compose.db.yml up --scale worker=3What our miracle randomizer generated can be accessed using the ‘ Data Profiling/Ad Hoc Query:
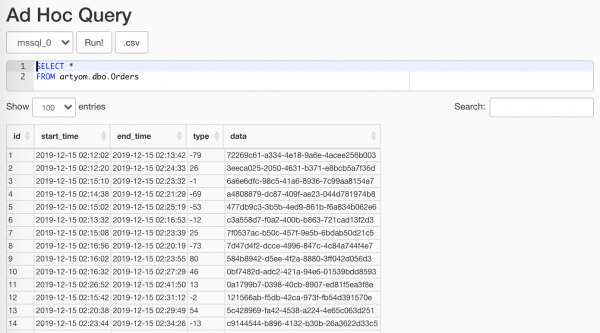
The main thing is not to show this to analysts
I won’t dwell on ETL sessions as it's all trivial: we create a database, within it a table, wrap everything in a context manager, and now we do it this way:
with Session(task_name) as session:
    print('Load', session.id, 'started')

    # Load workflow
    ...

    session.successful = True
    session.loaded_rows = 15
session.py
from sys import stderr

class Session:
    """ETL workflow session

    Example:
        with Session(task_name) as session:
            print(session.id)
            session.successful = True
            session.loaded_rows = 15
            session.comment = 'Well done'
    """

    def __init__(self, connection, task_name):
        self.connection = connection
        self.connection.autocommit = True

        self._task_name = task_name
        self._id = None

        self.loaded_rows = None
        self.successful = None
        self.comment = None

    def __enter__(self):
        return self.open()

    def __exit__(self, exc_type, exc_val, exc_tb):
        if any(exc_type, exc_val, exc_tb):
            self.successful = False
            self.comment = f'{exc_type}: {exc_val}n{exc_tb}'
            print(exc_type, exc_val, exc_tb, file=stderr)
        self.close()

    def __repr__(self):
        return (f'')

    @property
    def task_name(self):
        return self._task_name

    @property
    def id(self):
        return self._id

    def _execute(self, query, *args):
        with self.connection.cursor() as cursor:
            cursor.execute(query, args)
            return cursor.fetchone()[0]

    def _create(self):
        query = """
            CREATE TABLE IF NOT EXISTS sessions (
                id          SERIAL       NOT NULL PRIMARY KEY,
                task_name   VARCHAR(200) NOT NULL,

                started     TIMESTAMPTZ  NOT NULL DEFAULT current_timestamp,
                finished    TIMESTAMPTZ           DEFAULT current_timestamp,
                successful  BOOL,

                loaded_rows INT,
                comment     VARCHAR(500)
            );
            """
        self._execute(query)

    def open(self):
        query = """
            INSERT INTO sessions (task_name, finished)
            VALUES (%s, NULL)
            RETURNING id;
            """
        self._id = self._execute(query, self.task_name)
        print(self, 'opened')
        return self

    def close(self):
        if not self._id:
            raise SessionClosedError('Session is not open')
        query = """
            UPDATE sessions
            SET
                finished    = DEFAULT,
                successful  = %s,
                loaded_rows = %s,
                comment     = %s
            WHERE
                id = %s
            RETURNING id;
            """
        self._execute(query, self.successful, self.loaded_rows,
                      self.comment, self.id)
        print(self, 'closed',
              ', successful: ', self.successful,
              ', Loaded: ', self.loaded_rows,
              ', comment:', self.comment)

class SessionError(Exception):
    pass

class SessionClosedError(SessionError):
    pass
The time has come to retrieve our data from our one hundred and fifty tables. We will do this using very simple lines:
source_conn = MsSqlHook(mssql_conn_id=src_conn_id, schema=src_schema).get_conn()

query = f"""
    SELECT
        id, start_time, end_time, type, data
    FROM dbo.Orders
    WHERE
        CONVERT(DATE, start_time) = '{dt}'
    """

df = pd.read_sql_query(query, source_conn)- Using the hook, we will get from Airflow
pymssql-connection - We will place a date constraint in the query — the template engine will pass it to the function.
- We feed our query
pandas, which will fetch for usDataFrame— it will be useful to us later.
I use substitution
{dt}instead of the query parameter%snot because I am a malicious Buratino, but becausepandascannot cope withpymssqland pushes to the last oneparams: List, although he really wants totuple.
Also note that the developerpymssqldecided not to support it anymore, and it's time to move on topyodbc.
Let's see how Airflow filled the arguments of our functions:
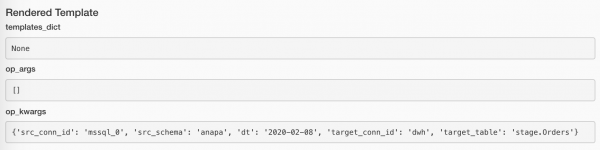
If there is no data, then there is no point in continuing. But considering the upload successful also seems strange. But this is not an error. Ah, what to do?! Here's what:
if df.empty:
    raise AirflowSkipException('No rows to load')
AirflowSkipException will say that there is actually no error, and we are skipping the task. In the interface, there will be neither a green nor a red square, but a pink color.
Let's throw our data a few columns:
df['etl_source'] = src_schema
df['etl_id'] = session.id
df['hash_id'] = hash_pandas_object(df[['etl_source', 'id']])
Namely:
- The database from which we retrieved the orders,
- The identifier of our uploading session (it will be different for each task),
- The hash from the source and the order identifier — so that in the final database (where everything will be aggregated into one table), we have a unique order identifier.
There is one penultimate step left: to upload everything to Vertica. And, strangely enough, one of the most effective ways to do this is through CSV!
# Export data to CSV buffer
buffer = StringIO()
df.to_csv(buffer,
          index=False, sep='|', na_rep='NUL', quoting=csv.QUOTE_MINIMAL,
          header=False, float_format='%.8f', doublequote=False, escapechar='\')
buffer.seek(0)

# Push CSV
target_conn = VerticaHook(vertica_conn_id=target_conn_id).get_conn()

copy_stmt = f"""
    COPY {target_table}({df.columns.to_list()})
    FROM STDIN
    DELIMITER '|'
    ENCLOSED '"'
    ABORT ON ERROR
    NULL 'NUL'
    """

cursor = target_conn.cursor()
cursor.copy(copy_stmt, buffer)- We create a special receiver
StringIO. pandaswill kindly accumulate ourDataFramein the form ofCSV-lines.- We will open a connection to our favorite Vertica hook.
- And now, using
copy()let's send our data straight to Vertica!
From the driver, we will retrieve how many rows were loaded, and we will inform the session manager that everything is OK:
session.loaded_rows = cursor.rowcount
session.successful = True
That's it.
In production, we create the target table manually. Here, I allowed myself a small automation:
create_schema_query = f'CREATE SCHEMA IF NOT EXISTS {target_schema};'
create_table_query = f"""
    CREATE TABLE IF NOT EXISTS {target_schema}.{target_table} (
         id         INT,
         start_time TIMESTAMP,
         end_time   TIMESTAMP,
         type       INT,
         data       VARCHAR(32),
         etl_source VARCHAR(200),
         etl_id     INT,
         hash_id    INT PRIMARY KEY
     );"""

create_table = VerticaOperator(
    task_id='create_target',
    sql=[create_schema_query,
         create_table_query],
    vertica_conn_id=target_conn_id,
    task_concurrency=1,
    dag=dag)
Using
VerticaOperator()I create the DB schema and the table (if they don't exist yet, of course). The main thing is to set the dependencies correctly:
for conn_id, schema in sql_server_ds:
    load = PythonOperator(
        task_id=schema,
        python_callable=workflow,
        op_kwargs={
            'src_conn_id': conn_id,
            'src_schema': schema,
            'dt': '{{ ds }}',
            'target_conn_id': target_conn_id,
            'target_table': f'{target_schema}.{target_table}'},
        dag=dag)

    create_table >> load
Summing up
— There you go, — said the little mouse, — isn't it true that now
Have you verified that I'm the fiercest beast in the forest?
Julia Donaldson, 'The Gruffalo'
I think if my colleagues and I held a competition: who can create and launch an ETL process from scratch the fastest: them with their SSIS and mouse, and I with Airflow... And then we would compare the convenience of maintenance... Oh, I believe you would agree that I would surpass them on all fronts!
If we take it a bit more seriously, Apache Airflow — thanks to the process description in the form of code — has made my job much more convenient and enjoyable.
Its unlimited scalability: both in terms of plugins and its readiness for scalability — gives you the ability to apply Airflow in virtually any field: whether in the full cycle of data collection, preparation, and processing, or in launching rockets (to Mars, of course).
Final part, informational reference
The pitfalls we've gathered for you
start_date. Yes, this is already a local meme. Through the main argument of the DAGstart_dateeverything passes. Briefly, if you specify in thestart_datecurrent date, and in theschedule_interval— one day, then the DAG will not start tomorrow any sooner.start_date = datetime(2020, 7, 7, 0, 1, 2)And no more problems.
It is also related to another execution error:
Task is missing the start_date parameter, which most often indicates that you forgot to attach a DAG operator.- Everything on one machine. Yes, both the databases (of Airflow itself and our application), the web server, the scheduler, and the workers. And it actually worked. But over time, the number of tasks for the services grew, and when PostgreSQL started delivering responses by index in 20 ms instead of 5 ms, we took it and moved it.
- LocalExecutor. Yes, we are still on it, and we have already come to the edge of the abyss. LocalExecutor has been sufficient until now, but now it’s time to expand by at least one worker, and we will have to put in some effort to switch to CeleryExecutor. And since it can even work on a single machine, nothing stops us from using Celery even on a server that 'naturally will never go into production, I swear!'
- Not using built-in tools:
- Connections for storing service credentials,
- SLA Misses to respond to tasks that did not complete on time,
- XCom for exchanging metadata (I said metadata!) between DAG tasks.data!) between the tasks of the DAG.
- Email Overload. What can I say? Alerts were set up for all the repeats of failed tasks. Now my work Gmail has over 90k emails from Airflow, and the web interface refuses to process and delete more than 100 at a time.
More pitfalls:
Tools for even greater automation
To help us work more with our brains rather than our hands, Airflow has prepared the following:
- — it still has Experimental status, which doesn’t stop it from working. With it, you can not only retrieve information about DAGs and tasks, but also stop/start a DAG, create a DAG Run or a pool.
- — many utilities are available through the command line that are not just inconvenient to access via WebUI, but are even absent altogether. For example:
backfillis used to re-run task instances.
For example, analysts come in and say: "Hey, you've got garbage data from January 1 to 13! Fix it, fix it, fix it!" And you go:airflow backfill -s '2020-01-01' -e '2020-01-13' orders- Database Maintenance:
initdb,resetdb,upgradedb,checkdb. run, which allows you to run a single task instance, ignoring all dependencies. Moreover, you can run it throughLocalExecutor, even if you have a Celery cluster.- It does approximately the same thing as
test, but it doesn’t write anything into the database. connectionsallows mass creation of connections from the shell.
- — quite a hardcore way of interaction, intended for plugins, not for manual fiddling. But who will stop us from heading into
/home/airflow/dags, launchingipythonand starting to do some serious work? For instance, you can export all connections with this code:from airflow import settings from airflow.models import Connection fields = 'conn_id conn_type host port schema login password extra'.split() session = settings.Session() for conn in session.query(Connection).order_by(Connection.conn_id): d = {field: getattr(conn, field) for field in fields} print(conn.conn_id, '=', d) - Connection to the Airflow metadata database. I don’t recommend writing to it, but retrieving task states for various specific metrics can be done much faster and easier than through any API.
Let’s say, not all of our tasks are idempotent and can fail sometimes, which is normal. But multiple failures are suspicious, and we should check.
Caution, SQL!
WITH last_executions AS (
SELECT
    task_id,
    dag_id,
    execution_date,
    state,
        row_number()
        OVER (
            PARTITION BY task_id, dag_id
            ORDER BY execution_date DESC) AS rn
FROM public.task_instance
WHERE
    execution_date > now() - INTERVAL '2' DAY
),
failed AS (
    SELECT
        task_id,
        dag_id,
        execution_date,
        state,
        CASE WHEN rn = row_number() OVER (
            PARTITION BY task_id, dag_id
            ORDER BY execution_date DESC)
                 THEN TRUE END AS last_fail_seq
    FROM last_executions
    WHERE
        state IN ('failed', 'up_for_retry')
)
SELECT
    task_id,
    dag_id,
    count(last_fail_seq)                       AS unsuccessful,
    count(CASE WHEN last_fail_seq
        AND state = 'failed' THEN 1 END)       AS failed,
    count(CASE WHEN last_fail_seq
        AND state = 'up_for_retry' THEN 1 END) AS up_for_retry
FROM failed
GROUP BY
    task_id,
    dag_id
HAVING
    count(last_fail_seq) > 0
Links
And of course, the first ten links from Google's search results contain my Airflow folder's contents.
- — of course, it’s important to start with the official documentation, but who actually reads the instructions?
- — at least read the recommendations from the creators.
- — the very beginning: the user interface illustrated
- — well explained basic concepts, in case (just in case!) you didn't understand something from my explanation.
- — a brief guide on setting up an Airflow cluster.
- — a similarly interesting article, but with more formalism and fewer examples.
- — about working with Celery.
- — on task idempotence, loading by ID instead of date, transformations, file structure, and other interesting aspects.
- — task dependencies and Trigger Rules, which I only mentioned briefly.
- — how to overcome some "works as intended" issues with the scheduler, load lost data, and prioritize tasks.
- — useful SQL queries for Airflow metadata.
- — there's a useful section on creating a custom sensor.
- — an interesting short note on building AWS infrastructure for Data Science.
- — common errors (when some still don't read the instructions).
- — smile, as people struggle with password storage, when you could simply use Connections.
- — implicit DAG passing, context injection in functions, again about dependencies, and also about skipping task runs.
- — on usage
default argumentsandparamsin templates, as well as about Variables and Connections. - — a story of how the scheduler is prepared for Airflow 2.0.
- — a slightly outdated article about deploying our cluster in
docker-compose. - — dynamic tasks using templates and context passing.
- — standard and custom notifications via email and Slack.
- — Task branching, macros, and XCom.
And the links used in the article:
- — placeholders available for use in templates.
- — Common mistakes when creating DAGs.
- —
docker-composefor experiments, debugging, and more. - — Python wrapper for the Telegram REST API.
Source: habr.com
