

The SDSM has ended, but the uncontrollable desire to write remains.
For many years, our brother suffered from routine tasks, crossing his fingers before commits and losing sleep due to nightly rollbacks.
But dark times come to an end.
With this article, I will start a series on how to me automation is perceived.
Along the way, we will look into automation stages, variable storage, design formalization, RestAPI, NETCONF, YANG, YDK, and we will be doing a lot of programming.
To me it means that a) this is not an objective truth, b) it is not an unconditionally best approach, c) my perspective may even change while moving from the first to the last article — honestly, from the draft stage to publication, I completely rewrote everything twice.
Content
- Objectives
- The network is like a single organism
- Configuration testing
- Versioning
- Monitoring and self-recovery of services
- Tools
- Inventory system
- IP space management system
- Network service description system
- Device initialization mechanism
- Vendor-agnostic configuration model
- Vendor-specific interface driver
- Configuration delivery mechanism to the device
- CI/CD
- Backup mechanism and anomaly detection
- Monitoring system
- Conclusion
I will try to conduct ADSCM in a format slightly different from SDSM. There will still be extensive numbered articles, and between them, I will publish small notes from everyday experience. I will attempt to fight perfectionism and not polish each of them.
How funny it is to walk the same path for the second time.
Initially, I had to write articles about networks myself because they were lacking in the RuNet.
Now I couldn't find a comprehensive document that systematizes approaches to automation and analyzes the aforementioned technologies with simple practical examples.
Perhaps I am mistaken, so feel free to share links to valuable resources. However, this will not change my determination to write because the main goal is to learn something myself, and making life easier for others is a pleasant bonus that tickles the urge to spread knowledge.
We will attempt to take a medium-sized data center, LAN DC, and work through the entire automation scheme.
I will be doing some things for the first time alongside you.
I won't be original in the ideas and tools described here. Dmitry Figol has an excellent .
The articles will intersect with these in many aspects.
In the LAN DC, there are 4 data centers, about 250 switches, half a dozen routers, and a couple of firewalls.
It's not Facebook, but it's enough to think deeply about automation.
However, there is an opinion that if you have more than one device, automation is already necessary.
In reality, it's hard to imagine someone living without at least a handful of knee scripts.
Though I’ve heard of companies where IP addresses are tracked in Excel, and each of the thousands of network devices is configured manually with its unique configuration. This can certainly be passed off as modern art, but an engineer's feelings will definitely be hurt.
Objectives
Now we will set the most abstract goals:
- The network is like a single organism
- Configuration testing
- Versioning the state of the network
- Monitoring and self-recovery of services
Later in this article, we will discuss what tools we will use, and in the following ones, the goals and means in detail.
The network is like a single organism
The defining phrase of the cycle, though it may seem insignificant at first glance: we will configure the network, not individual devices..
In recent years, we've seen a shift towards treating the network as a single entity, hence the arrival of Software Defined Networking, Intent Driven Networks and Autonomous Networks.
After all, what do applications fundamentally need from the network: connectivity between points A and B (and sometimes C) and isolation from other applications and users.
Thus, our task in this series is to build a system, supporting the current configuration of the entire network, which is already decomposed into the current configuration on each device according to its role and location.
System Network management implies that to make changes, we refer to it, and it then calculates the necessary state for each device and configures it.
In this way, we minimize human CLI access to almost zero — any changes in device settings or network design must be formalized and documented — and only then applied to the necessary network elements.
For instance, if we decide that from this moment forward, rack switches in Kazan should announce two networks instead of one, we
- First, we document the changes in the systems
- We generate the target configuration for all network devices
- We launch the network configuration update program, which calculates what needs to be removed on each node, what to add, and brings the nodes to the required state.
At this stage, we manually make changes only during the first step.
Configuration testing
, that 80% of problems occur during configuration changes — indirect evidence of this is that during the New Year holidays, everything is usually calm.
I have personally witnessed dozens of global downtimes due to human error: an incorrect command executed, not on the right configuration branch, forgetting the community, globally deleting MPLS on a router, configuring five devices, but missing an error on the sixth, committing old changes made by someone else. There are countless scenarios.
Automation will allow us to make fewer mistakes, but on a larger scale. This way, we could brick not just one device, but the entire network at once.
Since time immemorial, our ancestors checked the correctness of the changes made with keen eyes, steel nerves, and the operability of the network after deployment.
Those ancestors whose work led to downtimes and catastrophic losses left fewer descendants and should eventually die out, but evolution is a slow process, and therefore, not everyone still tests changes in the lab beforehand.
However, at the forefront of progress are those who automated the configuration testing process, and its further application to the network. In other words — borrowed the CI/CD procedure () from developers.
In one of the sections, we will examine how to implement this using a version control system, probably GitHub.
Once you come to terms with the idea of network CI/CD, the method of validating configuration by applying it to a live network will seem to you like early medieval ignorance. About as ridiculous as hitting a warhead with a hammer.
An organic continuation of the ideas about network management system and CI/CD becomes full-fledged configuration versioning. network management and CI/CD is becoming complete versioning of the configuration.
Versioning
We will assume that any changes, even the smallest, even on one unnoticed device, will cause the entire network to transition from one state to another.
And we never execute commands on the device; we change the state of the network instead.
So, shall we call these states versions?
Let's say the current version is 1.0.0.
Has the IP address of the loopback interface changed on one of the ToRs? That’s a minor version change — it will be numbered 1.0.1.
If we've revised the route import policies in BGP — that's a bit more serious — and already 1.1.0.
Decided to get rid of IGP and switch only to BGP — that’s a radical design change — 2.0.0.
At the same time, different data centers can have different versions — the network is evolving, new equipment is being installed, sometimes new spine levels are added, and sometimes they are not, etc.
About we will discuss it in a separate article.
I repeat — any change (except for debugging commands) is a version update. Administrators must be notified of any deviations from the current version.
The same goes for rolling back changes — this isn't the cancellation of the last commands, it’s not a rollback by the device's operating system — it’s bringing the entire network back to a new (previous) version.
Monitoring and self-recovery of services
This obvious task in modern networks is reaching a new level.
Often, large service providers practice the approach of very quickly terminating a failed service and raising a new one, instead of figuring out what happened.
“Very” means that one needs to slather on monitoring from all sides, which will detect the slightest deviations from the norm within seconds.
And here, the usual metrics, like interface load or node availability, are no longer sufficient. Manual monitoring by the on-duty personnel is also not enough.
For many things, there should be a — the monitors lit up red and went to apply a band-aid on where it hurts.
Here, we monitor not only individual devices but also the health of the entire network, both as a white box, which is relatively clear, and as a black box, which is more complex.
What do we need to implement such ambitious plans?
- We need a list of all devices in the network, their locations, roles, models, and software versions.
kazan-leaf-1.lmu.net, Kazan, leaf, Juniper QFX 5120, R18.3. - We need a system for describing network services.
IGP, BGP, L2/3VPN, Policy, ACL, NTP, SSH. - Be able to initialize the device.
Hostname, Mgmt IP, Mgmt Route, Users, RSA-Keys, LLDP, NETCONF - Configure the device and revert the configuration to the desired (including the old) version.
- Test the configuration
- Periodically check the status of all devices for deviations from the current state and report to the appropriate parties.
At night, someone quietly added a rule to the ACL. - Monitor performance.
Tools
It sounds complex enough to start breaking down the project into components.
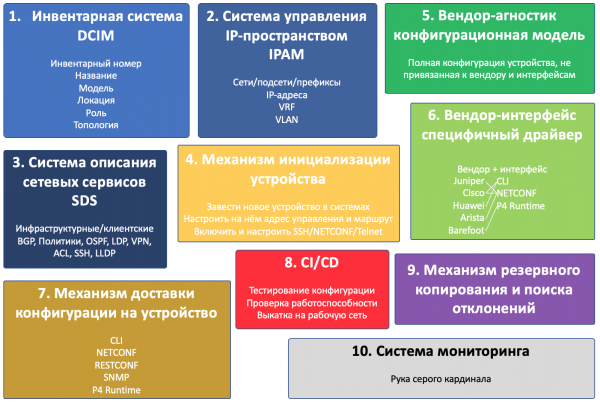
And there will be ten of them:
- Inventory system
- IP space management system
- Network service description system
- Device initialization mechanism
- Vendor-agnostic configuration model
- Vendor-specific interface driver
- Configuration delivery mechanism to the device
- CI/CD
- Backup mechanism and anomaly detection
- Monitoring system
This is, by the way, an example of how the view of the cycle's goals changed — the draft of the components had 4.
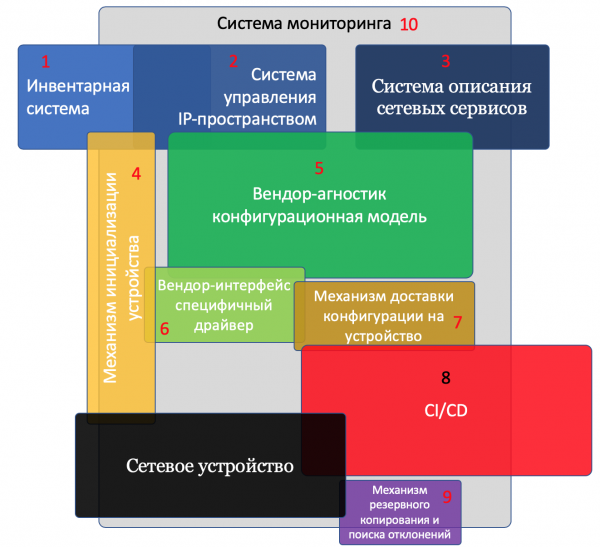
In the illustration, I depicted all components and the device itself.
Intersecting components interact with each other.
The larger the block, the more attention needs to be paid to this component.
Component 1. Inventory System
Clearly, we want to know what equipment is where and what it is connected to.
The inventory system is an integral part of any enterprise.
Most often, for network devices, the enterprise has a separate inventory system that addresses more specific tasks.
In this series of articles, we will refer to it as DCIM — Data Center Infrastructure Management. Although the term DCIM, strictly speaking, encompasses much more.
For our purposes, we will store the following information about the device:
- Inventory number
- Name/description
- Model (Huawei CE12800, Juniper QFX5120, etc.)
- Characteristics (boards, interfaces, etc.)
- Role (Leaf, Spine, Border Router, etc.)
- Location (region, city, data center, rack, unit)
- Interconnects between devices
- Network topology
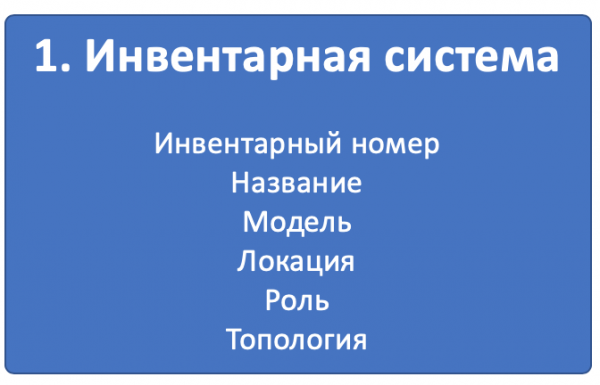
It's clear that we ourselves want to know all this.
But will this help with automation?
Absolutely.
For example, we know that in this data center on Leaf switches, if it is Huawei, ACLs for filtering certain traffic should be applied to VLAN, and if it is Juniper — then on unit 0 of the physical interface.
Or we need to deploy a new Syslog server on all borders of the region.
We will also store virtual network devices, such as virtual routers or route reflectors. We can add DNS servers, NTP, Syslog, and generally everything related to the network.
Component 2. IP Space Management System
Yes, even in our time, there are groups of people who keep track of prefixes and IP addresses in an Excel file. However, the modern approach is still to use a database, with a frontend on nginx/apache, an API, and extensive capabilities for managing IP addresses and networks with VRF segmentation.
IPAM – IP Address Management.
For our tasks, we will store the following information in it:
- VLAN
- VRF
- Networks/Subnets
- an IP address
- Binding addresses to devices, networks to locations, and VLAN numbers
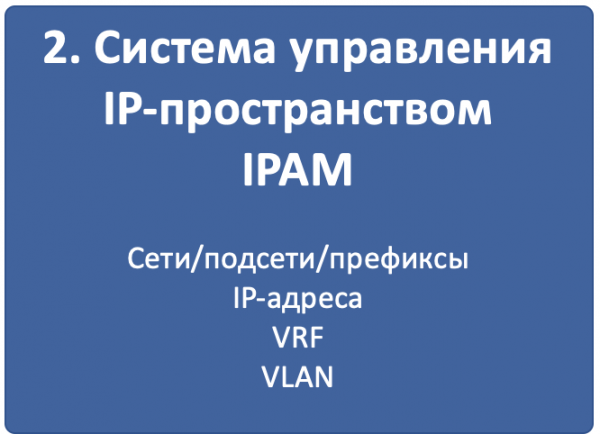
Again, it is clear that we want to be confident that when assigning a new IP address for a ToR loopback, we do not stumble upon the fact that it has already been assigned to someone else. Or that the same prefix has been used twice at different ends of the network.
But how will this help with automation?
Easy.
We request a prefix from the system with the role of Loopbacks that has available IP addresses to allocate — if found, we allocate the address; if not, we request the creation of a new prefix.
Or when creating a device configuration, we can learn from the same system which VRF the interface should be in.
And when launching a new server, the script will go into the system to find out which server switch it is in, which port, and what subnet is assigned to the interface — from that, the server address will be allocated.
It makes sense to combine DCIM and IPAM into one system to avoid duplicating functions and servicing two similar entities.
And we will do just that.
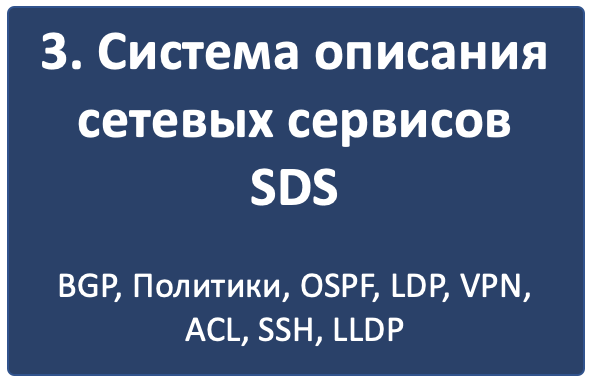
Component 3. Network Services Description System
While the first two systems store variables that still need to be used somehow, the third describes how each device role should be configured.
It is worth highlighting two different types of network services:
- Infrastructure
- Client.
The first provides basic connectivity and device management. This includes VTY, SNMP, NTP, Syslog, AAA, routing protocols, CoPP, etc.
The second organizes services for the client: MPLS L2/L3VPN, GRE, VXLAN, VLAN, L2TP, etc.
Of course, there are also edge cases — where to categorize MPLS LDP, BGP? Routing protocols can also be used for clients. But that is not critical.
Both types of services break down into configuration primitives:
- Physical and logical interfaces (tag/untag, mtu)
- IP addresses and VRF (IP, IPv6, VRF)
- ACLs and traffic processing policies
- Protocols (IGP, BGP, MPLS)
- Routing policies (prefix lists, communities, ASN filters).
- Service services (SSH, NTP, LLDP, Syslog…)
- Etc.
I can't quite figure out how exactly we will do this. We'll address it in a separate article.
If we relate it to real life, we could describe that
The Leaf switch must have BGP sessions with all connected Spine switches, import connected networks into the process, and accept only networks from a specific prefix from the Spine switches. Limit CoPP IPv6 ND to 10 pps, etc.
In turn, the Spine switches maintain sessions with all connected Leaf switches, acting as route reflectors, and only accept routes of a certain length and with a specific community from them.
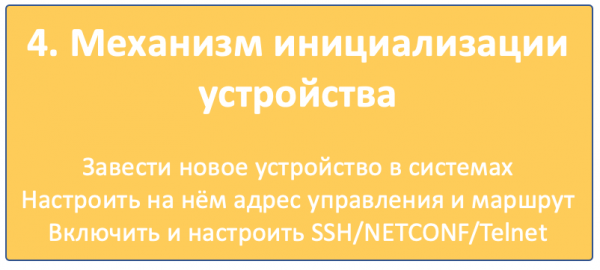
Component 4. Device Initialization Mechanism
Under this heading, I am combining many actions that must happen for the device to appear on the radar and be remotely accessible.
- Add the device to the inventory system.
- Allocate a management IP address.
- Configure basic access to it:
Hostname, management IP address, route to the management network, users, SSH keys, protocols — telnet/SSH/NETCONF
There are three approaches here:
- Everything entirely manual. The device is brought to the stand where an ordinary organic person will add it to the systems, connect via the console, and configure it. This might work for small static networks.
- ZTP — Zero Touch Provisioning. The hardware arrives, powers on, obtains an address via DHCP, goes to a special server, and self-configures.
- Infrastructure of console servers where the initial configuration takes place through the console port in automatic mode.
We'll talk about all three in a separate article.
Component 5. Vendor-Agnostic Configuration Model
Until now, all systems have been disparate patches providing variables and declarative descriptions of what we would like to see in the network. But sooner or later, we will have to deal with specifics.
At this stage, for each specific device, primitives, services, and variables are combined into a configuration model that effectively describes the complete configuration of that device, but in a vendor-independent manner.
What does this step provide? Why not form the device configuration directly, which can simply be uploaded?
In fact, it allows us to solve three tasks:
- Do not adapt to a specific device interaction interface. Whether it's CLI, NETCONF, RESTCONF, or SNMP, the model will be the same.
- Do not maintain the number of templates/scripts based on the number of vendors in the network; if the design changes, update the same thing in multiple places.
- Download the configuration from the device (backup), structure it into the exact same model, and directly compare the target configuration with the existing one to calculate the delta and prepare a configuration patch that will change only the necessary parts or identify discrepancies.
As a result of this stage, we obtain a vendor-independent configuration.
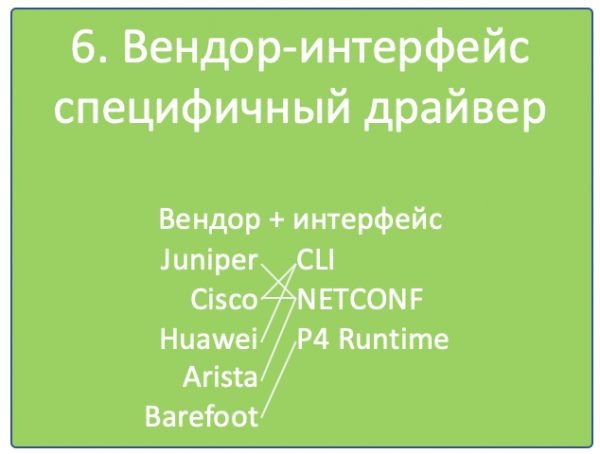
Component 6. Vendor-specific driver interface
Do not entertain the hope that one day configuring Cisco will be exactly the same as Juniper, simply by sending absolutely identical calls to them. Despite the increasing popularity of whiteboxes and the emergence of support for NETCONF, RESTCONF, and OpenConfig, the specific content delivered by these protocols differs from vendor to vendor, and this is one of their competitive distinctions that they will not easily give up.
It's roughly the same as OpenContrail and OpenStack, which have RestAPI as their NorthBound interface, expecting completely different calls.
So, in the fifth step, the vendor-independent model must take the form in which it will be sent to the hardware.
And here, anything goes (not really): CLI, NETCONF, RESTCONF, SNMP, simply due to necessity.
Therefore, we will need a driver that will transform the result of the previous step into the required format for a specific vendor: a set of CLI commands or XML structure.
Component 7. Mechanism for delivering configuration to the device
We have generated the configuration, but it still needs to be delivered to the devices — and obviously, not manually.
Firstly, we face the question of which transport to use? The choice today is quite vast:
- CLI (telnet, ssh)
- SNMP
- NETCONF
- RESTCONF
- REST API
- OpenFlow (although it stands out from the list, as it's a way to deliver FIB rather than configuration)
Let's clarify things here. CLI is legacy. SNMP... ahem.
RESTCONF is still an unknown creature; REST API is supported by almost no one. Therefore, we will focus on NETCONF in this iteration.
As the reader may already understand, we have settled on the interface by this point — the result of the previous step has already been presented in the format of the chosen interface.
Secondly, but what tools will we use to do this?
There are also many choices here:
- A custom script or platform. We will equip ourselves with ncclient and asyncIO and do it ourselves. How hard can it be to build a deployment system from scratch?
- Ansible, with its rich library of network modules.
- Salt, with its limited network functionality and integration with Napalm.
- Napalm itself, which knows a couple of vendors and that's it, farewell.
- Nornir — another tool we'll dissect in the future.
Here a favorite has not yet been chosen — we will have to explore.
What else is important here? The consequences of applying the configuration.
Whether it succeeded or not. Whether access to the device remains or not.
It seems that a commit with confirmation and validation of what has been loaded onto the device will help here.
This, combined with the correct implementation of NETCONF, significantly narrows the range of suitable devices — normal commits are not supported by many manufacturers. But this is just one of the necessary conditions in . After all, no one worries that no Russian vendor will meet the condition of a 32*100GE interface. Or do they?
Component 8. CI/CD
By this point, we already have the configuration ready for all the devices in the network.
I say "for all" because we are talking about versioning the state of the network. And even if it’s necessary to change the settings of just one switch, changes are calculated for the entire network. Obviously, they can be zero for most nodes.
But, as already mentioned above, we are not some kind of barbarians to deploy everything to production at once.
The generated configuration must go through the CI/CD Pipeline first.
CI/CD stands for Continuous Integration, Continuous Deployment. This approach allows the team to not just release a new major version every six months, completely replacing the old one, but to regularly implement new functionality incrementally (Deployment) in small portions, each of which is thoroughly tested for compatibility, security, and functionality (Integration).
For this, we have a version control system that tracks changes in configuration, a lab where we check whether the client service remains intact, a monitoring system that verifies this fact, and the final step — deploying changes to the production network.
With the exception of debugging commands, absolutely all changes to the network must go through the CI/CD Pipeline — this is our key to a peaceful life and a long, happy career.
Component 9. Backup and deviation detection system
Well, there's no need to go over backups again.
We will just store them on a cron schedule or when there is a change in configuration in Git.
Now the second part is more interesting — someone has to keep an eye on these backups. In some cases, this person must restore everything to its previous state, and in others, they need to notify someone about any irregularities.
For example, if a new user appears who is not listed in the variables, it needs to be removed quickly to avoid any hacks. And if there is a new firewall rule — it’s better not to change it; someone might just have enabled debugging, or maybe a careless new service wrote its configuration incorrectly, and people have already started using it.
We cannot escape some minor delta on the scale of the entire network, regardless of any automation systems and the firm hand of management. For troubleshooting issues, no one will still make changes to the configuration in the systems. Moreover, the configuration model may not even anticipate them.
For instance, a firewall rule for counting packets to a specific IP, used for localizing problems — is quite a standard temporary configuration.
Component 10. Monitoring system
At first, I didn’t plan to address the topic of monitoring — it is indeed a vast, contentious, and complex subject. But it turned out that it is an integral part of automation. We can't overlook it even without practical experience.
Further developing the thought — it is an organic part of the CI/CD process. After deploying the configuration to the network, we need to be able to determine if everything is now in order.
And it's not only about usage graphs of interfaces or node availability, but also about more nuanced aspects — the presence of necessary routes, attributes, the number of BGP sessions, OSPF neighbors, and the end-to-end operability of the higher-level services.
Have the syslogs stopped being sent to the external server, has the SFlow agent failed, have drops started to increase in the queues, and has the connectivity between any pair of prefixes been disrupted?
In a separate article, we will ponder this as well.
Conclusion
I chose one of the modern data center network designs as a base — L3 Clos Fabric with BGP as the routing protocol.
This time, we will build the network using Juniper, because now the JunOs interface is just a breeze.
We will complicate our lives by using only Open Source tools and a multi-vendor network — so besides Juniper, I'll choose another lucky winner as we go along.
The plan for upcoming publications is roughly as follows:
First, I will talk about virtual networks. Firstly, because I want to, and secondly, because without this, the design of the infrastructure network will not be very clear.
Then we will discuss the design of the network itself: topology, routing, policies.
We will assemble a lab setup.
We will reflect and perhaps practice initializing a device in the network.
Next, we will go into intimate details about each component.
And yes, I don't promise to gracefully conclude this cycle with a ready solution. 🙂
Useful links
- Before delving into the series, it's worth reading Natasha Samoylenko's book . And perhaps also go through .
- It will also be useful to read on the design of data center fabrics from Facebook authored by Petr Lapukhov.
- Documentation on the architecture will give you an idea of how Overlay SDN works (previously Open Contrail).
Thanks
Romanorge. For comments and edits.
Artem Chernobay. For the KDPV.
Source: habr.com
