

This article will help you understand how load balancing works in Kubernetes, what happens during the scaling of long-lived connections, and why you should consider client-side load balancing when using HTTP/2, gRPC, RSockets, AMQP, or other long-lived protocols.
A brief overview of how traffic is redistributed in Kubernetes
Kubernetes provides two convenient abstractions for deploying applications: Services and Deployments.
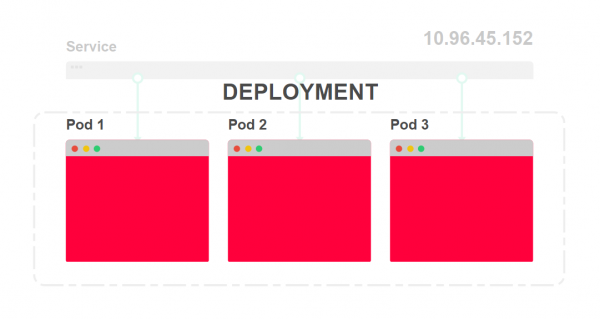
Deployments describe how many instances of your application should be running at any given time. Each application is deployed as a Pod and assigned an IP address.
Services function similarly to load balancers. They are designed to distribute traffic across multiple Pods.
Let's see how this looks.
- In the diagram below, you can see three instances of one application and a load balancer:

- The load balancer is called a Service, and it is assigned an IP address. Any incoming request is forwarded to one of the Pods:

- The deployment scenario defines the number of instances of the application. You will almost never have to deploy a Pod directly:

- Each Pod is assigned its own IP address:

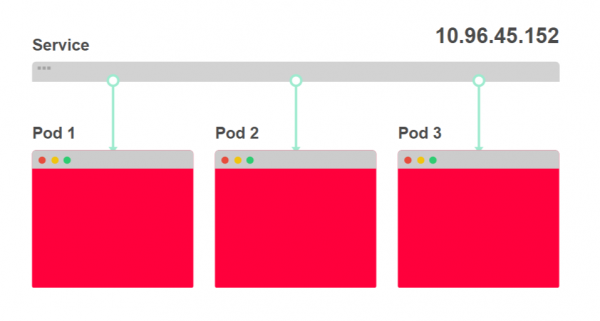
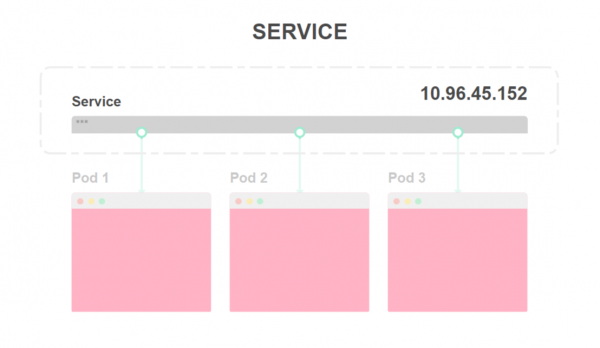
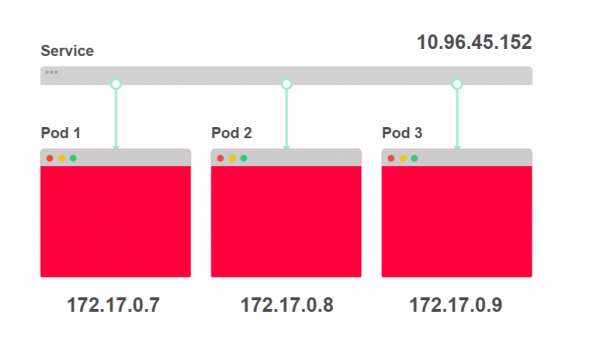
It's useful to think of Services as a set of IP addresses. Each time you access a Service, one of the IP addresses is selected from the list and used as the destination address.
It looks like this.
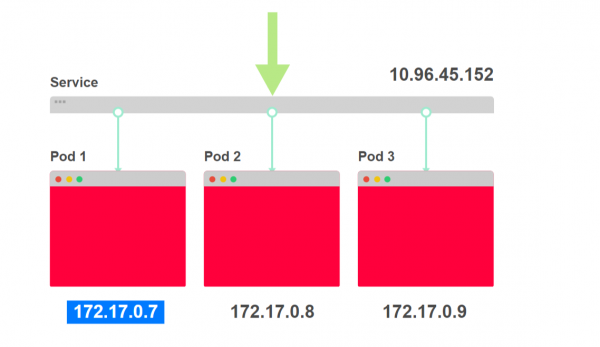
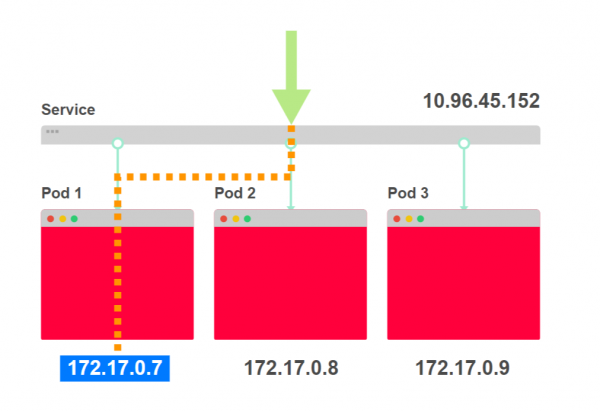
- A curl request to the service from 10.96.45.152 comes in:

- The Service selects one of the three Pod addresses as a destination:

- Traffic is redirected to a specific Pod:


If your application consists of a frontend and a backend, you will have both a Service and a Deployment for each.
When the frontend makes a request to the backend, it does not need to know how many Pods the backend is serving: there may be one, ten, or a hundred.
The frontend also knows nothing about the addresses of the Pods serving the backend.
When the frontend makes a request to the backend, it uses the IP address of the backend Service, which does not change.
Here's how it looks.
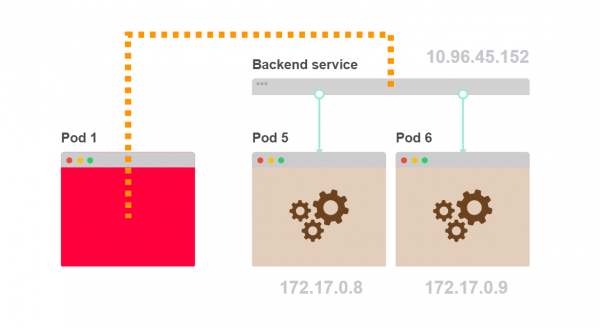
- Pod 1 requests an internal component of the backend. Instead of selecting a specific backend Pod, it makes a request to the Service:

- The service selects one of the backend pods as the destination address:

- Traffic goes from pod 1 to pod 5, selected by the service:

- Pod 1 does not know how many such pods as pod 5 are hidden behind the service:

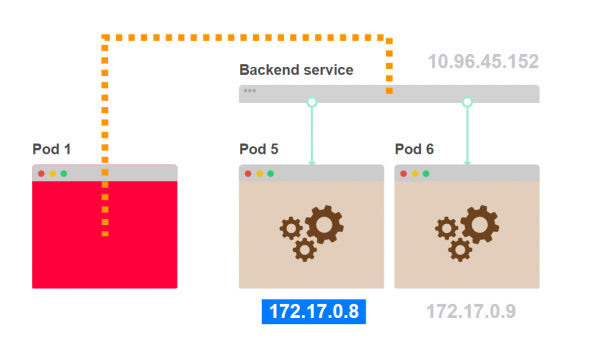
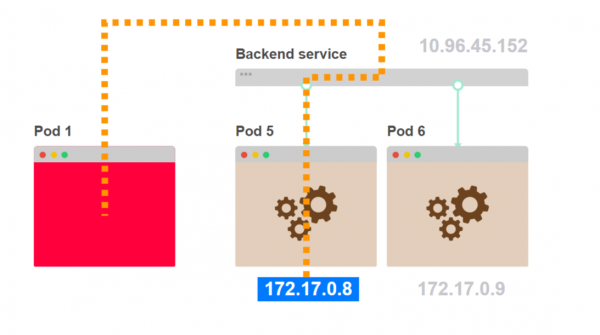
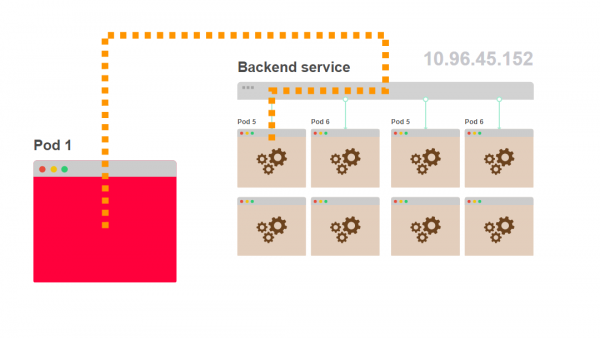
But how exactly does the service distribute requests? It seems that round-robin balancing is used? Let's find out.
Load Balancing in Kubernetes Services
Kubernetes services do not exist. There is no process assigned an IP address and port for the service.
You can verify this by going to any node in the cluster and executing the netstat -ntlp command.
You won't even be able to find the IP address assigned to the service.
The service's IP address is located in the control layer, in the controller, and is recorded in the database — etcd. This same address is used by another component — kube-proxy.
Kube-proxy receives a list of IP addresses for all services and creates a set of iptables rules on each node in the cluster.
These rules state: "If we see the service's IP address, we need to modify the destination address of the request and send it to one of the pods."
The service's IP address is used only as an entry point and is not handled by any process listening to this IP address and port.
Let's take a look at this.
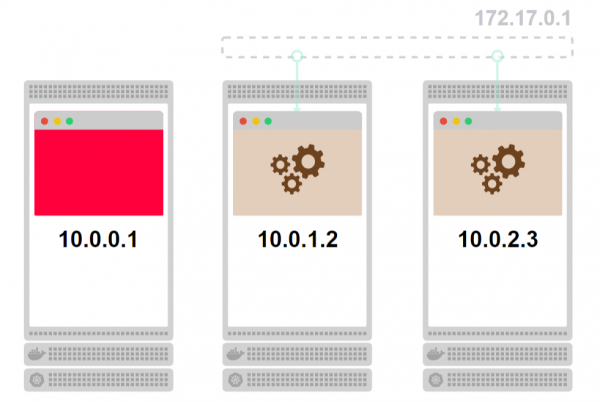
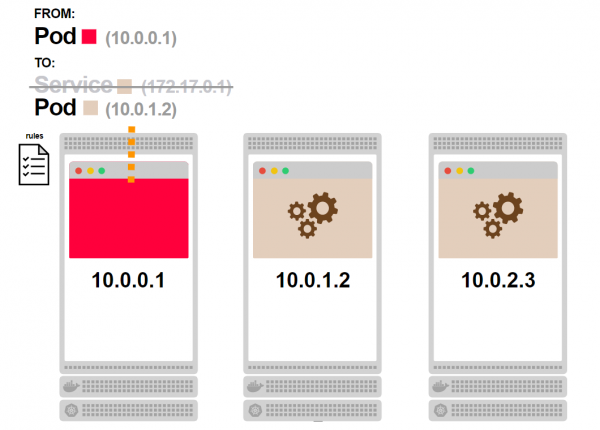
- Consider a cluster with three nodes. Each node has pods:

- Connected pods, shaded beige, are part of the service. Since the service does not exist as a process, it is depicted in gray:

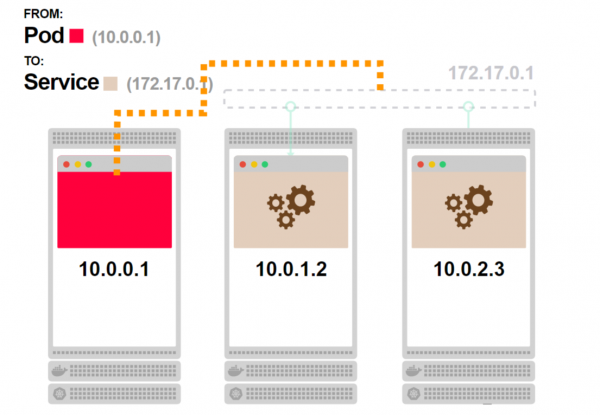
- The first pod requests the service and should reach one of the connected pods:

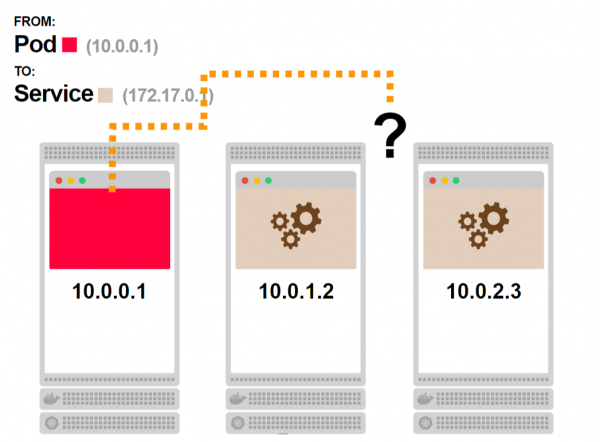
- But the service does not exist; there is no process. How does this work?

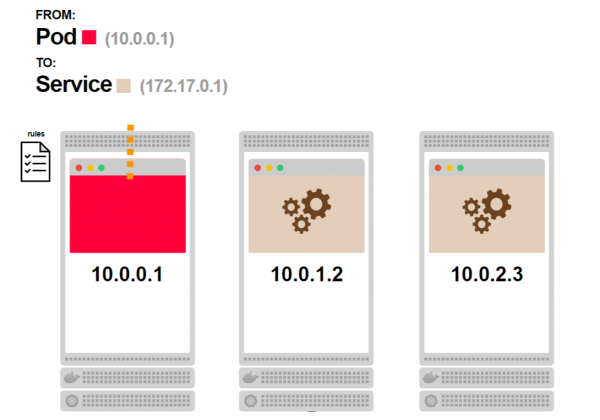
- Before the request leaves the node, it goes through the iptables rules:

- The iptables rules know that the service does not exist and replace its IP address with one of the IP addresses of the pods associated with this service:

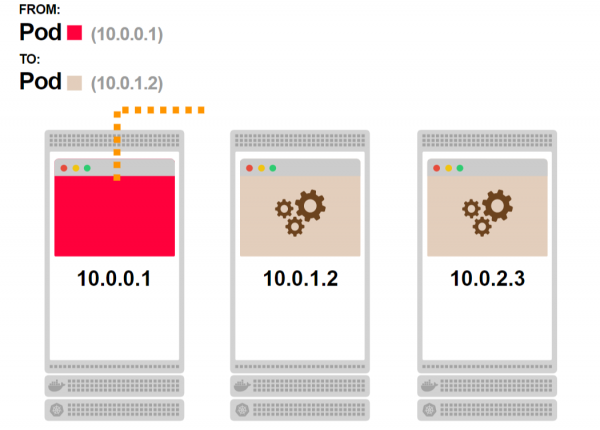
- The request receives a valid IP address as the destination address and is processed normally:
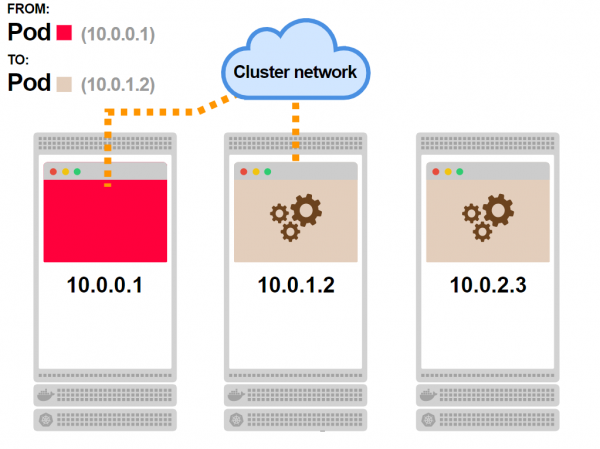
- Depending on the network topology, the request ultimately reaches the pod:

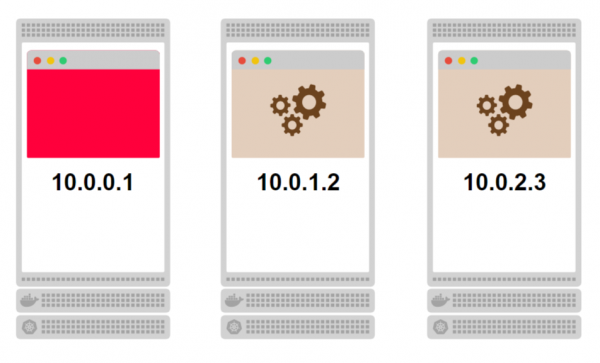
Can iptables balance the load?
No, iptables are used for filtering and were not designed for balancing.
However, there is an option to write a set of rules that work like .
And this is what is implemented in Kubernetes.
If you have three pods, kube-proxy will write the following rules:
- Select the first pod with a probability of 33%, otherwise move to the next rule.
- Select the second pod with a 50% probability, or move on to the next rule.
- Select the third pod.
This system results in each pod being selected with a 33% probability.
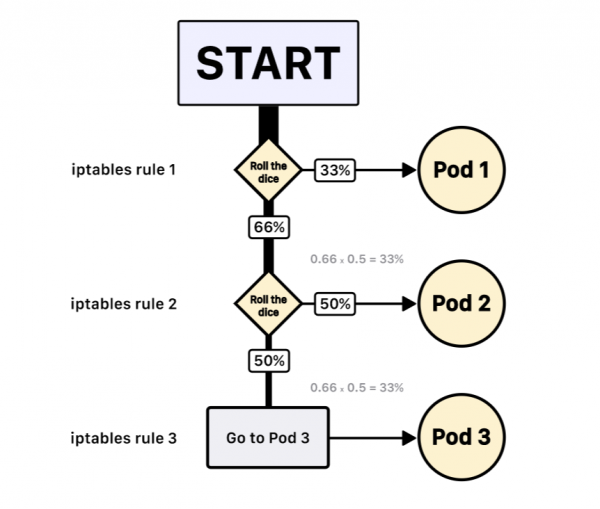
And there is no guarantee that pod 2 will be chosen next after pod 1.
Note: iptables uses a statistical module with random distribution. Thus, the load balancing algorithm is based on random selection.
Now that you understand how services work, let's look at more interesting scenarios.
Long-lived connections in Kubernetes do not scale by default.
Each HTTP request from the frontend to the backend is serviced by a separate TCP connection that is opened and closed.
If the frontend sends 100 requests per second to the backend, 100 different TCP connections will be opened and closed.
Processing time can be reduced and load decreased by opening a single TCP connection and using it for all subsequent HTTP requests.
The HTTP protocol has a built-in feature called HTTP keep-alive, or connection reuse. In this case, a single TCP connection is used for sending and receiving multiple HTTP requests and responses:
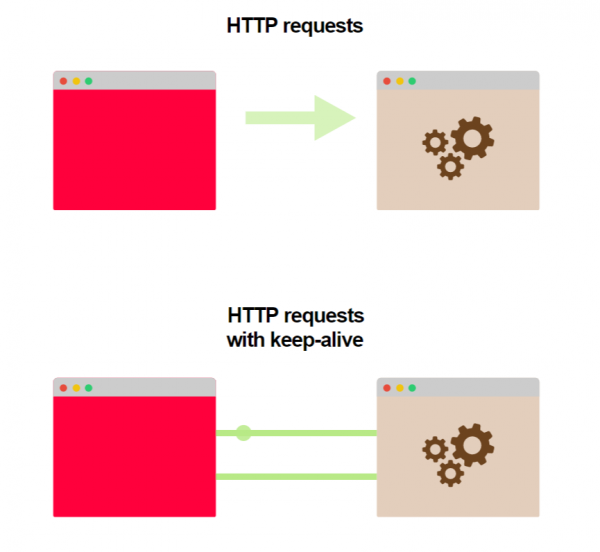
This feature is not enabled by default: both the server and client must be configured accordingly.
The configuration itself is straightforward and available for most programming languages and environments.
Here are some links to examples in different languages:
What happens if we use keep-alive in a Kubernetes service?
Let's assume that both the frontend and the backend support keep-alive.
We have one frontend instance and three backend pods. The frontend makes the first request and opens a TCP connection to the backend. The request reaches the service, and one of the backend pods is selected as the destination address. The backend pod sends a response, and the frontend receives it.
Unlike the usual situation where the TCP connection is closed after receiving the response, now it remains open for subsequent HTTP requests.
What will happen if the frontend sends more requests to the backend?
The existing TCP connection will be used to forward these requests; all requests will go to the same backend pod that the first request was routed to.
Shouldn't iptables redistribute traffic?
Not in this case.
When a TCP connection is created, it goes through the iptables rules, which choose a specific backend pod for the traffic.
Since all following requests go through the already established TCP connection, iptables rules are no longer invoked.
Let's see how this looks.
- The first pod sends a request to the service:

- You already know what will happen next. The service does not exist, but there are iptables rules that will handle the request:
- One of the backend pods will be selected as the destination address:

- The request reaches the pod. At this point, a persistent TCP connection between the two pods will be established:

- Any subsequent request from the first pod will go through the already established connection:

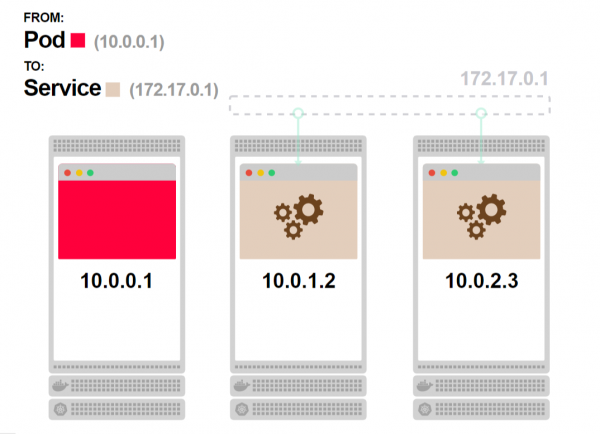
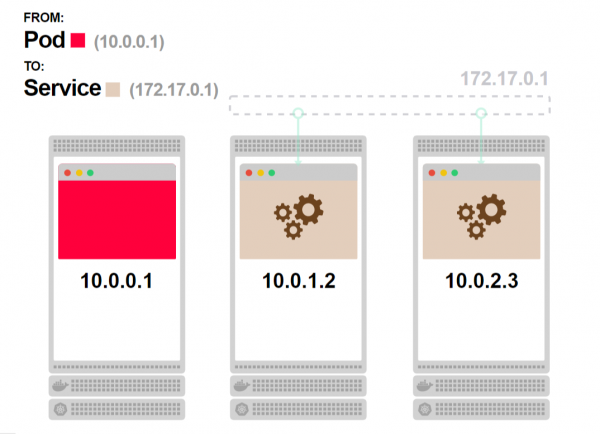
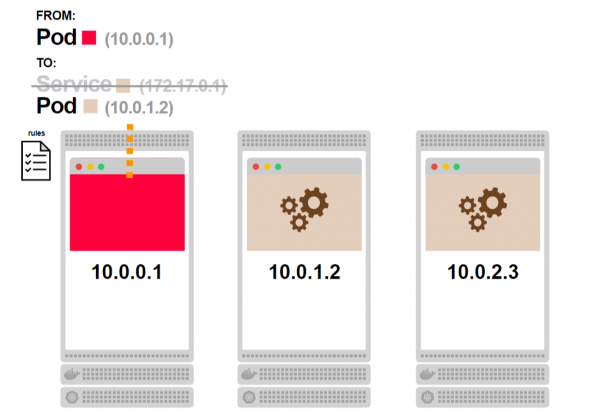
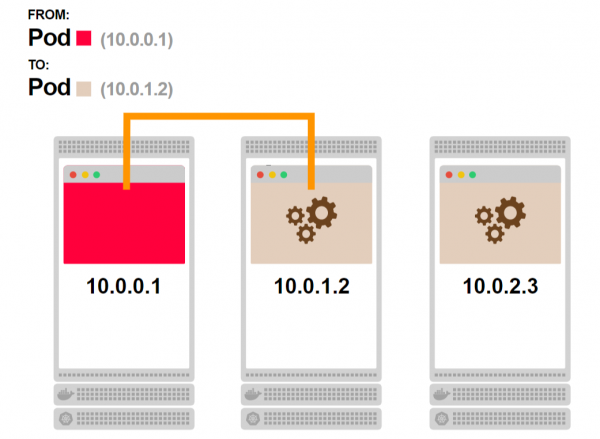
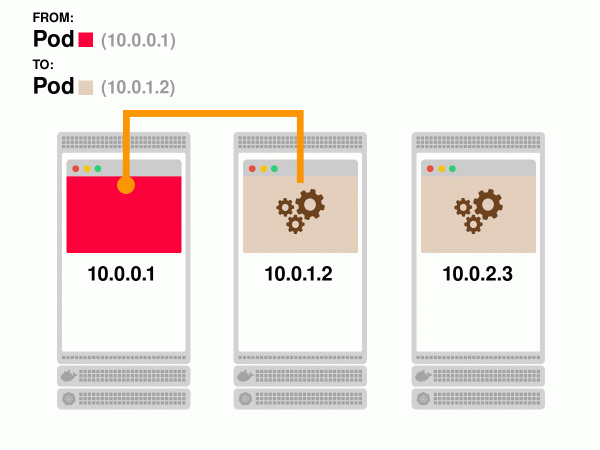
As a result, you get a faster response and higher throughput, but lose the ability to scale the backend.
Even if you have two pods in the backend, traffic will always go to one of them with a persistent connection.
Can this be fixed?
Since Kubernetes does not know how to balance persistent connections, this task is up to you.
Services are a set of IP addresses and ports that are called endpoints.
Your application can get a list of endpoints from the service and decide how to distribute requests among them. You can open a persistent connection with each pod and balance requests across these connections using round-robin.
Or apply more .
The client-side code responsible for balancing should follow this logic:
- Retrieve the list of endpoints from the service.
- For each endpoint, open a persistent connection.
- When a request needs to be made, use one of the open connections.
- Regularly update the list of endpoints, create new or close old persistent connections if the list changes.
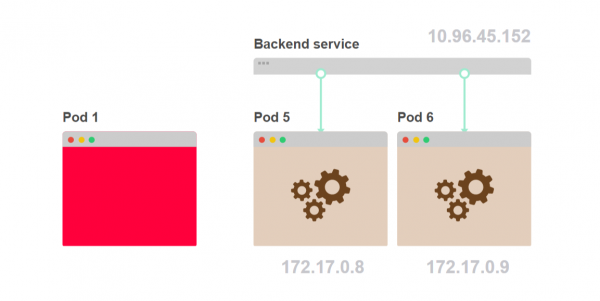
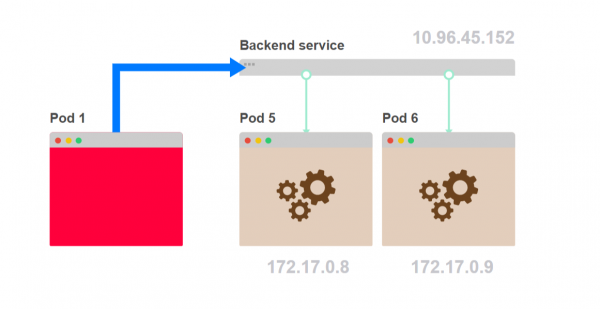
Here's how it will look:.
- Instead of the first pod sending a request to the service, you can balance requests on the client side:

- You need to write code that queries which pods are part of the service:

- Once you receive the list, store it on the client side and use it to connect to the pods:

- You are responsible for the load balancing algorithm:
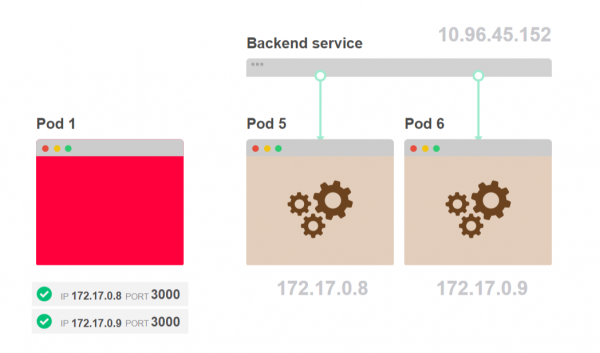
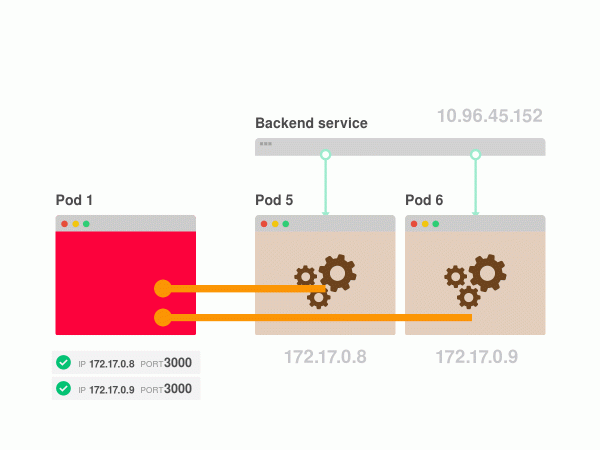
Now the question arises: does this issue only relate to HTTP keep-alive?
Client-side load balancing
HTTP is not the only protocol that can use persistent TCP connections.
If your application uses a database, then a TCP connection is not opened every time you need to execute a query or retrieve a document from the database.
Instead, a persistent TCP connection to the database is opened and used.
If your database is deployed in Kubernetes and access is provided as a service, you will encounter the same problems described in the previous section.
One replica of the database will be more loaded than the others. Kube-proxy and Kubernetes won't help balance connections. You need to ensure request balancing to your database.
Depending on the library you use to connect to the database, you may have different options for solving this problem.
Below is an example of accessing a MySQL database cluster from Node.js:
var mysql = require('mysql');
var poolCluster = mysql.createPoolCluster();

var endpoints = /* retrieve endpoints from the Service */

for (var [index, endpoint] of endpoints) {
  poolCluster.add(`mysql-replica-${index}`, endpoint);
}

// Make queries to the clustered MySQL database
There are many other protocols that use persistent TCP connections:
- WebSockets and secured WebSockets
- HTTP/2
- gRPC
- RSockets
- AMQP
You should already be familiar with most of these protocols.
But if these protocols are so popular, why is there no standardized solution for balancing? Why is client logic required to change? Is there a native solution in Kubernetes?
Kube-proxy and iptables are built to cover most common use cases when deploying in Kubernetes. This is done for convenience.
If you're using a web service that provides a REST API, you're in luck — in this case, persistent TCP connections are not used, and you may use any Kubernetes service.
But as soon as you start using persistent TCP connections, you’ll need to figure out how to evenly distribute the load across the backends. Kubernetes does not have ready-made solutions for this.
However, of course, there are options that can help.
Balancing long-lived connections in Kubernetes
There are four types of services in Kubernetes:
- ClusterIP
- NodePort
- LoadBalancer
- Headless
The first three services operate on the basis of a virtual IP address, which is used by kube-proxy to create iptables rules. However, the fundamental basis of all services is the headless service.
No IP address is associated with a headless service; it only provides a mechanism to obtain a list of IP addresses and ports associated with its pods (endpoints).
All services are based on the headless service.
The ClusterIP service is a headless service with some enhancements:
- The control layer assigns it an IP address.
- Kube-proxy forms the necessary iptables rules.
Thus, you can ignore kube-proxy and directly use the list of endpoints obtained from the headless service for load balancing in your application.
But how do you add such logic to all applications deployed in the cluster?
If your application is already deployed, this task may seem impossible. However, there is an alternative.
Service Mesh can help you.
You may have already noticed that the client-side load balancing strategy is quite standard.
When the application starts, it:
- Obtains a list of IP addresses from the service.
- Opens and maintains a pool of connections.
- Periodically updates the pool by adding or removing endpoints.
As soon as the application wants to make a request, it:
- Selects an available connection using some logic (for example, round-robin).
- Executes the request.
These steps work for WebSocket connections, gRPC, and AMQP.
You can extract this logic into a separate library and use it in your applications.
However, instead, you can use service meshes like Istio or Linkerd.
Service Mesh complements your application with a process that:
- Automatically discovers service IP addresses.
- Checks connections such as WebSockets and gRPC.
- Balances requests using the correct protocol.
Service Mesh helps manage traffic within the cluster, but it is quite resource-intensive. Other options include using third-party libraries like Netflix Ribbon or programmable proxies like Envoy.
What happens if you ignore load balancing issues?
You may not use load balancing and still not notice any changes. Let's look at a few working scenarios.
If you have more clients than servers, it's not such a big issue.
Let's assume there are five clients connecting to two servers. Even without load balancing, both servers will be utilized:
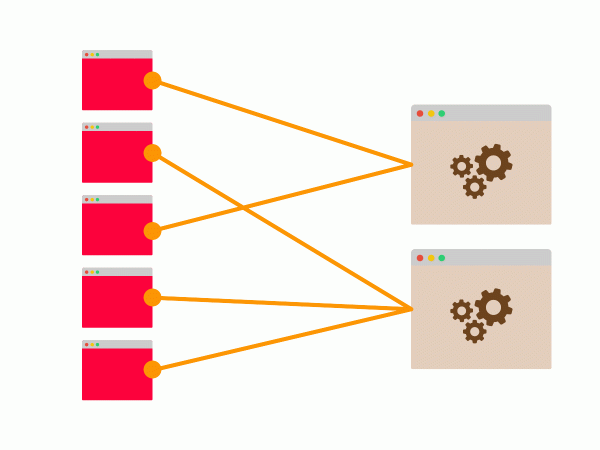
Connections may be distributed unevenly: four clients might connect to the same server, but there is a good chance that both servers will be used.
What is more problematic is the opposite scenario.
If you have fewer clients and more servers, your resources may not be utilized adequately, leading to a potential bottleneck.
Suppose there are two clients and five servers. In the best case, there will be two persistent connections to two of the five servers.
The other servers will remain idle:
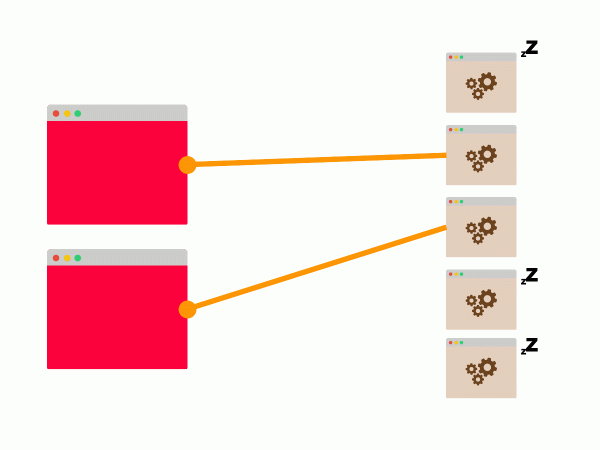
If these two servers cannot handle the client request load, horizontal scaling will not help.
Conclusion
Kubernetes services are designed to operate in most standard web application scenarios.
However, once you start working with application protocols that use persistent TCP connections, such as databases, gRPC, or WebSockets, services are no longer suitable. Kubernetes does not provide built-in mechanisms for balancing persistent TCP connections.
This means you need to design applications with client-side balancing in mind.
Translation prepared by the team .
What else to read on the topic:
- .
- .
- .
Source: habr.com
