

Hello, I recently came across an interesting task of setting up storage for backing up a large number of block devices.
Every week, we perform backups of all virtual machines in our cloud, so we need to be able to manage thousands of backups and do this as quickly and efficiently as possible.
Unfortunately, standard configurations RAID5, RAID6 will not suit us in this case due to the fact that the recovery process on such large disks as ours will be excruciatingly long and probably will never finish.
Let’s consider what alternatives there are:
— Analogous to RAID5, RAID6, but with adjustable parity levels. In this case, redundancy is performed not in blocks, but for each object separately. The easiest way to try erasure coding is to deploy .
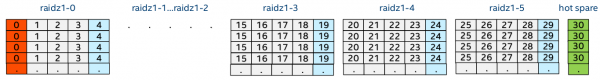
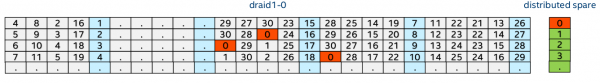
— this is currently an unreleased feature of ZFS. Unlike RAIDZ, DRAID has distributed parity blocks and uses all disks in the array for recovery, which makes it better at surviving disk failures and recovering faster after a crash.
We have the server Fujitsu Primergy RX300 S7 with a processor Intel Xeon CPU E5-2650L 0 @ 1.80GHz, nine sticks of RAM Samsung DDR3-1333 8Gb PC3L-10600R ECC Registered (M393B1K70DH0-YH9), a disk enclosure Supermicro SuperChassis 847E26-RJBOD1, connected via Dual LSI SAS2X36 Expander and 45 disks Seagate ST6000NM0115-1YZ110 by 6TB each.
Before making any decisions, we first need to properly test everything.
To do this, I prepared and conducted testing of various configurations. For this, I used minio, which acted as an S3 backend, running it in different modes with different numbers of targets.
The main test case was minio in erasure coding vs software raid with the same number of disks and parity disks, namely: RAID6, RAIDZ2, and DRAID2.
For reference: when you run minio with just one target, it operates in S3 gateway mode, presenting your local file system as an S3 storage. However, if you run minio with multiple targets specified, it will automatically enable Erasure Coding mode, which will distribute the data across your targets while providing fault tolerance.
By default, minio divides targets into groups of 16 disks, where each group has 2 parity disks. This means that two disks can fail simultaneously without data loss.
For performance testing, I used 16 disks, each 6TB, and wrote small objects of 1MB each. This accurately described our future load since all modern backup tools split data into blocks of several megabytes and write them this way.
The benchmarking was conducted using the s3bench utility, which was run on a remote server sending tens of thousands of such objects to minio in a hundred streams. It then attempted to request them back in the same way.
The benchmarking results are shown in the following table:
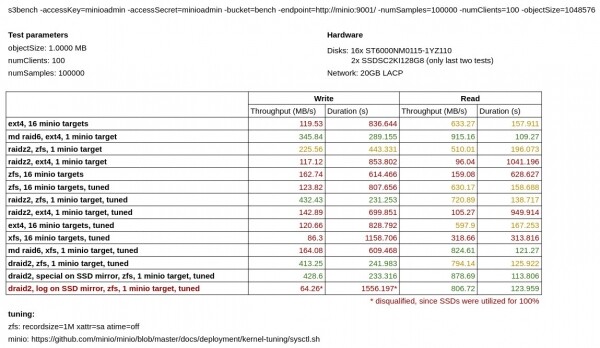
As we can see, minio with its own erasure coding mode performs significantly worse on writes than minio running on top of software RAID6, RAIDZ2, and DRAID2 in the same configuration.
Separately, I to test minio on ext4 vs XFS. Surprisingly, for my type of load, XFS turned out to be significantly slower than ext4.
In the first batch of tests, mdadm showed superiority over ZFS, but later , that performance of ZFS could be improved by setting the following options:
xattr=sa atime=off recordsize=1Mand after that, the tests with ZFS improved significantly.
It can also be noted that DRAID does not provide a significant performance gain over RAIDZ, but in theory should be much safer.
In the last two tests, I also tried to separate the metadata (special) and ZIL (log) onto a mirror from SSDs. However, moving the metadata didn't provide a significant speed gain in writing, and when moving the ZIL, my hit a ceiling with 100% utilization, so I consider this test a failure. I do not rule out that if I had faster SSDs, it might have greatly improved my results, but unfortunately, I did not have them.
In the end, I decided to stick with using DRAID, and despite its beta status, it is the fastest and most effective solution for storage in our case.
I created a simple DRAID2 in a configuration with three groups and two distributed spares:
# zpool status data
  pool: data
 state: ONLINE
  scan: none requested
config:

    NAME                 STATE     READ WRITE CKSUM
    data                 ONLINE       0     0     0
      draid2:3g:2s-0     ONLINE       0     0     0
        sdy              ONLINE       0     0     0
        sdam             ONLINE       0     0     0
        sdf              ONLINE       0     0     0
        sdau             ONLINE       0     0     0
        sdab             ONLINE       0     0     0
        sdo              ONLINE       0     0     0
        sdw              ONLINE       0     0     0
        sdak             ONLINE       0     0     0
        sdd              ONLINE       0     0     0
        sdas             ONLINE       0     0     0
        sdm              ONLINE       0     0     0
        sdu              ONLINE       0     0     0
        sdai             ONLINE       0     0     0
        sdaq             ONLINE       0     0     0
        sdk              ONLINE       0     0     0
        sds              ONLINE       0     0     0
        sdag             ONLINE       0     0     0
        sdi              ONLINE       0     0     0
        sdq              ONLINE       0     0     0
        sdae             ONLINE       0     0     0
        sdz              ONLINE       0     0     0
        sdan             ONLINE       0     0     0
        sdg              ONLINE       0     0     0
        sdac             ONLINE       0     0     0
        sdx              ONLINE       0     0     0
        sdal             ONLINE       0     0     0
        sde              ONLINE       0     0     0
        sdat             ONLINE       0     0     0
        sdaa             ONLINE       0     0     0
        sdn              ONLINE       0     0     0
        sdv              ONLINE       0     0     0
        sdaj             ONLINE       0     0     0
        sdc              ONLINE       0     0     0
        sdar             ONLINE       0     0     0
        sdl              ONLINE       0     0     0
        sdt              ONLINE       0     0     0
        sdah             ONLINE       0     0     0
        sdap             ONLINE       0     0     0
        sdj              ONLINE       0     0     0
        sdr              ONLINE       0     0     0
        sdaf             ONLINE       0     0     0
        sdao             ONLINE       0     0     0
        sdh              ONLINE       0     0     0
        sdp              ONLINE       0     0     0
        sdad             ONLINE       0     0     0
    spares
      s0-draid2:3g:2s-0  AVAIL
      s1-draid2:3g:2s-0  AVAIL

errors: No known data errors
Alright, we sorted out the storage, now let's discuss what we will use for backup. Here, I immediately want to talk about three solutions that I managed to try, which are:
— a fork of , a specialized solution for backing up block devices, has close integration with Ceph. It can retrieve diffs between snapshots and create incremental backups from them. It supports a large number of storage backends, including both local and S3. It requires a separate database to store the deduplication hash table. On the downside, it is written in Python and has a slightly unresponsive CLI.
— a fork of , a long-known and reliable tool for backing up, capable of backing up data and effectively deduplicating it. It can save backups both locally and on a remote server through SCP. It can back up block devices when run with the flag --special, downsides include: when creating a backup, the repository is completely locked, so it is recommended to create a separate repository for each virtual machine, which is not a problem since they are quite easy to create.
— an actively developing project, written in Go, fairly fast and supports a large number of storage backends, including both local storage and SCP, S3, and much more. It is worth noting that there is a specially created for Restic, which allows for the quickest export of the storage for remote use. Of all the above, I liked this one the most. It can back up from stdin. It has almost no noticeable downsides, but there are a few peculiarities:
Firstly, I tried to use it in shared repository mode for all virtual machines (like Benji) and it worked reasonably well, but restoration operations took quite a long time because each time before restoring, Restic tries to read the metadata of all backups. This issue was easily resolved, as with Borg, by creating a separate repository for each virtual machine. This approach also proved very effective for managing backups. Isolated repositories can have separate passwords for data access, and we don’t have to worry about the global repo potentially breaking. Spawning new repositories can be done as easily as in Borg Backup.
In any case, deduplication is performed only with respect to the previous backup version; the previous backup is determined by the path for the specified backup. Therefore, if you are backing up different objects from stdin to a shared repository, make sure to specify the option
--stdin-filename, or explicitly specify the option each time--parent.
Secondly, restoring to stdout takes significantly longer than restoring to the file system due to its parallelism. In the future, tighter support for block device backups is planned.
Thirdly, at the moment it is recommended to use , as version 0.9.6 has a bug with long restoration of large files.
To test the effectiveness of the backup and the speed of writing/restoring from the backup, I created a separate repository and tried to back up a small virtual machine image (21 GB). Two backups were made without changing the original, using each of the listed solutions to check how much faster/slower the deduplicated data is copied.
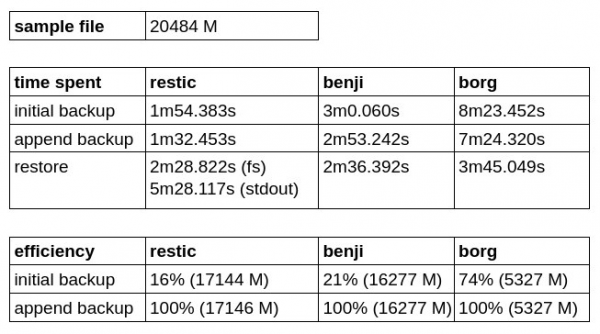
As we can see, Borg Backup has the best efficiency ratio for the initial backup, but it lags behind in both writing and restoring speeds.
Restic turned out to be faster than Benji Backup, but it takes longer to restore to stdout and unfortunately does not yet support writing directly to a block device.
Weighing all the pros and cons, I decided to settle on restic with rest-server as the most convenient and promising backup solution.
In this screencast, you can see how the 10-gigabit channel is fully utilized during several concurrently running backup operations. It’s worth noting that disk utilization does not rise above 30% during this.
I am more than satisfied with the resulting solution!
Source: habr.com
