

My name is Denis Rozhkov, and I am the head of software development at Gazinformservice, part of the product team. . Legislation and corporate standards impose certain requirements on data storage security. No one wants third parties to access confidential information, which is why the following issues are crucial for any project: identification and authentication, access management to data, ensuring information integrity in the system, and logging security events. Therefore, I want to discuss some interesting points regarding database security.
This article is based on a presentation at organized by . If you don't want to read, you can watch:
The article will have three parts:
- How to secure connections.
- What is action auditing and how to log what happens from the database side and the connection to it.
- How to protect data within the database itself and what technologies are available for this.
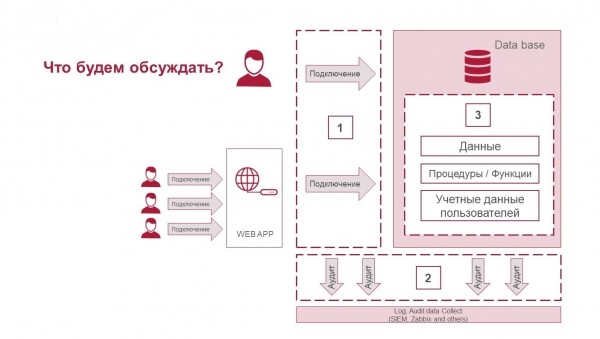
The three components of database security: connection protection, action auditing, and data protection.
Connection Protection
You can connect to the database either directly or indirectly through web applications. Typically, a business user, that is, a person who works with the database management system (DBMS), interacts with it indirectly.
Before discussing connection protection, it's important to answer key questions that determine how security measures will be structured:
- Is one business user equivalent to one DBMS user?
- Is access to DBMS data provided only through an API that you control, or is there direct access to tables?
- Is the DBMS isolated in a separate secure segment, and who interacts with it?
- Is pooling/proxy and intermediary layers used that can change information about how the connection is structured and who is using the database?
Now let's look at the tools that can be used to protect connections:
- Use database firewall-class solutions. An additional layer of protection will at least increase visibility into what is happening in the DBMS, and at most, you will be able to ensure additional data protection.
- Utilize password policies. Their application depends on how your architecture is structured. In any case, having only one password in the configuration file of a web application that connects to the DBMS is insufficient for protection. There are several DBMS tools that allow you to monitor what user and password require updating.
You can read more about user assessment features , and you can also learn about MS SQL Vulnerability Assessment .
- Enrich the session context with necessary information. If the session is opaque, and you do not understand who is operating within the DBMS, you can supplement the information regarding who is doing what and why within the executed operation. This information can be seen in the audit.
- Configure SSL if you do not have network segregation between the DBMS and end-users, and it is not in a separate VLAN. In such cases, it is essential to secure the channel between the consumer and the DBMS. Protection tools are available, including open source options.
How will this affect DBMS performance?
Let's look at the example of PostgreSQL, how SSL affects CPU load, increases timings, and decreases TPS; will it not consume too many resources if enabled.
We load PostgreSQL using pgbench — a simple program for running performance tests. It repeatedly executes a single sequence of commands, possibly in parallel database sessions, and then calculates the average transaction speed.
Test 1 without SSL and with SSL — a connection is established for each transaction:
pgbench.exe --connect -c 10 -t 5000 "host=192.168.220.129 dbname=taskdb user=postgres sslmode=require
sslrootcert=rootCA.crt sslcert=client.crt sslkey=client.key"
vs
pgbench.exe --connect -c 10 -t 5000 "host=192.168.220.129 dbname=taskdb user=postgres"Test 2 without SSL and with SSL — all transactions are executed in one connection:
pgbench.exe -c 10 -t 5000 "host=192.168.220.129 dbname=taskdb user=postgres sslmode=require
sslrootcert=rootCA.crt sslcert=client.crt sslkey=client.key"
vs
pgbench.exe -c 10 -t 5000 "host=192.168.220.129 dbname=taskdb user=postgres"Other settings:
scaling factor: 1
query mode: simple
number of clients: 10
number of threads: 1
number of transactions per client: 5000
number of transactions actually processed: 50000/50000
Test Results:
NO SSL
SSL
A connection is established for each transaction
latency average
171.915 ms
187.695 ms
tps including connections establishing
58.168112
53.278062
tps excluding connections establishing
64.084546
58.725846
CPU
24%
28%
All transactions are executed in one connection
latency average
6.722 ms
6.342 ms
tps including connections establishing
1587.657278
1576.792883
tps excluding connections establishing
1588.380574
1577.694766
CPU
17%
21%
Under light loads, the impact of SSL is comparable to measurement error. However, if the volume of transmitted data is very large, the situation may be different. If we establish one connection per transaction (which is rare, as connections are typically shared among users), the number of connects/disconnects can increase, slightly raising the impact. In other words, there might be performance risks, but the difference is not significant enough to forgo security.
Note that there is a significant difference when comparing operating modes: whether you're working within a single session or across different ones. This is understandable: resources are consumed in establishing each connection.
We had a case where we connected Zabbix in trust mode, meaning we did not check md5; authentication was unnecessary. Later, the client requested to enable md5 authentication. This led to a considerable CPU load, and performance declined. We began searching for optimization routes. One possible solution is to implement network restrictions, create separate VLANs for the DBMS, and add configurations to clarify who is connecting and from where, while eliminating authentication. Additionally, authentication settings can be optimized to reduce costs when enabling authentication, but in general, the use of various authentication methods impacts performance and must be factored into the design of server computational resources (hardware) for the DBMS.
Conclusion: in several solutions, even minor nuances in authentication can significantly affect the project, and it is unfortunate when this becomes apparent only during deployment into production.
Action Audit
Auditing may not be limited to the DBMS. An audit entails gathering information about what is happening across various segments. This can include database firewalls and the operating system on which the DBMS is built.
In commercial Enterprise-level DBMS systems, auditing is well-managed, but this is not always the case in open-source systems. Here’s what is available in PostgreSQL:
- default log — built-in logging;
- extensions: pgaudit — if the default logging is insufficient, separate configurations can be utilized to address some tasks.
Supplement to the report in the video:
The basic registration of operators can be achieved using the standard logging tool with log_statement = all.
This is acceptable for monitoring and other types of usage, but does not provide the level of detail typically required for auditing.
It is not enough to have a list of all operations performed on the database.
There should also be a way to find specific statements that are of interest to the auditor.
The standard logging tool shows what the user requested, while pgAudit focuses on the details of what happened when the database executed the request.
For example, an auditor may want to ensure that a particular table was created during a documented maintenance window.
This may seem like a simple task for basic auditing and grep, but what if you get something like this (intentionally convoluted) example:
DO $$
BEGIN
EXECUTE 'CREATE TABLE import' || 'ant_table (id INT)';
END $$;
The standard logging will give you this:
LOG: statement: DO $$
BEGIN
EXECUTE 'CREATE TABLE import' || 'ant_table (id INT)';
END $$;
It seems that finding the table of interest may require some knowledge of the code in cases where tables are created dynamically.
This is not ideal, as it would be preferable to simply search by the table name.
This is where pgAudit will be useful.
For the same input, it will produce this output in the log:
AUDIT: SESSION,33,1,FUNCTION,DO,,,"DO $$
BEGIN
EXECUTE 'CREATE TABLE import' || 'ant_table (id INT)';
END $$;"
AUDIT: SESSION,33,2,DDL,CREATE TABLE,TABLE,public.important_table,CREATE TABLE important_table (id INT)
Not only the DO block is logged, but also the full text of CREATE TABLE with the type of operator, object type, and full name, which makes searching easier.
When logging SELECT and DML operators, pgAudit can be configured to log a separate entry for each relation referenced in the operator.
No parsing is required to find all operators that pertain to a specific table ()».
How will this affect DBMS performance?
Let's run tests with full auditing enabled and see how it affects PostgreSQL performance. We will enable maximum database logging across all parameters.
In the configuration file, we change almost nothing; the important thing is to enable debug5 mode to get the most information.
postgresql.conf
log_destination = 'stderr'
logging_collector = on
log_truncate_on_rotation = on
log_rotation_age = 1d
log_rotation_size = 10MB
log_min_messages = debug5
log_min_error_statement = debug5
log_min_duration_statement = 0
debug_print_parse = on
debug_print_rewritten = on
debug_print_plan = on
debug_pretty_print = on
log_checkpoints = on
log_connections = on
log_disconnections = on
log_duration = on
log_hostname = on
log_lock_waits = on
log_replication_commands = on
log_temp_files = 0
log_timezone = 'Europe/Moscow'
On PostgreSQL with parameters 1 CPU, 2.8 GHz, 2 GB RAM, 40 GB HDD, we conduct three load tests using the following commands:
$ pgbench -p 3389 -U postgres -i -s 150 benchmark
$ pgbench -p 3389 -U postgres -c 50 -j 2 -P 60 -T 600 benchmark
$ pgbench -p 3389 -U postgres -c 150 -j 2 -P 60 -T 600 benchmark
Test results:
Without logging
With logging
Total time to fill the DB
43.74 sec
53.23 sec
RAM
24%
40%
CPU
72%
91%
Test 1 (50 connections)
Number of transactions in 10 min
74169
32445
Transactions/sec
123
54
Average latency
405 ms
925 ms
Test 2 (150 connections with 100 possible)
Number of transactions in 10 min
81727
31429
Transactions/sec
136
52
Average latency
550 ms
1432 ms
About sizes
DB size
2251 MB
2262 MB
Log size of the DB
0 MB
4587 MB
In conclusion: full auditing is not very good. The data from auditing will amount to the same volume as the data in the database itself, or even more. Such a volume of logging generated during operation with the DBMS is a common problem in production.
Let's look at other parameters:
- The speed doesn't change much: without logging — 43.74 sec, with logging — 53.23 sec.
- Performance in terms of RAM and CPU will decline, as a file for auditing needs to be created. This is also noticeable in production.
With an increase in the number of connections, naturally, the indicators will deteriorate slightly.
In corporations with auditing, it’s even more complex:
- there is a lot of data;
- audit is needed not only through syslog in SIEM but also in files: in case something happens with syslog, there should be a file close to the database where data is saved;
- for auditing, a separate shelf is needed to avoid degrading disk I/O, as it takes up a lot of space;
- sometimes IT staff need standards everywhere; they require state identification.
Access restriction to data
Let’s look at the technologies used to protect data and access to it in commercial DBMS and open source.
What can generally be used:
- Encryption and obfuscation of procedures and functions (Wrapping) — i.e., separate tools and utilities that make readable code unreadable. However, it cannot be changed or refactored back. This approach is sometimes required at least on the DBMS side — the logic of licensing restrictions or authorization logic is encrypted precisely at the level of procedures and functions.
- Row-Level Security (RLS) is when different users see the same table but different rows within it, meaning some information is restricted from being viewed at the row level.
- Data Masking is when users in one column of a table either see the data or just asterisks, meaning for some users the information will be hidden. The technology determines what to show each user based on their access level.
- Access Control for Security DBA/Application DBA/DBA is more about limiting access to the database management system itself, allowing for the separation of information security staff from database and application administrators. There aren't many such technologies in open source, but there are plenty in commercial DBMS. They are necessary when there are many users with access to the servers.
- File access restrictions at the filesystem level allow for granting rights and privileges to directories so that each administrator only accesses the necessary data.
- Mandatory access and memory cleansing are technologies that are rarely used.
- End-to-end encryption directly from the DBMS is client-side encryption with key management on the server side.
- Data encryption, such as column-level encryption, is when you use a mechanism that encrypts a specific column of the database.
How does this affect DBMS performance?
Let's look at column encryption in PostgreSQL as an example. There is a pgcrypto module that allows certain fields to be stored in encrypted form. This is useful when only some data is valuable. To read encrypted fields, the client sends a decryption key, the server decrypts the data, and returns it to the client. Without the key, no one can do anything with your data.
Let's conduct a test with pgcrypto. We will create a table with encrypted data and another with regular data. Below are the commands to create the tables, with the first line being a useful command to create the extension and register the DBMS:
CREATE EXTENSION pgcrypto;
CREATE TABLE t1 (id integer, text1 text, text2 text);
CREATE TABLE t2 (id integer, text1 bytea, text2 bytea);
INSERT INTO t1 (id, text1, text2)
VALUES (generate_series(1,10000000), generate_series(1,10000000)::text, generate_series(1,10000000)::text);
INSERT INTO t2 (id, text1, text2) VALUES (
generate_series(1,10000000),
encrypt(cast(generate_series(1,10000000) AS text)::bytea, 'key'::bytea, 'bf'),
encrypt(cast(generate_series(1,10000000) AS text)::bytea, 'key'::bytea, 'bf'));
Next, we will try to create a data selection from each table and observe the execution timings.
Selection from the table without encryption function:
psql -c "timing" -c "select * from t1 limit 1000;" "host=192.168.220.129 dbname=taskdb
user=postgres sslmode=disable" > 1.txt
The stopwatch is running.
id | text1 | text2
——+——-+——-
1 | 1 | 1
2 | 2 | 2
3 | 3 | 3
…
997 | 997 | 997
998 | 998 | 998
999 | 999 | 999
1000 | 1000 | 1000
(1000 rows)
Time: 1.386 ms
Selection from the table with encryption function:
psql -c "timing" -c "select id, decrypt(text1, 'key'::bytea, 'bf'),
decrypt(text2, 'key'::bytea, 'bf') from t2 limit 1000;"
"host=192.168.220.129 dbname=taskdb user=postgres sslmode=disable" > 2.txt
The stopwatch is running.
id | decrypt | decrypt
——+—————+————
1 | x31 | x31
2 | x32 | x32
3 | x33 | x33
…
999 | x393939 | x393939
1000 | x31303030 | x31303030
(1000 rows)
Time: 50.203 ms
Test Results:
Without encryption
Pgcrypto (decrypt)
Selection of 1000 rows
1.386 ms
50.203 ms
CPU
15%
35%
RAM
+5%
Encryption significantly affects performance. It is evident that timing has increased since decryption operations of encrypted data (and decryption is usually wrapped in your logic) require considerable resources. Thus, the idea of encrypting all columns containing any data carries the risk of reducing performance.
At the same time, encryption is not a silver bullet that solves all issues. The decrypted data and the decryption key are present on the server during the decryption and data transfer processes. Therefore, keys can be intercepted by those who have full access to the database server, such as a system administrator.
When there is one key for an entire column for all users (even if not for everyone, but for a limited set of clients), it is not always good or correct. This is why end-to-end encryption has started to be implemented; databases began exploring client-side and server-side data encryption options, leading to the emergence of key-vault storage — separate products that provide key management on the database side.

Security features in commercial and open-source databases
Features
Type
Password Policy
Audit
Protection of source code procedures and functions
RLS
Encryption
Oracle
Commercial
+
+
+
+
+
MsSql
Commercial
+
+
+
+
+
Commercial
+
+
+
+
extensions
PostgreSQL
Free
extensions
extensions
—
+
extensions
MongoDb
Free
—
+
—
—
Available in MongoDB Enterprise only
The table is far from complete, but the situation is as follows: in commercial products, security issues have been addressed for a long time, while in open source, security typically relies on some extensions; many features are lacking, and sometimes it is necessary to write something additional. For example, password policies — there are many different extensions in PostgreSQL., , , , ), which implement password policies, but in my opinion, none meets all the needs of the domestic corporate segment.
What to do if you can't find what you need anywhere?? Например, хочется использовать определенную СУБД, в которой нет функций, которые требует заказчик.
Then you can use third-party solutions that work with different DBMS, such as 'Crypto DB' or 'Garda DB'. When it comes to solutions from the domestic segment, they are more familiar with GOSTs than in open source.
The second option is to write what you need by yourself, implementing data access and encryption at the procedure level in the application. However, it will be more challenging with GOST. Overall, you can hide data as needed, store it in the DBMS, and then retrieve and decrypt it appropriately, right at the application level. At the same time, think about how you will protect these algorithms at the application level. In our view, this should be done at the DBMS level for better performance.
This presentation was first given at by Mail.ru Cloud Solutions. Seeother presentations and subscribe for event announcements on Telegram .
What else to read on the topic:
- .
- .
Source: habr.com
