

Defining DevOps is quite complex, so we often find ourselves restarting the discussion on this topic. There are thousands of publications about it on Habr alone. But if you are reading this, you likely already know what DevOps is. Because I don't. Hi, my name is Alexander Titov (@), and we will just talk about DevOps, and I will share my experience.
I've thought for a long time about how to make my story useful, so there will be many questions here—those I ask myself and those I ask our clients. By answering these questions, understanding improves. I will explain why DevOps is needed from my point of view, what it is again from my position, and how to understand if you are moving towards DevOps, once again from my point of view. The last point will be through questions. By answering them, you can determine whether your company is moving towards DevOps or has certain issues.
For some time, I rode the waves of mergers and acquisitions. First, I worked at a small startup called Qik, which was then bought by a slightly larger company, Skype, which was subsequently acquired by an even larger company, Microsoft. At this point, I gained insight into how the perception of DevOps transforms in companies of various sizes. After that, I became interested in looking at DevOps from a market perspective, and my colleagues and I founded the company Express 42. For 6 years now, we have been navigating the market waves.
Moreover, I am one of the organizers of the DevOps Moscow community and organized DevOps Days 2017, but I did not organize it in 2018. Express 42 collaborates with many companies. We cultivate DevOps there, observe how it unfolds, draw conclusions, analyze, share our findings with everyone, and educate people on DevOps practices. In short, we are consistently building experience and expertise in this sense.
Why DevOps
The first question that haunts everyone, always—why? Many believe that DevOps is simply automation or something similar that was already present in every company.
— We had Continuous Integration—that means we already had DevOps, so why do we need all this nonsense? They are just having fun abroad, while we are being hindered at work!
After 9 years of community development and methodology, it has become clear that this is not just a marketing gimmick, but it is still not fully understood why it is needed. Like any tool or process, DevOps has specific goals that it ultimately addresses.
This is all related to the fact that the world is changing. It is moving away from the enterprise approach, where companies aim straight for their dream, as our St. Petersburg classic sang, from point A to point B according to a specific strategy, with a predetermined structure built for that purpose.
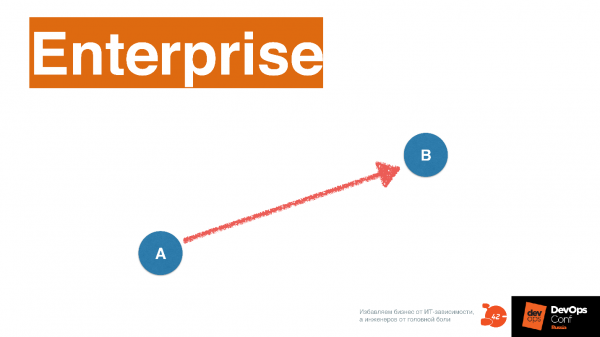
In principle, everything in IT should be structured around this approach. Here, IT is used exclusively for the automation of processes.
Automation does not change often, because when a company follows a beaten path—why change anything? If it works, don’t touch it. Nowadays, approaches are changing in the world, and the one known as Agile indicates that the final point B is not immediately visible.
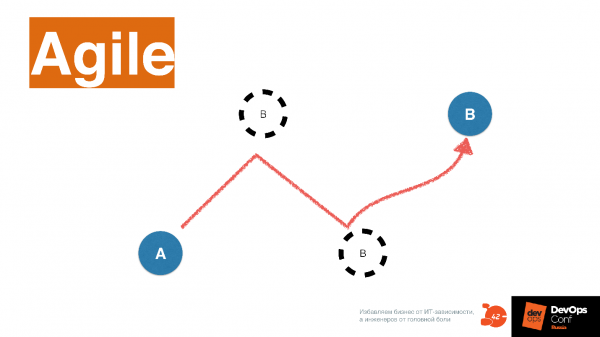
When a company operates in the market, working with clients, it constantly researches the market and adjusts its final point B. Moreover, the more frequently a company changes its direction, the more successful it ultimately becomes, as it captures more market niches.
A strategy is exemplified by an interesting company I learned about recently. One Box Shave is a subscription service for delivering razors and shaving supplies in a box. They can customize their 'box' for different clients. This is managed by specific software that then sends the order to a Korean factory producing the goods.
This product was purchased by Unilever for 1 billion dollars. It now competes with Gillette and has claimed a significant share of consumers in the American market. One Box Shave says:
"Four blades? Are you serious? Why do you need that—this doesn’t enhance the shaving quality. A specially selected cream, fragrance, and a quality razor with two blades solve far more issues than those ridiculous four Gillette blades! Are we going to reach 10 soon?"
Thus, the world is changing. Unilever claims they have a cool IT system that allows this to happen. Ultimately, it looks like a concept. Time-to-market, which has been discussed by many.
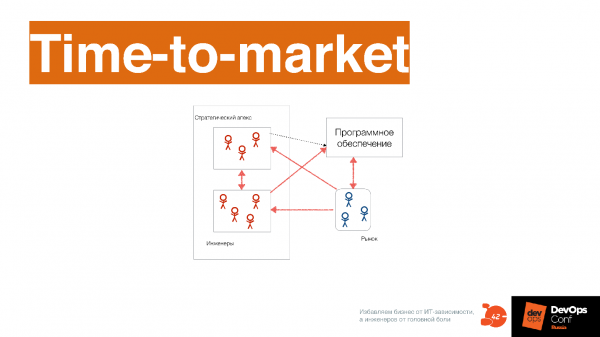
The meaning of Time-to-Market is not about how often we deploy. We can deploy frequently, but the release cycles may still be lengthy. If we overlap three-month release cycles week by week, it appears that the company is deploying once a week. However, it still takes 3 months from the idea to the final implementation.
Time-to-Market is about minimizing the time from idea to final implementation.
In this case, the software interacts with the market. For example, at One Box Shave, the website interacts with the client. They have no salespeople—just a website where visitors click and leave their requests. Therefore, the site must constantly feature something new and be updated according to those requests. For instance, in South Korea, people shave differently than in Russia, and they prefer scents like vanilla carrot instead of pine.
Since it is necessary to quickly change the site's content, software development changes significantly. Through software, we must learn what the client wants. Previously, we learned this through indirect means, such as business management. Then we would design and incorporate requirements into the IT system, and everything would be fine. Now it’s different—the software is designed by everyone involved in the process, including engineers, because they learn through technical specifications how the market works and also share their insights with the business.
For example, at Qik, we suddenly discovered that people really enjoy uploading contact lists to the server, and they provided us with an application for this. Initially, we hadn’t considered it. In a traditional company, everyone would have decided that this was a bug, as the specification did not state that it should work well. They would have turned off the feature and said, 'This is unnecessary; the main functionality works.' However, a technological company sees this as an opportunity and begins to alter the software accordingly.
In 1968, the insightful guy Melvin Conway formulated the following idea.
An organization that designs a system is limited by the design of the communication structure within that organization.
In more detail, to produce systems of a different type, you also need to have a different type of communication structure within the company. If your communication structure is top-down hierarchical, it won’t allow you to create systems that can ensure a very high Time-to-market rate.
Read more in . It is important for understanding the culture or philosophy of DevOps because the only thing that fundamentally changes in DevOps is the communication structure between teams..
From a process perspective, before DevOps, all stages: analysis, development, testing, and operation were linear.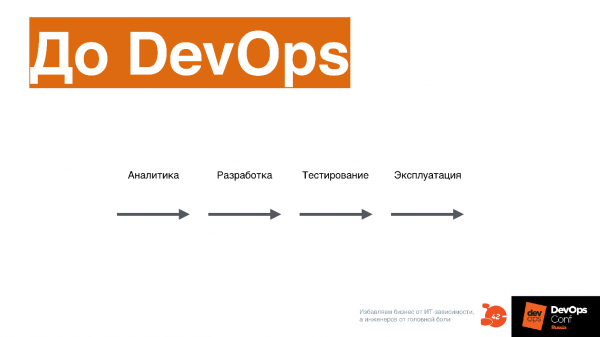
In the case of DevOps, all these processes happen simultaneously.
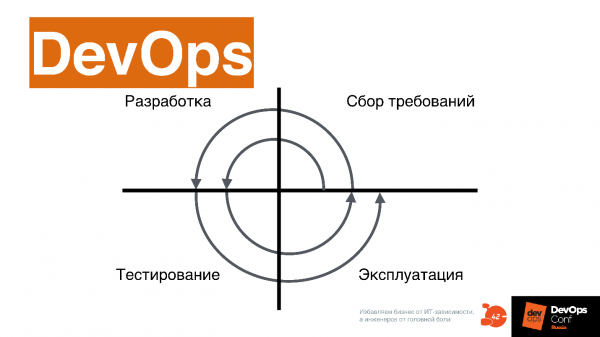
Time-to-market can only be achieved this way. For people who have worked in the old process, it seems somewhat outlandish and not very appealing at all.
So why is DevOps needed?
For the development of digital products. If your company doesn’t have a digital product, DevOps is not necessary—this is very important.
DevOps overcomes the speed limitations of a sequential software production scheme. In it, all processes occur simultaneously.
Complexity increases. When DevOps evangelists say that it will make software releases easier for you, that’s utter nonsense.
With DevOps, everything will only become more complicated.
At the conference at the Avito booth, you could see what it means to deploy a Docker container—it's an unrealistic task. The complexity becomes overwhelming; you have to juggle many balls at once.
DevOps completely changes the process and organization within the company — actually, it’s not DevOps that changes things, but the digital product. To get to DevOps, you still need to completely change this process.
Questions for the specialist
What about you? Questions you might want to ask yourself while working in a company and developing as a specialist.
Do you have a strategy for creating a digital product? If yes, that’s already good. It means your company is moving towards DevOps.
Is your company already creating a digital product? This means you can rise to an even higher level, dealing with more interesting tasks—from the perspective of DevOps, again. I'm speaking from this viewpoint.
Is your company one of the market leaders in the niche of digital products? Spotify, Yandex, Uber — companies that are at the peak of technological progress right now.
Ask yourself these questions, and if all the answers are negative, perhaps DevOps isn't for you in this company. However, if you're genuinely interested in the DevOps topic, maybe you should consider moving to another company? If your company wants to adopt DevOps but you answered 'No' to all the questions, it resembles that beautiful rhinoceros that will never change.
Organization
As I mentioned, according to Conway's Law, the organization within a company changes. I'll start with what hinders DevOps from penetrating the company from an organizational perspective.
The issue of 'silos'
The English word 'Silo' is translated here into Russian as 'колодец'. The essence of this problem is that there is no exchange of information between teams.Each team delves deeper into its expertise without creating a common map to navigate.
This is somewhat reminiscent of a person who has just arrived in Moscow and still doesn't know how to navigate the metro map. Muscovites usually know their district well, and they navigate all of Moscow using the metro map. When you arrive in Moscow for the first time, you lack that skill and are simply disoriented.
DevOps suggests overcoming this moment of disorientation and collaboratively building a shared interaction map for all departments.
Two factors hinder this.
The consequence of the corporate governance system. It is built on separate hierarchical 'silos'. For example, there are certain KPIs in companies that maintain this system. On the other hand, a person's mindset can hinder as well, making it difficult to step outside their expertise and understand the entire system. It's simply uncomfortable. Imagine finding yourself in Bangkok Airport — it's hard to orient yourself quickly. It's also challenging to navigate in DevOps, which is why people say you need to find a guide to get there.
But most importantly, the 'silo' problem for an engineer who is immersed in the spirit of DevOps, has read Fowler and many other books, manifests in the fact that 'silos' prevent doing 'obvious' things.We often gather after DevOps Moscow, talk to each other, and people complain:
— We just wanted to launch CI, but it turned out that management didn't need it.
This is happening precisely because CI and Continuous Delivery process are at the intersection of many areas of expertise. If we do not overcome the issue of "silos" at the organizational level, we will not be able to progress further, no matter what you do and how sad it may be.
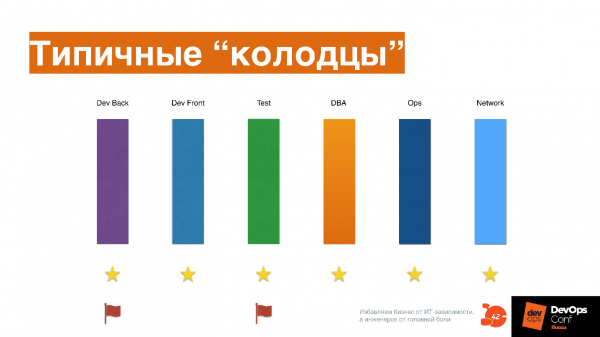
Every participant in the process within the company: backend and frontend developers, testers, DBAs, operations, network, is digging in their own direction, and no one has the overall picture except for the manager, who somehow oversees them and manages by the method of "divide and conquer."
People are fighting for certain stars or flags, each digging into their own expertise.
As a result, when the task arises to connect all this together and build a common pipeline, and there’s no need to fight for stars and flags anymore, the question arises—what should we do? We need to somehow come to an agreement, but how to do that is something we were never taught in school. Since school, we have been trained: eighth grade—wow!—compared to the seventh grade! The same is true here.
Is it the same in your company?
To check this, you can ask yourself the following questions.
Are teams using common tools, and are they contributing to changes to these common tools?
How often do teams reform—do specialists from one team move to another? This becomes normal in the DevOps environment because sometimes a person simply cannot understand what another area of expertise is doing. They move to another department, work there for a couple of weeks to create a map of orientation and interaction with that department.
Can a committee for change be created and can something be changed? Or is a strong hand from top management and an order needed for this? Recently, I wrote on Facebook about how a little-known bank implements tools through orders: they wrote an order, implemented it for a year, and observed what happens. This, of course, is slow and sad.
How important is it for managers to achieve personal accomplishments without considering the company's achievements?
If you answer these questions for yourself, it will become clearer whether you have such a problem in the company.
Infrastructure as Code
Once this issue is resolved, the first important practice without which it's difficult to advance further in DevOps is infrastructure as code.
Infrastructure as code is most often perceived as follows:
— Let's automate everything using bash, let's cover ourselves with scripts to reduce manual work for sysadmins!
But that's not the case.
Infrastructure as code implies that the IT system you work with is described in code, allowing you to continually understand its state.
Together with other teams, you create a map in code that is understandable to everyone, which can be navigated. It doesn't matter what it's built on — whether it's Chef, Ansible, Salt, or YAML files used in Kubernetes — it makes no difference.
At a conference, a colleague from 2GIS talked about how they created their internal tool for Kubernetes that describes the architecture of individual systems. To document 500 systems, they needed a separate tool that generates this documentation. With this documentation, everyone can cross-check with each other, monitor changes, see how to modify and improve it, and identify what is lacking.
Admittedly, separate bash scripts usually do not provide this understanding. In one of the companies I worked for, there was even a term 'write only' script — when the script is written but cannot be read anymore. I think this is familiar to you as well.
Infrastructure as code is code that describes the current state of infrastructure. Many product, infrastructure, and service teams collaborate on this code, and, most importantly, they all need to understand how this code actually works.
The code is maintained according to best practices for working with code: collaborative development, code review, XP programming, testing, pull requests, CI for infrastructure code — all these practices are valuable and can be utilized.
The code becomes a common language for all engineers.
Changing infrastructure in code doesn’t take much time. Yes, there can also be technical debt in infrastructure code. Usually, teams encounter this about a year and a half after they start implementing 'infrastructure as code' in the form of a bunch of scripts or even Ansible, which they write like spaghetti code, and still throw in some bash scripts to boot it!
Important: if you haven't tried this mess yet, remember that Ansible is not bashPay close attention to the documentation, learn what is being said about this topic.
Infrastructure as Code is the division of infrastructure code into separate layers.
We identify three basic layers in our company that are very clear and simple, though there can be more. You can look at your infrastructure code and determine whether you have this condition or not. If no layers are identified, take some time to refactor a bit.
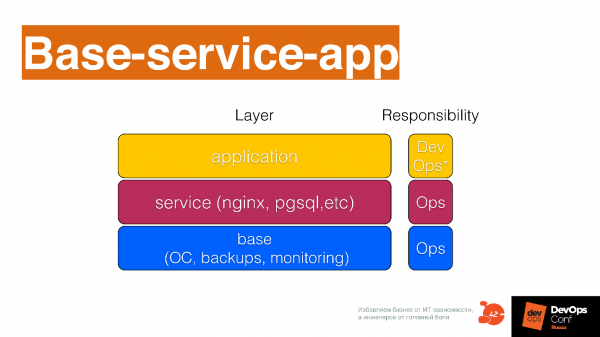
Basic Layer is how the OS is configured, backups, and other low-level aspects, such as how Kubernetes is deployed at the fundamental level.
Service Level includes the services you provide to the developer: logging as a service, monitoring as a service, database as a service, load balancer as a service, queue as a service, Continuous Delivery as a service — a bunch of services that different teams can provide to development. All of this needs to be described as separate modules in your configuration management system.
The layer where applications are created and described, outlining how they will be deployed over the two previous layers.
Control Questions
Does your company have a common infrastructure repository? Do you monitor technical debt in your infrastructure? Are you using development practices in the infrastructure repository? Is your infrastructure divided into layers? You can check against the Base-service-APP scheme. How difficult is it to implement a change?
If you've experienced changes taking a day and a half, it means you have accumulated technical debt that needs to be addressed. You've encountered the pitfalls of technical debt in your infrastructure code. I remember many instances when changing a certain CCTL required rewriting half of the infrastructure code because creativity and the desire to automate everything led to a convoluted situation, with all handles removed and refactoring needed.
Continuous Delivery
Let's summarize the debit with credit. First, there appears a description of the infrastructure, which can be quite basic. It's not necessary to describe everything in detail, but a basic description is required for you to work with this. Otherwise, it’s unclear what to base the continuous delivery on. All these practices unfold simultaneously when you move to DevOps, but you need to start understanding what you have and how to manage it. This is precisely the practice of infrastructure as code.
After understanding what you have and how to manage it, you start thinking about how to get the developer’s code deployed to production as quickly as possible. I mean together with the developer – remember the issue of 'silos,' meaning it’s not individual people coming up with ideas, but the team as a whole.
When we met with Ilya Yevtukhovich and saw the first book by Jez Humble and a group of authors "Continuous Delivery", which was published in 2009, we thought for a long time about how to translate its title into Russian. We wanted to translate it as "Delivering Continuously,” but unfortunately, we translated it as "Continuous Delivery." I believe that our title has something inherently Russian, with a punch.
Delivering continuously means
The code in the product repository can always be deployed to production.. It may not be deployed, but it is always ready for that. Accordingly, you always write code with a somewhat inexplicable feeling of anxiety in your lower back. This feeling often arises when you deploy infrastructure code. This sense of anxiety should be present—it triggers cognitive processes that help you write code somewhat differently. This should be fixed in the development rules.
To deliver continuously, a format for the artifact is needed that runs through the infrastructure platform. If you throw various formats of 'byproducts' around the infrastructure platform, it becomes non-unified and hard to maintain, leading to technical debt issues. The artifact format needs to be aligned—it's also a collective task: everyone should come together, brainstorm, and come up with this format.
The artifact continuously improves and changes in the production environment while going through the delivery pipeline. As the artifact moves through the pipeline, it constantly faces various challenges that resemble what the artifact encounters when you deploy it to production. In classical development, a system administrator handles the deployment, but in the DevOps process, this occurs continuously: here it's tested with various tests, there it’s thrown into a Kubernetes cluster that resembles production to some extent, and suddenly load testing is initiated.
This is somewhat akin to a Pac-Man game—the artifact goes through a story. It's crucial to monitor whether the code genuinely follows the story and its connection to your production. You can incorporate production scenarios into the Continuous Delivery process: there was a time when something broke, so let's just code this scenario into the system. Each time, the code will undergo this scenario too, and you won’t encounter this problem the next time. You'll know about it much earlier before it reaches your client.
Different deployment strategies. For example, you use A/B testing or canary deployments to 'gauge' the code on different clients, obtaining information on how the code performs, and significantly earlier than it would roll out to 100 million users.
‘Continuous delivery’ looks like this.
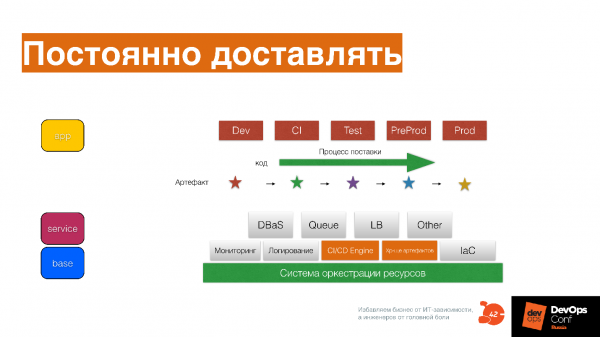
The delivery process of Dev, CI, Test, PreProd, Prod is not a separate environment; these are stages or stations with non-burning sums through which your artifact passes.
If you have infrastructure code described as Base Service APP, it helps not to forget all scenarios, and record them in code form for this artifact, to promote the artifact and modify it along the way.
Self-check questions
Is the time from feature description to deployment in production less than a week in 95% of cases? Does the quality of the artifact improve at every stage of the pipeline? Is there a history that it follows? Are you using different deployment strategies?
If all the answers are yes, then you are incredibly awesome! Leave your answers in the comments—I would be glad to hear them.).
Feedback
This is the most complex practice of all. At the DevOpsConf conference, a colleague from Infobip, while talking about it, got a bit confused because it's really a very complex practice about monitoring everything!
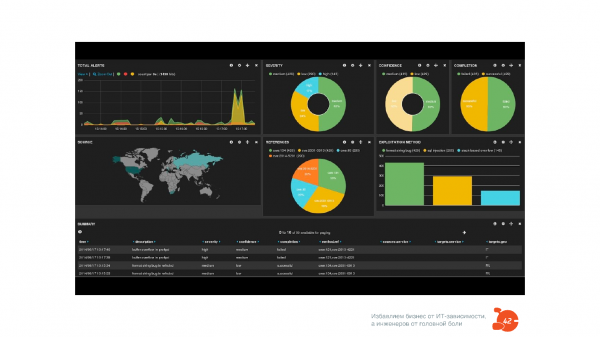
For example, a long time ago, when I worked at Qik and we realized that we needed to monitor everything. We did, and we had 150,000 items monitored constantly in Zabbix. It was daunting; the technical director was rolling his eyes and said:
— Guys, why are you torturing the server with who-knows-what?
But then there was a case that showed that this is actually a really cool strategy.
One of the services began to crash constantly. Interestingly, it hadn't been crashing initially, the code hadn’t been changed because it was a basic broker with almost no business functionality—it just routed messages between separate services. The service hadn't changed for 4 months, and suddenly it started crashing with a "Segmentation fault" error.
We were shocked; we opened our graphs in Zabbix and found out that, as it turned out, a week and a half ago, the behavior of requests in the API service that uses this broker had drastically changed. Next, we noticed that the frequency of sending a certain type of messages had changed. We discovered that it was the Android clients. We asked:
— Guys, what happened a week and a half ago?
In response, we heard an interesting story that they had redesigned the UI. Few would immediately say that they changed the HTTP library. For Android clients, it's like changing soap in the bathroom—they just don’t remember. Ultimately, after 40 minutes of conversation, we found out that they indeed changed the HTTP library, and its default timings had changed. This led to changes in traffic behavior on the API server, which triggered a race condition in the broker, causing it to start crashing.
Without deep monitoring, it's impossible to uncover this.If there is still a "well" problem in the organization, where everyone pushes onto each other, it can last for years. You just restart the server because it's impossible to resolve the issue. When you monitor, track, and log all events you have, and use monitoring as testing—writing code and immediately specifying how to monitor it, also in the form of code (we already have infrastructure as code), everything becomes clear as day. Even such complex problems are easily traceable.
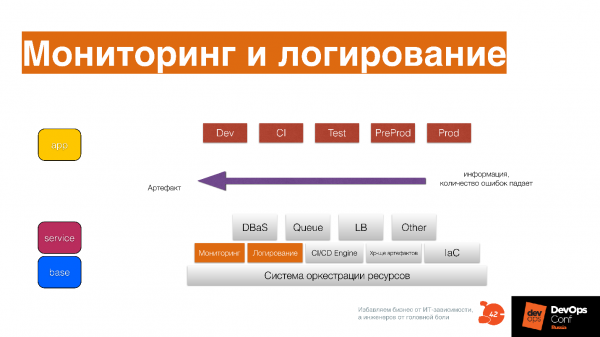
Gather all information about what happens to the artifact at every stage of the delivery process—not just in production.
Push monitoring onto CI, and then some basic things will be visible. Then you'll see them in Test, in PredProd, and in load testing. Collect information at all stages, not only metrics and statistics but also logs: how the application was deployed, anomalies—collect everything.
Otherwise, it will be difficult to figure things out. I've already said that DevOps is a greater complexity. To cope with this complexity, you need a proper analytics setup..
Self-assessment questions
Is your monitoring and logging a development tool for you? Do your developers, including you, think about how to monitor the code they write?
Do you learn about problems from clients? Do you understand the client better from monitoring and logging? Do you understand the system better from monitoring and logging? Do you change the system just because you see that a trend in the system is rising and understand that in another three weeks everything will collapse?
When you have these three components, you can think about what your company's infrastructure platform looks like.
Infrastructure platform
The point is not that it is a set of disparate tools that every company has.
The essence of the infrastructure platform is that all teams use these tools and develop them together.
It is clear that there are separate teams responsible for the development of individual pieces of the infrastructure platform. However, every engineer is responsible for the development, reliability, and promotion of the infrastructure platform. At the internal level, this becomes a common tool..
All teams develop the infrastructure platform, treating it as their own IDE with care.In your IDE, you install various plugins to make everything look nice and work quickly, setting up hotkeys. When you open Sublime, Atom, or Visual Studio Code, you immediately face code errors and realize that working is nearly impossible; it brings you down, and you rush to fix your IDE.
Treat your infrastructure platform in exactly the same way. If you sense something is off, submit a request if you can't fix it yourself. If it's something simple—fix it on your own, send a pull request—people will review it and add it. This reflects a different approach to the engineering toolkit in a developer’s mind.
The infrastructure platform facilitates transferring artifacts from development to the client with continuous quality improvement.In the IP, a set of stories is programmed that occur with the code in production. Over years of development, these stories accumulate significantly, and some are unique to you—impossible to find on Google.
At this point, the infrastructure platform becomes your competitive advantage.because it contains elements not present in competitors' tools. The deeper your IP, the greater your competitive advantage in terms of Time-to-market. This introduces the vendor lock issue: you can adopt someone else's platform, but by relying on their experience, you will not understand how relevant it is to your situation. Yes, not every company can build a platform like Amazon. It’s a delicate balance where a company’s experience is relevant to its market position, and you can't lower yourself to vendor lock. This is also an important consideration.
Scheme
This is a basic scheme of the infrastructure platform that will help you establish all practices and processes in a DevOps company.
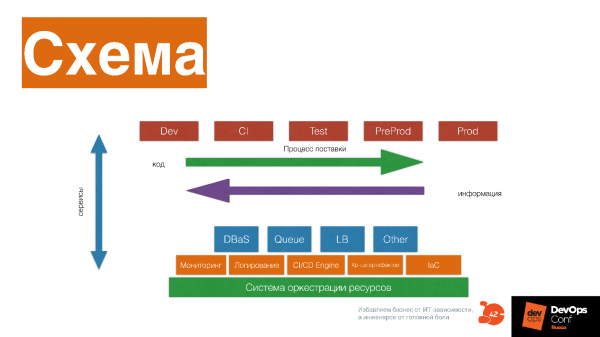
Let's examine what it consists of.
Resource orchestration system, which provides CPU, memory, and disk to applications and other services. On top of this, low-level services: monitoring, logging, CI/CD Engine, artifact storage, infrastructure as code systems.
Higher-level servicesdatabase as a service, queues as a service, Load Balance as a service, image resizing as a service, Big Data factory as a service. On top of this — a pipeline that continuously delivers modified code to your client.
You receive information on how your software is performing at the client's site, make changes, deliver that code again, gather information — and thus continually develop both the infrastructure platform and your software.
In the diagram, the delivery pipeline consists of multiple stages. But this is a basic diagram provided as an example — do not replicate it exactly. The stages interact with services as services — each building block of the platform has its own story: how resources are allocated, how the application starts, operates with resources, is monitored, and updated.
It is important to understand that each part of the platform carries a story, and to ask yourself — what story does this building block carry, maybe it should be discarded and replaced with a third-party service. For example, could we replace this block with Okmeter? Perhaps the team has already developed this expertise far more than we have. But maybe not — we might have unique expertise, so we need to implement Prometheus and further develop that.
Creating a platform
It is a complex communication process. When you have basic practices, you initiate communication between different engineers and specialists who generate requirements and standards, and continuously alter them for different tools and approaches. Here, the culture that exists in DevOps is crucial.
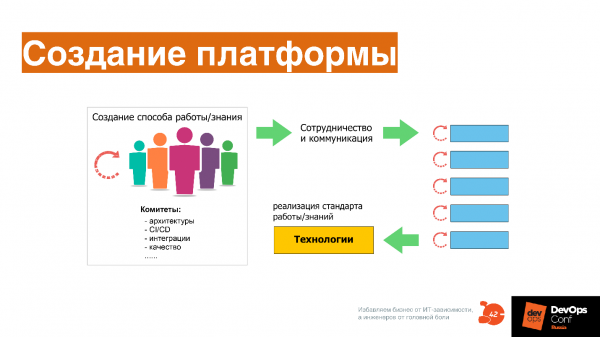
With culture, everything is very simple — it's collaboration and communication, that is, the willingness to work in the same field with each other, the desire to use the same tool together. There's no rocket science here — it's very straightforward, basic. For example, we all live in an apartment building and keep it clean — that's the level of culture.
And what about you?
Again, questions you might ask yourself.
Is the infrastructure platform clearly defined? Who is responsible for its development? Do you understand the competitive advantages of your infrastructure platform?
These are questions you should always be asking yourself. If something can be outsourced to external services, it should be, and if an external service starts to hinder your progress, then a system needs to be built internally.
So, DevOps…
… is a complex system that must include:
- Digital products.
- Business modules that enhance this digital product.
- Product teams that write code.
- Continuous Delivery practices.
- Platforms as a service.
- Infrastructure as a service.
- Infrastructure as code.
- Individual reliability maintenance practices embedded within DevOps.
- Feedback practices that describe all of this.
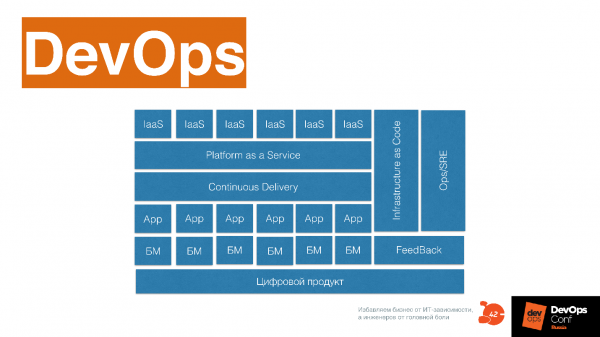
You can use this framework, highlighting what you already have in your company in some form: it has developed or still needs to be developed.
In just a couple of weeks, . as part of RIT++. Join the conference where many exciting talks await you about continuous delivery, infrastructure as code, and DevOps transformation. , the final deadline for prices is May 20th.
Source: habr.com
