

On August 10, Slyurm launched , where we cover it thoroughly — from basic abstractions to network parameters.
In this article, we will discuss the history of Docker and its primary abstractions: Image, CLI, Dockerfile. The lecture is aimed at beginners, so it is unlikely to be interesting for experienced users. There will be no blood, appendices, or deep dives. Just the basics.
What is Docker
Let’s look at Docker’s definition from Wikipedia.
Docker is software for automating the deployment and management of applications in environments that support containerization.
This definition doesn’t clarify much. Particularly, it’s unclear what ‘in environments that support containerization’ means. To understand it, we need to go back in time. Let’s start from what I term the 'Monolithic Era.'
Monolithic Era
The Monolithic Era was the early 2000s when all applications were monolithic, with a plethora of dependencies. Development took a long time. At that time, there weren't many servers; we all knew them by name and monitored them closely. There's a funny analogy:
Pets — these are household animals. In the monolithic era, we treated our servers like pets, nurturing and cherishing them, dusting off any debris. To manage resources better, we used virtualization: taking one server and splitting it into several virtual machines to ensure environment isolation.
Hypervisor-based Virtualization Systems
Everyone has surely heard of virtualization systems: VMware, VirtualBox, Hyper-V, Qemu KVM, etc. They provide application isolation and resource management, but they also have downsides. To enable virtualization, a hypervisor is required. And a hypervisor brings resource overhead. Moreover, the virtual machine itself is usually quite bulky — a heavy image containing the operating system, Nginx, Apache, and possibly MySQL. The image is large and cumbersome to operate with. Consequently, working with virtual machines can be slow. To address this issue, virtualization systems at the kernel level were created.
Kernel-Level Virtualization Systems
Kernel-level virtualization is supported by systems such as OpenVZ, Systemd-nspawn, LXC. A prominent example of such virtualization is LXC (Linux Containers).
LXC is an operating system-level virtualization system for running multiple isolated instances of the Linux operating system on a single node. LXC does not use virtual machines but creates a virtual environment with its own process space and network stack.
Essentially, LXC creates containers. What is the difference between virtual machines and containers?
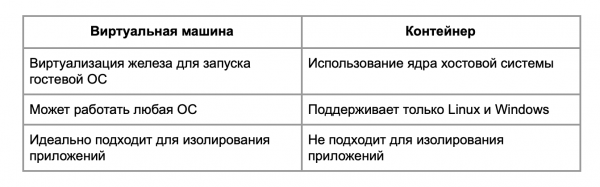
A container is not suitable for isolating processes: kernel-level virtualization systems have vulnerabilities that allow escaping from the container to the host. Therefore, if you need to isolate something, it is better to use a virtual machine.
The differences between virtualization and containerization can be seen in the diagram.
There are hardware hypervisors, hypervisors on top of the OS, and containers.
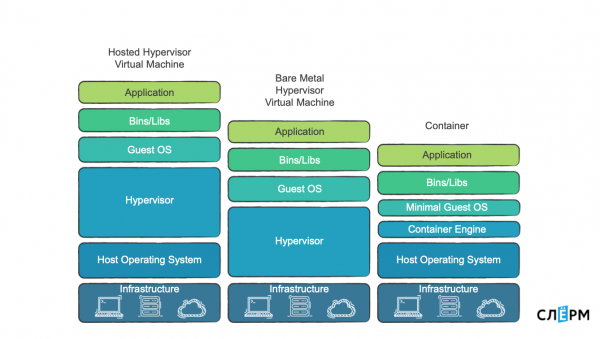
Hardware hypervisors are great if you really want to isolate something. Because they offer the ability to isolate at the level of memory pages and processors.
There are hypervisors as programs, and there are containers, which we will discuss next. In containerization systems, there is no hypervisor, but there is a Container Engine that creates and manages containers. This is a lighter-weight solution, so due to its operation with the kernel, the overhead is lower or nonexistent.
What is used for kernel-level containerization
The main technologies that allow creating a container isolated from other processes are Namespaces and Control Groups.
Namespaces: PID, Networking, Mount, and User. There are others, but for simplicity, we will focus on these.
The PID Namespace restricts processes. When we create a PID Namespace and place a process in it, it becomes PID 1. Normally, in systems, PID 1 is either systemd or init. Accordingly, when we place a process into a new namespace, it too receives PID 1.
The Networking Namespace allows limiting/isolate the network and to place its own interfaces within. Mount is a restriction on the file system. User is a restriction on users.
Control Groups: Memory, CPU, IOPS, Network — there are about 12 settings in total. They are also called Cgroups.
Control Groups manage resources for the container. Through Control Groups, we can specify that a container should not consume more than a certain amount of resources.
For containerization to work effectively, additional technologies are used: Capabilities, Copy-on-write, and others.
Capabilities refer to defining what a process is allowed to do and what it is not. At the kernel level, these are simply bitmaps with numerous parameters. For example, the root user has full privileges and can do anything. A time server can change the system time: it has capabilities for the Time Capsule, and that's it. Privileges allow for flexible configurations to set restrictions on processes, thereby enhancing security.
The Copy-on-write system enables us to work with Docker images more efficiently.
At present, Docker has compatibility issues with Cgroups v2; therefore, this article focuses on Cgroups v1.
But let's return to the history.
When virtualization systems at the kernel level emerged, they began to be actively adopted. The overhead for the hypervisor disappeared, but some problems remained:
- large images: in OpenVZ, you push the operating system, libraries, and a bunch of different software, resulting in a rather large image;
- there's no proper packaging and delivery standard, leading to dependency issues. There are situations where two pieces of code use the same library but with different versions. Conflicts can arise between them.
To address all these issues, the next era came.
The Era of Containers
When the Era of Containers began, the philosophy of how to work with them changed:
- One process—one container.
- All dependencies needed by the process are delivered within its container. This requires breaking down monoliths into microservices.
- The smaller the image, the better—fewer potential vulnerabilities, faster deployments, and so on.
- Instances become ephemeral.
Remember, I mentioned pets vs cattle? Earlier, instances resembled pets, but now they resemble cattle. There used to be a monolith—one application. Now, there are 100 microservices, 100 containers. Some containers may have 2-3 replicas. We are less concerned with controlling each container. Instead, we prioritize the availability of the service itself: what that set of containers does. This changes monitoring approaches.
In 2014-2015, Docker flourished—the technology we will discuss now.
Docker has changed the philosophy and standardized application packaging. With Docker, we can package an application, send it to a repository, download it from there, and deploy it.
In a Docker container, we include everything necessary, thus solving the dependency problem. Docker ensures reproducibility. I believe many have faced the issue of non-reproducibility: everything works for you, you push it to production, and then it stops working. With Docker, this problem disappears. If your Docker container runs and does what it's supposed to do, it will very likely run in production and do the same thing there.
A digression about overhead
There are ongoing debates regarding overhead. Some believe that Docker does not impose additional load as it uses the Linux kernel and all the processes necessary for containerization. They argue, "If you say Docker is overhead, then the Linux kernel is also overhead."
On the other hand, if you look deeper, there are indeed several aspects of Docker that can be somewhat considered overhead.
The first is the PID namespace. When we place a process in the namespace, it is assigned PID 1. At the same time, this process has another PID, which resides in the host namespace, outside the container. For example, if we run Nginx in a container, it becomes PID 1 (the master process). Meanwhile, on the host, it has PID 12623. It's difficult to say how much this constitutes overhead.
The second aspect is Cgroups. Let's take Cgroups for memory, that is, the ability to limit the container's memory. When it's enabled, counters are activated, memory accounting: the kernel needs to understand how many pages have been allocated and how many are still free for that container. This could be overhead, but I haven't seen any precise studies on how it affects performance, and I haven't noticed that applications running in Docker suddenly lost performance.
And one more note on performance. Some kernel parameters are passed from the host to the container. Specifically, some network parameters. Therefore, if you want to run something high-performance in Docker, for instance, something that will actively use the network, you will need to at least adjust these parameters. For example, nf_conntrack.
About the concept of Docker
Docker consists of several components:
- The Docker Daemon is the Container Engine; it runs containers.
- Docker CII is a utility for managing Docker.
- A Dockerfile is an instruction on how to build an image.
- An Image is the template from which containers are created.
- Container.
- A Docker registry is a repository for images.
Schematically, it looks like this:
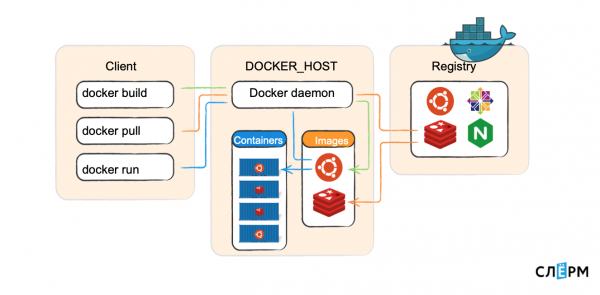
On the Docker host, the Docker daemon runs containers. There is a Client that sends commands: build an image, download an image, run a container. The Docker daemon connects to the registry to execute them. The Docker client can interact both locally (with a Unix socket) and remotely via TCP.
Let's go through each component.
Docker daemon is the server part, running on the host machine: it downloads images and starts containers from them, creates a network between containers, and collects logs. When we say 'create an image,' that's also handled by the daemon.
Docker CLI is the client part of Docker, a command-line utility for working with the daemon. Again, it can operate not only locally but over a network as well.
Basic commands:
docker ps — shows the containers currently running on the Docker host.
docker images — displays images downloaded locally.
docker search — search for an image in the registry.
docker pull — download an image from the registry to the machine.
docker build <> — build an image.
docker run — run a container.
docker rm — remove a container.
docker logs — view container logs.
docker start/stop/restart — manage a container.
If you master these commands and use them confidently, you can consider yourself 70% proficient in Docker at the user level.
Dockerfile is an instruction for creating an image. Almost every command in the instruction represents a new layer. Let's examine an example.
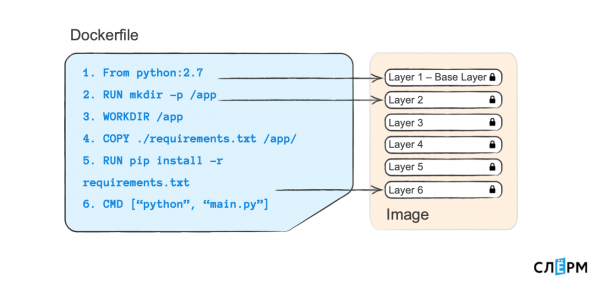
Here's what a Dockerfile looks like: commands on the left, arguments on the right. Each command present here (and written in a Dockerfile) creates a new layer in the Image.
Even looking at the left side, you can roughly understand what's happening. We say, 'create a folder' — that's one layer. 'Set the folder as the working directory' — that's another layer, and so on. The layered approach simplifies the process. If I create another Dockerfile and change something in the last line — running not 'python main.py' but something else or installing dependencies from another file — then the previous layers will be reused as cache.
Image — is a container image, from which containers are launched. If we look at Docker from the perspective of a package manager (as if we were working with deb or rpm packages), then an image is essentially an rpm package. Through yum install, we can install an application, remove it, find it in the repository, download it. Here it is roughly the same: containers are launched from an image, they are stored in a Docker registry (similarly to yum, in a repository), and each image has a SHA-256 hash, name, and tag.
An image is built according to the instructions in the Dockerfile. Each instruction from the Dockerfile creates a new layer. Layers can be reused.
Docker registry — is a repository of Docker images. Similarly to operating systems, Docker has a public standard registry — dockerhub. However, you can build your own repository, your own Docker registry.
Container — is what runs from an image. After building an image according to the Dockerfile, we launch it from that image. This container is isolated from other containers; it must contain everything needed for the application to work. Moreover, one container means one process. Occasionally, you may have to run two processes, but this somewhat contradicts the ideology of Docker.
The requirement of "one container — one process" is associated with PID Namespace. When a process with PID 1 is launched in the Namespace, if it dies unexpectedly, the entire container dies as well. However, if two processes are running: one is alive while the other has died, the container will still continue to live. But this relates to Best Practices, which we will discuss in other materials.
To learn more about the features and full program of the course, follow this link: "».
Author: Marsel Ibraev, certified Kubernetes administrator, practicing engineer at Southbridge, speaker and course developer at Slurm.
Source: habr.com
