

The professions of Data Scientist and Data Engineer are often confused. Each company has its own specifics regarding data work, different analysis goals, and varying perspectives on which specialist should handle which part of the job, hence the requirements differ.
We will explore the differences between these specialists, the business tasks they solve, their skill sets, and their salaries. The material is extensive, so we have divided it into two publications.
In the first article, Elena Gerasimova, head of the "" faculty at Netology, discusses the differences between Data Scientists and Data Engineers and the tools they use.
How the Roles of Engineers and Scientists Differ
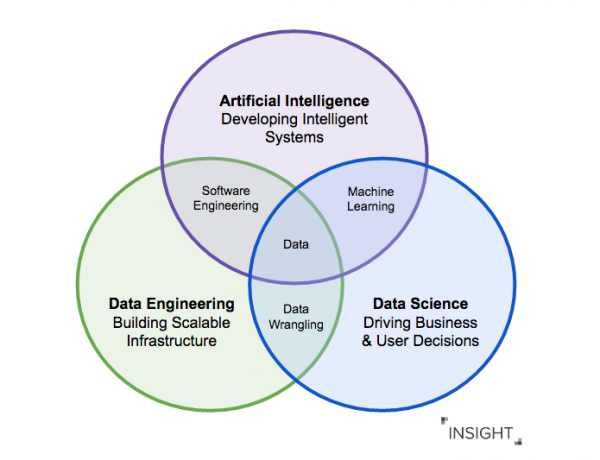
A Data Engineer is a specialist who, on one hand, develops, tests, and maintains the infrastructure for working with data: databases, storage, and large-scale processing systems. On the other hand, they clean and "refine" the data for use by analysts and data scientists, meaning they create data processing pipelines.
A Data Scientist builds and trains predictive (and other) models using machine learning algorithms and neural networks, helping the business uncover hidden patterns, forecast events, and optimize key business processes.
The main difference between a Data Scientist and a Data Engineer is that they usually have different goals. Both work to ensure that data is accessible and of high quality. However, a Data Scientist seeks answers to specific questions and tests hypotheses in the data ecosystem (for example, on a Hadoop cluster), while a Data Engineer builds the maintenance pipeline for the machine learning algorithm developed by the data scientist within the same ecosystem on a Spark cluster.
A Data Engineer adds value to the business by working within a team. Their task is to act as a crucial link between various participants, from developers to business report consumers, and to enhance the productivity of analysts—from marketing and product teams to BI.
In contrast, a Data Scientist actively participates in the company's strategy and insight extraction, decision-making, implementation of automation algorithms, modeling, and generating value from data.
Working with data follows the GIGO principle (garbage in — garbage out): if analysts and data scientists deal with unprepared and potentially incorrect data, the results will be inaccurate even with the most sophisticated analysis algorithms.
Data engineers solve this problem by building pipelines for data processing, cleaning, and transformation, allowing data scientists to work with quality data.
The market offers many tools for data handling that cover every stage: from data emergence to dashboard outputs for the board of directors. It's crucial that decisions about their use are made by engineers, not because it's trendy, but because they genuinely help other participants in the process.
Conditionally: if a company needs to bridge BI and ETL — data loading and report updating, here is a typical legacy infrastructure that a Data Engineer will have to deal with (it's good if there's also an architect in the team besides him).
Responsibilities of a Data Engineer
- Designing, building, and maintaining the data workflow infrastructure.
- Error handling and creating reliable data processing pipelines.
- Transforming unstructured data from various dynamic sources into a format necessary for analysts' work.
- Providing recommendations to improve data consistency and quality.
- Ensuring and maintaining the data architecture used by data scientists and analysts.
- Processing and storing data consistently and efficiently in a distributed cluster of dozens or hundreds of servers.
- Evaluating the technical trade-offs of tools to create simple yet reliable architectures that can withstand failures.
- Monitoring and maintaining data streams and related systems (setting up monitoring and alerts).
There is another specialization within the Data Engineer trajectory — ML engineer. In short, these engineers specialize in bringing machine learning models to industrial implementation and use. Often, a model received from a data scientist is part of a study and may not perform well in real-world conditions.
Responsibilities of a Data Scientist
- Extracting features from data for the application of machine learning algorithms.
- Using various machine learning tools for predicting and classifying patterns in data.
- Improving the performance and accuracy of machine learning algorithms through fine-tuning and optimization.
- Formulating ‘strong’ hypotheses in line with company strategy that need to be tested.
Both Data Engineers and Data Scientists contribute significantly to the development of a data-driven culture, enabling companies to generate additional profits or reduce costs.
What languages and tools do engineers and scientists work with?
Today, the expectations of data processing specialists have changed. Previously, engineers would build large SQL queries, manually write MapReduce, and process data using tools like Informatica ETL, Pentaho ETL, and Talend.
In 2020, a specialist cannot do without knowledge of Python and modern computational tools (like Airflow), as well as an understanding of how to work with cloud platforms (using them to save on hardware while adhering to security principles).
SAP, Oracle, MySQL, Redis are traditional tools for data engineers in large companies. They are good, but the cost of licenses is so high that learning to work with them makes sense only in industrial projects. There is, however, a free alternative in the form of Postgres — it is free and suitable not only for learning.
Historically, there has often been a demand for Java and Scala, although as technologies and approaches evolve, these languages are becoming less prominent.
However, hardcore Big Data tools like Hadoop, Spark, and other frameworks are no longer mandatory for data engineers, but rather a variety of tools to solve problems that cannot be addressed with traditional ETL.
The trend is towards services that allow the use of tools without knowledge of the programming language they are written in (e.g., Hadoop without knowing Java), as well as providing ready-made services for processing streaming data (like voice recognition or image recognition in videos).
Industrial solutions from SAS and SPSS are popular, while Tableau, Rapidminer, Stata, and Julia are also widely used by data scientists for local tasks.
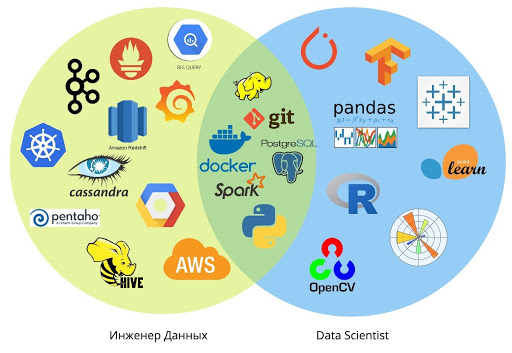
The ability to build pipelines for themselves has only recently become available to analysts and data scientists, as they can now use relatively simple scripts to direct data into a PostgreSQL-based storage.
Typically, the use of pipelines and integrated data structures remains the domain of data engineers. However, today the trend for T-shaped specialists with broad competencies in adjacent fields is stronger than ever, as tools are constantly being simplified.
Why Data Engineers and Data Scientists Should Work Together
By working closely with engineers, Data Scientists can focus on the research aspect, creating ready-to-use machine learning algorithms.
Engineers, in turn, can concentrate on scalability, data reusability, and ensuring that input and output data pipelines for each project align with the global architecture.
This division of responsibilities ensures consistency in actions among teams of specialists working on different machine learning projects.
Collaboration helps efficiently create new products. Speed and quality are achieved through a balance between creating services for everyone (global storage or dashboard integration) and addressing each specific need or project (niche pipeline, connecting external sources).
Close collaboration with data scientists and analysts helps engineers develop analytical and research skills for writing higher-quality code. This improves knowledge sharing between users of data warehouses and data lakes, making projects more flexible and ensuring more sustainable long-term results.
In companies that aim to cultivate a data-driven culture and build business processes based on it, Data Scientists and Data Engineers complement each other and create a comprehensive data analytics system.
In the next article, we will discuss the educational background that Data Engineers and Data Scientists should have, the skills they need to develop, and how the job market looks.
From the editorial team of Netology
If you're considering a career as a Data Engineer or Data Scientist, we invite you to explore our course programs:
- The profession of “».
- The profession of “».
Source: habr.com
