

Open Source DataHub: a platform for searching and discovering metadata from LinkedIn
A quick search for necessary data is essential for any company that relies on a large volume of data to make informed decisions. This not only impacts the productivity of data users (including analysts, machine learning developers, data processing specialists, and data engineers) but also has a direct effect on end products that depend on a quality machine learning (ML) pipeline. Furthermore, the trend of adopting or creating machine learning platforms naturally raises the question: what is your method for internal feature, model, metric, dataset discovery, etc.?
In this article, we will discuss how we open-sourced our data source. in our metadata search and discovery platform, starting from the early days of the project. . LinkedIn maintains its own version of DataHub separate from the open-source version. We will start by explaining why we need two distinct development environments, followed by discussions on the early approaches to using the open-source WhereHows, and a comparison between our internal (production) version of DataHub and the version on . We will also share details about our new automated solution for sending and receiving updates from the open-source repository to synchronize both repositories. Finally, we will provide instructions on how to get started with the open-source DataHub and briefly discuss its architecture.
WhereHows is now DataHub!
The LinkedIn metadata team previously introduced (the successor to WhereHows), LinkedIn's metadata search and discovery platform, and shared plans to open it. Soon after this announcement, we released the alpha version of DataHub and shared it with the community. Since then, we have continuously contributed to the repository and worked with interested users to add the most requested features and resolve issues. We are now excited to announce the official release of .
Open-source approaches
WhereHows, LinkedIn's original portal for data search and lineage, was launched as an internal project; the metadata team opened its Since then, the team has always maintained two separate codebases — one for open source and another for internal use by LinkedIn, as not all product features developed for LinkedIn's use cases were applicable to a broader audience. Additionally, WhereHows has some internal dependencies (infrastructure, libraries, etc.) whose source code is not open. Over the years, WhereHows has gone through many iterations and development cycles, making the synchronization of the two codebases a significant challenge. The metadata team has attempted various approaches over the years to try to synchronize internal development with open source development.
The first attempt: 'Open source first'
Initially, we followed an 'open source first' development model, where primary development took place in the open source repository, and changes were made for internal deployment. The problem with this approach is that the code is always sent to GitHub first before it is fully validated internally. Until changes are made from the open source repository and a new internal deployment is performed, we do not identify any production issues. In the case of a bad deployment, it was also very challenging to determine the culprit because the changes were made in batches.
Moreover, this model reduced the team's productivity when developing new features that required rapid iterations, as it forced all changes to first go into the open source repository before being carried over to the internal repository. To reduce processing time, any necessary fix or change could initially be made in the internal repository, but this became a huge issue when it came to merging those changes back into the open source repository, as the two repositories fell out of sync.
This model is much easier to implement for shared platforms, libraries, or infrastructure projects than for fully functional user web applications. Moreover, this model is ideal for projects that start with open source from day one, but WhereHows was created as a fully internal web application. It was indeed challenging to fully abstract from all internal dependencies, so we needed to maintain an internal fork, but maintaining an internal fork while primarily developing in open source did not quite work out.
Second attempt: 'Internal first'
** As a second attempt, we switched to an 'internal first' development model, where the main development occurs within the company, and changes are regularly made to the open source. Although this model best fits our use case, it has its issues. Directly sending all differences to the open-source repository and then trying to resolve merge conflicts later is an option, but it is very time-consuming. Developers tend to avoid doing this on every code check most of the time. As a result, it will be done much less frequently, in batches, thereby making subsequent merge conflict resolution more difficult.
The third time was a charm!
The two failed attempts mentioned above led to the WhereHows GitHub repository being outdated for a long time. The team continued to enhance product features and architecture, making the internal version of WhereHows for LinkedIn increasingly sophisticated compared to the open-source version. It even had a new name — DataHub. Based on previous unsuccessful attempts, the team decided to develop a scalable long-term solution.
For any new open-source project, the LinkedIn open-source development team advises and supports a development model where project modules are fully developed as open source. Version-supported artifacts are deployed to a public repository and then returned to the internal LinkedIn artifact via Following this development model is not only beneficial for those who use open source, but also leads to the creation of a more modular, extensible, and plug-in architecture.
However, reaching this state for a mature internal application like DataHub will require a significant amount of time. This also rules out the possibility of open-sourcing a fully functioning implementation until all internal dependencies are completely abstracted. Therefore, we developed tools that help us contribute to open source faster and much less painfully. This solution is advantageous for both the metadata team (DataHub developer) and the open source community. This new approach will be discussed in the following sections.
Open Source Publication Automation
The latest approach from the metadata group regarding DataHub with open source is the development of a tool that automatically synchronizes the internal codebase and the open source repository. High-level features of this toolkit include:
- Synchronizing LinkedIn code to/from open source, similar to .
- License header generation, similar to .
- Automatic generation of open source commit logs from internal commit logs.
- Preventing internal changes from breaking the open source build by .
The following subsections will delve into the aforementioned features, which present interesting challenges.
Source Code Synchronization
Unlike the open source version of DataHub, which is a single GitHub repository, the LinkedIn version of DataHub consists of a combination of several repositories (internally referred to as ). The DataHub interface, metadata model library, metadata storage backend service, and streaming jobs are in different repositories within LinkedIn. However, to ease the workflow for open source users, we have a single repository for the open source version of DataHub.
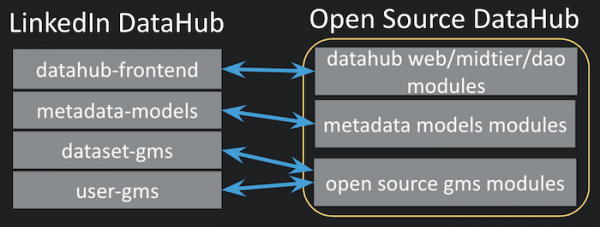
Figure 1: Synchronization Between Repositories LinkedIn DataHub and a single repository DataHub for open source
To support automated workflows for building, sending, and extracting, our new tool automatically creates file-level mappings corresponding to each source file. However, the tool requires initial configuration, and users must provide a high-level mapping of modules, as shown below.
{
  "datahub-dao": [
    "${datahub-frontend}/datahub-dao"
  ],
  "gms/impl": [
    "${dataset-gms}/impl",
    "${user-gms}/impl"
  ],
  "metadata-dao": [
    "${metadata-models}/metadata-dao"
  ],
  "metadata-builders": [
    "${metadata-models}/metadata-builders"
  ]
}
Module-level mapping is a simple JSON where the keys are target modules in the open-source repository and the values are lists of source modules in LinkedIn repositories. Any target module in the open-source repository can be fed by multiple source modules. Internal repository names in source modules are designated using in Bash style. Using the module-level mapping file, tools create a file-level mapping by scanning all files in the related directories.
{
  "${metadata-models}/metadata-builders/src/main/java/com/linkedin/Foo.java":
"metadata-builders/src/main/java/com/linkedin/Foo.java",
  "${metadata-models}/metadata-builders/src/main/java/com/linkedin/Bar.java":
"metadata-builders/src/main/java/com/linkedin/Bar.java",
  "${metadata-models}/metadata-builders/build.gradle": null,
}
File-level mapping is automatically created by the tools; however, it can also be updated manually by the user. This is a 1:1 mapping of the source file in LinkedIn to the file in the open-source repository. There are several rules associated with this automatic creation of file mappings:
- In the case of multiple source modules for a target module in open source, conflicts may arise, for example, the same , existing in more than one source module. As a conflict resolution strategy, our tools use the 'last wins' option by default.
- 'null' means that the source file is not part of the open-source repository.
- After each submission of open source code or extraction, this mapping is automatically updated and a snapshot is created. This is necessary to identify additions and deletions of source code since the last action.
Creating commit logs
Commit logs for open source commits are also automatically generated by merging commit logs from internal repositories. Below is a sample commit log to illustrate the structure of the commit log generated by our tool. The commit clearly indicates which versions of the source repositories are packaged in this commit and provides a summary of the commit log. Check this against a real example of a commit log created by our tooling.
metadata-models 29.0.0 -> 30.0.0
    Added aspect model foo
    Fixed issue bar

dataset-gms 2.3.0 -> 2.3.4
    Added rest.li API to serve foo aspect

MP_VERSION=dataset-gms:2.3.4
MP_VERSION=metadata-models:30.0.0
Dependency testing
LinkedIn has , which helps ensure that changes to the internal multi-product do not break the builds of dependent multi-products. The open source DataHub repository is not a multi-product and cannot be a direct dependency of any multi-product, but through a multi-product shell that pulls the source code of the open source DataHub, we can still utilize this dependency testing system. Therefore, any change (which may later be opened) in any of the multi-products feeding into the open source DataHub repository triggers a build event in the shell multi-product. Consequently, any change that prevents the shell multi-product from building does not pass the tests before committing to the original multi-product and is rejected.
This is a useful mechanism that helps prevent any internal commit that breaks the build of the open source code, detecting it during the commit creation. Without this, it would be quite difficult to determine which internal commit caused the build failure of the open source repository, because we place bundled internal changes into the open source DataHub repository.
Differences between the open-source DataHub and our production version
Up to this point, we have discussed our solution for synchronizing two versions of the DataHub repositories, but we have not yet outlined the reasons why we need two different development streams at all. In this section, we will outline the differences between the public version of DataHub and the production version on LinkedIn’s servers, as well as explain the reasons for these differences.
One source of discrepancies arises from the fact that our production version has dependencies on proprietary code, such as LinkedIn’s Offspring (the internal dependency injection framework). Offspring is widely used within the internal codebase because it is the preferred method for managing dynamic configuration. However, it is not open source; thus, we needed to find open-source alternatives for the open-source DataHub.
There are other reasons as well. As we create metadata model extensions for LinkedIn's needs, these extensions tend to be highly specific to LinkedIn and may not be directly applicable to other environments. For example, we have very specific tags for participant IDs and other types of metadata matching. Therefore, we have currently excluded these extensions from the metadata model of the open-source DataHub. As we engage with the community and understand their needs, we will work on open-source versions of these extensions where necessary.
Ease of use and easier adaptation for the open-source community have also inspired some differences between the two versions of DataHub. Differences in streaming infrastructure are a good example. While our internal version uses managed streaming infrastructure, we chose to implement embedded (standalone) streaming for the open-source version, as it helps avoid creating yet another infrastructure dependency.
Another example of the difference is the presence of a single GMS (Generalized Metadata Store) in the open-source implementation, as opposed to multiple GMS. GMA (Generalized Metadata Architecture) refers to the internal architecture for DataHub, while GMS is the metadata store in the context of GMA. GMA is a highly flexible architecture that allows you to distribute each data construct (e.g., datasets, users, etc.) into its own metadata store or keep multiple data constructs in one metadata store as long as the registry containing the mapping of the data structure in GMS is updated. For ease of use, we chose a single instance of GMS that stores all the various data constructs in the open-source DataHub.
A complete list of differences between the two implementations is provided in the table below.
Product Features
LinkedIn DataHub
Open Source DataHub
Supported Data Constructs
1) Datasets 2) Users 3) Metrics 4) ML Features 5) Charts 6) Dashboards
1) Datasets 2) Users
Supported Metadata Sources for Datasets
1) 2) Couchbase 3) 4) 5) HDFS 6) Hive 7) Kafka 8) MongoDB 9) MySQL 10) Oracle 11) 12) Presto 12) 13) Teradata 13) Vector 14)
Hive Kafka RDBMS
Pub-sub
Confluent Kafka
Stream Processing
Managed
Embedded (standalone)
Dependency Injection & Dynamic Configuration
LinkedIn Offspring
Build Tooling
Ligradle (LinkedIn’s internal Gradle wrapper)
CI/CD
CRT (LinkedIn’s internal CI/CD)
and
Metadata Stores
Distributed multiple GMS: 1) Dataset GMS 2) User GMS 3) Metric GMS 4) Feature GMS 5) Chart/Dashboard GMS
Single GMS for: 1) Datasets 2) Users
Microservices in Docker containers
simplifies the deployment and distribution of applications through Each part of the service in the open-source DataHub, including infrastructure components such as Kafka, , and , has its own Docker image. For orchestration of Docker containers, we used .
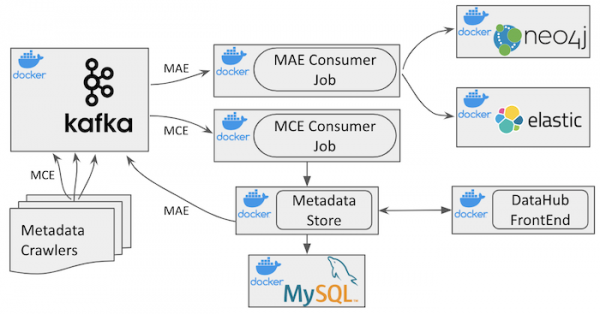
Figure 2: Architecture DataHub *open source*
You can see the high-level architecture of DataHub in the image above. Besides infrastructure components, it has four different Docker containers:
datahub-gms: metadata storage service
datahub-frontend: application , serving the DataHub interface.
datahub-mce-consumer: application , which uses the metadata change event (MCE) stream and updates the metadata store.
datahub-mae-consumer: application , which uses the metadata audit event (MAE) stream to create a search index database and a graph.
Documentation for the open-source repository and contain more detailed information about the features of various services.
CI / CD in DataHub with open source
The open-source DataHub repository uses for continuous integration and for continuous deployment. Both have good integration with GitHub and are easy to set up. For most of the open-source infrastructure developed by the community or private companies (e.g., ), Docker images are created and deployed in Docker Hub for ease of use by the community. Any Docker image found in Docker Hub can be easily used with a simple command .
With every commit in the open-source DataHub repository, all Docker images are automatically created and deployed to Docker Hub with the tag 'latest'. If there is a setup in Docker Hub for certain , all tags in the open-source repository are also released with corresponding tag names in Docker Hub.
Using DataHub
is very straightforward and consists of three simple steps:
- Clone the open-source repository and run all Docker containers with docker-compose using the provided docker-compose script for quick setup.
- Download the sample data presented in the repository using the command-line tool that is also provided.
- View DataHub in your browser.
An actively monitored is also set up for quick questions. Users can also create issues directly in the GitHub repository. Most importantly, we welcome and appreciate all feedback and suggestions!
Plans for the future
Currently, every infrastructure or microservice for DataHub is built as a Docker container, and the entire system is orchestrated using . Given the popularity and widespread use of , we would also like to provide a Kubernetes-based solution in the near future.
We also plan to provide a ready-to-use solution for deploying DataHub in a public cloud service such as , or . Considering the recent announcement of LinkedIn's migration to Azure, this aligns with the internal priorities of the metadata group.
And last but not least, thank you to all the early users of DataHub in the open-source community who valued the alpha versions of DataHub and helped us identify issues and improve the documentation.
Source: habr.com
