

Variti develops bot and DDoS protection and also conducts stress and load testing. At the HighLoad++ 2018 conference, we discussed how to secure resources from various types of attacks. In short: isolate parts of the system, use cloud services and CDNs, and stay updated regularly. However, without specialized companies for protection, you still won't manage 🙂
Before reading the text, you can review the short theses .
And if you prefer not to read or just want to watch a video, the recording of our presentation is below under the spoiler.
Video recording of the presentation
Many companies already know how to perform load testing, but not all conduct stress testing. Some of our clients believe that their site is invulnerable because they have a high-load system, and it is well protected from attacks. We show that this is not entirely true.
Of course, before conducting tests, we obtain permission from the client, with a signature and stamp, and with our assistance, a DDoS attack cannot be directed at anyone. Testing is conducted at a time chosen by the client when traffic to their resource is minimal, and access issues will not affect customers. Additionally, since things can go wrong during testing, we maintain constant contact with the client. This allows us not only to report on the results achieved but also to make adjustments during the testing process. Upon completion of the testing, we always prepare a report that highlights identified shortcomings and provides recommendations for addressing the vulnerabilities of the site.
How We Operate
When conducting testing, we emulate a botnet. Since we work with clients who are not located within our networks, we ensure that the test does not end in the first minute due to limits or protections by applying load not from a single IP but from our own subnet. Moreover, to create significant load, we have our own sufficiently powerful test server.
Postulates
More does not mean better
The lower the load we can bring the resource to failure, the better. If we can make the site stop functioning with just one request per second, or even with one request per minute, that’s great. Because according to Murphy's law, users or attackers will accidentally exploit that vulnerability.
Partial failure is better than complete failure.
We always recommend making systems heterogeneous. Moreover, they should be separated at the physical level, not just through containerization. In the case of physical separation, even if something fails on the site, there is a good chance that it won't stop working completely, and users will retain access to at least part of the functionality.
Proper architecture is the foundation of resilience.
The fault tolerance of a resource and its ability to withstand attacks and loads must be built in at the design stage, essentially when sketching the first flowcharts in a notebook. Because if critical errors creep in, fixing them later is possible but very difficult.
Not only the code, but also the configuration must be good.
Many think that a good development team guarantees the fault tolerance of the service. A good development team is indeed necessary, but there also needs to be good operations, a solid DevOps. This means having specialists who can properly configure Linux and the network, correctly write configurations in nginx, set limits, and so on. Otherwise, the resource will work well only in testing, but at some point in production, everything will break.
Differences between load testing and stress testing.
Load testing allows you to identify the operating limits of the system. Stress testing is aimed at finding the system's weak points and is used to break the system and see how it behaves during the failure of certain components. The nature of the load typically remains unknown to the customer until the stress testing begins.
Distinctive features of L7 attacks.
We usually divide loads into L7 and L3&4 levels. L7 is application-level load, most often understood to mean only HTTP; we mean any load at the TCP protocol level.
L7 attacks have certain distinctive features. Firstly, they target applications directly, making it unlikely to mitigate them with network-level defenses. These attacks leverage application logic, thus consuming CPU, memory, disk, database, and other resources very efficiently even with low traffic.
HTTP Flood
In any attack, it's easier to create load than to process it, and this holds true for L7 as well. The attack traffic is not always easy to distinguish from legitimate traffic, often identifiable only by frequency. However, if planned correctly, it becomes impossible to differentiate between attack logs and legitimate requests.
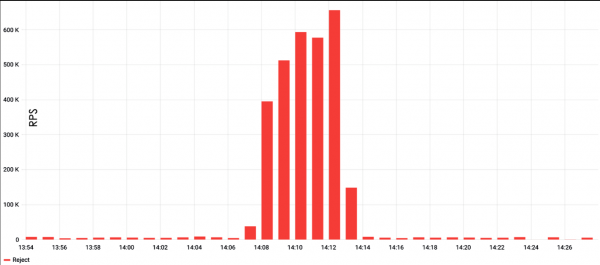
As a first example, let's examine an HTTP Flood attack. The graph indicates that such attacks are typically very powerful; in the example below, the peak number of requests exceeded 600,000 per minute.
HTTP Flood is the simplest way to generate load. Typically, a load testing tool like ApacheBench is used to specify a request and a target. With this straightforward approach, there's a high chance of encountering server caching, but it can be easily bypassed by adding random strings to the request, which forces the server to continuously deliver fresh pages.
Additionally, it’s crucial to consider the user-agent during the load generation process. Many user-agents from popular testing tools are filtered by system administrators, which means the load may not even reach the backend. The results can be significantly improved by inserting a more or less valid header from a browser into the request.
Despite their simplicity, HTTP Flood attacks have their drawbacks. Firstly, generating load requires substantial resources. Secondly, these attacks are very easy to detect, especially if they originate from a single address. Consequently, requests are often filtered either by system administrators or even at the provider level.
What to look for
To reduce the number of requests per second without losing efficiency, some creativity is required to explore the website. It is possible to load not only the channel or server but also individual parts of the application, such as databases or file systems. Additionally, one can look for areas on the site that perform heavy computations: calculators, product selection pages, and more. Finally, it's common for a website to have a PHP script that generates a page from several hundred thousand lines. Such a script can significantly load the server and may become a target for attacks.
Where to look
When we scan a resource before conducting testing, we primarily look at the site itself. We search for various input fields, heavy files — basically anything that could create problems for the resource and slow it down. Basic development tools in Google Chrome and Firefox help here, showing page response times.
We also scan subdomains. For example, there is an online store, abc.com, which has a subdomain admin.abc.com. This is likely an admin panel requiring authorization, but if we apply load to it, it could cause problems for the main resource.
The site might have a subdomain api.abc.com. This is likely a resource for mobile applications. The application can be found in the App Store or Google Play, we can set up a specific access point, dissect the API, and register test accounts. The issue is that people often believe that anything protected by authentication is immune to denial-of-service attacks. Supposedly, authentication serves as the best CAPTCHA, but that’s not true. Creating 10-20 test accounts is simple, and once we have them, we gain access to complex and unguarded functionality.
Naturally, we look at history, robots.txt, and WebArchive, ViewDNS, searching for old versions of the resource. Sometimes developers roll out, say, mail2.yandex.net, while an old version, mail.yandex.net, remains. This mail.yandex.net becomes unsupported, development resources are not allocated to it, but it continues to consume database resources. Hence, the old version can effectively utilize backend resources and everything that lies behind the markup. Of course, this doesn't happen all the time, but we encounter similar situations fairly often.
Of course, we analyze all request parameters and the cookie structure. For example, we can push some value into a JSON array inside a cookie, create significant nesting, and cause the resource to operate unreasonably slowly.
Load in search
The first thought that comes to mind when researching a site is to load the database, as almost every site has search functionality, and unfortunately, most of them are poorly protected. For some reason, developers do not pay enough attention to search functions. However, one recommendation here is to avoid making identical requests, as you may encounter caching, just like with an HTTP flood.
Making random requests to the database isn't always effective either. It's much better to create a list of keywords relevant to the search. Returning to the example of an online store: suppose the site sells car tires and allows users to specify tire radius, type of vehicle, and other parameters. Consequently, combinations of relevant words will make the database work under much more complex conditions.
Additionally, it's advisable to use pagination: it's much more difficult for the search to provide the penultimate results page than the first. In other words, pagination can diversify the load somewhat.
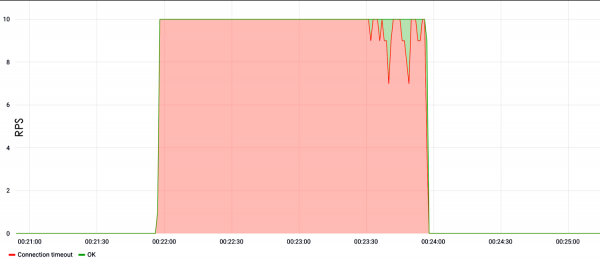
The example below shows the load on search. It is evident that from the very first second of the test at a speed of ten requests per second, the site crashed and did not respond.
What if there is no search?
If there is no search, it doesn't mean that the site doesn't have other vulnerable input fields. One such field could be authentication. Nowadays, developers like to create complex hashes to protect the login database from rainbow table attacks. This is good, but such hashes consume significant CPU resources. A large stream of false authentications leads to processor failure, and as a result, the site stops functioning.
The presence of various comment and feedback forms on the site is an opportunity to send very large texts there or simply to create mass flooding. Sometimes, sites accept nested files, including in gzip format. In this case, we take a file that is 1TB big, compress it down to several bytes or kilobytes with gzip, and send it to the site. It then gets decompressed, resulting in a very interesting effect.
Rest API
It's worth paying some attention to popular services like Rest API. Protecting a Rest API is much more challenging than securing a regular website. Even basic methods for preventing password guessing and other illegitimate activities don't work for Rest APIs.
Rest APIs can be easily compromised because they interact directly with the database. Disabling such a service can have severe repercussions for a business. This is because the Rest API usually connects not only to the main website but also to mobile applications and certain internal business resources. If these are disrupted, the impact is much greater than that of a simple website failure.
Load on heavy content
When we are asked to test a standard one-page application, landing page, or business card website that lacks complex functionality, we look for heavy content. For example, large images served by the server, binary files, PDF documentation — we try to download all of this. Such tests put significant load on the file system and saturate the channels, making them effective. So even if you don’t crash the server while downloading a large file at low speeds, you will simply congest the network of the target server, leading to a denial of service.
From such a test, it's evident that at a rate of 30 RPS, the site stopped responding, or returned server error 500.
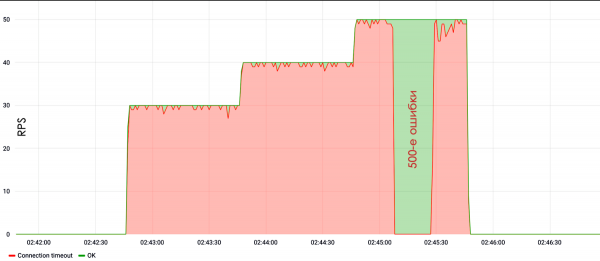
One should not overlook server configuration. It's common to encounter situations where someone buys a virtual machine, installs Apache, sets it up using default settings, deploys a PHP application, and the results can be seen below.
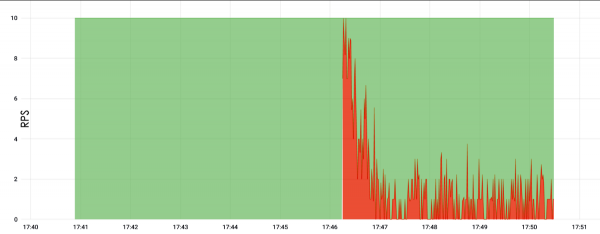
Here, the load was placed at the root and amounted to just 10 RPS. We waited 5 minutes, and the server went down. The exact reason for the crash is uncertain, but it is presumed that it simply ran out of memory, causing it to stop responding.
Wave based
In the past year or two, wave attacks have become quite popular. This is because many organizations purchase certain devices to protect against DDoS attacks, which require a certain amount of time to accumulate statistics before they can start filtering the attack. That is, they do not filter the attack in the first 30-40 seconds because they are gathering data and learning. Accordingly, during these 30-40 seconds, a website can be overwhelmed to the point of being down for a long time until all requests are processed.
In the case of the attack below, there was a 10-minute interval after which a new, modified wave of the attack occurred.
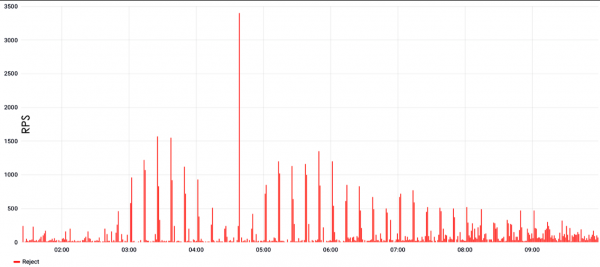
This means that the protection learned, started filtering, but a new, completely different wave of the attack came, and the protection began learning again. In effect, filtering stops working, the protection becomes ineffective, and the website is inaccessible.
Wave attacks are characterized by very high values at their peak, which can reach hundreds of thousands or even a million requests per second in the case of L7. When it comes to L3&4, there can be hundreds of gigabits of traffic, or, accordingly, hundreds of mpps when counted in packets.
The problem with such attacks lies in synchronization. Attacks originate from botnets, and to create a very large one-time peak, a high degree of synchronization is required. This coordination does not always work out: sometimes there ends up being some parabolic peak that looks quite pitiful.
Not by HTTP alone
Besides HTTP at the L7 level, we also like to exploit other protocols. Typically, an ordinary website, especially on standard hosting, exposes email protocols and MySQL. Email protocols are less susceptible to load than databases, but they can also be effectively stressed, resulting in high CPU usage on the server.
We have realistically achieved success using the SSH vulnerability from 2016. Currently, this vulnerability has been patched by almost everyone, but that doesn’t mean that SSH cannot be stressed. It can. An enormous load of authorizations can be submitted, consuming almost all CPU on the server, and then the website collapses under just one or two requests per second. Accordingly, these one or two requests cannot be distinguished from legitimate load in the logs.
Many connections that we open on servers remain relevant. Previously, Apache was prone to this issue, and now nginx essentially suffers from it as well, since it is often configured by default. The number of connections that nginx can keep open is limited, so once we reach that limit, nginx does not accept new connections, resulting in the website becoming unavailable.
Our test cluster has sufficient CPU power to handle SSL handshake attacks. In practice, it seems that botnets sometimes like to do this as well. On one hand, it's clear that SSL is essential because of Google rankings and security. On the other hand, unfortunately, SSL comes with CPU issues.
L3&4
When we talk about attacks at levels L3&4, we are generally referring to attacks at the channel level. Such load is almost always distinguishable from legitimate traffic, unless it’s a SYN-flood attack. The issue with SYN-flood attacks for protective measures lies in their large volume. The maximum size for L3&4 attacks reached 1.5-2 Tbps. Such traffic is incredibly difficult to handle even for large companies like Oracle and Google.
SYN and SYN-ACK are packets used during the establishment of a connection. Therefore, SYN-flood attacks can be hard to distinguish from legitimate load: it is unclear whether the SYN packet is meant for establishing a connection or is part of a flood.
UDP-flood
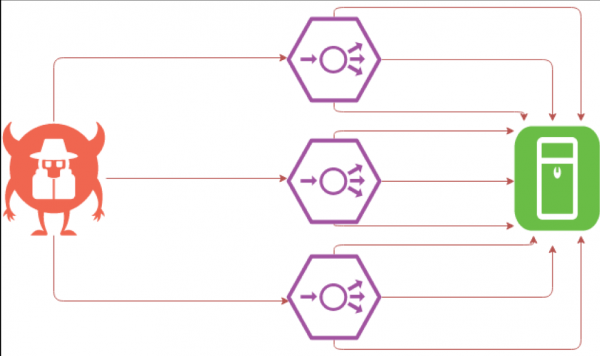
Typically, attackers do not have the same power we have, so amplification is often used to organize attacks. That is, an attacker scans the internet and finds either vulnerable or misconfigured servers that, for example, respond with three SYN-ACK packets to a single SYN packet. By spoofing the source address from the target server's address, one can amplify the traffic, say threefold, and redirect it towards the victim.
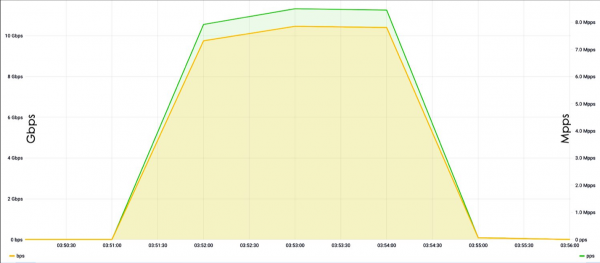
The issue with amplifications is their difficult detection. A recent example would be the notorious case with the vulnerable memcached. Furthermore, there are now many IoT devices and IP cameras, which are mostly configured by default, and unfortunately they are often misconfigured, allowing attackers to execute attacks through these devices more frequently.
Challenging SYN-flood
SYN flood is perhaps the most interesting type of attack from a developer's perspective. The problem is that system administrators often use IP blocking for protection. Unfortunately, this IP blocking affects not only administrators who follow scripts but also, sadly, some security systems that are purchased at great expense.
Such a method can turn into a disaster, as if attackers substitute an IP address, the company will block its own subnet. When the firewall blocks its own cluster, external interactions will fail, and the resource will collapse.
Moreover, it’s not difficult to achieve blocking of one's own network. If there is a Wi-Fi network in the client's office, or if the performance of resources is measured using various monitoring tools, we take the IP address of that monitoring system or the office Wi-Fi client and use it as the source. As a result, the resource appears to be accessible, but the target IP addresses are blocked. Thus, the Wi-Fi network of the HighLoad conference, where the company's new product is presented, can be blocked, leading to certain business and economic losses.
During testing, we cannot utilize amplification via memcached with external resources, as there are agreements for traffic to be directed only to permitted IP addresses. Accordingly, we utilize amplification through SYN and SYN-ACK, where sending one SYN results in two or three SYN-ACK responses, amplifying the attack two to three times.
Tools
One of the main tools we use for load testing at L7 is Yandex-tank. Specifically, a phantom is used as a cannon, along with several scripts for generating bullets and analyzing results.
Tcpdump is used for network traffic analysis, and Nmap is employed for server analysis. To create load at L3&4, we use OpenSSL and a bit of our own magic with the DPDK library. DPDK is an Intel library that allows working with the network interface while bypassing the Linux stack, thereby increasing efficiency. Naturally, we use DPDK not only at L3&4 but also at L7, as it allows for generating very high traffic loads, in the range of several million requests per second from a single machine.
We also use certain traffic generators and special tools that we develop for specific tests. When recalling the SSH vulnerability, it cannot be exploited by the set mentioned above. If we attack the mail protocol, we take mail utilities or simply write scripts for them.
Conclusions
In conclusion, I would like to say:
- In addition to classic load testing, stress testing must also be conducted. We have a real example where a partner's subcontractor only performed load testing. It showed that the resource can handle normal loads. But then, irregular load appeared, and visitors started using the resource differently—resulting in the subcontractor going down. Therefore, even if you are already protected against DDoS attacks, it is still essential to look for vulnerabilities.
- It is necessary to isolate some parts of the system from others. If you have a search function, it should be placed on separate machines, not even in Docker. Because if search or authentication fails, at least something will continue to work. In the case of an online store, users will continue to find products through the catalog, transition from aggregators, and make purchases if they are already logged in or log in via OAuth2.
- Do not neglect various cloud services.
- Use a CDN not only for optimizing network latency but also as a means of protection against channel exhaustion attacks and simple static flooding.
- It is necessary to use specialized protection services. You will not be able to defend yourself against L3&4 attacks at the channel level because you likely do not have a sufficient channel. You will also struggle against L7 attacks, as they can be very large. Furthermore, detecting small attacks remains the prerogative of specialized services and algorithms.
- Regularly update your systems. This applies not only to the core but also to the SSH daemon, especially if they are exposed externally. In principle, you should update everything because it is unlikely you will be able to monitor vulnerabilities on your own.
Source: habr.com
