

Ahead of the launch of a new stream for the course prepared a translation of interesting material.
Overview
We will discuss a fairly popular pattern through which applications utilize multiple data stores, where each store serves its purpose, such as storing canonical data (MySQL, etc.), providing enhanced search capabilities (ElasticSearch, etc.), caching (Memcached, etc.), and others. Typically, in a multi-store setup, one store acts as the primary store while others function as derivative stores. The only challenge lies in synchronizing these data stores.
We examined several different patterns that attempted to address the problem of synchronizing multiple stores, such as dual writes, distributed transactions, etc. However, these approaches have significant limitations regarding real-world usage, reliability, and maintenance. In addition to data synchronization, some applications also need to enrich the data by calling external services.
Delta was developed to address these issues. Ultimately, Delta represents a consistent, event-driven platform for data synchronization and enrichment.
Existing solutions
Dual write
To synchronize two data stores, dual write can be used, which performs a write to one store and then immediately writes to the other. The first write can be retried, while the second can be aborted if the first fails after exhausting attempts. However, the two data stores might become desynchronized if the write to the second store fails. This issue is typically resolved by creating a recovery procedure, which can periodically transfer data from the first store to the second, or only do so if discrepancies in the data are detected.
Challenges:
The process of performing recovery is a specific task that cannot be reused. Moreover, the data between the storage systems remains unsynchronized until the recovery process is completed. The solution becomes more complex when more than two data stores are used. Finally, the recovery process may put a load on the original data source.
Change Log Table
When changes occur in the set of tables (such as inserting, updating, or deleting a record), change records are added to the log table as part of the same transaction. Another thread or process continuously requests events from the log table and writes them to one or more data stores, deleting events from the log table as needed after confirming the record with all data stores.
Challenges:
This pattern should be implemented as a library, ideally without modifying the application code that uses it. In a polyglot environment, such a library should exist in any required language, but ensuring consistent function and behavior across languages is quite challenging.
Another issue lies in capturing schema changes in systems that do not support transactional schema changes [1][2], such as MySQL. Therefore, the pattern for executing changes (e.g., schema changes) and transactional logging of them in the change log table may not always work.
Distributed Transactions
Distributed transactions can be used to split a transaction across multiple heterogeneous data stores in such a way that the operation either commits in all the stores used or does not commit in any of them.
Challenges:
Distributed transactions are a significant challenge for heterogeneous data storage systems. By their nature, they can rely only on the lowest common denominator of the involved systems. For instance, XA transactions block execution if a failure occurs during the prepare phase in the application process. Additionally, XA does not provide deadlock detection and does not support optimistic concurrency control schemes. Furthermore, some systems like ElasticSearch do not support XA or any other heterogeneous transaction model. Thus, ensuring atomicity of writes across various data storage technologies remains a complex task for applications [3].
Delta
Delta was developed to address the limitations of existing data synchronization solutions, and it also enables real-time data enrichment. Our goal was to abstract all these complexities away from application developers so they could fully focus on implementing business functionality. Next, we will describe 'Movie Search,' an actual use case of Delta at Netflix.
Netflix widely employs a microservices architecture, and each microservice typically handles one type of data. Basic movie information is managed by a microservice called Movie Service, while related data, such as information about producers, actors, vendors, and so on, is managed by several other microservices (namely Deal Service, Talent Service, and Vendor Service).
Business users at Netflix Studios often need to search for movies based on various criteria, which is why it is crucial for them to have the ability to search across all data related to films.
Before Delta, the movie search team needed to retrieve data from multiple microservices before indexing movie data. In addition, the team had to develop a system that periodically updated the search index by polling for changes from other microservices, even when there were no changes at all. This system quickly became complex and difficult to maintain.
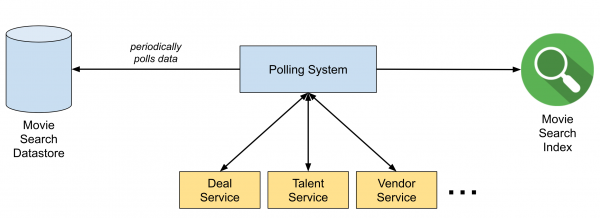
Figure 1. The polling system before Delta
After starting to use Delta, the system was simplified to an event-driven system, as shown in the following diagram. CDC (Change Data Capture) events are sent to Keystone Kafka topics via the Delta Connector. The Delta application, built using the Delta Stream Processing Framework (based on Flink), receives CDC events from the topic, enriches them by calling other microservices, and finally sends the enriched data to the search index in Elasticsearch. The entire process occurs almost in real-time, meaning that as soon as changes are recorded in the data warehouse, the search indices are updated.
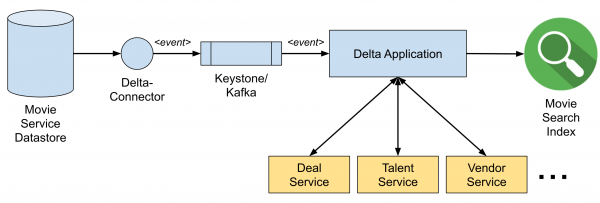
Figure 2. Data pipeline when using Delta
In the following sections, we will describe the operation of the Delta Connector, which connects to the warehouse and publishes CDC events at the transport level, which serves as the real-time data transmission infrastructure directing CDC events to Kafka topics. Finally, we will discuss the structure of Delta stream processing, which application developers can use for data processing and enrichment logic.
CDC (Change Data Capture)
We developed a CDC service called Delta Connector, which can capture committed changes from the data warehouse in real-time and write them to a stream. Real-time changes are fetched from the transaction log and warehouse dumps. Dumps are used because transaction logs typically do not store the entire history of changes. Changes are usually serialized as Delta events, so the recipient does not need to worry about the source of the change.
Delta Connector supports several additional features, such as:
- The ability to write to custom output streams bypassing Kafka.
- The capability to trigger manual dumps at any time for all tables, a specific table, or for certain primary keys.
- Dumps can be taken in chunks, so there is no need to start over in case of a failure.
- There is no need to place locks on tables, which is very important to ensure that write traffic to the database is never blocked by our service.
- High availability due to backup instances in AWS Availability Zones.
Currently, we support MySQL and Postgres, including deployment in AWS RDS and Aurora. We also support Cassandra (multi-master). You can find more details about Delta-Connector in this .
Kafka and transport layer
The Delta event transport layer is built on the messaging service of the platform .
Historically, message publishing in Netflix has been optimized for availability rather than durability (see ). The compromise has resulted in potential data inconsistency across various edge scenarios. For example, unclean leader election is responsible for the possibility that the recipient may duplicate or lose events.
With Delta, we aimed to achieve stronger durability assurances to ensure the delivery of CDC events to downstream storage. To do this, we proposed a specially designed Kafka cluster as a first-class object. You can see some broker settings in the table below:
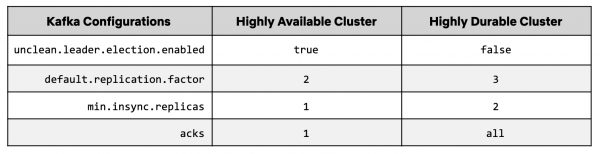
In Keystone Kafka clusters, unclean leader election is typically enabled to ensure publisher availability. This may lead to message loss if an unsynchronized replica is chosen as the leader. For the new highly reliable Kafka cluster, the unclean leader election is disabled to prevent message loss.
We have also increased replication factor from 2 to 3 and minimum insync replicas from 1 to 2. Publishers writing to this cluster require acks from all others, ensuring that 2 out of 3 replicas will have the most recent messages sent by the publisher.
When a broker instance shuts down, a new instance replaces the old one. However, the new broker will need to catch up on unsynchronized replicas, which can take several hours. To reduce the recovery time for this scenario, we started using block storage (Amazon Elastic Block Store) instead of local disks for brokers. When the new instance replaces the terminated broker instance, it attaches the EBS volume that was associated with the terminated instance and begins catching up on new messages. This process reduces the backlog elimination time from several hours to several minutes, as the new instance no longer needs to replicate from a cold state. Overall, separate storage and broker lifecycles significantly lessen the impact of the broker switch effect.
To further increase the data delivery guarantee, we utilized to detect any message loss under extreme circumstances (e.g., clock desynchronization in the partition leader).
Stream Processing Framework
The processing layer in Delta is built on the Netflix SPaaS platform, which integrates Apache Flink with the Netflix ecosystem. The platform provides a user interface that manages the deployment of Flink jobs and orchestrates Flink clusters on top of our container management platform, Titus. The interface also handles job configurations and allows users to make dynamic changes to the configuration without the need to recompile Flink jobs.
Delta provides a data stream processing framework based on Flink and SPaaS, which uses annotation-based DSL (Domain Specific Language) to abstract technical details. For instance, to define the step to enrich events by invoking external services, users need to write the following DSL, and the framework will create a model based on it that will execute in Flink.
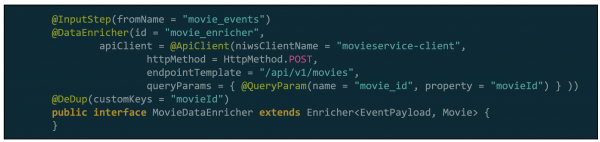
Figure 3. Example of enrichment in DSL in Delta
The processing framework not only shortens the learning curve but also provides common stream processing features such as deduplication, schematization, as well as flexibility and resilience to tackle common operational issues.
The Delta Stream Processing Framework consists of two key modules: the DSL & API module and the Runtime module. The DSL & API module provides a DSL and UDF (User-Defined Function) API allowing users to write their own processing logic (such as filtering or transformations). The Runtime module provides the implementation of the DSL parser, which builds an internal representation of processing steps in DAG models. The Execution component interprets the DAG models to initialize the actual Flink operators and ultimately launch the Flink application. The architecture of the framework is illustrated in the following figure.
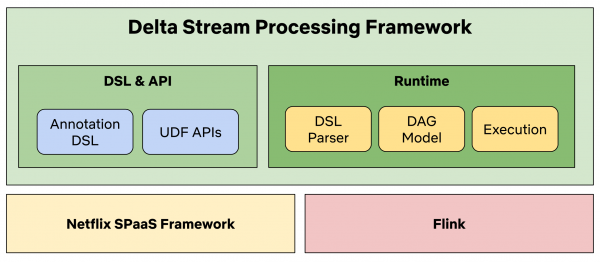
Figure 4. Architecture of the Delta Stream Processing Framework
This approach has several advantages:
- Users can focus on their business logic without needing to delve into Flink specifics or SPaaS structure.
- Optimization can be done in a way that is transparent to users, and errors can be corrected without the need to make any changes to the user code (UDF).
- The operation of Delta applications is simplified for users, as the platform provides out-of-the-box flexibility and fault tolerance, and collects a wealth of detailed metrics that can be used for alerts.
Production Use
Delta has been in production for over a year and plays a key role in many Netflix Studio applications. It has helped teams implement use cases such as search indexing, data storage, and event-driven workflows. Below is an overview of the high-level architecture of the Delta platform.
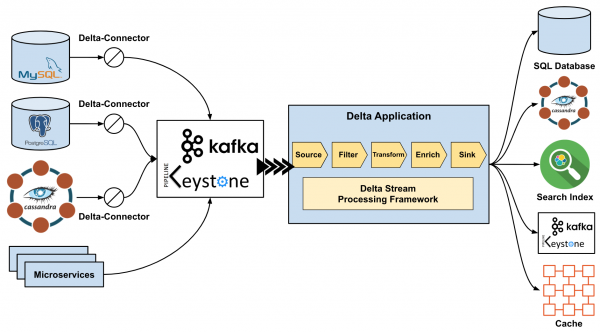
Figure 5. High-Level Architecture of Delta.
Acknowledgments
We would like to thank the following individuals who contributed to the creation and development of Delta at Netflix: Allen Wang, Charles Zhao, Jaebin Yoon, Josh Snyder, Kasturi Chatterjee, Mark Cho, Olof Johansson, Piyush Goyal, Prashanth Ramdas, Raghuram Onti Srinivasan, Sandeep Gupta, Steven Wu, Tharanga Gamaethige, Yun Wang, and Zhenzhong Xu.
file — continuous reading of events from one or more local files;
- Martin Kleppmann, Alastair R. Beresford, Boerge Svingen: Online event processing. Commun. ACM 62(5): 43–49 (2019). DOI:
: "Data Build Tool for Amazon Redshift data warehouse."
Source: habr.com
