

Last week, I attended the IT conference DUMP (https://dump-ekb.ru/) in Yekaterinburg and I want to share what was discussed in the Backend and DevOps sections, and whether regional IT conferences are worth attending.
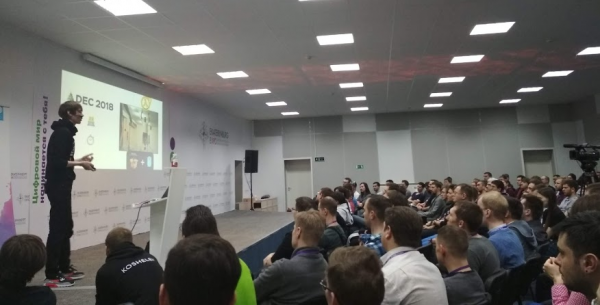
Nikolai Sverchkov from Evil Martians on Serverless
What was it all about?
There were a total of 8 sections at the conference: Backend, Frontend, Mobile, Testing and QA, DevOps, Design, Science, and Management.
Interestingly, the largest halls were for Science and Management, each accommodating around 350 people. Backend and Frontend were only slightly smaller. The DevOps hall was the smallest, but very active.
I attended talks in the DevOps and Backend sections and had some discussions with the speakers. I want to cover the topics that were discussed and provide an overview of these sections at the conference.
In the DevOps and Backend sections, representatives from SKB Kontur, DataArt, Evil Martians, the Yekaterinburg web studio Flag, and Miro (RealTimeBoard) spoke. The topics included CI/CD, working with queue services, logging, and the themes of Serverless and working with PostgreSQL in Go were well covered.
There were also talks from Avito, Tinkoff, Yandex, Jetstyle, MegaFon, and Ak Bars Bank, but I did not manage to physically attend them (video recordings and slides of the talks are not yet available; they promise to release them within 2 weeks on dump-ekb.ru).
DevOps section
What surprised me was that the section was held in the smallest hall, seating about 50 people. People were even standing in the aisles 🙂 I will discuss the talks I managed to catch.
Elastic weighing in at a petabyte
The section started with a presentation by Vladimir Lila (SKB Kontur) about Elasticsearch at Kontur. They have a fairly large and heavily loaded Elastic (~800 TB of data, ~1.3 petabytes considering redundancy). Elasticsearch is unified for all services of Kontur, consisting of 2 clusters (of 7 and 9 servers), and is so important that there is a dedicated Elasticsearch engineer at Kontur (Vladimir himself).
Vladimir also shared his thoughts on the benefits of Elasticsearch and the problems it brings.
Benefits:
- All logs in one place, easy access to them
- Storing logs for a year and easy analysis
- High speed of working with logs
- Great data visualization 'out of the box'
Challenges:
- Message broker — a must-have (Kafka serves this role at Kontur)
- Features of working with Elasticsearch Curator (periodically generated high load from regular tasks in Curator)
- no built-in authorization (only available for a substantial fee, or as open-source plugins of varying levels of readiness for production)
Feedback on Open Distro for Elasticsearch has been overwhelmingly positive 🙂 The same authorization issue has been resolved there.
Where does the petabyte come from?Their nodes consist of servers with 12*8 Tb SATA + 2*2 Tb SSD. Cold storage on SATA, SSD only for hot cache.
7+9 servers, (7 + 9) * 12 * 8 = 1536 Tb.
Some space is reserved for redundancy and such.
Logs from about 90 applications are sent to Elasticsearch, including all reporting services from Kontur, Elba, and others.
Characteristics of development on Serverless
Next is a presentation by Ruslan Serkin from DataArt on Serverless.
Ruslan explained what development with the Serverless approach is all about and what its features are.
Serverless is an approach to development where developers do not interact with the infrastructure in any way. An example is AWS Lambda Serverless, Kubeless.io (Serverless within Kubernetes), Google Cloud Functions.
An ideal Serverless application is simply a function that sends a request to the Serverless provider through a special API Gateway. An ideal microservice, with AWS Lambda supporting many modern programming languages. The cost of maintaining and deploying infrastructure becomes zero in the case of cloud providers, and supporting small applications will also be very inexpensive (AWS Lambda — $0.2 / 1 million simple requests).
The scalability of such a system is practically perfect — the cloud provider takes care of it, Kubeless scales automatically within the Kubernetes cluster.
There are disadvantages:
- developing large applications becomes more complex
- there's difficulty with profiling applications (you only have access to logs, not profiling in the traditional sense)
- no versioning
I'll be honest, I heard about Serverless several years ago, but all these years I couldn't understand how to apply it correctly. After Ruslan's presentation, I gained clarity, and after the talk by Nikolai Sverkhov (Evil Martians) from the Backend section, it solidified. It was worth attending the conference 🙂
CI for the poor, or is it worth writing your CI for a web studio?
Mikhail Radionov, head of the Flag web studio from Yekaterinburg, spoke about a custom CI/CD.
His studio has transitioned from 'manual CI/CD' (logging into the server via SSH, doing git pull, repeating 100 times a day) to Jenkins and to a custom tool called Pullkins, which allows for code control and release execution.
Why wasn't Jenkins suitable? It didn't provide enough flexibility by default and was too complex for customization.
The 'Flag' team is developing on Laravel (PHP framework). While building the CI/CD server, Mikhail and his colleagues leveraged Laravel's built-in mechanisms called Telescope and Envoy. As a result, they created a PHP server (note) that processes incoming webhook requests, builds the frontend and backend, deploys to different servers, and reports to Slack.
Next, to enable blue/green deployment and maintain uniform settings in dev-stage-prod environments, they transitioned to Docker. The advantages remained the same, but they added capabilities for environment homogenization and seamless deployment, as well as the need to learn Docker for effective interaction.
How we reduced the number of server release rollbacks by 99%
The last presentation in the DevOps section was by Viktor Yermchenko, Lead DevOps Engineer at Miro.com (formerly RealTimeBoard).
At the core of RealTimeBoard, Miro's main product, is a monolithic Java application. Building, testing, and deploying it without downtime is a complex task. It’s crucial to deploy a version of the code that doesn’t require rollback (it's a heavy monolith).
In their journey to establish a system that allows for this, Miro underwent a process that included working on architecture, the tools used (Atlassian Bamboo, Ansible, etc.), and team structure (they currently have a dedicated DevOps team plus several separate Scrum teams made up of developers from various backgrounds).
The path proved to be difficult and thorny, and Viktor shared the accumulated pain and enduring optimism.
Won a book for questions
Backend section
I made it to two presentations — one by Nikolai Sverchkov (Evil Martians) also about Serverless, and another by Grigoriy Koshelev (Kontur) on telemetry.
Serverless for ordinary mortals
While Ruslan Siriikin spoke about what Serverless is, Nikolai showcased simple applications using Serverless and discussed details that affect cost and application performance in AWS Lambda.
An interesting detail: the minimum billable element is 128 MB of memory and 100 ms of CPU, costing $0.000000208. At the same time, 1 million such requests per month are free.
Some functions for Nikolai often exceeded the limit of 100 ms (the main application was written in Ruby), so rewriting them in Go resulted in significant savings.
Vostok Hercules — make telemetry great again!
The latest report from the Backend section by Grigory Koshelev (Kontur) on telemetry. Telemetry consists of logs, metrics, and application traces.
Kontur uses custom-built tools shared on Github. The tool mentioned in the report — Hercules, , is used for delivering telemetry data.
In Vladimir Lily's report in the DevOps section, the storage and processing of logs in Elasticsearch were discussed, but there is also the task of delivering logs from thousands of devices and applications, which is tackled by tools like Vostok Hercules.
Kontur has taken the well-known path from RabbitMQ to Apache Kafka, but it wasn't that simple. They had to add Zookeeper, Cassandra, and Graphite to the scheme. I won't fully disclose the details of this report (it's not my expertise), but if you're interested, you can wait for the slides and video on the conference website.
How does it compare to other conferences?
I can't compare it to conferences in Moscow and St. Petersburg, but I can compare it to other events in the Urals and 404fest in Samara.
DUMP is held in 8 sections, setting a record for Ural conferences. The Science and Management sections are particularly large, which is also unusual. The audience in Yekaterinburg is quite structured — the city has large development departments from Yandex, Kontur, and Tinkoff, which influences the presentations.
Another interesting point is that many companies have 3-4 speakers at the conference (this was the case for Kontur, Evil Martians, and Tinkoff). Many of them were sponsors, but their presentations were on par with others, and not just promotional talks.
Should you go or not? If you live in the Urals or nearby, have the opportunity, and are interested in the topics — yes, definitely. If you're considering a longer trip — I would look at the topics of the presentations and videos from previous years. and make a decision.
Another plus of regional conferences is that it's generally easy to chat with the speaker after the presentations, simply because there are fewer candidates for such interaction.
Thank you to DUMP and Yekaterinburg! )
Source: habr.com
