

Hello everyone. We are developing a product for analyzing offline traffic. The project includes a task related to the statistical analysis of visitor pathways across areas.
Within this task, users can issue the system queries of the following types:
- how many visitors passed from area "A" to area "B";
- how many visitors passed from area "A" to area "B" through area "C", and then through area "D";
- how long it took for a certain type of visitor to travel from area "A" to area "B."
and a number of similar analytical queries.
Visitor movement across areas can be represented as a directed graph. After researching online, I found that graph databases are also used for analytical reports. I became interested to see how graph databases would handle such queries (TL;DR; poorly).
I chose to use the database system , as an outstanding representative of graph open-source databases, which relies on a stack of mature technologies that (in my opinion) should provide decent operational characteristics:
- BerkeleyDB, Apache Cassandra, Scylla as the storage backend;
- complex indexes can be stored in Lucene, Elasticsearch, Solr.
The authors of JanusGraph state that it is suitable for both OLTP and OLAP.
I have worked with BerkeleyDB, Apache Cassandra, Scylla, and ES; moreover, these products are often used in our systems, so I looked forward to testing this graph database with optimism. I found it strange to choose BerkeleyDB over RocksDB, but perhaps this is related to transaction requirements. In any case, for scalable, production use, it is suggested to use a backend on Cassandra or Scylla.
I did not consider Neo4j since a commercial version is required for clustering, meaning the product is not open source.
Graph databases say: "If something looks like a graph — treat it like a graph!" — beautiful!
First, I drew a graph that was done strictly according to the canons of graph databases:
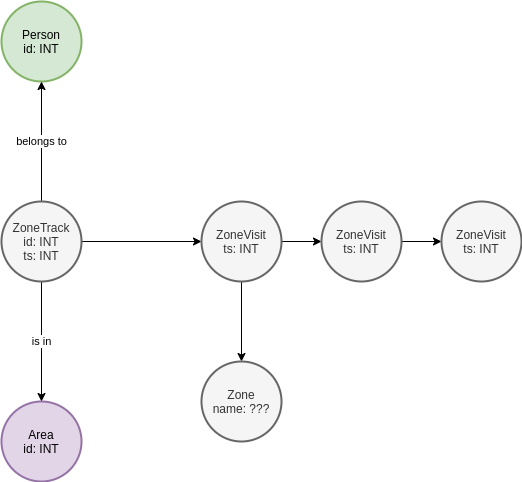
There is an entity Zone, responsible for the area. If ZoneStep belongs to this Zone, then it references it. Do not pay attention to the entities Area, ZoneTrack, Person , they belong to the domain and are not considered in this test. Therefore, for such a graph structure, a query to find chains would look like this:
g.V().hasLabel('Zone').has('id',0).in_()
       .repeat(__.out()).until(__.out().hasLabel('Zone').has('id',19)).count().next()
What this means in English is: find Zone with ID=0, take all vertices from which an edge (ZoneStep) goes to it, traverse without going back until you find such ZoneStep from which an edge goes to Zone with ID=19, count the number of such chains.
I do not claim to know all the intricacies of graph searches, but this query was generated based on this book ().
I uploaded 50,000 tracks ranging from 3 to 20 points into the JanusGraph database, which uses a BerkeleyDB backend, and created indexes according to .
The script for loading in Python:
from random import random
from time import time

from init import g, graph

if __name__ == '__main__':

    points = []
    max_zones = 19
    zcache = dict()
    for i in range(0, max_zones + 1):
        zcache[i] = g.addV('Zone').property('id', i).next()

    startZ = zcache[0]
    endZ = zcache[max_zones]

    for i in range(0, 10000):

        if not i % 100:
            print(i)

        start = g.addV('ZoneStep').property('time', int(time())).next()
        g.V(start).addE('belongs').to(startZ).iterate()

        while True:
            pt = g.addV('ZoneStep').property('time', int(time())).next()
            end_chain = random()
            if end_chain < 0.3:
                g.V(pt).addE('belongs').to(endZ).iterate()
                g.V(start).addE('goes').to(pt).iterate()
                break
            else:
                zone_id = int(random() * max_zones)
                g.V(pt).addE('belongs').to(zcache[zone_id]).iterate()
                g.V(start).addE('goes').to(pt).iterate()

            start = pt

    count = g.V().count().next()
    print(count)
A VM with 4 cores and 16 GB of RAM on SSD was used. JanusGraph was deployed with the following command:
docker run --name janusgraph -p8182:8182 janusgraph/janusgraph:latestIn this case, the data and indexes used for exact match searches are stored in BerkeleyDB. After executing the previously mentioned query, I obtained a time equal to several dozen seconds.
Running the 4 aforementioned scripts in parallel, I managed to turn the DBMS into a pumpkin with a cheerful stream of Java stack traces (and we all love reading Java stack traces) in the Docker logs.
Upon reflection, I decided to simplify the graph schema to the following:
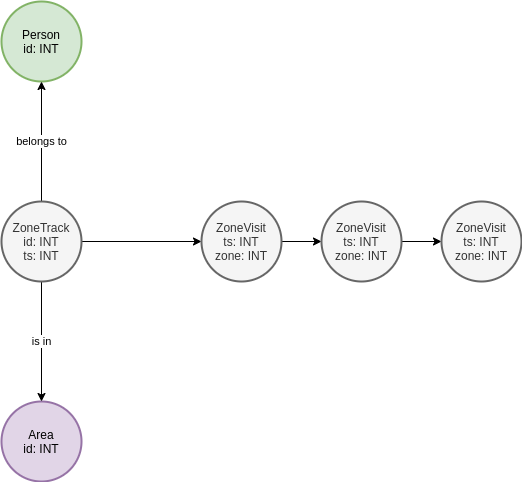
Deciding that searching by entity attributes would be faster than searching by edges. As a result, my query transformed into the following:
g.V().hasLabel('ZoneStep').has('id',0).repeat(__.out().simplePath()).until(__.hasLabel('ZoneStep').has('id',19)).count().next()What this means in English is: find ZoneStep with ID=0, traverse without going back until you find ZoneStep with ID=19, count the number of such chains.
I also simplified the loading script mentioned above, in order to avoid creating unnecessary connections, limiting myself to attributes.
The query was still executing for several seconds, which was completely unacceptable for our task, as it was not suitable for AdHoc queries of arbitrary types.
I tried deploying JanusGraph using Scylla as the fastest implementation of Cassandra, but it didn't lead to any significant performance changes either.
Thus, despite it looking like a graph, I couldn't make the graph database process it quickly. I assume that I'm missing something and JanusGraph can perform this search in fractions of a second, but I couldn't manage it.
Since the task still needed to be solved, I started thinking about JOINs and table Pivots, which did not inspire optimism in terms of elegance, but could be a workable option in practice.
Our project is already using Apache ClickHouse, so I decided to test my findings on this analytical DBMS.
I deployed ClickHouse with a simple recipe:
sudo docker run -d --name clickhouse_1
     --ulimit nofile=262144:262144
     -v /opt/clickhouse/log:/var/log/clickhouse-server
     -v /opt/clickhouse/data:/var/lib/clickhouse
     yandex/clickhouse-server
I created a database and table like this:
CREATE TABLE
db.steps (`area` Int64, `when` DateTime64(1, 'Europe/Moscow') DEFAULT now64(), `zone` Int64, `person` Int64)
ENGINE = MergeTree() ORDER BY (area, zone, person) SETTINGS index_granularity = 8192
I populated it with data using the following script:
from time import time

from clickhouse_driver import Client
from random import random

client = Client('vm-12c2c34c-df68-4a98-b1e5-a4d1cef1acff.domain',
                database='db',
                password='secret')

max = 20

for r in range(0, 100000):

    if r % 1000 == 0:
        print("CNT: {}, TS: {}".format(r, time()))

    data = [{
            'area': 0,
            'zone': 0,
            'person': r
        }]

    while True:
        if random() < 0.3:
            break

        data.append({
                'area': 0,
                'zone': int(random() * (max - 2)) + 1,
                'person': r
            })

    data.append({
            'area': 0,
            'zone': max - 1,
            'person': r
        })

    client.execute(
        'INSERT INTO steps (area, zone, person) VALUES',
        data
    )
Since inserts are done in batches, the filling was much faster than for JanusGraph.
I constructed two queries using JOIN. To transition from point A to point B:
SELECT s1.person AS person,
       s1.zone,
       s1.when,
       s2.zone,
       s2.when
FROM
  (SELECT *
   FROM steps
   WHERE (area = 0)
     AND (zone = 0)) AS s1 ANY INNER JOIN
  (SELECT *
   FROM steps AS s2
   WHERE (area = 0)
     AND (zone = 19)) AS s2 USING person
WHERE s1.when <= s2.when
For transitioning through 3 points:
SELECT s3.person,
       s1z,
       s1w,
       s2z,
       s2w,
       s3.zone,
       s3.when
FROM
  (SELECT s1.person AS person,
          s1.zone AS s1z,
          s1.when AS s1w,
          s2.zone AS s2z,
          s2.when AS s2w
   FROM
     (SELECT *
      FROM steps
      WHERE (area = 0)
        AND (zone = 0)) AS s1 ANY INNER JOIN
     (SELECT *
      FROM steps AS s2
      WHERE (area = 0)
        AND (zone = 3)) AS s2 USING person
   WHERE s1.when <= s2.when) p ANY INNER JOIN
  (SELECT *
   FROM steps
   WHERE (area = 0)
     AND (zone = 19)) AS s3 USING person
WHERE p.s2w <= s3.when
Queries certainly look quite intimidating; a programming wrapper-generator is needed for real use. However, they work and do so quickly. Both the first and second queries execute in less than 0.1 seconds. Here’s an example execution time for the count(*) across 3 points:
SELECT count(*)
FROM
(
    SELECT
        s1.person AS person,
        s1.zone AS s1z,
        s1.when AS s1w,
        s2.zone AS s2z,
        s2.when AS s2w
    FROM
    (
        SELECT *
        FROM steps
        WHERE (area = 0) AND (zone = 0)
    ) AS s1
    ANY INNER JOIN
    (
        SELECT *
        FROM steps AS s2
        WHERE (area = 0) AND (zone = 3)
    ) AS s2 USING (person)
    WHERE s1.when <= s2.when
) AS p
ANY INNER JOIN
(
    SELECT *
    FROM steps
    WHERE (area = 0) AND (zone = 19)
) AS s3 USING (person)
WHERE p.s2w <= s3.when

┌─count()─┐
│   11592 │
└─────────┘
1 rows in set. Elapsed: 0.068 sec. Processed 250.03 thousand rows, 8.00 MB (3.69 million rows/s., 117.98 MB/s.)Note on IOPS. While filling in the data, JanusGraph generated a fairly high amount of IOPS (1000-1300 for four data fill threads), and IOWAIT was quite high. At the same time, ClickHouse generated minimal load on the disk subsystem.
Conclusion
We decided to use ClickHouse for servicing requests of this type. We can always further optimize queries using materialized views and parallelization, performing preliminary event stream processing with Apache Flink before loading them into ClickHouse.
The performance is so good that we probably won’t even have to consider table pivots programmatically. Previously, we had to create data pivots extracted from Vertica through export to Apache Parquet.
Unfortunately, yet another attempt to use a graph DBMS was unsuccessful. I found that JanusGraph does not have a friendly ecosystem that allows for quick familiarity with the product. Moreover, the server configuration employs the traditional Java-way, which will make those unfamiliar with Java weep blood tears:
host: 0.0.0.0
port: 8182
threadPoolWorker: 1
gremlinPool: 8
scriptEvaluationTimeout: 30000
channelizer: org.janusgraph.channelizers.JanusGraphWsAndHttpChannelizer

graphManager: org.janusgraph.graphdb.management.JanusGraphManager
graphs: {
  ConfigurationManagementGraph: conf/janusgraph-cql-configurationgraph.properties,
  airlines: conf/airlines.properties
}

scriptEngines: {
  gremlin-groovy: {
    plugins: { org.janusgraph.graphdb.tinkerpop.plugin.JanusGraphGremlinPlugin: {},
               org.apache.tinkerpop.gremlin.server.jsr223.GremlinServerGremlinPlugin: {},
               org.apache.tinkerpop.gremlin.tinkergraph.jsr223.TinkerGraphGremlinPlugin: {},
               org.apache.tinkerpop.gremlin.jsr223.ImportGremlinPlugin: {classImports: [java.lang.Math], methodImports: [java.lang.Math#*]},
               org.apache.tinkerpop.gremlin.jsr223.ScriptFileGremlinPlugin: {files: [scripts/airline-sample.groovy]}}}}

serializers:
# GraphBinary is here to replace Gryo and Graphson
  - { className: org.apache.tinkerpop.gremlin.driver.ser.GraphBinaryMessageSerializerV1, config: { ioRegistries: [org.janusgraph.graphdb.tinkerpop.JanusGraphIoRegistry] }}
  - { className: org.apache.tinkerpop.gremlin.driver.ser.GraphBinaryMessageSerializerV1, config: { serializeResultToString: true }}
  # Gryo and Graphson, latest versions
  - { className: org.apache.tinkerpop.gremlin.driver.ser.GryoMessageSerializerV3d0, config: { ioRegistries: [org.janusgraph.graphdb.tinkerpop.JanusGraphIoRegistry] }}
  - { className: org.apache.tinkerpop.gremlin.driver.ser.GryoMessageSerializerV3d0, config: { serializeResultToString: true }}
  - { className: org.apache.tinkerpop.gremlin.driver.ser.GraphSONMessageSerializerV3d0, config: { ioRegistries: [org.janusgraph.graphdb.tinkerpop.JanusGraphIoRegistry] }}
  # Older serialization versions for backwards compatibility:
  - { className: org.apache.tinkerpop.gremlin.driver.ser.GryoMessageSerializerV1d0, config: { ioRegistries: [org.janusgraph.graphdb.tinkerpop.JanusGraphIoRegistry] }}
  - { className: org.apache.tinkerpop.gremlin.driver.ser.GryoMessageSerializerV1d0, config: { serializeResultToString: true }}
  - { className: org.apache.tinkerpop.gremlin.driver.ser.GryoLiteMessageSerializerV1d0, config: {ioRegistries: [org.janusgraph.graphdb.tinkerpop.JanusGraphIoRegistry] }}
  - { className: org.apache.tinkerpop.gremlin.driver.ser.GraphSONMessageSerializerGremlinV2d0, config: { ioRegistries: [org.janusgraph.graphdb.tinkerpop.JanusGraphIoRegistry] }}
  - { className: org.apache.tinkerpop.gremlin.driver.ser.GraphSONMessageSerializerGremlinV1d0, config: { ioRegistries: [org.janusgraph.graphdb.tinkerpop.JanusGraphIoRegistryV1d0] }}
  - { className: org.apache.tinkerpop.gremlin.driver.ser.GraphSONMessageSerializerV1d0, config: { ioRegistries: [org.janusgraph.graphdb.tinkerpop.JanusGraphIoRegistryV1d0] }}

processors:
  - { className: org.apache.tinkerpop.gremlin.server.op.session.SessionOpProcessor, config: { sessionTimeout: 28800000 }}
  - { className: org.apache.tinkerpop.gremlin.server.op.traversal.TraversalOpProcessor, config: { cacheExpirationTime: 600000, cacheMaxSize: 1000 }}

metrics: {
  consoleReporter: {enabled: false, interval: 180000},
  csvReporter: {enabled: false, interval: 180000, fileName: /tmp/gremlin-server-metrics.csv},
  jmxReporter: {enabled: false},
  slf4jReporter: {enabled: true, interval: 180000},
  gangliaReporter: {enabled: false, interval: 180000, addressingMode: MULTICAST},
  graphiteReporter: {enabled: false, interval: 180000}}
threadPoolBoss: 1
maxInitialLineLength: 4096
maxHeaderSize: 8192
maxChunkSize: 8192
maxContentLength: 65536
maxAccumulationBufferComponents: 1024
resultIterationBatchSize: 64
writeBufferHighWaterMark: 32768
writeBufferHighWaterMark: 65536
ssl: {
  enabled: false}
I accidentally managed to "put" BerkeleyDB version JanusGraph.
The documentation is quite convoluted regarding indexes, since managing them requires performing some peculiar operations in Groovy. For instance, creating an index must be done by writing code in the Gremlin console (which, by the way, does not work out of the box). From the official JanusGraph documentation:
graph.tx().rollback() //Never create new indexes while a transaction is active
mgmt = graph.openManagement()
name = mgmt.getPropertyKey('name')
age = mgmt.getPropertyKey('age')
mgmt.buildIndex('byNameComposite', Vertex.class).addKey(name).buildCompositeIndex()
mgmt.buildIndex('byNameAndAgeComposite', Vertex.class).addKey(name).addKey(age).buildCompositeIndex()
mgmt.commit()

//Wait for the index to become available
ManagementSystem.awaitGraphIndexStatus(graph, 'byNameComposite').call()
ManagementSystem.awaitGraphIndexStatus(graph, 'byNameAndAgeComposite').call()
//Reindex the existing data
mgmt = graph.openManagement()
mgmt.updateIndex(mgmt.getGraphIndex("byNameComposite"), SchemaAction.REINDEX).get()
mgmt.updateIndex(mgmt.getGraphIndex("byNameAndAgeComposite"), SchemaAction.REINDEX).get()
mgmt.commit()
Afterword
In some sense, the experiment mentioned above is a comparison of apples to oranges. Upon reflection, the graph DB performs different operations to achieve the same results. However, during the tests, I also conducted an experiment with a query like:
g.V().hasLabel('ZoneStep').has('id',0)
    .repeat(__.out().simplePath()).until(__.hasLabel('ZoneStep').has('id',1)).count().next()
which reflects step accessibility. However, even with such data, the graph DB yielded results that exceeded a few seconds... This is certainly related to the existence of paths like 0 -> X -> Y ... -> 1, which the graph engine was also checking.
Even for a query like:
g.V().hasLabel('ZoneStep').has('id',0).out().has('id',1)).count().next()I was unable to obtain a performant response with processing times under a second.
The moral of the story is that a beautiful idea and paradigmatic modeling do not lead to the desired result, which is shown with significantly higher efficiency in the case of ClickHouse. The use case presented in this article is a clear anti-pattern for graph DBs, even though it appears suitable for modeling within their paradigm.
Source: habr.com
