

There are many backup systems, but what should we do if the servers being serviced are scattered across different regions and clients and we need to rely on the operating system's assets?
Good afternoon, Habr!
My name is Natalia. I am the team lead of the application administrators group at NPO 'Krista'. We are the Ops for our company's project group. We have quite a unique situation: we install and maintain our software both on our company's servers and on servers located at clients' sites. In this case, there is no need to back up the entire server. Only 'essential data' is important: the DBMS and specific directories of the file system. Of course, clients have (or do not have) their own backup regulations and often provide some external storage for placing backups. In this case, after creating a backup, we ensure that it is sent to external storage.
For some time, we relied on a bash script for backup purposes, but as the variety of settings grew, so did the complexity of this script, and at one fine moment, we came to the necessity of 'tearing it down to the ground, and then....'.
Ready-made solutions did not fit for various reasons: due to the need to decentralize backups, the necessity of storing backups locally at the client, setup complexity, import substitution, and access restrictions.
We thought it would be easier to write something of our own. At the same time, we wanted to create something sufficient for our situation for the next N years, but with the potential for expanding its scope.
The conditions of the task were as follows:
- the base backup instance is autonomous, works locally
- storage of backups and logs is always within the client's network
- the instance consists of modules – a kind of 'constructor'
- compatibility with the used Linux distributions, including outdated ones, with potential cross-platform capabilities is desirable
- only ssh access is required to work with the instance; opening additional ports is not necessary
- maximum simplicity of setup and operation
- the existence of a separate instance that allows centralized monitoring of backup states across different servers is possible (but not mandatory)
What we have achieved can be seen here:
The software is written in Python 3 and works on Debian, Ubuntu, CentOS, and AstraLinux 1.6.
The documentation is available in the docs directory of the repository.
Key concepts used by the system:
action – An operation that performs a single atomic operation (e.g., database backup, directory backup, moving from directory A to directory B, etc.). Existing actions are located in the core/actions directory.
task – A job that is a collection of actions describing a single logical "backup task".
schedule – A schedule consisting of a set of tasks with optional specification of when the task should be executed.
Backup configuration is stored in a YAML file; the overall structure of the config:
- common settings
- section actions: description of actions used on this server
- section schedule: description of all tasks (sets of actions) and their cron schedule, if such scheduling is required
Current capabilities of the application:
- Core operations supported include: PostgreSQL backup via pg_dump, backup of the file system directory via tar; operations with external storage; rsync between directories; backup rotation (removal of old copies)
- calling an external script
- manually executing a specific task
/opt/KristaBackup/KristaBackup.py run make_full_dump - You can add (or remove) a specific task or the entire schedule in the crontab
/opt/KristaBackup/KristaBackup.py enable all - generation of a trigger file based on backup results. This feature is useful in conjunction with Zabbix for monitoring backups
- can operate in the background in webapi or web mode
/opt/KristaBackup/KristaBackup.py web start [--api]
The difference between modes: In webapi, there is no actual web interface, but the application responds to requests from another instance. The web mode requires installation of Flask and several additional packages, which may not be acceptable everywhere, for example, in certified AstraLinux SE.
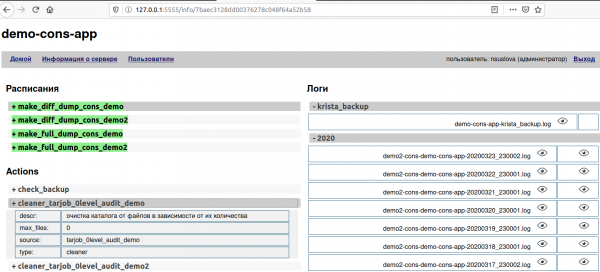
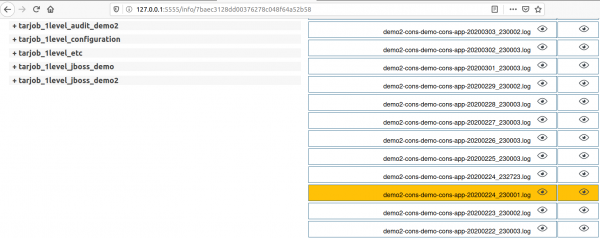
Through the web interface, you can view the status and logs of backups from connected servers: the 'web instance' requests data from the 'backup instances' via API. Access to the web requires authentication; access to webapi does not.
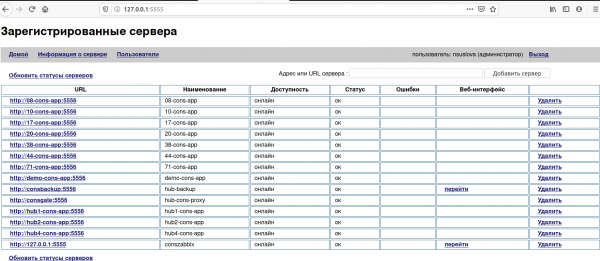
Logs of improperly completed backups are marked by color: warning – yellow, error – red.
If the administrator does not need a cheat sheet for parameters and the server operating systems are homogeneous, a file can be compiled and a ready package can be distributed.
We mainly distribute this utility through Ansible, initially deploying it to a few less critical servers, and after testing, rolling it out to all others.
In the end, we have created a compact standalone copying utility that can be automated and is suitable for use even by less experienced administrators. It's convenient for us - perhaps it will be useful for you too?
Source: habr.com
