

The command offers Engineer Rahul Bhatia from Clairvoyant discusses the various file formats in big data, the most common functions of Hadoop formats, and the best format to use.
Why Different File Formats Are Necessary
A serious bottleneck in the performance of applications supporting HDFS, such as MapReduce and Spark, is the time it takes to find, read, and write data. These issues are exacerbated by the challenges of managing large datasets when we have an evolving schema or face certain storage limitations.
Processing big data increases the load on the storage subsystem—Hadoop stores data redundantly for fault tolerance. Besides disks, the CPU, network, input/output system, and so forth are also taxed. As the volume of data grows, so too does the cost of processing and storage.
Different file formats in are designed to address these very issues. Choosing the right file format can offer significant advantages:
- Faster read times.
- Faster write times.
- Shareable files.
- Support for schema evolution.
- Enhanced compression support.
Some file formats are intended for general use, others for more specific cases, and some are developed with specific data characteristics in mind. Thus, the choice is quite extensive.
The Avro File Format
For of data serialization is widely used. Avro is a row-baseddata storage format in Hadoop. It stores the schema in JSON format, making it easier to read and interpret by any program. The data itself is stored in a binary format, compactly and efficiently.
The Avro serialization system is language-neutral. Files can be processed in multiple languages, currently including C, C++, C#, Java, Python, and Ruby.
A key feature of Avro is its robust support for evolving data schemas over time, accommodating changes such as field deletion, addition, or modification.
Avro supports a variety of data structures. For instance, one can create a record that contains an array, an enumerated type, and a sub-record.
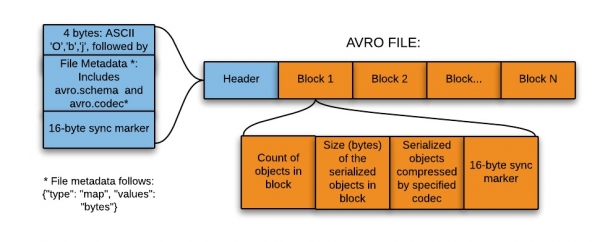
This format is ideal for writing to the landing (transition) zone of a data lake., or data lake — a collection of instances for storing different types of data in addition to direct data sources).
So, for writing to the landing zone of the data lake, this format is best suited for the following reasons:
- Data from this zone is usually read in full for further processing by downstream systems — and a string-based format is more efficient in this case.
- Downstream systems can easily extract schema tables from files — there’s no need to store schemas separately in an external metadata repository.
- Any change to the original schema is easily handled (schema evolution).
Parquet file format
Parquet is an open-source file format for Hadoop that stores nested data structures in a flat columnar format..
Compared to the traditional row-based approach, Parquet is more efficient in terms of storage and performance.
This is particularly useful for queries that read specific columns from a wide (multi-column) table. Because of the file format, only the required columns are read, minimizing I/O.
A brief explanatory aside: to better understand the Parquet file format in Hadoop, let’s look at what a column-based — that is, columnar — format is. In such a format, values of the same type for each column are stored together.
, the record includes fields ID, Name, and Department. In this case, all values in the ID column will be stored together, as will values in the Name column, and so on. The table would look something like this:
ID
Name
Department
1
emp1
d1
2
emp2
d2
3
emp3
d3
In row format, the data will be saved as follows:
1
emp1
d1
2
emp2
d2
3
emp3
d3
In columnar format, the same data will be stored like this:
1
2
3
emp1
emp2
emp3
d1
d2
d3
The columnar format is more efficient when you need to query multiple columns from a table. It reads only the necessary columns because they are stored adjacently, minimizing I/O operations.
For example, if you only need the NAME column. In , each record in the dataset needs to be loaded, parsed by fields, and then the NAME data extracted. The columnar format allows you to go directly to the Name column since all values for that column are stored together. You won’t have to scan the entire record.
Thus, the columnar format improves query performance, as it takes less time to search for the required columns and reduces the number of input-output operations, since only the necessary columns are read.
One of the unique features is that in this format it can store data with nested structures. This means that in a Parquet file, even nested fields can be read separately without the need to read all fields in the nested structure. To store nested structures, Parquet uses a shredding and assembly algorithm.
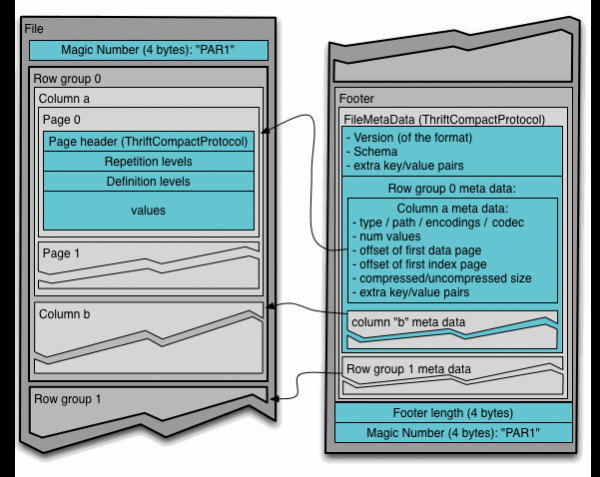
To understand the Parquet file format in Hadoop, it is necessary to know the following terms:
- Row group (row group): a logical horizontal partition of the data into rows. A row group consists of a fragment of each column in the dataset.
- Column chunk (column chunk): a fragment of a specific column. These column fragments reside in a certain row group and are guaranteed to be contiguous in the file.
- Page (page): column fragments are divided into pages, written sequentially. Pages have a shared header, so unnecessary pages can be skipped when reading.
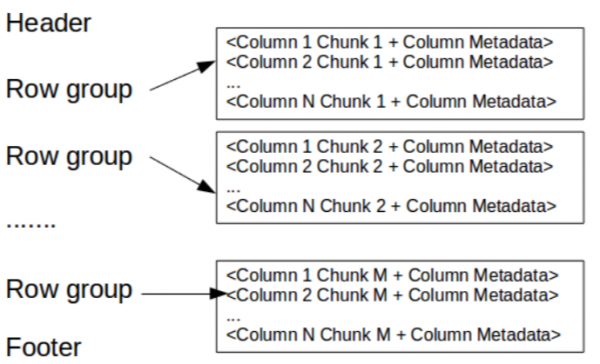
Here the header simply contains the magic number PAR1 (4 bytes), which identifies the file as a Parquet format file.
The footer records the following:
- File metadata, which contains the starting coordinates of each column's metadata. When reading, the file's metadata must be read first to find all the relevant column fragments. Then the column fragments should be read sequentially. Metadata also includes the format version, schema, and any additional key-value pairs.
- Length of the metadata (4 bytes).
- The magic number PAR1 (4 bytes).
The ORC file format
Optimized Row Columnar file format (Optimized Row Columnar, ) offers a very efficient way to store data and was developed to overcome the limitations of other formats. It stores data in a perfectly compact form, allowing for the skipping of unnecessary details—without requiring the construction of large, complex, or manually maintained indexes.
Advantages of the ORC format:
- One file as output for each task, which reduces the load on the NameNode.
- Support for Hive data types, including DateTime, decimal, and complex data types (struct, list, map, and union).
- Simultaneous reading of the same file by different RecordReader processes.
- The ability to split files without scanning for markers.
- Estimation of the maximum possible heap memory allocation for reading/writing processes based on footer file information.
- Metadata is stored in a binary format using Protocol Buffers serialization, allowing fields to be added and removed.
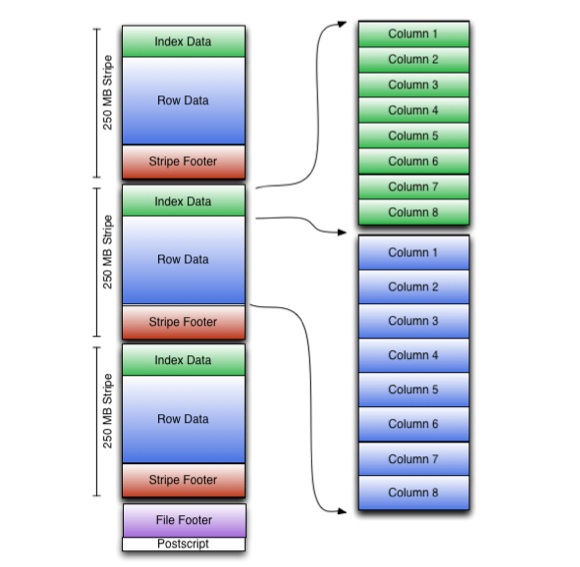
ORC stores collections of rows in a single file, while the row data within a collection is stored in a columnar format.
An ORC file stores groups of rows called stripes, along with auxiliary information in the file footer. A postscript at the end of the file contains compression parameters and the size of the compressed footer.
By default, the stripe size is 250 MB. Large stripe sizes make reading from HDFS more efficient, allowing for larger continuous blocks.
The footer of the file records a list of stripes in the file, the number of rows per stripe, and the data type of each column. It also includes the resulting count, min, max, and sum for each column.
The stripe footer contains a catalog of stream locations.
Row data is used when scanning tables.
Index data includes minimum and maximum values for each column and the position of rows in each column. ORC indexes are used only for selecting stripes and groups of rows, not for responding to queries.
Comparison of different file formats
Avro vs Parquet
- Avro is a row-oriented storage format, whereas Parquet stores data in a columnar manner.
- Parquet is better suited for analytical queries, meaning reading operations and data querying are much more efficient than writing.
- Write operations in Avro are more efficient than in Parquet.
- Avro handles schema evolution more maturely. Parquet only supports schema addition, while Avro implements multi-faceted evolution, meaning the addition or modification of columns.
- Parquet is ideal for querying a subset of columns in a multi-column table. Avro is suitable for ETL operations where we query all columns.
ORC vs Parquet
- Parquet better supports nested data storage.
- ORC is better adapted for predicate pushdown.
- ORC supports ACID properties.
- ORC compresses data better.
What else to read on the topic:
- .
- .
- .
Source: habr.com
