

is a columnar database management system for online analytical processing (OLAP) with open source code, developed by Yandex. It is used by Yandex, CloudFlare, VK.com, Badoo, and other services worldwide for storing truly large volumes of data (inserting thousands of rows per second or petabytes of data stored on disk).
In a typical "row-based" database, examples of which include MySQL, Postgres, and MS SQL Server, data is stored in the following order:
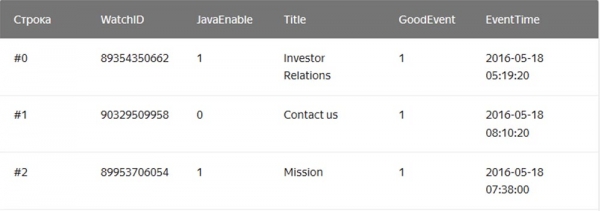
In this case, values corresponding to a single row are physically stored together. In columnar databases, values from different columns are stored separately, while the data of one column is kept together:
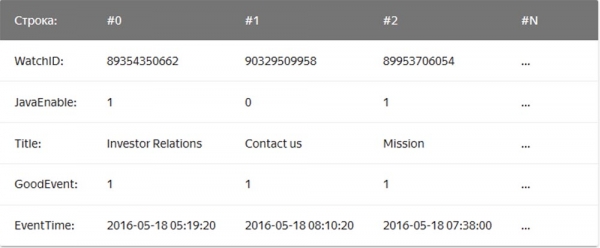
Examples of columnar databases include Vertica, Paraccel (Actian Matrix, Amazon Redshift), Sybase IQ, Exasol, Infobright, InfiniDB, MonetDB (VectorWise, Actian Vector), LucidDB, SAP HANA, Google Dremel, Google PowerDrill, Druid, and kdb+.
Company – mail forwarder began using Clickhouse in 2018 for reporting and was very impressed with its simplicity, scalability, SQL support, and speed. The performance of this database was almost magical.
Simplicity
Clickhouse can be installed on Ubuntu with a single command. If you know SQL, you can immediately start using Clickhouse for your needs. However, this does not mean you can execute "show create table" in MySQL and copy-paste SQL into Clickhouse.
Compared to MySQL, there are important differences in data types in table schema definitions in this DBMS, so you will still need some time to modify the table schema definitions and learn the table engines for comfortable operation.
Clickhouse works perfectly without any additional software, but if you want to use replication, you will need to install ZooKeeper. Query performance analysis shows excellent results—system tables contain all the information, and all data can be retrieved using old and dull SQL.
Performance
- comparisons of Clickhouse with Vertica and MySQL on a server configuration: two Intel® Xeon® CPU E5-2650 v2 @ 2.60GHz sockets; 128 GiB RAM; md RAID-5 on 8 6TB SATA HDD, ext4.
- comparisons of Clickhouse with Amazon RedShift cloud data storage.
- Excerpts from the blog :
The ClickHouse database has a very simple design— all nodes in the cluster have the same functionality and use ZooKeeper solely for coordination. We built a small cluster of several nodes and conducted testing, during which we discovered that the system boasts quite impressive performance, matching the claimed advantages in benchmarks of analytical DBMS. We decided to take a closer look at the underlying concept of ClickHouse. The first hurdle for our research was the lack of tools and the limited community around ClickHouse, so we delved into the design of this DBMS to understand how it works.
ClickHouse does not support receiving data directly from Kafka since it is merely a database, so we wrote our own adapter service in Go. It read encoded Cap’n Proto messages from Kafka, converted them to TSV, and inserted them into ClickHouse in batches via the HTTP interface. Later, we rewrote this service to use the Go library in conjunction with our own ClickHouse interface to improve performance. When evaluating batch reception performance, we discovered something important— it turns out that ClickHouse's performance is significantly dependent on the batch size, that is, the number of rows inserted simultaneously. To understand why this happens, we studied how ClickHouse stores data.
The main engine, or rather, the family of engines for tables used by ClickHouse to store data is the MergeTree. Conceptually, this engine resembles the LSM algorithm used in Google BigTable or Apache Cassandra, but it avoids creating an intermediate memory table and writes data directly to disk. This gives it excellent write throughput since each inserted batch is sorted only by the primary key, compressed, and written to disk to form a segment.
The absence of a memory table or any concept of data freshness also means that data can only be added; the system does not support modification or deletion. Currently, the only way to delete data is to remove them by calendar months, as segments never cross the month boundary. The ClickHouse team is actively working to make this feature customizable. On the other hand, this makes the writing and merging of segments conflict-free, so the ingestion throughput scales linearly with the number of parallel inserts until I/O or core saturation occurs.
However, this circumstance also means that the system is not suitable for small batches, so Kafka services and inserters are used for buffering. Additionally, ClickHouse continues to merge segments constantly in the background, so many small pieces of information will be combined and written multiple times, thereby increasing the writing intensity. At the same time, too many unrelated parts will cause aggressive throttling of inserts until the merging continues. We found that the best compromise between real-time data ingestion and ingestion performance is to have a limited number of inserts per second into the table.
The key to reading table performance is indexing and data layout on disk. Regardless of how fast processing is, when the engine needs to scan terabytes of data from disk and use only a part of it, it will take time. ClickHouse is a columnar storage, so each segment contains a file for each column with sorted values for each row. Thus, entire columns not present in the query can be skipped at first, and then several cells can be processed in parallel with vectorized execution. To avoid a full scan, each segment has a small index file.
Given that all columns are sorted by the 'primary key', the index file contains only the markers (captured rows) of every N-th row, allowing them to be stored in memory even for very large tables. For instance, you can set the default settings to 'mark every 8192-th row', in which case 'sparse' indexing of a table with 1 trillion rows that easily fits in memory will only take 122,070 characters.
System Development
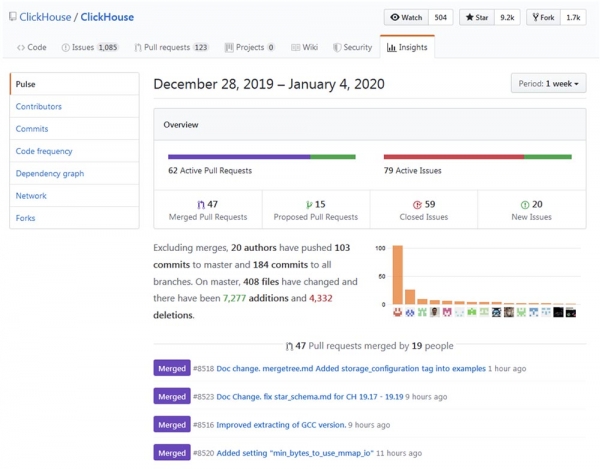
The development and improvement of Clickhouse can be tracked on and you can see that the process of 'maturation' is happening at an impressive pace.
Popularity
It seems that the popularity of Clickhouse is growing exponentially, especially within the Russian-speaking community. Last year's High Load 2018 conference (Moscow, November 8-9, 2018) showcased that giants like vk.com and Badoo use Clickhouse to insert data (for example, logs) from tens of thousands of servers simultaneously. In a 40-minute video . Soon we will publish the transcript on Habr for easier handling of the material.
Application Areas
After spending some time researching, I believe there are areas where ClickHouse can be useful or able to completely replace other more traditional and popular solutions like MySQL, PostgreSQL, ELK, Google Big Query, Amazon RedShift, TimescaleDB, Hadoop, MapReduce, Pinot, and Druid. Below are the details on using ClickHouse for modernizing or fully replacing the aforementioned DBMS.
Extending MySQL and PostgreSQL capabilities
Recently, we partially replaced MySQL with ClickHouse for the Mautic newsletter platform. . The problem was that MySQL, due to its poorly thought-out design, logged every sent email and every link in that email with a base64 hash, creating a huge MySQL table (email_stats). After sending just 10 million emails to subscribers, this table occupied 150 GB of disk space, causing MySQL to slow down on simple queries. To fix the disk space issue, we successfully used InnoDB table compression, which reduced its size by four times. However, it still doesn’t make sense to store more than 20-30 million emails in MySQL just for the sake of reading history, as any simple query that requires a full scan for some reason leads to swapping and high I/O load, resulting in regular warnings from Zabbix.
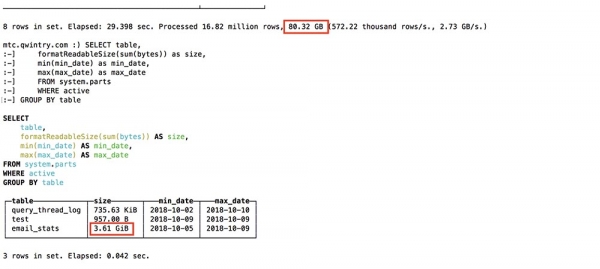
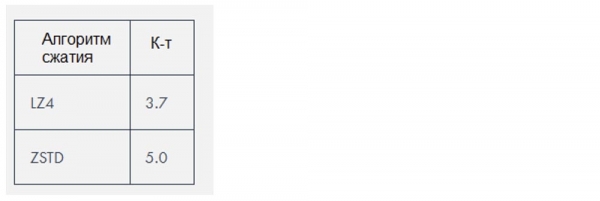
Clickhouse uses two compression algorithms that reduce the data size by about , but in this particular case, the data was especially 'compressible'.
Replacing ELK
Based on my own experience, the ELK stack (ElasticSearch, Logstash, and Kibana, specifically ElasticSearch in this case) requires significantly more resources to run than necessary for storing logs. ElasticSearch is a great engine if you need good full-text search in logs (and I don't think you actually need that), but I'm curious why it has become the de facto standard engine for logging. Its ingestion performance combined with Logstash led to issues even under fairly light loads and required increasing amounts of RAM and disk space. As a database, Clickhouse outperforms ElasticSearch for the following reasons:
- Support for SQL dialect;
- Better compression ratio of stored data;
- Support for Regex search instead of full-text search;
- Improved query planning and higher overall performance.
Currently, the biggest issue when comparing ClickHouse with ELK is the lack of solutions for log shipping, as well as a shortage of documentation and tutorials on this topic. However, any user can set up ELK using the Digital Ocean guide, which is very important for quick implementation of such technologies. Here there's a database engine, but there’s still no Filebeat for ClickHouse. Yes, it is present. and the system for working with logs , there is a tool for inputting log file data into ClickHouse, but all of this takes more time. However, ClickHouse still leads due to its simplicity, so even beginners can easily set it up and start fully utilizing it in just 10 minutes.
Preferring minimalist solutions, I tried using FluentBit, a tool for shipping logs with a very small memory footprint, along with ClickHouse, while trying to avoid using Kafka. However, some minor incompatibilities need to be addressed, such as , before this can be done without a proxy layer that converts data from FluentBit to ClickHouse.
As an alternative to Kibana, ClickHouse can be used as a backend . As far as I understand, this can lead to performance issues when rendering a huge volume of data points, especially with older versions of Grafana. At Qwintry, we haven't tried this yet, but complaints about such issues occasionally crop up on the ClickHouse support channel on Telegram.
Replacing Google BigQuery and Amazon RedShift (a solution for large companies)
The ideal use case for BigQuery is to load 1 TB of JSON data and run analytics queries on it. BigQuery is an excellent product whose scalability is hard to overestimate. It is a much more complex software than ClickHouse, running on an internal cluster, but from the client's perspective, it has a lot in common with ClickHouse. BigQuery can quickly become 'expensive' once you start paying for every SELECT, making it a true SaaS solution with all its pros and cons.
ClickHouse is the best choice when you're running a lot of computationally expensive queries. The more SELECT queries you execute each day, the more sense it makes to replace BigQuery with ClickHouse, as this switch can save you thousands of dollars when dealing with many terabytes of processed data. This does not apply to stored data, which is relatively inexpensive to process in BigQuery.
In an article by Altinity co-founder Alexander Zaitsev , the advantages of such a database migration are discussed.
Replacing TimescaleDB
TimescaleDB is a PostgreSQL extension that optimizes the handling of time series in a standard database., ).
While ClickHouse is not a serious contender in the time series niche, its columnar structure and vector query execution allow it to outpace TimescaleDB in most analytical query processing scenarios. Moreover, ClickHouse’s capability for ingesting batch data is about three times greater, and it uses 20 times less disk space, which is crucial for managing large volumes of historical data..
Unlike ClickHouse, the only way to save some disk space in TimescaleDB is by using ZFS or similar file systems.
Upcoming ClickHouse updates are expected to introduce delta compression, which will make it even more suitable for processing and storing time series data. TimescaleDB might be a better choice than ‘vanilla’ ClickHouse in the following cases:
- small installations with very low memory capacity (<3 GB);
- a large number of small INSERTs that you do not want to buffer into larger segments;
- better consistency, uniformity, and AСID compliance;
- support for PostGIS;
- integration with existing PostgreSQL tables, since essentially TimescaleDB is PostgreSQL.
Competition with Hadoop and MapReduce
Hadoop and other MapReduce products can perform many complex computations, but they typically work with significant latencies. ClickHouse addresses this issue by processing terabytes of data and delivering results almost instantly. Therefore, ClickHouse is much more efficient for performing fast, interactive analytical queries, which should appeal to data processing specialists.
Competition with Pinot and Druid
The closest competitors to ClickHouse are the columnar, linearly scalable open source products Pinot and Druid. Excellent comparisons of these systems are published in the article dated February 1, 2018.
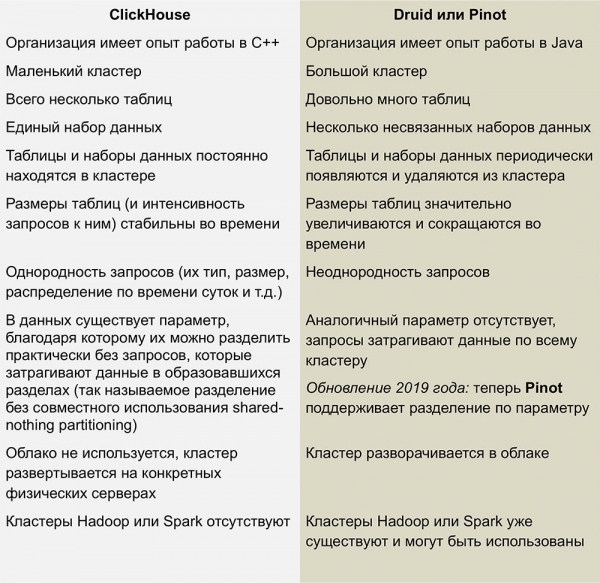
This article requires an update – it states that ClickHouse does not support UPDATE and DELETE operations, which is not entirely accurate regarding recent versions.
We lack sufficient experience with these databases, but I really dislike the complexity of the infrastructure required to run Druid and Pinot — there are a lot of 'moving parts' surrounded by Java on all sides.
Druid and Pinot are Apache incubator projects, and their development is thoroughly covered by Apache on their GitHub project pages. Pinot entered the incubator in October 2018, while Druid was born eight months earlier— in February.
The lack of information about how AFS works raises some questions for me, possibly silly ones. I wonder if the creators of Pinot have noticed that the Apache Foundation is more supportive of Druid and if such favoritism has caused feelings of envy towards the competitor? Will Druid's development slow down and Pinot's accelerate if the sponsors supporting the former suddenly take an interest in the latter?
Disadvantages of ClickHouse
Immaturity: it is clear that this is still a non-boring technology, but in any case, nothing like this is observed in other columnar databases.
Small inserts work poorly at high speed: inserts need to be split into large chunks because the performance of small inserts decreases proportionally to the number of columns in each row. This is how data is stored on disk in ClickHouse — each column represents 1 file or more, so to insert 1 row containing 100 columns, you need to open and write to at least 100 files. That’s why a mediator is required for buffering inserts (unless the client itself provides buffering) — usually this is Kafka or some queue management system. The Buffer table engine can also be used to later copy large chunks of data into MergeTree tables.
Table joins are limited by the server's RAM, but at least they exist! For example, Druid and Pinot have no such joins at all, as they are difficult to implement in distributed systems that do not support moving large chunks of data between nodes.
Conclusions
In the coming years, we plan to widely adopt ClickHouse at Qwintry, as this DBMS offers an excellent balance of performance, low overhead, scalability, and simplicity. I am quite certain it will begin to spread rapidly once the ClickHouse community discovers more ways to utilize it in small and medium installations.
A little advertisement 🙂
Thank you for staying with us. Do you enjoy our articles? Want to see more interesting content? Support us by placing an order or recommending us to your friends, , a unique entry-level server alternative that we have created for you: (options available with RAID1 and RAID10, up to 24 cores and up to 40GB DDR4).
Dell R730xd at half the price in the Equinix Tier IV data center in Amsterdam? Only with us in the Netherlands! Dell R420 — 2x E5-2430 2.2GHz 6C 128GB DDR3 2x960GB SSD 1Gbps 100TB — from $99! Read about how
Source: habr.com
