

The holidays are over, and we're back with our second post in the Istio Service Mesh series.
Today's topic is Circuit Breaker, which translates to 'automatic switch' in Russian, colloquially known as 'protection switch'. However, in Istio, this switch does not disable a shorted or overloaded circuit but rather faulty containers.
How this is supposed to work in an ideal world
When microservices are managed by Kubernetes, for example, within the OpenShift platform, they automatically scale up and down depending on the load. Since microservices run in pods, multiple instances of a containerized microservice can exist at a single endpoint, and Kubernetes will route requests and balance the load among them. Ideally, all of this should work seamlessly.
We must remember that microservices are small and ephemeral. The ephemerality, which here means the ease of coming into existence and disappearing, is often underestimated. The birth and death of each microservice instance in a pod is quite expected; OpenShift and Kubernetes handle this well, and everything works wonderfully – but again, only in theory.
How this really works
Now imagine that a specific instance of a microservice, that is, a container, has failed: either it isn’t responding (error 503), or, even worse, it responds but too slowly. In other words, it’s glitching or not answering requests, but it hasn’t been removed from the pool. What should be done in this case? Retry? Remove it from the routing schema? And what does 'too slow' mean – how do we quantify that, and who makes that determination? Maybe just give it a break and try later? If so, how much later?
What is Pool Ejection in Istio
This is where Istio comes to the rescue with its Circuit Breaker mechanisms, which temporarily remove faulty containers from the resource pool for routing and load balancing, implementing the Pool Ejection procedure.
Using an outlier detection strategy, Istio detects skewed pods that deviate from the norm and removes them from the resource pool for a defined period known as the 'sleep window'.
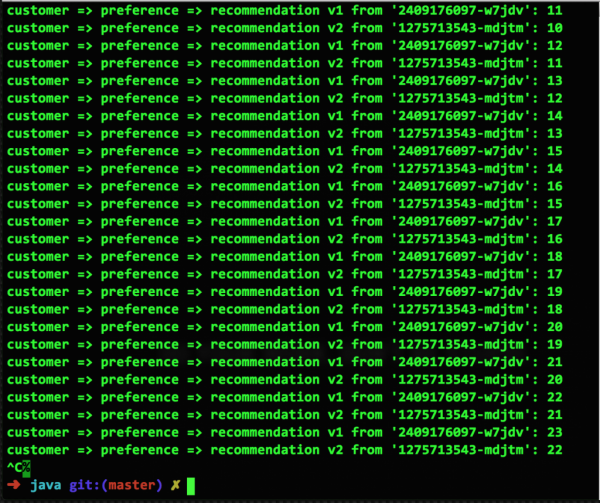
To illustrate how this works in Kubernetes on the OpenShift platform, let's start with a screenshot of the functioning microservices from the example in the repository. Here we have two pods, v1 and v2, each running one container. When Istio routing rules are not in use, Kubernetes defaults to evenly balanced round-robin routing.
Preparing for failure
Before performing Pool Ejection, we need to create an Istio routing rule. Let's say we want to distribute requests between the pods with a 50/50 ratio. Additionally, we will increase the number of v2 containers from one to two, as follows:
oc scale deployment recommendation-v2 --replicas=2 -n tutorial
Now we set the routing rule so that traffic is distributed between the pods in a 50/50 ratio.
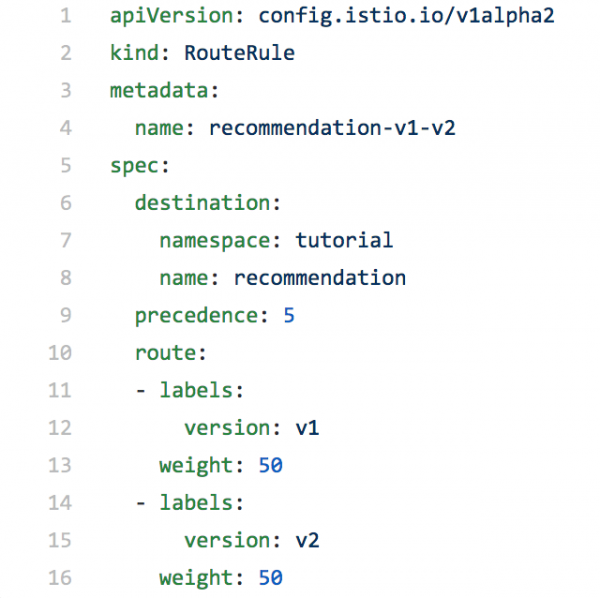
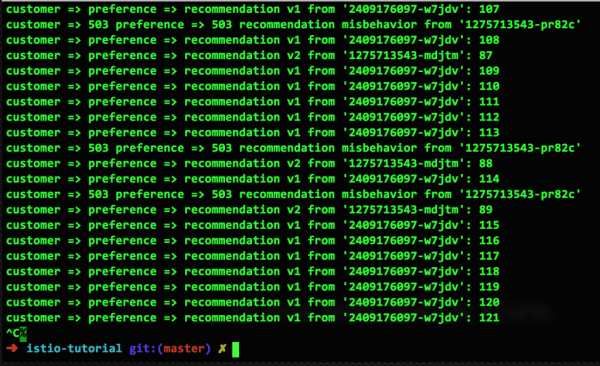
Here is how the result of this rule looks:
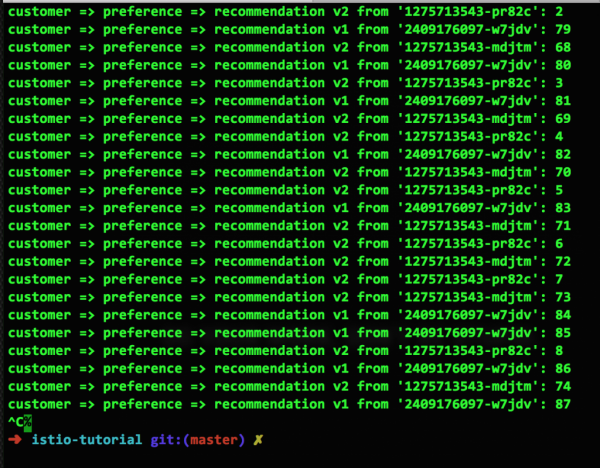
One might argue that this screenshot shows not 50/50, but rather 14:9, but over time the situation will balance out.
Inducing failure
Now we will take one of the two v2 containers out of service so that we have one healthy v1 container, one healthy v2 container, and one unhealthy v2 container.
Fixing failure
So, we have an unhealthy container, and it's time for Pool Ejection. With a very simple config, we will exclude this faulty container from any routing schemes for 15 seconds, hoping that it will return to a healthy state (either by restarting or restoring performance). Here’s what this config looks like and the results of its operation:
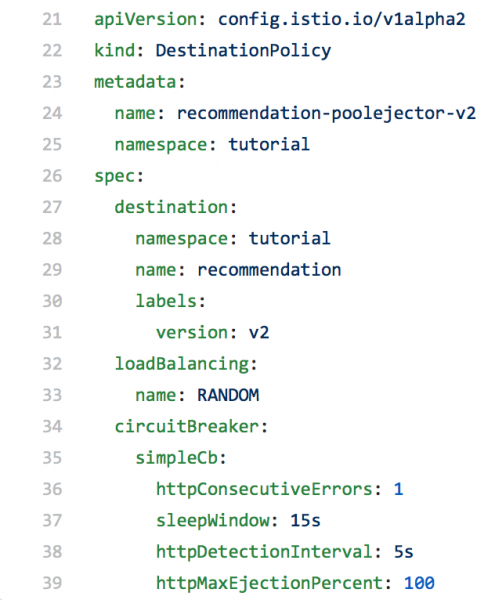
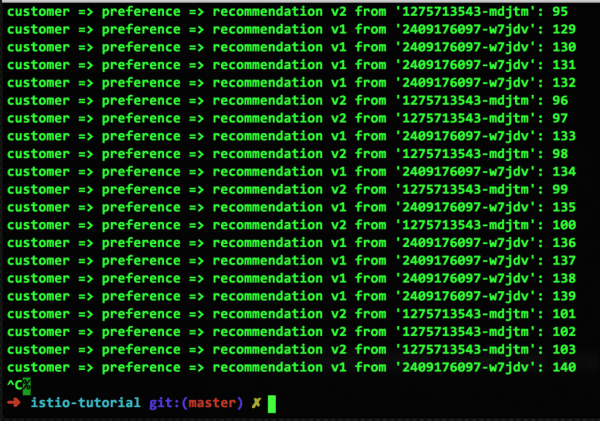
As seen, the unhealthy v2 container is no longer used for routing requests since it was removed from the pool. However, after 15 seconds, it will automatically return to the pool. In fact, we've just demonstrated how Pool Ejection works.
Starting to build architecture
Pool Ejection, combined with Istio's monitoring capabilities, allows us to start establishing a framework for automatically replacing unhealthy containers, reducing or even eliminating downtime and failures.
NASA has a famous motto – Failure Is Not an Option, attributed to the Flight Director. In English, it can be translated as "Failure is not an option," meaning that everything can be made to work if there is enough willpower. However, in real life, failures are not just occurrences, they are inevitable, everywhere and in everything. So how do we deal with them in the case of microservices? In our opinion, it is better to rely not on willpower, but on the capabilities of containers. , , and .
As we mentioned earlier, Istio successfully implements the well-established physical world concept of circuit breakers. Just as an electrical circuit breaker disconnects a problematic section of the circuit, the software Circuit Breaker in Istio breaks the connection between the stream of requests and the problematic container when something is wrong with the endpoint, for example, when the server crashes or starts to lag.
Moreover, in the second case, problems only multiply, since the delays of one container not only cause cascading delays in the services that depend on it, consequently lowering the overall system performance, but also generate repeat requests to an already slow service, which only exacerbates the situation.
Circuit Breaker in theory
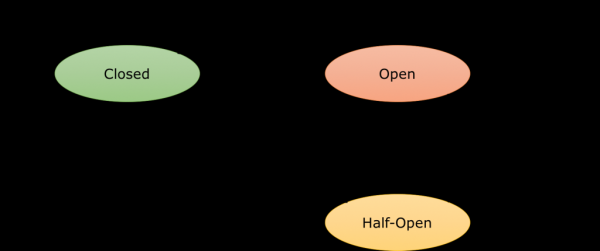
The Circuit Breaker is a proxy that controls the flow of requests to the endpoint. When this endpoint stops working or – depending on the settings – starts to lag, the proxy breaks the connection with the container. After that, traffic is redirected to other containers, simply for load balancing. The connection remains open for a specified sleep window, say two minutes, and then transitions to a half-open state. An attempt to send the next request determines the further state of the connection. If everything is OK with the service, the connection returns to a working state and becomes closed again. If there is still an issue with the service, the connection breaks again, and the sleep window resets. Here's what a simplified state transition diagram of the Circuit Breaker looks like:
It is important to note that all this occurs at a systemic architecture level, so at some point you will need to teach your applications to work with the Circuit Breaker, for example, by providing a default value in response or, if possible, ignoring the existence of the service. This is achieved using the bulkhead pattern, but it is beyond the scope of this article.
Circuit Breaker in practice
As an example, we will run two versions of our recommendation microservice on OpenShift. Version 1 will function properly, while in v2 we will introduce a delay to simulate server slowness. The results will be viewed using the tool :
siege -r 2 -c 20 -v customer-tutorial.$(minishift ip).nip.io
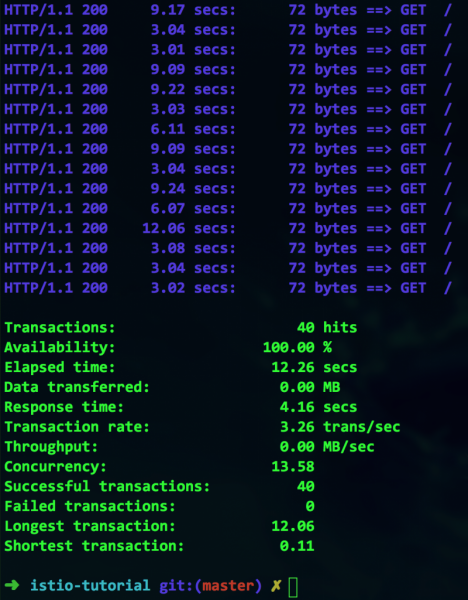
Everything seems to be working, but at what cost? At first glance, we have 100% availability, but take a closer look – the maximum transaction duration is a full 12 seconds. This is clearly a bottleneck that needs to be addressed.
To do this, we will use Istio to exclude calls to slow containers. Here is what the corresponding config looks like using the Circuit Breaker:
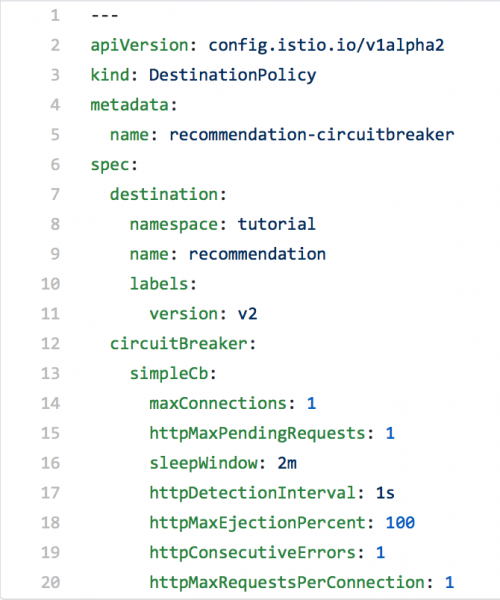
The last line with the parameter httpMaxRequestsPerConnection signals that the connection should be broken when attempting to create another – second – connection in addition to the existing one. Since our container simulates a slowing service, such situations will occur periodically, and then Istio will return a 503 error, while this is what siege will show:
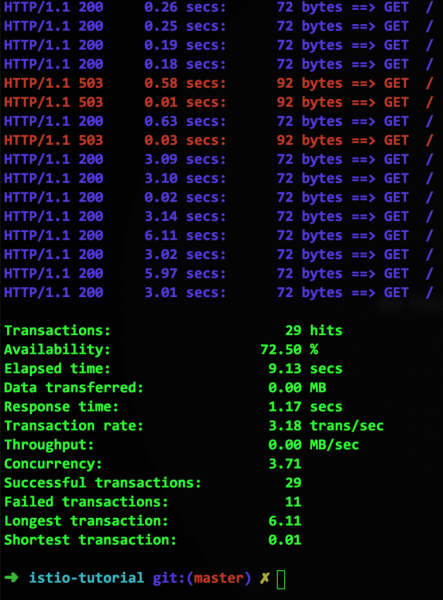
Okay, we have a Circuit Breaker, what next?
So, we have implemented automatic disconnection without touching the original code of the services themselves. By using the Circuit Breaker and the Pool Ejection procedure described above, we can remove slowing containers from the resource pool until they return to normal, and check their status at a specified interval – in our example, this is two minutes (the sleepWindow parameter).
Note that the application's ability to respond to a 503 error is still set at the level of its original code. There are many strategies for working with Circuit Breaker that are applied depending on the situation.
In the next post: we will discuss tracing and monitoring, which are already built-in or easily added to Istio, as well as how to intentionally introduce errors into the system.
Source: habr.com
