

From the Google Blog Editor: Have you ever wondered how Google Cloud Technical Solutions (TSE) engineers handle your support requests? TSE technical support engineers are responsible for identifying and resolving issues reported by users. Some of these problems are quite straightforward, but sometimes a request requires the attention of several engineers. In this article, one of the TSE staff will share with us a particularly tricky problem from their recent experience — . Throughout this narrative, we will see how the engineers managed to resolve the situation and what new insights they gained during the troubleshooting process. We hope that this story not only highlights a deeply rooted bug but also provides an understanding of the processes involved in submitting a request to Google Cloud Support.
Troubleshooting is both a science and an art. It all starts with forming a hypothesis about the cause of the system's unusual behavior, which is then rigorously tested. However, before we can formulate a hypothesis, we must clearly define and articulate the problem. If the question is too vague, you will need to do some thorough analysis; this is where the 'art' of troubleshooting comes into play.
In the context of Google Cloud, such processes become significantly more complicated because Google Cloud strives to ensure the privacy of its users. As a result, TSE engineers do not have access to modify your systems or view configurations as broadly as users can. Therefore, to verify any of our hypotheses, we (the engineers) cannot quickly modify the system.
Some users think we will fix everything like mechanics in an auto shop and simply send us the ID of the virtual machine, while in reality, the process involves conversation: gathering information, forming and confirming (or refuting) hypotheses, and ultimately, the solution to the problem is built on communication with the client.
The Issue at Hand
Today we have a story with a happy ending. One of the reasons for the successful resolution of the proposed case is the very detailed and accurate description of the problem. Below you can see a copy of the first ticket (edited to conceal confidential information):
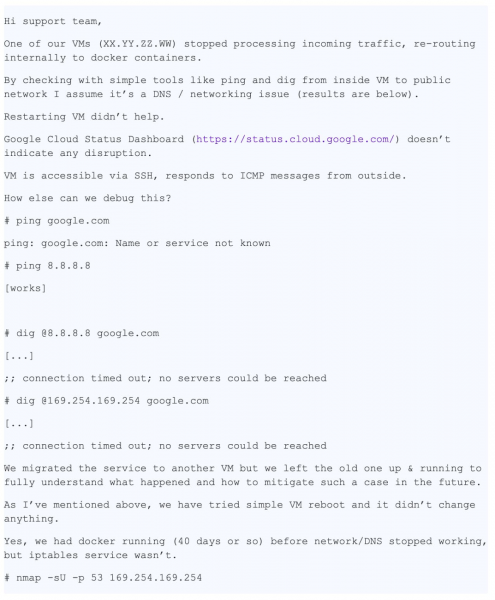
This message contains a lot of useful information for us:
- It specifies a particular VM.
- It states the problem — DNS is not working.
- It specifies where the problem manifests itself — VM and container.
- It outlines the steps the user took to identify the problem.
The inquiry was registered as "P1: Critical Impact — Service Unusable in production," which means constant monitoring of the situation 24/7 according to the "Follow the Sun" scheme (you can read more about ), with its transfer from one support team to another with each shift of time zones. Essentially, by the time the problem reached our team in Zurich, it had circled the globe. By this time, the user had taken measures to mitigate the impact, but was concerned about a recurrence of the situation in production, as the root cause had still not been identified.
By the time the ticket reached Zurich, we already had the following information:
- Contents
/etc/hosts - Contents
/etc/resolv.conf - Output
iptables-save - The file was collected by the team
ngreppcap file
With this data, we were ready to move on to the "investigation" and troubleshooting stage.
Our first steps
First, we checked the logs and status of the metadata server and confirmed that it was functioning correctly. The metadata server responds to the IP address 169.254.169.254 and, among other things, is responsible for domain name control. We also double-checked that the firewall is correctly working with the VM and is not blocking packets.
It was a strange problem: nmap checks disproved our primary hypothesis about UDP packet loss, so we mentally generated several more variants and ways to check them:
- Are packets lost selectively? => Check iptables rules.
- Is too small ? => Проверить вывод
ip a show - Does the problem only affect UDP packets or TCP as well? => Run
dig +tcp - Are the generated dig packets returning? => Run
tcpdump - Is libdns working correctly? => Run
straceto check packet transmission in both directions.
Here we decide to call the user for live troubleshooting.
During the call, we manage to check several things:
- After several checks, we rule out iptables as a cause.
- We check network interfaces and routing tables, and recheck the correctness of the MTU.
- We discover that
dig +tcp google.com(TCP) works fine, butdig google.com(UDP) does not work. - Running
tcpdumpit works for now.dig, we find that UDP packets are being returned. - We run
strace dig google.comand see how dig correctly callssendmsg()andrecvmsg(),but the second one gets interrupted by a timeout.
Unfortunately, the end of the shift comes, and we have to pass the issue to the next time zone. However, the inquiry sparked interest in our team, and a colleague suggests creating a raw DNS packet using the Python module scrapy.
from scapy.all import *

answer = sr1(IP(dst="169.254.169.254")/UDP(dport=53)/DNS(rd=1,qd=DNSQR(qname="google.com")),verbose=0)
print ("169.254.169.254", answer[DNS].summary())
This snippet creates a DNS packet and sends a request to the metadata server.
The user runs the code, the DNS response is returned, and the application receives it, confirming that there is no issue at the network level.
After another "world tour," the inquiry returns to our team, and I take it over completely, believing that it will be more convenient for the user if the inquiry stops bouncing around.
Meanwhile, the user kindly agrees to provide a snapshot of the system image. This is great news: the ability to test the system myself significantly speeds up troubleshooting, as I no longer have to ask the user to run commands, send me results, and analyze them; I can do everything myself!
My colleagues start to be a little envious. During lunch, we discuss the inquiry, but no one has any ideas about what is happening. Fortunately, the user has already taken measures to mitigate the situation and is in no rush, so we have time to dissect the problem. And since we have the image, we can conduct any tests we find interesting. Great!
Taking a step back,
One of the most popular questions in systems engineer interviews goes like this: "What happens when you ping ?» Вопрос шикарный, так как кандидату необходимо описать пусть от оболочки до пользовательского пространства, до ядра системы и далее к сети. Я улыбаюсь: иногда вопросы с интервью оказываются полезны и в реальной жизни…
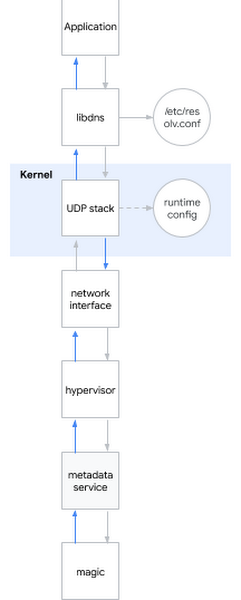
I decide to apply this HR question to the current issue. Roughly speaking, when you try to resolve a DNS name, the following happens:
- The application calls a system library, such as libdns
- libdns checks the system configuration for which DNS server to query (in the diagram this is 169.254.169.254, the metadata server)
- libdns uses system calls to create a UDP socket (SOCK_DGRAM) and sends UDP packets with DNS queries in both directions
- The UDP stack can be configured at the kernel level through the sysctl interface
- The kernel interacts with hardware to transmit packets over the network through the network interface
- The hypervisor captures and forwards the packet to the metadata server upon contact
- The metadata server determines the DNS name through its magic and returns the answer in the same manner
Let me remind you what hypotheses we have already discussed:
Hypothesis: Libraries are broken
- Test 1: Run strace on the system, check that dig makes the correct system calls
- Result: Correct system calls are being made
- Test 2: Use srapy to check if we can resolve names bypassing the system libraries
- Result: We can
- Test 3: Run rpm -V on the libdns package and check the md5sum of the library files
- Result: The library code is completely identical to the code in the working operating system
- Test 4: Mount the user root system image on a VM without such behavior, run chroot, see if DNS works
- Result: DNS works correctly
Conclusions based on the tests: The problem is not with the libraries
Hypothesis: There is an error in the DNS settings
- Test 1: Check tcpdump and observe whether DNS packets are sent and received correctly after running dig
- Result: Packets are transmitted correctly
- Test 2: Double-check on the server
/etc/nsswitch.confand/etc/resolv.conf - Result: Everything is correct
Conclusions based on the tests: The problem is not with the DNS configuration
Hypothesis: The kernel is corrupted
- Test: Install a new kernel, check the signature, reboot
- Result: Similar behavior
Conclusions based on the tests: The kernel is not corrupted
Hypothesis: Incorrect behavior of the user network (or the hypervisor's network interface)
- Test 1: Check the firewall settings
- Result: The firewall allows DNS packets on both the host and GCP
- Test 2: Intercept traffic and trace the correctness of the transmission and return of DNS queries
- Result: tcpdump confirms the receipt of response packets by the host
Conclusions based on the tests: The problem is not in the network
Hypothesis: The metadata server is not working
- Test 1: Check the metadata server logs for anomalies
- Result: There are no anomalies in the logs
- Test 2: bypass the metadata server through
dig @8.8.8.8 - Result: resolution fails even without using the metadata server
Conclusions based on the tests: the issue is not with the metadata server
Conclusion: we tested all subsystems except the runtime settings!
Diving into the kernel runtime settings
To configure the kernel runtime, you can use command line options (grub) or the sysctl interface. I peeked into /etc/sysctl.conf and just think, I found several custom settings. Feeling as though I had grasped something, I disregarded all non-network or non-TCP settings, leaving me with a handful of settings net.core. Then I went to where the VM host permissions are stored and began applying settings one by one from the broken VM until I found the culprit:
net.core.rmem_default = 2147483647Here it is, the DNS configuration breaker! I found the weapon of the crime. But why is this happening? I still needed a motive.
The basic buffer size setting for DNS packets is configured through net.core.rmem_default. The typical value ranges somewhere around 200KiB, but if your server is receiving a lot of DNS packets, you can increase the buffer size. If a new packet arrives while the buffer is full, for example because the application isn't processing it fast enough, you'll start losing packets. Our client correctly increased the buffer size out of concern for data loss since they were using a metrics collection application via DNS packets. The value they set was the maximum possible: 231-1 (if you set it to 231, the kernel returns 'INVALID ARGUMENT').
Suddenly I realized why nmap and scapy were working correctly: they were using raw sockets! Raw sockets are different from regular ones: they bypass iptables, and they are not buffered!
But why does a 'too large buffer' cause problems? It clearly doesn't work as intended.
By this point, I was able to reproduce the problem on several kernels and multiple distributions. The issue had already appeared on kernel 3.x and was now showing up on kernel 5.x as well.
Indeed, when executing
sysctl -w net.core.rmem_default=$((2**31-1))DNS stopped working.
I started looking for working values using a simple binary search algorithm and found that the system operates with 2147481343; however, that number was just a meaningless string of digits to me. I suggested this number to the client, and he replied that the system worked with google.com, but still returned an error with other domains, so I continued my investigation.
I installed , a tool I should have used earlier: it shows exactly where in the kernel the packet hits. The culprit turned out to be the function udp_queue_rcv_skb. I downloaded the kernel sources and added a few to track exactly where the packet goes. I quickly discovered the necessary condition if, and for a while I just stared at it, because that was when everything finally clicked into place: 231-1, a meaningless number, a non-working domain… It was all because of a piece of code in __udp_enqueue_schedule_skb:
if (rmem > (size + sk->sk_rcvbuf))
		goto uncharge_drop;
Please note:
rmemis of type intsizeis of type u16 (unsigned sixteen-bit int) and holds the packet sizesk->sk_rcvbufis of type int and holds the buffer size which by definition equals the value innet.core.rmem_default
Once sk_rcvbuf approaches 231, summing the packet size can lead to . And since this is an int, its value becomes negative, so the condition becomes true when it should be false (more about this can be found in ).
The issue can be trivially fixed by casting to unsigned int. I applied the fix and restarted the system, after which DNS worked again.
The taste of victory
I forwarded my findings to the client and sent the kernel patch. I am satisfied: every piece of the puzzle came together, I can clearly explain why we observed what we observed, and most importantly, we were able to find a solution thanks to teamwork!
It must be acknowledged that the case was rare, and fortunately we rarely receive such complex inquiries from users.
Source: habr.com
