

Hello, Habr!
I work in the Tinkoff team, which is developing our own notification center. Mostly, I develop in Java using Spring Boot and solve various technical problems that arise in the project.
Most of our microservices communicate asynchronously with each other through a message broker. Previously, we used IBM MQ as the broker, which could no longer handle the load, although it had high delivery guarantees.
As a replacement, we were offered Apache Kafka, which has high scalability potential but unfortunately requires a nearly tailored approach to configuration for different scenarios. Moreover, the at least once delivery mechanism, which operates in Kafka by default, did not allow maintaining the necessary level of consistency out of the box. Next, I will share our experience in configuring Kafka, particularly how to set it up and live with exactly once delivery.
Guaranteed delivery and more
The parameters that will be discussed below will help prevent a number of issues with the default connection settings. But first, I want to focus on one parameter that will ease potential debugging.
This will help client.id for the Producer and Consumer. At first glance, you can use the application name as the value, and in most cases, that will work. However, in situations where an application uses multiple Consumers and you assign them the same client.id, it leads to the following warning:
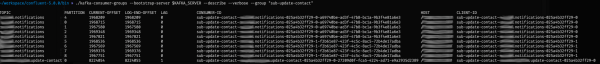
org.apache.kafka.common.utils.AppInfoParser — Error registering AppInfo mbean javax.management.InstanceAlreadyExistsException: kafka.consumer:type=app-info,id=kafka.test-0If you want to use JMX in an application with Kafka, this can be a problem. For this case, it's best to use a combination of the application name and, for example, the topic name as the value for client.id. You can see the result of our configuration in the output of the command kafka-consumer-groups from Confluent's utilities:
Now let's consider the scenario of guaranteed message delivery. Kafka Producer has a parameter acks, which allows you to configure after how many acknowledgments the cluster leader should consider the message successfully written. This parameter can take the following values:
- 0 — acknowledgments will not be counted.
- 1 — the default parameter, acknowledgment is required only from 1 replica.
- -1 — acknowledgments are required from all synchronized replicas (cluster configuration min.insync.replicas).
From the listed values, it is clear that an acks value of -1 provides the strongest guarantees that a message will not be lost.
As we all know, distributed systems are unreliable. To protect against temporary failures, the Kafka Producer provides the retriesparameter, which allows specifying the number of resend attempts within delivery.timeout.ms. Since the retries parameter defaults to Integer.MAX_VALUE (2147483647), the number of message resends can be controlled by adjusting only delivery.timeout.ms.
Now let's move on to exactly once delivery.
The listed settings allow our Producer to deliver messages with high guarantees. Now let's discuss how to ensure that only one copy of a message is recorded in a Kafka topic? In the simplest case, for this, the Producer needs to set the enable.idempotence parameter to true. Idempotence ensures that only one message is recorded in a specific partition of a topic. Prerequisites for enabling idempotence include values acks = all, retry > 0, max.in.flight.requests.per.connection ≤ 5. If these parameters are not specified by the developer, the above values will be set automatically.
Once idempotence is configured, it is necessary to ensure that the same messages go to the same partitions every time. This can be achieved by setting the key and partitioner.class parameter on the Producer. Let's start with the key. For each send, it must be the same. This is easily achieved by using some business identifier from the original message. The partitioner.class parameter defaults to . With this default partitioning strategy, we act as follows:
- If a partition is explicitly specified when sending the message, we use it.
- If no partition is specified but a key is provided, we choose the partition based on the hash of the key.
- If neither partition nor key is specified, we choose partitions in a round-robin manner.
Additionally, using a key and idempotent sending with the parameter max.in.flight.requests.per.connection = 1 provides you with ordered message processing on the Consumer. It is also important to remember that if access control is configured on your cluster, you will need permissions for idempotent writing to the topic.
If you find that you lack the ability for idempotent sending by key or the logic on the Producer side requires maintaining data consistency across different partitions, transactions can help. Additionally, using a chained transaction, you can conditionally synchronize a write to Kafka with a write to the database. To enable transactional sending on the Producer, it is necessary for it to have idempotency, and you must additionally specify transactional.id. If your Kafka cluster has access control configured, you will need write permissions for transactional writing, just like for idempotent writing, which can be granted by a mask using the value stored in transactional.id.
Formally, any string can be used as a transaction identifier, such as the application name. However, if you are running multiple instances of the same application with the same transactional.id, the first started instance will be stopped with an error because Kafka will consider it a zombie process.
org.apache.kafka.common.errors.ProducerFencedException: Producer attempted an operation with an old epoch. Either there is a newer producer with the same transactionalId, or the producer's transaction has been expired by the broker.To resolve this issue, we append a suffix to the application name, consisting of the hostname obtained from the environment variables.
The Producer is configured, but transactions in Kafka only manage the visibility of messages. Regardless of the transaction status, a message immediately goes to the topic but has additional system attributes.
To ensure that such messages are not read by the Consumer prematurely, it needs to set the parameter isolation.level to read_committed. Such a Consumer will be able to read non-transactional messages as before, while transactional messages will only be readable after the commit.
If you have set all the previously mentioned settings, then you have configured exactly once delivery. Congratulations!
But there is one more nuance. The transactional.id we configured above is actually a prefix for the transaction. A sequential number is appended to it on the transaction manager. The resulting identifier is issued at transactional.id.expiration.ms, which is configured on a Kafka cluster and has a default value of "7 days". If the application has not received any messages during this time, you will receive a message when attempting the next transactional send. InvalidPidMappingException. After this, the transaction coordinator will issue a new sequence number for the next transaction. However, the message may be lost if the InvalidPidMappingException is not handled correctly.
Instead of summaries
As you might notice, it's not enough to simply send messages to Kafka. You need to choose a combination of parameters and be prepared to make quick changes. In this article, I aimed to detail the configuration of exactly-once delivery and described some issues with the client.id and transactional.id configurations that we encountered. Below are the configurations for Producer and Consumer in brief.
Producer:
- acks = all
- retries > 0
- enable.idempotence = true
- max.in.flight.requests.per.connection ≤ 5 (1 for ordered sending)
- transactional.id = ${application-name}-${hostname}
Consumer:
- isolation.level = read_committed
To minimize errors in future applications, we created our wrapper over the spring configuration, where values for some of the mentioned parameters are already set.
And here are a couple of materials for self-study:
Source: habr.com
