

My name is Anton Baderin. I work at the High Technology Center and focus on system administration. A month ago, we completed our corporate conference where we shared accumulated knowledge with the IT community in our city. I spoke about web application monitoring. The material was aimed at junior or mid-level professionals who haven't built this process from scratch.
The cornerstone of any monitoring system is solving business problems. Monitoring for the sake of monitoring is of no interest to anyone. What does business want? For everything to run quickly and without errors. Business wants proactivity, so that we identify issues in service performance ourselves and resolve them as quickly as possible. This is essentially what I focused on all of last year in a project for one of our clients.
About the Project
The project is one of the largest loyalty programs in the country. We help retail chains increase sales frequency through various marketing tools such as bonus cards. In total, the project includes 14 applications running on ten servers.
During interviews, I repeatedly noticed that admins do not always approach web application monitoring correctly: many still focus on operating system metrics and occasionally monitor services.
In my case, the client's previous monitoring system was based on Icinga. It did not address the aforementioned issues. Often, the client would inform us of problems, and just as often, we lacked the data needed to get to the root cause.
Additionally, there was a clear understanding of the futility of its further development. I believe those familiar with Icinga will understand me. So, we decided to completely redesign the web application monitoring system for the project.
Prometheus
We chose Prometheus based on three main criteria:
- A vast number of available metrics. In our case, there are 60,000. Of course, it's worth noting that the overwhelming majority of them are not in use (probably around 95%). On the other hand, they are all relatively inexpensive. For us, this is quite different compared to the previously used Icinga. Adding metrics in that system was particularly painful: the existing ones were costly (just take a look at the source code of any plugin). Each plugin was a script in Bash or Python, the execution of which is not cheap in terms of resource consumption.
- This system consumes a relatively small amount of resources. All our metrics fit within 600 MB of RAM, 15% of one core, and a few dozen IOPS. Of course, we have to run metric exporters, but they are all written in Go and are not resource-hungry either. I don't think this is a problem in today's realities.
- Allows for a transition to Kubernetes. Given the client's plans, the choice is obvious.
ELK
Previously, we did not collect or process logs. The downsides are clear to everyone. We chose ELK because we already had experience working with this system. We only store application logs there. The main selection criteria were full-text search and its speed.
Clickhouse
Initially, we chose InfluxDB. We recognized the need to collect Nginx logs, statistics from pg_stat_statements, and store historical data from Prometheus. We didn't like Influx as it periodically started consuming large amounts of memory and would crash. Additionally, we wanted to group requests by remote_addr, but grouping in this database was only by tags. Tags are expensive (in terms of memory), and their number is conditionally limited.
We started the search anew. We needed an analytical database with minimal resource consumption, ideally with data compression on disk.
Clickhouse meets all these criteria, and we have never regretted our choice. We do not write remarkable volumes of data into it (the number of inserts is only about five thousand per minute).
NewRelic
NewRelic has historically been with us, as it was the client's choice. We use it as APM.
Zabbix
We use Zabbix exclusively for monitoring the Black Box of various APIs.
Defining the approach to monitoring
We wanted to decompose the task and thus systematize the approach to monitoring.
To achieve this, I divided our system into the following levels:
- "hardware" and VMS;
- operating system;
- system services, software stack;
- application;
- business logic.
The advantage of this approach is:
- we know who is responsible for the operation of each level, and based on that, we can send alerts;
- we can utilize the structure when suppressing alerts — it would be strange to send an alert about database unavailability when the entire virtual machine is inaccessible.
Since our task is to identify issues in system performance, we need to highlight a set of metrics at each level to focus on when writing alerting rules. Next, we'll go through the ‘VMS’, ‘Operating System’, and ‘System Services, Software Stack’ levels.
Virtual machines
Hosting allocates processor, disk, memory, and network for us. And we had issues with the first two. So, the metrics are:
CPU stolen time — when you buy a virtual machine on Amazon (like t2.micro, for instance), it’s essential to understand that you’re not allocated a whole core of the processor but only a quota of its time. When you exhaust this quota, your processor time will start to be taken away.
This metric allows tracking such moments and making decisions. For example, you may need to choose a more robust plan or separate background task processing and API requests into different channels. server.
IOPS + CPU iowait time — for some reason, many cloud hosting services tend to under-provision IOPS. Moreover, a graph showing low IOPS is not a convincing argument for them. Therefore, it's worthwhile to collect CPU iowait as well. With this pair of graphs — showing low IOPS and high I/O wait — you can start negotiations with the hosting provider to resolve the issue.
Operating system
Operating system metrics include:
- available memory in %;
- swap usage activity: vmstat swapin, swapout;
- available inodes and free space in the file system in %
- average load;
- number of connections in state tw;
- fill level of the conntrack table;
- network performance can be monitored using the ss utility from the iproute2 package — getting the RTT connection indicator from its output and grouping by destination port.
Additionally, at the level of the operating system, we have an entity known as processes. It’s important to identify a set of processes in the system that play a critical role in its functioning. For example, if you have several pgpool instances, you need to gather information on each of them.
The set of metrics is as follows:
- CPU;
- Memory primarily refers to resident memory;
- IO — preferably in IOPS;
- FileFd — open and limit;
- Significant page failures — this will help you understand which process is being swapped.
All our monitoring is deployed in Docker, and we use cAdvisor for collecting metric data. On other machines, we apply process-exporter.
System services, software stack
Each application has its own specifics, and it's difficult to pinpoint a set of metrics.
A universal set includes:
- request rate;
- error count;
- latency;
- saturation.
The most notable examples of this level of monitoring for us are Nginx and PostgreSQL.
The most overloaded service in our system is the database. Previously, we frequently encountered issues in figuring out what the database was doing.
We saw high disk load, but slow logs didn’t tell us much. We solved this problem using pg_stat_statements, a view that collects query statistics.
That's all an admin needs.
We build graphs of read and write request activity:
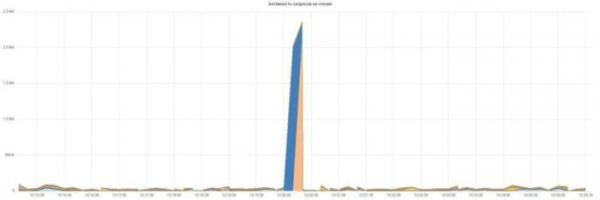
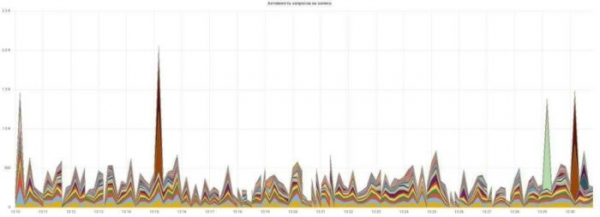
It's simple and clear, each request has its own color.
Another vivid example is the Nginx logs. It's no surprise that few parse them or mention them in mandatory lists. The standard format isn’t very informative and needs to be extended.
Personally, I added request_time, upstream_response_time, body_bytes_sent, request_length, request_id. We build graphs of response times and error counts:
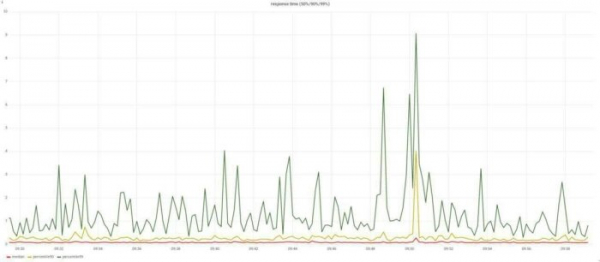
We build graphs of response times and error counts. Remember? I mentioned business tasks? To be quick and error-free? We already covered those issues with two graphs. Based on these, we can call on-duty admins.
But there’s still one problem left — ensuring a quick resolution of the incident causes.
Incident resolution
The entire process from detection to resolution can be broken down into a series of steps:
- problem identification;
- notifying the on-duty administrator;
- responding to the incident;
- eliminating the causes.
It's important that we do this as quickly as possible. And while we can't save much time at the stages of problem identification and notification — they will take two minutes anyway, the subsequent stages are a completely untapped field for improvement.
Let's just imagine that the duty officer received a phone call. What will he do? Look for answers to questions — what broke, where it broke, how to respond? This is how we answer these questions:
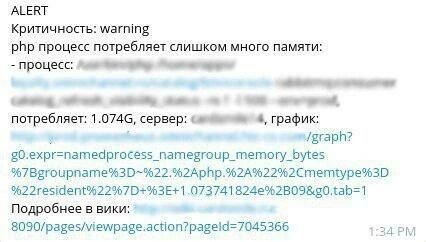
We simply include all this information in the notification text, providing a link to the wiki page that describes how to respond to this issue, how to resolve it, and escalate it.
I still haven't said anything about the application level and business logic. Unfortunately, our applications do not yet implement metric collection. The only source of any information from these levels is the logs.
A couple of points.
Firstly, write structured logs. Do not include context in the message text. This complicates their grouping and analysis. Logstash takes a lot of time to normalize all this.
Secondly, use severity levels correctly. Each language has its own standard. Personally, I distinguish four levels:
- no error;
- client-side error;
- server-side error without loss of money, no risks incurred;
- server-side error with loss of money.
To summarize. We should try to build monitoring from the business logic perspective. We need to monitor the application itself and operate with metrics such as the number of sales, the number of new user registrations, the number of active users at the moment, and so on.
If your entire business is a single button in a browser, you need to monitor whether it is being clicked and if it is working properly. Everything else is not important.
If you do not have this, you can try to catch up with logs from the application, Nginx logs, and so on, as we have done. You need to be as close to the application as possible.
Operating system metrics are certainly important, but they are not interesting to the business; we are not paid for them.
Source: habr.com
