

Introduction
It's time to buy a storage system. Which one to choose, and whose advice to follow? Vendor A talks about vendor B, while there is also integrator C, who tells the opposite and recommends vendor D. In such a situation, even an experienced storage architect might feel overwhelmed, especially with all the new vendors and the currently popular SDS and hyper-convergence.
So, how do we make sense of all this and avoid being misled? We ( Anton Zhbankov and Evgeny Elizаров) will try to explain this in plain language.
This article largely overlaps and effectively expands on “” in terms of choosing storage systems and reviewing storage technologies. We will briefly cover the general theory but recommend reading the mentioned article as well.
Why
It is common to see a new person coming to a forum or a specialized chat, like Storage Discussions, asking a question: “I have two options for storage systems — ABC SuperStorage S600 and XYZ HyperOcean 666v4, which one do you suggest?”
And the discussion starts about whose implementation has which frightening and confusing features that for an unprepared person look like Chinese.
So, the key and first question to ask yourself long before comparing specifications in commercial offers is — WHY? Why do you need this storage system?
The answer may be surprising and very much in the style of Tony Robbins — to store data. Thank you, Captain! However, sometimes we get so deep into comparing details that we forget why we are doing all this in the first place.
Thus, the task of a data storage system is to store and provide access to DATA with a specified performance. This is where we will start.
Data
Type of data
What data do we plan to store? This is a crucial question that may eliminate many storage systems from consideration. For example, if we plan to store video recordings and photographs, we can immediately exclude systems designed for random access with small blocks or those with proprietary features for compression or deduplication. These can be excellent systems, and we don't mean to speak ill of them. However, in this case, their strengths might become weaknesses (video and photo files are not compressible) or simply significantly increase the cost of the system.
Conversely, if the intended use is a heavily loaded transactional database, excellent streaming systems for multimedia capable of delivering gigabytes per second would be a poor choice.
Data Volume
How much data do we plan to store? Quantity always transforms into quality; this should never be forgotten, especially in our time of exponential data growth. Petabyte-class systems are no longer rare, but the larger the petabyte volume, the more specialized the system becomes, and the less familiar functionality of small to medium-sized random access systems will be available. Simply put, just the access statistics tables for blocks become larger than the available memory on controllers. Not to mention compression or tiering. Let's assume we want to switch to a more powerful compression algorithm and compress 20 petabytes of data. How long will that take: six months, a year?
On the other hand, why build an expansive system if we need to store and process just 500 GB of data? Just 500. Consumer SSDs (with low DWPD) of that size are quite affordable. Why build a Fiber Channel factory and purchase a high-class external storage system that costs as much as a small fortune?
What percentage of the total volume is hot data? How uneven is the load across the data volume? Here, multi-tier storage technology or Flash Cache can be very helpful if the hot data volume is negligible compared to the total. Conversely, if the load is uniform across the entire volume, often found in streaming systems (such as video surveillance or certain analytics systems), such technologies will provide no benefit and will only increase the cost or complexity of the system.
IS
The flip side of the data is the information system that utilizes this data. The information system has a set of requirements that the data inherits. For more details on IS, see "Design of a Virtualized Data Center."
Requirements for fault tolerance / availability
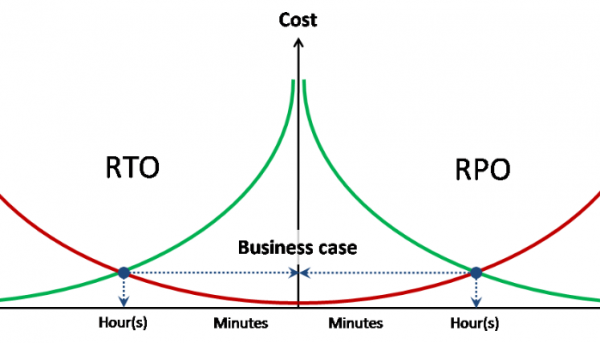
Data fault tolerance / availability requirements are inherited from the information systems that use them and are expressed in three numbers — RPO, RTO, availability.
All exploit scenarios related to attack vectors on — the percentage of time during which data is available for use within a specified period. This is usually expressed in terms of nines. For example, two nines in a year means that availability equals 99%, or alternatively, allows for 95 hours of downtime per year. Three nines equate to 9.5 hours per year.
RPO / RTO — these metrics are not cumulative; they apply to each incident (failure), unlike availability.
RPO — the amount of data lost during a failure (in hours). For example, if backups are performed once a day, then RPO = 24 hours. This means that, in the event of a failure and complete loss of the storage system, data amounting to up to 24 hours (from the last backup) could be lost. Based on the specified RPO for the information system, backup regulations are written. Additionally, based on RPO, one can determine the necessity of synchronous / asynchronous data replication.
RTO — the time taken to restore the service (access to data) after a failure. Based on the specified RTO value, we can determine if a metro cluster is needed or if unidirectional replication is sufficient. We can also assess whether a high-end, multi-controller storage system is necessary.
Performance requirements
Although this seems like an obvious question, this is where most difficulties arise. Depending on whether you already have some infrastructure in place or not, it will determine how the necessary statistics will be collected.
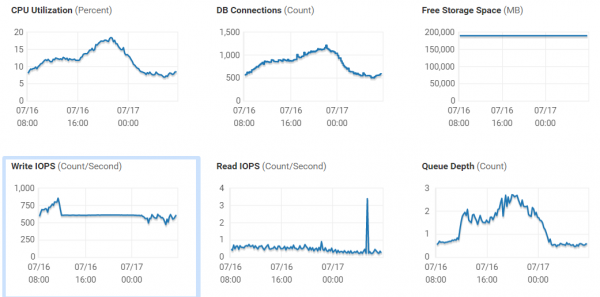
You already have a storage system and are looking for a replacement or want to acquire another one for expansion. It’s straightforward. You understand what services you currently have and which ones you plan to implement in the near future. Based on your current services, you can gather performance statistics. Determine the current number of IOPS and current latencies — what are these metrics and are they sufficient for your tasks? This can be assessed both from the storage system itself and from the hosts connected to it.
Furthermore, you need to look not just at the current load but over a certain period (preferably a month). Examine what the maximum peaks are during the day, what load is generated by backups, etc. If your storage system or its software does not provide you with a complete set of this data, you can use the free RRDtool, which can work with most popular storage systems and switches and will be able to provide you with detailed performance statistics. It’s also worth monitoring the load on the hosts that work with this storage, focusing on specific virtual machines or what exactly is operating on a given host.
It is important to note that if the latencies on the volume and the datastore located on that volume differ significantly, you should pay attention to your SAN network; there is a high likelihood that there are issues with it. Before purchasing a new system, it would be prudent to address this matter, as there is a strong possibility of increasing the performance of your current system.
You are building infrastructure from scratch or acquiring a system for a new service, the load of which you are not familiar with. There are several options here: communicate with colleagues on specialized resources to try to learn and forecast the load, reach out to an integrator who has experience implementing similar services and who can calculate the load for you. The third option (usually the most complex, especially when it concerns custom or rare applications) is to try to clarify performance requirements with the system developers.
And, attention, the most appropriate option from a practical application standpoint is a pilot on current equipment or equipment provided for testing by the vendor/integrator.
Special requirements
Special requirements refer to everything that does not fall under the performance, fault tolerance, and functionality requirements for direct data processing and delivery.
One of the simplest special requirements for a data storage system can be described as 'removable information carriers.' It is immediately clear that this data storage system must include a tape library or simply a streamer, where a backup is stored. After that, a specially trained person labels the tape and proudly carries it to a special safe.
Another example of a special requirement is shockproof protection.
Where
The second key component in choosing a data storage system is information about WHERE this data storage system will be located. This includes everything from geography or climatic conditions to personnel.
Customer
Who is this data storage system intended for? This question is based on the following grounds:
State customer/commercial.
A commercial customer has no restrictions and is not even required to hold tenders, except according to its internal regulations.
A state customer is a different matter. 44 FZ and other intricacies with tenders and specifications that can be contested.
Customer under sanctions
Well, here the question is very simple — the choice is limited only to the offers available for this customer.
Internal regulations/approved vendors/models
This question is also very straightforward, but it's important to remember.
Where physically
In this section, we consider all questions regarding geography, communication channels, and microclimate in the placement premises.
Personnel
Who will work with this data storage system? This is no less important than what the data storage system can actually do.
No matter how promising, cool, and wonderful the data storage system from vendor A may be, it probably makes little sense to install it if the personnel only knows how to work with vendor B, and no further purchases or ongoing collaboration with A are planned.
And of course, the flip side of the question is how available trained personnel is in this geographical location, both within the company and potentially in the labor market. For regions, it can significantly matter to choose a storage system with simple interfaces or the ability for remote centralized management. Otherwise, at some point, it can become painfully difficult. The internet is full of stories about how a new employee, just yesterday's student, misconfigured something so that the whole company collapsed.
Environment
And of course, an important question is what environment this storage system will operate in.
- What about power supply / cooling?
- What kind of connection?
- Where will it be installed?
- And so on.
Often, these questions are taken for granted and not particularly considered, but sometimes they can turn everything upside down.
What?
Vendor
As of today (mid-2019), the Russian storage market can be divided into approximately 5 categories:
- Top division — reputable companies with a wide range from the simplest disk shelves to hi-end (HPE, DellEMC, Hitachi, NetApp, IBM / Lenovo)
- Second division — companies with a limited lineup, niche players, serious SDS vendors, or emerging newcomers (Fujitsu, Datacore, Infinidat, Huawei, Pure, etc.)
- Third division — niche solutions in the low-end range, cheap SDS, DIY products based on Ceph and other open projects (Infortrend, Starwind, etc.)
- SOHO segment — small and ultra-small storage systems suitable for home/small office (Synology, QNAP, etc.)
- Import-substituted storage systems — this includes both first division hardware with rebranded labels, as well as rare representatives from the second (RAIDIX, we briefly give them the second), but mainly this is the third division (Aerodisk, Baum, Depo, etc.)
The division is quite conditional and does not mean at all that the third or SOHO segments are poor and cannot be used. In specific projects with a clearly defined data set and workload profile, they can perform very well, far surpassing the first division in terms of price/quality ratio. It’s important to first determine the tasks, growth prospects, required functionality — and then Synology will serve you faithfully, while your hair will become soft and silky.
One of the important factors when choosing a vendor is the current environment. How many and which storage systems do you already have, and what storage systems can your engineers work with? Do you need another vendor, another point of contact, and will you be gradually migrating all the load from vendor A to vendor B?
One should not create entities beyond necessity.
iSCSI / FC / File
There is no consensus among engineers regarding access protocols, and the debates resemble more theological discussions than engineering ones. However, the following points can generally be noted:
FCoE is rather dead than alive.
FC vs iSCSIOne of the key advantages of FC in 2019 over IP storage systems, a dedicated fabric for data access, is neutralized by a dedicated IP network. There are no global advantages of FC over IP networks, and storage systems of any load level can be built on IP, even for heavy DBMS systems for large banks. On the other hand, the death of FC has been predicted for several years, but something always seems to hinder this. For example, currently, some players in the storage market are actively developing the NVMe over Fabrics standard. Whether it will divide the fate of FCoE remains to be seen.
File access is also not something unworthy of attention. NFS / CIFS perform excellently in productive environments and, with proper design, have no more complaints than block protocols.
Hybrid / All Flash Array
Classic storage systems come in 2 types:
- AFA (All Flash Array) — systems optimized for SSD usage.
- Hybrid — allowing the use of both HDDs and SSDs or their combination.
The main difference lies in the supported storage efficiency technologies and the maximum performance level (high IOPS and low latency). Both systems (in most of their models, excluding the low-end segment) can function as both block devices and file systems. The level of the system influences both the supported functionality and, in the case of lower models, this functionality is often limited to a minimal level. This is important to note when examining the specifications of a particular model, rather than just the capabilities of the entire line as a whole. Of course, the level of the system also affects its technical characteristics, such as the processor, memory volume, cache, number and types of ports, etc. From a management perspective, AFA systems differ from hybrid (disk) systems only in the ways they implement SSD interaction mechanisms, and even if you use SSDs in a hybrid system, it does not mean you will achieve performance levels comparable to an AFA system. Additionally, in most cases, inline mechanisms for efficient storage on hybrid systems are disabled, and enabling them leads to a drop in performance.
Specialized Storage Systems
In addition to general-purpose storage systems, primarily designed for real-time data processing, there are specialized storage systems with key principles fundamentally different from the usual ones (low latency, high IOPS):
Media.
These systems are designed for the storage and processing of media files that are characterized by large sizes. Therefore, latency becomes almost irrelevant, while the ability to send and receive data at high bandwidth in multiple parallel streams takes precedence.
Deduplication Storage Systems for Backups.
Since backups typically share little similarity with one another (an average backup differs from yesterday's by 1-2%), this class of systems very effectively packages the data stored on them within a relatively small number of physical media. For example, in some cases, data compression ratios can reach 200 to 1.
Object Storage Systems.
These storage systems do not have conventional blocks with block access and file shares; rather, they resemble a huge database. Access to an object stored in such a system is conducted via a unique identifier or by metadata (for example, all JPEG objects created between XX-XX-XXXX and YY-YY-YYYY).
Compliance systems.
They are not very common in Russia today, but they are worth mentioning. The purpose of such storage systems is guaranteed data storage to comply with security policies or regulatory requirements. In some systems (such as EMC Centera), a function has been implemented that prohibits data deletion—once the key is turned and the system switches to this mode, neither the administrator nor anyone else can physically delete already recorded data.
Proprietary technologies
Flash cache
Flash Cache is a general term for all proprietary technologies that use flash memory as a second-level cache. When using flash cache, the storage system is typically designed to handle the established load from magnetic disks, while peak loads are managed by the cache.
It is important to understand the load profile and the degree of localization of accesses to the storage volume blocks. Flash cache is a technology for workloads with high request localization and is practically not applicable for evenly loaded volumes (as in analytical systems).
Two implementations of flash cache are available on the market:
- Read Only. In this case, only read data is cached, while writes go directly to the disks. Some manufacturers, such as NetApp, believe that writes to their storage systems are already optimally managed, and caching does not help.
- Read/Write. Not only reading but also writing is cached, which allows buffering the stream and reduces RAID Penalty impact, consequently improving overall performance for storage systems with less optimal writing mechanisms.
Tiering
Multi-tier storage (tiering) is a technology that combines different performance levels, such as SSD and HDD, into a single disk pool. In cases of pronounced uneven access to data blocks, the system can automatically rebalance the data blocks by moving the loaded ones to a high-performance level while moving the colder ones to a slower level.
Hybrid systems of the lower and mid-range classes use tiered storage with data movement between levels on a schedule. The block size of tiered storage in the best models is 256 MB. These characteristics do not allow the tiered storage technology to be considered a performance-enhancing technology, as is mistakenly believed by many. Tiered storage in lower and mid-range systems is a cost optimization technology for systems with pronounced uneven load.
Snapshot
No matter how much we talk about the reliability of storage systems, there are many ways to lose data that are not dependent on hardware issues. These can include viruses, hackers, or any other unintentional deletion/corruption of data. For this reason, backing up productive data is an essential part of an engineer's job.
A snapshot is a snapshot of a volume at a certain point in time. When working with most systems, such as virtualization, databases, etc., we need to take such a snapshot from which we will copy data for backup, while our IS can continue to operate normally with this volume. However, it's important to remember that not all snapshots are equally useful. Different vendors have different approaches to creating snapshots, depending on their architecture.
CoW (Copy-On-Write). When attempting to write to a data block, its original content is copied to a special area, after which the write operation proceeds normally. This prevents data corruption within the snapshot. Naturally, all these "parasitic" manipulations with data put an additional load on the storage system, which is why vendors with such implementations do not recommend using more than a dozen snapshots, and in highly loaded volumes, not to use them at all.
RoW (Redirect-On-Write). In this case, the original volume is naturally frozen, and when attempting to write to a data block, the storage system writes the data to a special area in free space, changing the location of this block in the metadata table. This helps reduce the number of overwrite operations, ultimately alleviating performance degradation and lifting restrictions on snapshots and their quantity.
Snapshots also come in two types with respect to applications:
Application consistent. At the time of snapshot creation, the storage system triggers an agent in the consumer's operating system, which forces disk caches to be flushed from memory to disk and compels the application to do so. In this case, when restoring from a snapshot, the data will be consistent.
Crash consistentIn this case, nothing similar happens, and the snapshot is created as it is. When recovering from such a snapshot, the situation is identical to if the power was suddenly turned off, and some data that was stuck in caches and did not reach the disk may be lost. Such snapshots are easier to implement and do not cause performance drops in applications but are less reliable.
What are snapshots used for in storage systems?
- Agentless backup directly from storage systems
- Creating test environments based on real data
- In the case of file storage systems, it can be used to create VDI environments by using snapshots of the storage system instead of a hypervisor.
- Ensuring low RPO by creating snapshots on a schedule with a frequency significantly higher than that of backups.
Cloning
Volume cloning works on a similar principle to snapshots, but it serves not just for reading data but for full interaction with it. We can obtain an exact copy of our volume, with all data on it, without making a physical copy, thus saving space. Usually, volume cloning is used in Test & Dev scenarios or if you want to test the functionality of some updates on your information system. Cloning allows for this to be done as quickly and economically as possible in terms of disk resources, as only the modified data blocks will be written.
Replication / Journaling
Replication is the mechanism for creating a copy of data on another physical storage system. Typically, each vendor has its proprietary technology that works only within its own product line. However, there are also third-party solutions, including those that operate at the hypervisor level, such as VMware vSphere Replication.
The functionality of proprietary technologies and their ease of use usually far exceed those of universal solutions, but they become impractical when, for instance, it is necessary to create a replica from NetApp to HP MSA.
Replication is divided into two subtypes:
SynchronousIn the case of synchronous replication, the write operation is immediately sent to the secondary storage system and is not confirmed until the remote storage system acknowledges it. This increases access latency, but we get an exact mirror copy of the data. That is, RPO = 0 in the event of a loss of the primary storage system.
Asynchronous. Write operations are executed only on the primary storage system and confirmed immediately, while being accumulated in a buffer for batch transfer to the remote storage system. This type of replication is suitable for less critical data or for channels with low bandwidth or high latency (typical for distances over 100 km). Accordingly, RPO = batch sending frequency.
Often, along with replication, there exists a mechanism for logging disk operations. In this case, a special area is allocated for logging, storing write operations for a certain depth in time, or limited by the size of the log. For specific proprietary technologies, such as EMC RecoverPoint, there is integration with system software that allows binding specific bookmarks to a particular record in the log. This enables rolling back the state of a volume (or creating a clone) not just to April 23 at 11:59:13.013, but to a moment that preceded "DROP ALL TABLES; COMMIT".
Metro cluster
A metro cluster is a technology that allows the creation of bidirectional synchronous replication between two storage systems so that on one side this pair appears as a single storage system. It is used to create clusters with geographically dispersed links over metro distances (less than 100 km).
In the context of virtualization, a metro cluster allows the creation of a datastore with virtual machines that is writable from two data centers at once. In this case, a cluster is formed at the hypervisor level, consisting of hosts in different physical data centers, connected to this datastore. This enables the following:
- Full automation of the recovery process after the failure of one of the data centers. Without any additional tools, all VMs that were operating in the failed data center will be automatically restarted in the remaining one. RTO = high availability cluster timeout (15 seconds for VMware) + operating system boot time and service startup.
- Disaster avoidance, or in Russian, avoiding disasters. If scheduled power works are planned in data center 1, we have the opportunity to migrate all critical loads to data center 2 non-stop before the work begins.
Virtualization
Storage virtualization is technically using volumes from another storage system as disks. The storage virtualizer can simply present a foreign volume to the consumer as its own while mirroring it to another storage system, or even create a RAID from external volumes.
Classic representatives in the storage virtualization class are EMC VPLEX and IBM SVC. And naturally, storage systems with virtualization features include NetApp, Hitachi, and IBM/Lenovo Storwize.
Why might this be needed?
- Redundancy at the storage level. A mirror is created between volumes, with one half potentially on HP 3Par and the other on NetApp. And the virtualizer from EMC.
- Data migration with minimal downtime between storage systems from different manufacturers. Suppose we need to migrate data from an old 3Par, which will be decommissioned, to a new Dell. In this case, consumers are disconnected from 3Par, volumes are presented under VPLEX, and are then re-presented to consumers anew. Since no bits on the volume have changed, the operation continues. Meanwhile, a process for mirroring the volume to the new Dell starts in the background, and upon completion, the mirror is broken, and 3Par is turned off.
- Metro cluster organization.
Compression / deduplication
Compression and deduplication are technologies that allow you to save disk space on your storage system. It’s important to mention that not all data can be compressed and/or deduplicated in principle, as some types of data compress and deduplicate better, while others do the opposite.
Compression and deduplication come in two forms:
Inline Data compression and deduplication occur before the data is written to disk. Thus, the system only calculates the hash of the block and compares it against the existing table. Firstly, this is done faster than just writing to disk, and secondly, we do not waste extra disk space.
Post When these operations are performed on already written data that is on disks. Accordingly, the data is first written to the disk, and only then is the hash calculated, and unnecessary blocks are deleted, freeing up disk resources.
It should be noted that most vendors use both types, which allows for optimizing these processes and thus enhancing their efficiency. Most storage system vendors have utilities that can analyze your data sets. These utilities operate on the same logic as implemented in the storage system, so the estimated efficiency level will match. Furthermore, many vendors have efficiency guarantee programs that promise a level no lower than stated for certain (or all) data types. It is essential not to overlook this program; by designing a system tailored to your needs considering the efficiency coefficient of a specific system, you may save on volume. It's also worth noting that these programs are designed for AFA systems, but due to the purchase of a smaller volume of SSD compared to HDD in traditional systems, this allows for a decrease in cost, and while it may not equal the cost of disk systems, it can get quite close.
Model
And here we arrive at the correctly posed question.
“I am being offered two options for storage systems — ABC SuperStorage S600 and XYZ HyperOcean 666v4, which one would you recommend?”
It turns into “I am being offered two options for storage systems — ABC SuperStorage S600 and XYZ HyperOcean 666v4, which one would you recommend?
The target load is mixed VMware virtual machines from productive/test/development environments. Test = production. 150 TB for each with peak performance of 80,000 IOPS with 8kb block size at 50% random access, 80/20 read-write. 300 TB for development, where 50,000 IOPS will suffice, with 80 random, 80 write.
Production is supposedly in a metro cluster with RPO = 15 minutes, RTO = 1 hour, development in asynchronous replication with RPO = 3 hours, and testing on one site.
There will be a 50TB database, it would be good to have logging for them.
We have Dell servers everywhere, the old Hitachi storage systems are barely keeping up. We are planning a 50% increase in load in terms of volume and performance.
As they say, in a properly formulated question lies 80% of the answer.
Additional information
What is worth reviewing additionally according to the authors.
Books
- Oliefer and Oliefer 'Computer Networks'. This book will help to systematize and possibly better understand how data transmission environments for IP/Ethernet storage systems work.
- 'EMC Information Storage and Management'. A great book on the basics of storage systems, why, how, and why.
Forums and Chats
General recommendations
Prices
Now, regarding prices — regarding storage systems, if prices are found, they are usually list prices from which each customer receives individual discounts. The size of the discount is made up of a large number of parameters, so predicting what final price your company will receive without inquiry to the distributor is simply impossible. However, recently, low-end models have begun appearing in regular computer stores, such as, for example, or . Here you can immediately purchase the system you’re interested in at a fixed price, just like any computer components.
But I want to point out right away that directly comparing by TB/$ is not correct. If approached from this perspective, the cheapest solution would be a simple JBOD + server, which will not provide the flexibility or reliability that a full, dual-controller storage system offers. This does not mean that JBOD is a bad solution; you just need to clearly understand how and for what purposes you will use this solution. You often hear that in JBOD there is nothing to fail, as there is only one backplane. However, even backplanes can fail. Everything breaks down eventually.
Total
Systems should be compared not only by price or performance, but by the overall combination of all indicators.
Purchase HDDs only if you are sure you need them. For low workloads and non-compressible data types, you should consider the efficiency guarantee programs for SSD storage that most vendors now offer (and they really work, even in Russia), but it all depends on the applications and data that will be stored on this storage system.
Don't chase after cheapness. Often, this hides many unpleasant moments, one of which Evgeny Elizаров described in his articles about . And ultimately, this cheapness may cost you more in the long run. Remember — "a miser pays twice."
Source: habr.com
