

Some time ago, we faced the question of choosing an ETL tool for working with Big Data. The previously used solution, Informatica BDM, did not meet our needs due to its limited functionality. Its use boiled down to a framework for launching spark-submit commands. There weren't many alternatives on the market that could handle the volume of data we deal with every day. Ultimately, we chose Ab Initio. During pilot demonstrations, the product showed very high data processing speeds. There is almost no information about Ab Initio in Russian, so we decided to share our experience on Habr.
Ab Initio has many classical and unique transformations, the code for which can be extended using its own PDL language. For small businesses, such a powerful tool may be excessive, and many of its features might prove costly and unnecessary. However, if your scale approaches that of a large enterprise, Ab Initio could be of interest to you.
It helps businesses globally accumulate knowledge and develop ecosystems, while allowing developers to enhance their ETL skills, improve their shell knowledge, master the PDL language, provide a visual representation of loading processes, and simplify development through a wealth of functional components.
In this post, I will discuss the capabilities of Ab Initio and provide comparative characteristics of its performance with Hive and GreenPlum.
- Description of the MDW framework and work on its fine-tuning for GreenPlum.
- Comparative performance characteristics of Ab Initio working with Hive and GreenPlum.
- Ab Initio's operation with GreenPlum in Near Real Time mode.
The functionalities of this product are extensive and require considerable time to study. However, with the right skills and proper performance settings, the results of data processing can be quite impressive. Using Ab Initio can provide developers with a valuable experience. It offers a fresh perspective on ETL development, blending visual environments with script-like language loading.
Businesses are developing their ecosystems, and this tool is more relevant than ever. With Ab Initio, one can accumulate knowledge about the current business and utilize that knowledge to expand existing operations and open new ones. Alternatives to Ab Initio include visual development environments like Informatica BDM and non-visual environments like Apache Spark.
Ab Initio Description
Ab Initio, like other ETL tools, is a suite of products.
Ab Initio GDE (Graphical Development Environment) is a developer environment where transformations are configured and connected through data streams represented as arrows. Such a collection of transformations is referred to as a graph:
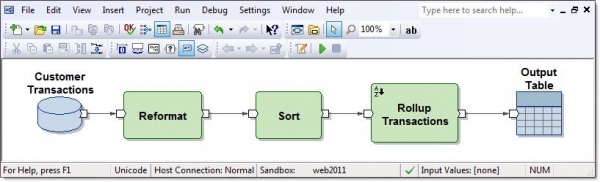
Input and output connections of functional components are ports and contain fields computed within transformations. Several graphs connected by streams in sequential order are called a plan.
There are several hundred functional components, which is a substantial number. Many of them are highly specialized. The capabilities of classic transformations in Ab Initio are broader than in other ETL tools. For example, Join has multiple outputs. In addition to the result of joining datasets, it is possible to output records from the input datasets that could not be joined by keys. It is also possible to obtain rejects, errors, and the log of the transformation, which can be read as a text file and processed by other transformations within the same graph:
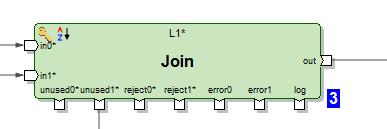
Or, for instance, one can materialize a data sink as a table and read data from it in the same graph.
There are original transformations as well. For example, the Scan transformation functions similarly to analytic functions. There are transformations with descriptive names: Create Data, Read Excel, Normalize, Sort within Groups, Run Program, Run SQL, Join with DB, and others. Graphs can use runtime parameters, including the ability to pass parameters from the operating system or to the operating system. Files containing a prepared set of parameters for the graph are called parameter sets (psets).
As expected, Ab Initio GDE has its own repository, known as EME (Enterprise Meta Environment). Developers have the option to work with local versions of the code and check in their developments to the central repository.
You can click on any transformation connection in the graph during or after execution to view the data that has passed between these transformations.
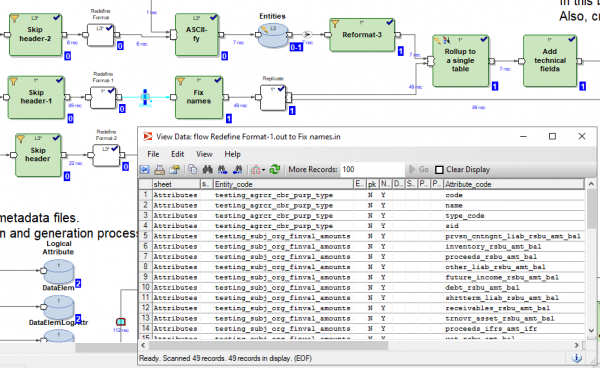
You can also click on any stream to see tracking details — including how many parallel instances the transformation operated in, how many rows and bytes were loaded in each of the parallels.
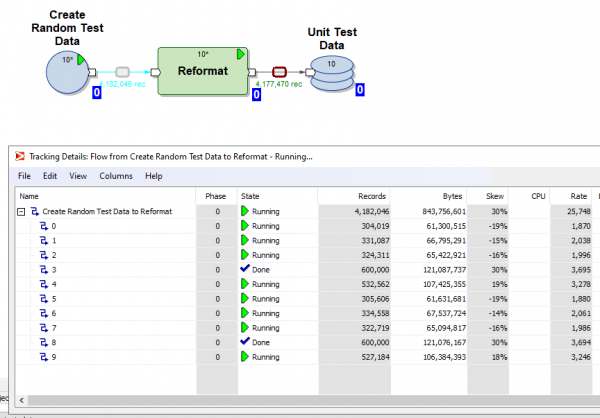
It is possible to break the execution of the graph into phases and mark which transformations need to be executed first (in phase zero), followed by others in the first phase, then in the second phase, and so on.
For each transformation, you can select what is known as a layout (where it will run): either without parallels or in parallel streams, the number of which can be specified. Temporary files that Ab Initio creates during the operation of transformations can be placed in both the file system server, and in HDFS.
In each transformation based on the default template, you can create your own script in the PDL language, which resembles shell scripting.
With the PDL language, you can extend the functionality of transformations and, in particular, you can dynamically (at runtime) generate arbitrary code fragments depending on runtime parameters.
Ab Initio also has well-developed integration with the OS via shell. Specifically, Linux ksh is used at Sberbank. You can exchange variables with the shell and use them as graph parameters. You can invoke the execution of Ab Initio graphs from the shell and administer Ab Initio.
In addition to Ab Initio GDE, many other products are included in the delivery. There is a Co>Operation System that claims to be an operating system. There is a Control>Center, where you can schedule and monitor data loading streams. There are products for development at a more primitive level than what Ab Initio GDE allows.
Description of the MDW framework and work on its fine-tuning for GreenPlum.
Along with its products, the vendor provides the MDW (Metadata Driven Warehouse) product, which is a graph configurator designed to assist with typical tasks related to populating data warehouses or data vaults.
It contains user-specific (project-specific) metadata parsers and ready-made code generators 'out of the box.'
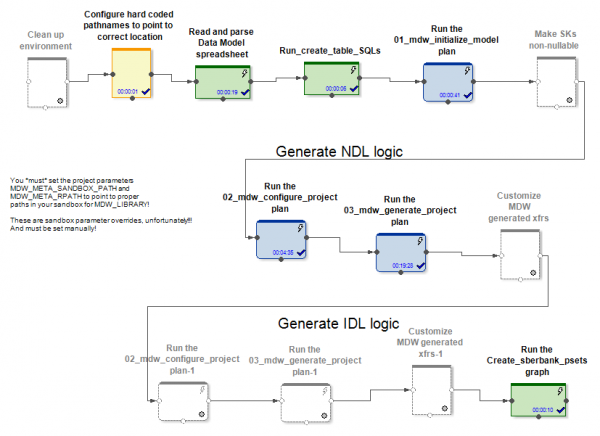
At the input, MDW receives a data model, a configuration file for database connection settings (Oracle, Teradata, or Hive), and some other settings. The project-specific part, for example, deploys the model in the database. The out-of-the-box part of the product generates graphs and configuration files for them based on loading data into the model tables. In this process, graphs (and psets) are created for several modes of initializing and incrementally updating entities.
In the cases of Hive and RDBMS, different graphs are generated for initializing and incrementally updating data.
In the case of Hive, the incoming delta data is joined using Ab Initio Join with the data that was in the table before the update. The data loaders in MDW (both in Hive and RDBMS) not only insert new data from the delta but also close the validity periods of the data by the primary keys for which the delta was received. Additionally, it may be necessary to rewrite the unchanged part of the data. However, this is necessary because Hive does not support delete or update operations.
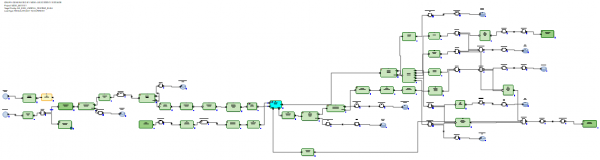
In the case of RDBMS, graphs for incremental data updates appear more optimal, as RDBMS have real update capabilities.
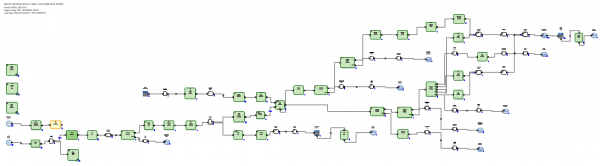
The incoming delta is loaded into a temporary table in the database. After that, the delta is joined with the data that was in the table before the update. This is done using SQL via a generated SQL query. Then, with SQL commands delete+insert, new data from the delta is inserted into the target table, and the validity periods of the data whose primary keys received the delta are closed.
There is no need to rewrite unchanged data.
Thus, we conclude that in the case of Hive, MDW must resort to rewriting the entire table because Hive lacks update functionality. There is no better solution for data updates than complete rewriting. In contrast, for RDBMS, the product creators deemed it necessary to delegate the joining and updating of tables to SQL usage.
For a project at Sberbank, we created a new reusable database loader implementation for GreenPlum. This was based on the version generated by MDW for Teradata. Teradata, rather than Oracle, was the best fit since it is also an MPP system. The working methods and syntax of Teradata and GreenPlum turned out to be similar.
Examples of critical differences for MDW between various RDBMS are as follows. In GreenPlum, unlike Teradata, when creating tables, you need to write the clause
distributed byIn Teradata, you write
delete <table> all, while in GreenPlum you write
delete from <table>In Oracle, for optimization purposes, you write
delete from t where rowid in (), whereas in Teradata and GreenPlum you write
delete from t where exists (select * from delta where delta.pk=t.pk)It should also be noted that for Ab Initio to work with GreenPlum, it was necessary to install the GreenPlum client on all nodes of the Ab Initio cluster. This is because we connected to GreenPlum from all nodes of our cluster simultaneously. To ensure that reading from GreenPlum was parallel and each parallel Ab Initio thread read its batch of data from GreenPlum, it was necessary to place an understood by Ab Initio construct in the SQL query's 'where' section.
where ABLOCAL()and define the value of this construct by specifying a parameter for the transformation reading from the database
ablocal_expr="string_concat("mod(t.", string_filter_out("{$TABLE_KEY}","{}"), ",", (decimal(3))(number_of_partitions()),")=", (decimal(3))(this_partition()))", which compiles to something like
mod(sk,10)=3, meaning it is necessary to inform GreenPlum of the explicit filter for each partition. For other databases (Teradata, Oracle), Ab Initio can perform this parallelization automatically.
Comparative performance characteristics of Ab Initio working with Hive and GreenPlum.
An experiment was conducted at Sberbank to compare the performance of the generated MDW graphs for Hive and GreenPlum. In the experiment, Hive had 5 nodes on the same cluster as Ab Initio, while GreenPlum had 4 nodes on a separate cluster. Hence, Hive had a slight advantage over GreenPlum in terms of hardware.
Two pairs of graphs were examined, performing the same task of data updating in Hive and GreenPlum. The graphs generated by the MDW configurator were run:
- initial load + incremental load of randomly generated data into a Hive table
- initial load + incremental load of randomly generated data into the same GreenPlum table
In both cases (Hive and GreenPlum), we executed loads in 10 parallel streams on the same Ab Initio cluster. Intermediate data for Ab Initio calculations was stored in HDFS (in terms of Ab Initio, an MFS layout using HDFS was used). One line of randomly generated data occupied 200 bytes in both cases.
The result was as follows:
Hive:
Initial load in Hive
Inserted rows
6 000 000
60 000 000
600 000 000
Duration of initial load
in seconds
41
203
1 601
Incremental load in Hive
Number of rows that were in
the target table at the beginning of the experiment
6 000 000
60 000 000
600 000 000
Number of delta rows applied to
the target table during the experiment
6 000 000
6 000 000
6 000 000
Duration of incremental
in seconds
88
299
2 541
GreenPlum:
Initial load in GreenPlum
Inserted rows
6 000 000
60 000 000
600 000 000
Duration of initial load
in seconds
72
360
3 631
Incremental load in GreenPlum
Number of rows that were in
the target table at the beginning of the experiment
6 000 000
60 000 000
600 000 000
Number of delta rows applied to
the target table during the experiment
6 000 000
6 000 000
6 000 000
Duration of incremental
in seconds
159
199
321
We see that the speed of the initial load in both Hive and GreenPlum is linearly dependent on the volume of data, and due to better hardware, it is somewhat faster for Hive than for GreenPlum.
The incremental load in Hive also depends linearly on the volume of previously loaded data in the target table and occurs quite slowly as the volume increases. This is due to the need to completely rewrite the target table. This means that applying small changes to large tables is not a very good use case for Hive.
In contrast, the incremental load in GreenPlum is weakly dependent on the volume of previously loaded data in the target table and occurs quite quickly. This is thanks to SQL Joins and the architecture of GreenPlum, which allows for delete operations.
Thus, GreenPlum applies the delta using delete+insert, while Hive does not have delete or update operations, so the entire data array had to be rewritten completely during incremental updates. It's most illustrative to compare the highlighted cells, as they correspond to the most common use case for resource-intensive loads. We see that GreenPlum outperformed Hive in this test by 8 times.
Ab Initio's operation with GreenPlum in Near Real Time mode.
In this experiment, we will test the ability of Ab Initio to update the GreenPlum table with randomly generated batches of data in a mode close to real-time. We will consider the GreenPlum table dev42_1_db_usl.TESTING_SUBJ_org_finval, which will be worked on.
We will use three Ab Initio graphs to work with it:
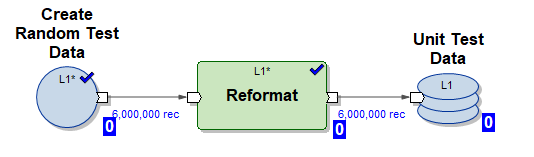
1) Graph Create_test_data.mp – creates data files in HDFS with 6,000,000 rows in 10 parallel streams. The data is random, structured for insertion into our table.
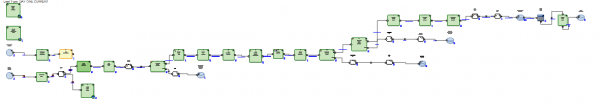
2) Graph mdw_load.day_one.current.dev42_1_db_usl_testing_subj_org_finval.pset – generated MDW graph for the initializing data insertion into our table in 10 parallel streams (test data generated by graph (1) is used).
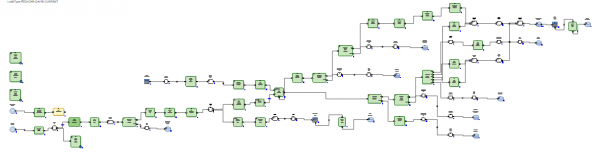
3) Graph mdw_load.regular.current.dev42_1_db_usl_testing_subj_org_finval.pset – generated MDW graph for incremental updates of our table in 10 parallel streams using a batch of newly arrived data (deltas) generated by graph (1).
We will execute the following scenario in NRT mode:
- generate 6,000,000 test rows
- perform an initializing load by inserting 6,000,000 test rows into an empty table
- repeat the incremental load 5 times
- generate 6,000,000 test rows
- perform the incremental insertion of 6,000,000 test rows into the table (marking old data with a valid_to_ts expiration time and inserting fresher data with the same primary key).
This scenario emulates the real operation mode of a business system – a sufficiently large batch of new data appears in real-time and is immediately fed into GreenPlum.
Now let's look at the log of the scenario's execution:
Start Create_test_data.input.pset at 2020-06-04 11:49:11
Finish Create_test_data.input.pset at 2020-06-04 11:49:37
Start mdw_load.day_one.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 11:49:37
Finish mdw_load.day_one.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 11:50:42
Start Create_test_data.input.pset at 2020-06-04 11:50:42
Finish Create_test_data.input.pset at 2020-06-04 11:51:06
Start mdw_load.regular.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 11:51:06
Finish mdw_load.regular.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 11:53:41
Start Create_test_data.input.pset at 2020-06-04 11:53:41
Finish Create_test_data.input.pset at 2020-06-04 11:54:04
Start mdw_load.regular.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 11:54:04
Finish mdw_load.regular.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 11:56:51
Start Create_test_data.input.pset at 2020-06-04 11:56:51
Finish Create_test_data.input.pset at 2020-06-04 11:57:14
Start mdw_load.regular.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 11:57:14
Finish mdw_load.regular.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 11:59:55
Start Create_test_data.input.pset at 2020-06-04 11:59:55
Finish Create_test_data.input.pset at 2020-06-04 12:00:23
Start mdw_load.regular.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 12:00:23
Finish mdw_load.regular.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 12:03:23
Start Create_test_data.input.pset at 2020-06-04 12:03:23
Finish Create_test_data.input.pset at 2020-06-04 12:03:49
Start mdw_load.regular.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 12:03:49
Finish mdw_load.regular.current.dev42_1_db_usl_testing_subj_org_finval.pset at 2020-06-04 12:06:46
Here is the picture:
Graph
Start time
Finish time
Length
Create_test_data.input.pset
04.06.2020 11:49:11
04.06.2020 11:49:37
00:00:26
mdw_load.day_one.current.
dev42_1_db_usl_testing_subj_org_finval.pset
04.06.2020 11:49:37
04.06.2020 11:50:42
00:01:05
Create_test_data.input.pset
04.06.2020 11:50:42
04.06.2020 11:51:06
00:00:24
mdw_load.regular.current.
dev42_1_db_usl_testing_subj_org_finval.pset
04.06.2020 11:51:06
04.06.2020 11:53:41
00:02:35
Create_test_data.input.pset
04.06.2020 11:53:41
04.06.2020 11:54:04
00:00:23
mdw_load.regular.current.
dev42_1_db_usl_testing_subj_org_finval.pset
04.06.2020 11:54:04
04.06.2020 11:56:51
00:02:47
Create_test_data.input.pset
04.06.2020 11:56:51
04.06.2020 11:57:14
00:00:23
mdw_load.regular.current.
dev42_1_db_usl_testing_subj_org_finval.pset
04.06.2020 11:57:14
04.06.2020 11:59:55
00:02:41
Create_test_data.input.pset
04.06.2020 11:59:55
04.06.2020 12:00:23
00:00:28
mdw_load.regular.current.
dev42_1_db_usl_testing_subj_org_finval.pset
04.06.2020 12:00:23
04.06.2020 12:03:23
00:03:00
Create_test_data.input.pset
04.06.2020 12:03:23
04.06.2020 12:03:49
00:00:26
mdw_load.regular.current.
dev42_1_db_usl_testing_subj_org_finval.pset
04.06.2020 12:03:49
04.06.2020 12:06:46
00:02:57
We can see that 6,000,000 incremental rows are processed in 3 minutes, which is quite fast.
The data in the target table is distributed as follows:
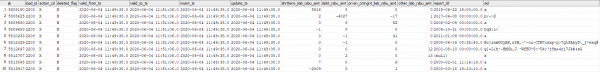
select valid_from_ts, valid_to_ts, count(1), min(sk), max(sk) from dev42_1_db_usl.TESTING_SUBJ_org_finval group by valid_from_ts, valid_to_ts order by 1,2; 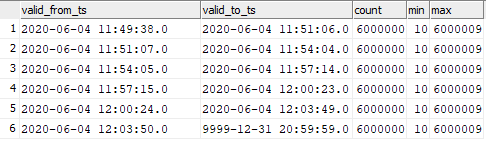
You can see the correlation of the inserted data with the moments of graph launches.
This means we can run incremental data loading in GreenPlum using Ab Initio very frequently and observe a high insertion speed of this data into GreenPlum. Of course, running it once a second isn't feasible, as Ab Initio, like any ETL tool, requires a startup time.
Conclusion
Currently, Ab Initio is used in Sberbank to build a Unified Semantic Data Layer (USDL). This project entails creating a unified version of the states of various banking business entities. Information comes from various sources, which are prepared as replicas in Hadoop. Based on business needs, a data model is created, and data transformations are described. Ab Initio loads information into the USDL, and the loaded data not only holds intrinsic value for the business but also serves as a source for building data marts. The product's functionality allows various systems (Hive, Greenplum, Teradata, Oracle) to be used as recipients, enabling easy preparation of data for the business in various required formats.
Ab Initio's capabilities are vast; for example, the accompanying MDW framework allows for building technical and business data lineage 'out of the box.' For developers, Ab Initio provides the opportunity not to 'reinvent the wheel' but to utilize a multitude of existing functional components, which essentially act as libraries needed for data handling.
Author — an expert of the Sberbank professional community SberProfi DWH/BigData. The SberProfi DWH/BigData professional community is responsible for developing competencies in areas such as the Hadoop ecosystem, Teradata, Oracle DB, GreenPlum, as well as BI tools Qlik, SAP BO, Tableau, and others.
Source: habr.com
