

I would like to discuss an interesting mechanism for working with the configuration of a distributed system. The configuration is presented directly in a compiled language (Scala) using safe types. This post examines an example of such a configuration and considers various aspects of incorporating compiled configuration into the overall development process.
()
Introduction
Building a reliable distributed system implies that all nodes use a correct configuration synchronized with other nodes. Typically, DevOps technologies (terraform, ansible, or something similar) are used for automatic generation of configuration files (often tailored for each node). We also want to be sure that identical protocols are used on all interacting nodes (including the same version). Otherwise, there will be incompatibility built into our distributed system. In the JVM world, one consequence of such a requirement is the need to use the same version of the library that contains the protocol messages everywhere.
What about testing the distributed system? Of course, we assume that unit tests are provided for all components before we move on to integration testing. (To extrapolate testing results to runtime, we also need to ensure an identical set of libraries during both the testing phase and runtime.)
When working with integration tests, it is often easier to use a unified classpath across all nodes. We just need to ensure that the same classpath is also in use at runtime. (While it is entirely possible to run different nodes with different classpaths, this complicates the overall configuration and poses challenges for deployment and integration testing.) For this post, we assume that the same classpath will be used on all nodes.
Configuration evolves alongside the application. To identify various stages of software evolution, we use versions. It seems logical to also identify different versions of configurations. The configuration itself can be placed in a version control system. If there's a single configuration in production, we can simply use a version number. However, if multiple production instances are being used, we will need several
configuration branches and an additional label beyond the version (for example, the branch name). This way, we can uniquely identify the exact configuration. Each configuration identifier corresponds uniquely to a specific combination of distributed nodes, ports, external resources, and library versions. In this post, we will assume that there is only one branch, and we can identify the configuration in the usual way using three numbers separated by periods (1.2.3).
In modern environments, configuration files are rarely created manually. More often, they are generated during deployment and are not modified afterwards (to ). This raises the question of why we still use a text format for storing configurations. A viable alternative is to use regular code for configuration and gain advantages through compile-time checks.
In this post, we will explore the idea of representing configuration within a compiled artifact.
Compiled Configuration
This section presents an example of a static compiled configuration. Two simple services are implemented — an echo service and a client for the echo service. Based on these two services, two variants of the system are built. In one variant, both services reside on the same node, while in the other variant, they are on different nodes.
A distributed system typically contains several nodes. Nodes can be identified using values of some type NodeId:
sealed trait NodeId
case object Backend extends NodeId
case object Frontend extends NodeId
or
case class NodeId(hostName: String)or even
object Singleton
type NodeId = Singleton.type
Nodes perform various roles, run services, and TCP/HTTP connections can be established between them.
To describe a TCP connection, we need at least a port number. We would also like to reflect the protocol supported on this port to ensure that both the client and server are using the same protocol. We will describe the connection using the following class:
case class TcpEndPoint[Protocol](node: NodeId, port: Port[Protocol])where Port — just an integer Int specifying a range of acceptable values:
type PortNumber = Refined[Int, Closed[_0, W.`65535`.T]]Refined types
See the library and . In brief, the library allows adding constraints to types that are checked at compile time. In this case, the valid port numbers are 16-bit integers. The use of the refined library for the compiled configuration is not mandatory, but it enhances the compiler’s capabilities for verifying the configuration.
For HTTP (REST) protocols, in addition to the port number, we may also need the path to the service:
type UrlPathPrefix = Refined[String, MatchesRegex[W.`"[a-zA-Z_0-9\/]*"`.T]]
case class PortWithPrefix[Protocol](portNumber: PortNumber, pathPrefix: UrlPathPrefix)
Phantom types
To identify the protocol at compile time, we use a type parameter that is not used within the class. This approach is due to the fact that we do not use a protocol instance at runtime, but we want the compiler to check the compatibility of protocols. By specifying the protocol, we cannot pass an incompatible service as a dependency.
One of the common protocols is REST API with JSON serialization:
sealed trait JsonHttpRestProtocol[RequestMessage, ResponseMessage]where RequestMessage — request type, ResponseMessage — response type.
Of course, other protocol descriptions can be used that provide the required accuracy of description.
For the purposes of this post, we will use a simplified version of the protocol:
sealed trait SimpleHttpGetRest[RequestMessage, ResponseMessage]Here, the request is a string added to the URL, and the response is a string returned in the body of the HTTP response.
The service configuration is described by the service name, ports, and dependencies. These elements can be represented in Scala in several ways (for example, HList-s, algebraic data types). For the purposes of this post, we will use the Cake Pattern and represent modules using trait's. (The Cake Pattern is not a mandatory element of the described approach; it is just one of the possible implementations.)
Dependencies between services can be represented as methods that return the ports EndPoint's of other nodes:
  type EchoProtocol[A] = SimpleHttpGetRest[A, A]

  trait EchoConfig[A] extends ServiceConfig {
    def portNumber: PortNumber = 8081
    def echoPort: PortWithPrefix[EchoProtocol[A]] = PortWithPrefix[EchoProtocol[A]](portNumber, "echo")
    def echoService: HttpSimpleGetEndPoint[NodeId, EchoProtocol[A]] = providedSimpleService(echoPort)
  }
To create an echo service, all you need is a port number and to indicate that this port supports the echo protocol. We could have omitted specifying a specific port, as traits allow declaring methods without an implementation (abstract methods). In that case, when creating a specific configuration, the compiler would require us to provide an implementation for the abstract method and specify the port number. Since we have implemented the method, we can omit specifying another port when creating a specific configuration. The default value will be used.
In the client's configuration, we declare a dependency on the echo service:
  trait EchoClientConfig[A] {
    def testMessage: String = "test"
    def pollInterval: FiniteDuration
    def echoServiceDependency: HttpSimpleGetEndPoint[_, EchoProtocol[A]]
  }
The dependency has the same type as the exported service echoService. Specifically, in the echo client, we require the same protocol. Therefore, when connecting two services, we can be sure that everything will work correctly.
Implementation of services
To start and stop the service, a function is required. (The ability to stop the service is critically important for testing.) Again, there are several options for implementing such a function (for example, we could use type classes based on the configuration type). For the purposes of this post, we will use the Cake Pattern. We will represent the service using a class cats.Resource, as this class already includes means for safe guaranteed resource release in case of issues. To obtain the resource, we need to provide a configuration and a ready runtime context. The service's start function might look like this:
  type ResourceReader[F[_], Config, A] = Reader[Config, Resource[F, A]]

  trait ServiceImpl[F[_]] {
    type Config
    def resource(
      implicit
      resolver: AddressResolver[F],
      timer: Timer[F],
      contextShift: ContextShift[F],
      ec: ExecutionContext,
      applicative: Applicative[F]
    ): ResourceReader[F, Config, Unit]
  }
where
Config— the type of configuration for this serviceAddressResolver— a runtime object that allows knowing the addresses of other nodes (see below)
and other types from the library cats:
F[_]— the type of effect (in the simplest caseF[A]can simply be a function() => A. In this post, we will usecats.IO.)Reader[A,B]— more or less a synonym for functionA => Bcats.Resource— a resource that can be obtained and releasedTimer— a timer (allows sleeping for a period of time and measuring intervals)ContextShift— an analogousExecutionContextApplicative— a class of effect type that allows combining individual effects (almost a monad). In more complex applications, it seems better to useMonad/ConcurrentEffect.
Using this function signature, we can implement several services. For example, a service that does nothing:
  trait ZeroServiceImpl[F[_]] extends ServiceImpl[F] {
    type Config  Resource.pure[F, Unit](()))
  }
(See. , where other services are implemented — ,
and .)
A node is an object that can start several services (the launch of the resource chain is ensured by the Cake Pattern):
object SingleNodeImpl extends ZeroServiceImpl[IO]
  with EchoServiceService
  with EchoClientService
  with FiniteDurationLifecycleServiceImpl
{
  type Config = EchoConfig[String] with EchoClientConfig[String] with FiniteDurationLifecycleConfig
}
Note that we specify the exact type of configuration required for this node. If we forget to specify any of the configuration types required by a specific service, it will result in a compilation error. Additionally, we will not be able to start the node if we do not provide an object that has the appropriate type with all the necessary data.
Node name resolution
To connect to a remote node, we need a real IP address. It is quite possible that the address becomes known later than the other parts of the configuration. Therefore, we need a function that maps the node identifier to the address:
case class NodeAddress[NodeId](host: Uri.Host)
trait AddressResolver[F[_]] {
  def resolve[NodeId](nodeId: NodeId): F[NodeAddress[NodeId]]
}
Several ways to implement such a function can be proposed:
- If the addresses become known to us before deployment, we can generate Scala code with
the addresses and then run the build. This will involve compilation and tests being executed.
In this case, the function will be known statically and can be represented in the code as a mappingMap[NodeId, NodeAddress]. - In some cases, the valid address becomes known only after the node is launched.
In this case, we can implement a discovery service that starts before the other nodes, where all nodes will register with this service and request the addresses of other nodes. - If we can modify
/etc/hosts, we can use predefined host names (likemy-project-main-nodeandecho-backend) and simply bind these names
to IP addresses during deployment.
In this post, we will not discuss these cases in detail. For our
toy example, all nodes will have the same IP address — 127.0.0.1.
Next, we will consider two variants of a distributed system:
- Deploying all services on one node.
- And deploying the echo service and echo client on different nodes.
Configuration for :
Configuration for one node
object SingleNodeConfig extends EchoConfig[String]
  with EchoClientConfig[String] with FiniteDurationLifecycleConfig
{
  case object Singleton \/\/ identifier of the single node
  \/\/ configuration of server
  type NodeId = Singleton.type
  def nodeId = Singleton

  \/** Type safe service port specification. *\/
  override def portNumber: PortNumber = 8088

  \/\/ configuration of client

  \/** We'll use the service provided by the same host. *\/
  def echoServiceDependency = echoService

  override def testMessage: UrlPathElement = "hello"

  def pollInterval: FiniteDuration = 1.second

  \/\/ lifecycle controller configuration
  def lifetime: FiniteDuration = 10500.milliseconds \/\/ additional 0.5 seconds so that there are 10 requests, not 9.
}
The object implements both the client and server configuration. It also uses the lifetime configuration to terminate the program after a certain interval lifetime . (Ctrl-C also works and correctly releases all resources.)
The same set of traits for configuration and implementations can be used to create a system consisting of :
Configuration for two nodes
  object NodeServerConfig extends EchoConfig[String] with SigTermLifecycleConfig
  {
    type NodeId = NodeIdImpl

    def nodeId = NodeServer

    override def portNumber: PortNumber = 8080
  }

  object NodeClientConfig extends EchoClientConfig[String] with FiniteDurationLifecycleConfig
  {
    \/\/ NB! dependency specification
    def echoServiceDependency = NodeServerConfig.echoService

    def pollInterval: FiniteDuration = 1.second

    def lifetime: FiniteDuration = 10500.milliseconds \/\/ additional 0.5 seconds so that there are 10 requests, not 9.

    def testMessage: String = "dolly"
  }
Important! Note how service binding is executed. We specify a service implemented by one node as a dependency method for another node. The type of dependency is checked by the compiler as it contains the protocol type. Upon startup, the dependency will hold the correct identifier of the target node. With this scheme, we specify the port number exactly once and are always guaranteed to reference the correct port.
Implementation of two nodes in the system
For this configuration, we use the same service implementations without changes. The only difference is that now we have two objects implementing different sets of services:
  object TwoJvmNodeServerImpl extends ZeroServiceImpl[IO] with EchoServiceService with SigIntLifecycleServiceImpl {
    type Config = EchoConfig[String] with SigTermLifecycleConfig
  }

  object TwoJvmNodeClientImpl extends ZeroServiceImpl[IO] with EchoClientService with FiniteDurationLifecycleServiceImpl {
    type Config = EchoClientConfig[String] with FiniteDurationLifecycleConfig
  }
The first node implements the server and only requires server configuration. The second node implements the client and utilizes a different part of the configuration. Both nodes also require lifecycle management. The server node runs indefinitely until stopped, SIGTERMwhile the client node terminates after some time. See .
The overall development process
Let's see how this configuration approach affects the overall development process.
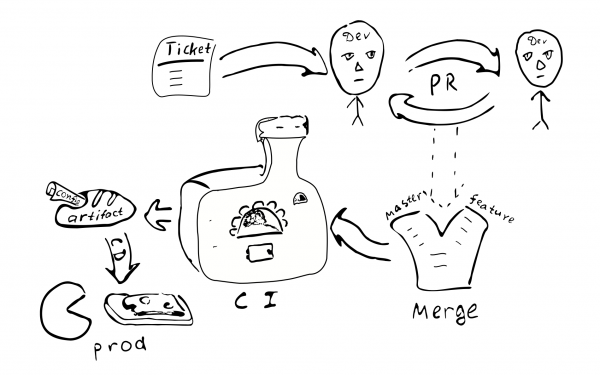
The configuration will be compiled along with the rest of the code, and an artifact (.jar) will be generated. It makes sense to place the configuration in a separate artifact, as we may have multiple configurations based on the same code. Again, artifacts can be generated that correspond to different configuration branches. Along with the configuration, dependencies on specific versions of libraries are preserved, and these versions are saved forever whenever we decide to deploy this version of the configuration.
Any change in configuration becomes a change in code. Therefore, each such
change will be covered by the usual quality assurance process:
Ticket in the bug tracker -> PR -> review -> merging with the corresponding branches ->
integration -> deployment
Key implications of implementing a compilable configuration:
The configuration will be synchronized across all nodes of the distributed system. Since all nodes receive the same configuration from a single source.
It is problematic to change the configuration on just one of the nodes. Therefore, 'configuration drift' is unlikely.
It becomes harder to make small changes to the configuration.
Most configuration changes will occur within the overall development process and will be subjected to review.
Is a separate repository needed for storing the production configuration? This configuration may contain passwords and other sensitive information, access to which we would like to restrict. Given this, it seems logical to store the final configuration in a separate repository. The configuration can be divided into two parts—one containing public configuration parameters and another containing restricted access parameters. This allows most developers to access the common parameters. Such separation can be easily achieved using intermediate traits that contain default values.
Possible variations
Let’s try to compare the compiled configuration with some common alternatives:
- A text file on the target machine.
- A centralized key-value store (
etcd/zookeeper). - Process components that can be reconfigured/restarted without restarting the process.
- Storing configuration outside of artifacts and version control.
Text files provide considerable flexibility regarding small changes. A system administrator can access a remote node, make changes to the relevant files, and restart the service. However, for larger systems, such flexibility may be undesirable. No traces of the changes remain in other systems. No one conducts a review of the changes. It is difficult to determine who made the changes and why. Changes are not tested. If the system is distributed, the administrator may forget to make the corresponding change on other nodes.
(It should also be noted that the use of a compiled configuration does not exclude the possibility of using text files in the future. It will be sufficient to add a parser and validator that outputs the same type Config, allowing for the use of text files. From this, it directly follows that the complexity of a system with a compiled configuration is somewhat lower than that of a system using text files, as additional code is required for text files.)
A centralized key-value store is a good mechanism for distributing meta-parameters of a distributed application. We need to define what configuration parameters are and what constitutes mere data. Let’s assume we have a function C => A => B, where the parameters C rarely change, and the data A often does. In this case, we can say that C are configuration parameters, while A are data. It seems that configuration parameters differ from data in that they generally change less frequently than data. Additionally, data usually comes from one source (the user), while configuration parameters come from another (the system administrator).
If rarely-changing parameters need to be updated without restarting the program, this can often complicate the program, as we will need some method to deliver parameters, store, parse, validate, and handle incorrect values. Therefore, in terms of reducing program complexity, it makes sense to minimize the number of parameters that may change during program execution (or not maintain such parameters at all).
From the perspective of this post, we will distinguish between static and dynamic parameters. If the service logic requires changes to parameters during the program's execution, we will refer to such parameters as dynamic. Otherwise, the parameters are static and can be configured using a compile-time configuration. For dynamic reconfiguration, we may need a mechanism to restart parts of the program with new parameters, similar to how processes in an operating system are restarted. (In our opinion, it is preferable to avoid real-time reconfiguration, as this increases system complexity. If possible, it is better to use the standard OS capabilities for restarting processes.)
One of the important aspects of using static configuration that leads people to consider dynamic reconfiguration is the time the system takes to reboot after configuration updates (downtime). Indeed, if we need to make changes to the static configuration, we will have to restart the system for the new values to take effect. The issue of downtime has varying severity for different systems. In some cases, a reboot can be scheduled for times when the load is minimal. If continuous service is required, we can implement . In this case, when we need to restart the system, we launch a parallel instance of that system, switch the load balancer to it, and wait for the old connections to finish. After all old connections are completed, we shut down the old instance of the system.
Now, let's consider the issue of storing configuration inside the artifact or outside it. If we store the configuration inside the artifact, then at the very least, we had the opportunity during the artifact build to verify the correctness of the configuration. If the configuration is outside the controlled artifact, it is difficult to track who made changes to this file and why. How important is this? In our view, it is crucial for many production systems to maintain a stable and high-quality configuration.
The artifact version allows us to determine when it was created, what values it contains, which functions are enabled/disabled, and who is responsible for any changes in the configuration. Naturally, storing the configuration within the artifact requires some effort, so a conscious decision must be made.
Pros and cons
I would like to highlight the advantages and disadvantages of the proposed technology.
Benefits
Below is a list of the main capabilities of the compiled configuration of a distributed system:
- Static configuration checking. This ensures that
the configuration is correct. - Rich configuration language. Typically, other configuration methods are limited to mere string variable substitution. Using Scala provides a wide range of language capabilities to enhance the configuration. For example, we can use
traits for default values, group parameters with objects, and reference vals declared once (DRY) in the encompassing scope. We can directly instantiate any classes within the configuration (Seq,Map, custom classes). - DSL. In Scala, there are several language features that facilitate the creation of DSL. We can leverage these capabilities to implement a configuration language that would be more convenient for the target user group, making the configuration at least readable for domain specialists. Specialists can, for example, participate in the configuration review process.
- Integrity and synchronization between nodes. One of the advantages of storing the configuration for the entire distributed system in a single point is that all values are declared exactly once and then reused wherever needed. Using phantom types for declaring ports ensures that all valid configurations of the system use compatible protocols. The presence of explicit mandatory dependencies between nodes guarantees that all services will be interconnected.
- High-quality change implementation. Modifying the configuration using a common development process ensures that high standards of quality are also available for the configuration.
- Simultaneous configuration updates. Automatic deployment of the system after changes to the configuration guarantees that all nodes will be updated.
- Application simplification. The application does not require parsing, configuration checks, or handling invalid values. This reduces the complexity of the application. (Some complexity in the configuration observed in our example is not an attribute of the compiled configuration but a conscious decision made to ensure greater type safety.) It is relatively easy to revert to the regular configuration — just implement the missing parts. Therefore, for example, one can start with a compiled configuration, deferring the implementation of additional parts until they are truly needed.
- Versioned configuration. Since configuration changes follow the usual fate of any other changes, the output results in an artifact with a unique version. This allows us, for example, to revert to a previous configuration version if necessary. We can even use a configuration from a year ago, and the system will operate exactly the same. A stable configuration improves the predictability and reliability of a distributed system. As the configuration is fixed at the compilation stage, it is quite difficult to tamper with it in production.
- Modularity. The proposed framework is modular, and modules can be combined in various configurations to create different systems. In particular, one configuration can be set up to run on a single node, while another can be configured for multiple nodes. Multiple configurations can be created for production instances of the system.
- Testing. By replacing individual services with mock objects, several versions of the system can be generated that are suitable for testing.
- Integration testing. Having a unified configuration for the entire distributed system enables the ability to run all components in a controlled environment during integration testing. It's easy to emulate scenarios where certain nodes become inaccessible.
Disadvantages and Limitations
Compiled configuration differs from other configuration approaches and may not be suitable for some applications. Below are some disadvantages:
- Static configuration. Sometimes it is necessary to quickly fix the configuration in production, bypassing all protective mechanisms. In this approach, this can be more complicated. At the very least, compilation and automatic deployment will still be required. This is both a useful feature of the approach and a drawback in certain cases.
- Configuration generation. If the configuration file is generated by an automated tool, additional efforts may be required to integrate the build script.
- Tooling. Currently, utilities and methods designed to work with configurations are based on text files. Not all such utilities/methods will be available in the case of compiled configuration.
- A shift in perspective is required. Developers and DevOps are used to text files. The very idea of compiling configurations can be somewhat unexpected and unfamiliar, leading to resistance.
- A high-quality development process is required. To comfortably use compiled configuration, full automation of the application's build and deployment process (CI/CD) is necessary. Otherwise, it can be quite inconvenient.
Let’s also address a number of limitations in the example discussed that are not related to the idea of compiled configuration:
- If we provide extra configuration information that is not used by the node, the compiler will not help us detect the absence of implementation. This problem can be resolved by abandoning the Cake Pattern and using stricter types, for example,
HListor algebraic data types (case classes) to represent the configuration. - The configuration file contains lines that are not directly related to the configuration: (
package,import, object declarations;override deffor parameters that have default values). This can be partially avoided by implementing your own DSL. Moreover, other types of configuration (for example, XML) also impose certain restrictions on the structure of the file. - In this post, we do not consider dynamic reconfiguration of a cluster of similar nodes.
Conclusion
In this post, we explored the idea of representing configuration in source code using the advanced capabilities of the Scala type system. This approach can find application in various applications as a substitute for traditional configuration methods based on XML or text files. Although our example is implemented in Scala, the same ideas can be transferred to other compiled languages (such as Kotlin, C#, Swift, etc.). This approach can be tested in one of the following projects, and if it does not work, we can switch to text files, adding the missing details.
Naturally, compiled configuration requires a high-quality development process. In return, high quality and reliability of configurations are ensured.
The discussed approach can be expanded:
- Macros can be used to perform checks at compile time.
- A DSL can be implemented to present the configuration in a manner accessible to end users.
- Dynamic resource management can be implemented with automatic configuration adjustment. For example, when the number of nodes in the cluster changes, (1) each node should receive a slightly different configuration; (2) the cluster manager should be informed about the new nodes.
Acknowledgments
I would like to thank Andrey Saksonov, Pavel Popov, and Anton Nekhayev for their constructive feedback on the draft of this article.
Source: habr.com
