

An important aspect of distributed systems is failure handling. Kubernetes helps with this by using controllers that monitor the state of your system and restart services that have stopped working. However, Kubernetes can also forcibly stop your applications to ensure the overall viability of the system. In this series, we will explore how to help Kubernetes perform its functions more efficiently and reduce application downtime.
Before the advent of containers, most applications ran on virtual or physical machines. If an application crashed or hung, it took a long time to terminate the running task and reload the program. In the worst cases, someone had to resolve the issue manually at inconvenient hours. If an important task was handled by only 1-2 worker machines, such a failure was simply unacceptable.
Therefore, instead of manual restarts, process monitoring began to be used for automatically restarting applications in case of crashes. If a program failed, the monitoring process captures the exit code and restarts the server. With the advent of systems like Kubernetes, this type of system failure response was simply integrated into the infrastructure.
Kubernetes uses an event loop of 'watching – diffing – acting' to ensure that resources remain operational along the path from containers to the nodes themselves.
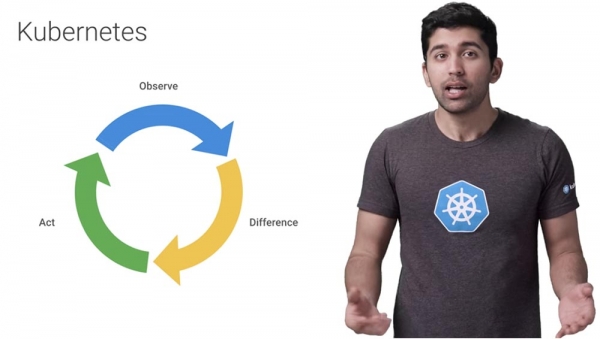
This means you no longer need to manually run process monitoring. If a resource fails a Health Check, Kubernetes will simply automatically provide a replacement. In this process, Kubernetes does much more than just watch for application failures. It can create additional copies of the application to run on multiple machines, update the application, or even run several versions of your app simultaneously.
There are many reasons why Kubernetes might terminate a perfectly healthy container. For example, if you are updating your deployment, Kubernetes will gradually stop the old pods while simultaneously starting new ones. If you shut down a node, Kubernetes will stop all pods running on that node. Lastly, if a node runs out of resources, Kubernetes will shut down all pods to free up those resources.
It is therefore crucial for your application to shut down with minimal impact on the end user and minimal recovery time. This means that before shutting down, it should save all necessary data, close all network connections, finish remaining tasks, and complete any other urgent actions.
In practice, this means that your application must be able to handle the SIGTERM message – a termination signal that is the default for the kill utility in Unix-like operating systems. Upon receiving this message, the application should shut down.
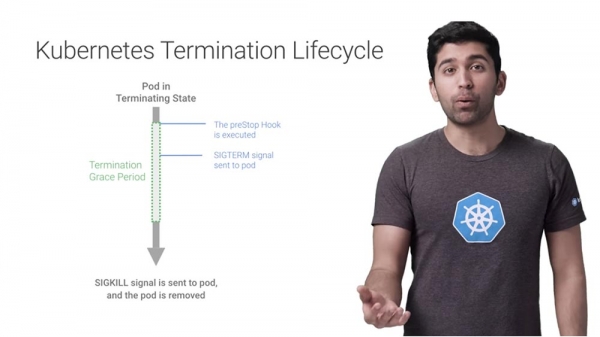
Once Kubernetes decides to terminate a pod, a series of events occurs. Let's take a look at each step Kubernetes takes when shutting down a container or pod.
Suppose we want to terminate one of the pods. At this point, it will stop receiving new traffic – the containers running in the pod will not be affected, but all new traffic will be blocked.
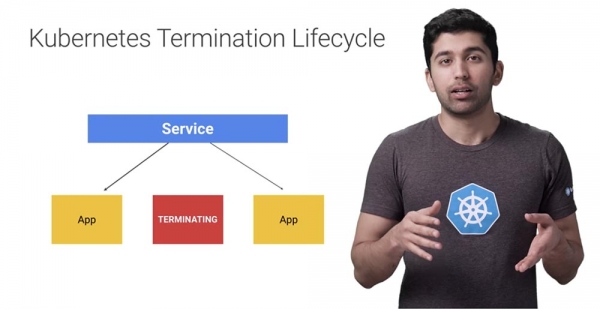
Let's examine the preStop hook — a special command or HTTP request sent to the containers in the pod. If your application does not shut down properly upon receiving SIGTERM, you can use preStop for a graceful shutdown.
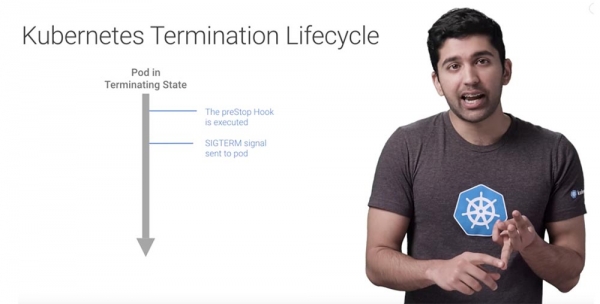
Most programs shut down correctly upon receiving the SIGTERM signal, but if you are using third-party code or a system that you cannot fully control, the preStop hook serves as an excellent way to trigger a graceful shutdown without altering the application.
After executing this hook, Kubernetes will send a SIGTERM signal to the containers in the pod, informing them that they will soon be shut down. Upon receiving this signal, your code will initiate the shutdown process. This process may involve stopping any long-lived connections, such as database or WebSocket connections, saving the current state, and so on.
Even if you use the preStop hook, it’s crucial to monitor what happens to your application when you send it a SIGTERM signal, how it behaves during this time, so that events or system changes caused by the pod's shutdown do not catch you off guard.
At this moment, before taking further actions, Kubernetes will wait for a specified time, known as terminationGracePeriodSecond, or the grace period for proper shutdown upon receiving the SIGTERM signal.
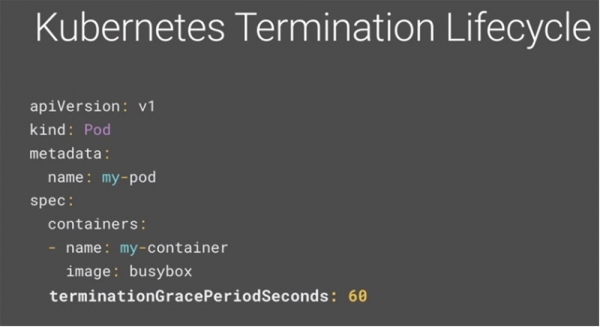
By default, this period is set to 30 seconds. It's important to note that it runs concurrently with the preStop hook and the SIGTERM signal. Kubernetes will not wait for the preStop hook and SIGTERM to complete — if your application finishes before the terminationGracePeriod ends, Kubernetes will immediately move on to the next step. Therefore, ensure that the value of this period in seconds is no less than the time required for a proper pod shutdown, and if it exceeds 30 seconds, increase the period to the required amount in YAML. In the example given, it is set to 60 seconds.
Finally, the last step — if the containers are still running after the terminationGracePeriod, they will be sent a SIGKILL signal and forcibly removed. At this point, Kubernetes will also clean up any other pod objects.
Kubernetes terminates pods for many reasons, so ensure that your application will be properly shut down in any case to maintain service stability.
A little advertisement 🙂
Thank you for staying with us. Do you enjoy our articles? Want to see more interesting content? Support us by placing an order or recommending us to your friends, , a unique entry-level server alternative that we have created for you: (options available with RAID1 and RAID10, up to 24 cores and up to 40GB DDR4).
Dell R730xd at half the price in the Equinix Tier IV data center in Amsterdam? Only with us in the Netherlands! Dell R420 — 2x E5-2430 2.2GHz 6C 128GB DDR3 2x960GB SSD 1Gbps 100TB — from $99! Read about how
Source: habr.com
