

For each Kubernetes resource, you can configure two types of requirements — Requests and Limits. The first describes the minimum resource availability required for launching a container or pod, while the second strictly limits the resources available to the container.
When Kubernetes schedules a pod, it is crucial that the containers have sufficient resources for normal operation. If you plan to deploy a large application on a node with limited resources, it is quite possible that it will not function due to the node running out of memory or lacking CPU power. In this article, we will explore how to resolve computational power shortages using resource requests and limits.
Requests and Limits are mechanisms that Kubernetes uses to manage resources such as CPU and memory. Requests are the means by which a container is guaranteed to receive the requested resource. If a container requests a resource, Kubernetes will only schedule it on a node that can provide it. Limits control that the resources requested by a container never exceed a specified value.
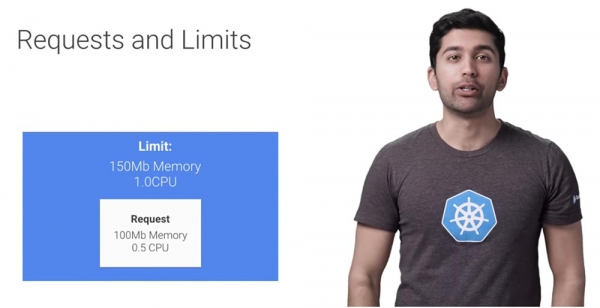
A container can only scale computing power up to a certain limit, after which it will be constrained. Let’s look at how this works. There are two types of resources — CPU and memory. The Kubernetes scheduler uses data about these resources to determine where to run your pods. A typical resource specification for a pod looks like this.
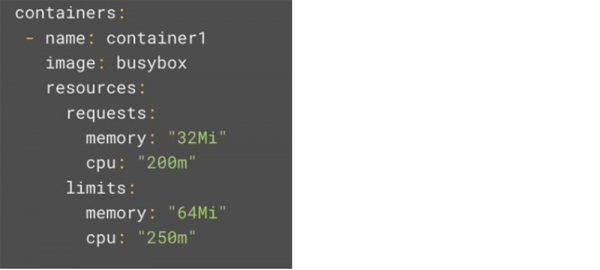
Each container in a pod can set its own requests and limits, and these are additive. CPU resources are defined in millicores. If your container needs to run on two full cores, you set the value to 2000m. If the container only needs the power of a quarter core, the value would be 250m. Keep in mind that if you assign a CPU resource value greater than the number of cores in the largest node, your pod will not be scheduled at all. A similar situation will occur if you have a pod that requires four cores while your Kubernetes cluster consists of only two main virtual machines.
Unless your application is specifically designed to leverage the advantages of multiple cores (such as complex scientific computations and database operations), the best practice is to set CPU Requests to 1 or lower, then run more replicas for scalability. This approach will give your system greater flexibility and reliability.
When it comes to CPU limits, things get more interesting since it is considered a compressible resource. If your application starts approaching its CPU power limit, Kubernetes will begin throttling your container using CPU Throttling — reducing the CPU frequency. This means that the CPU will be artificially limited, potentially providing worse performance for the application, although the process will not be terminated or evicted.
Memory resources are defined in bytes. Typically, the value in configurations is measured in mebibytes (MiB), but you can specify any value from bytes to petabytes. The same situation applies as with CPU — if you place a memory request exceeding the amount of memory on your nodes, the execution of that pod will not be scheduled. However, unlike CPU resources, memory cannot be throttled because there is no way to limit its usage. Therefore, the execution of the container will be halted as soon as it exceeds the allocated memory.
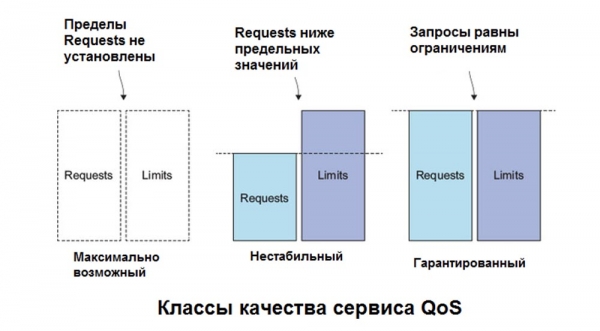
It is important to remember that you cannot configure requests that exceed the resource sizes that your nodes can provide. The characteristics of shared resources for GKE virtual machines can be found at the links placed under this video.
In an ideal world, the default container settings would be sufficient for workflows to run smoothly. However, the real world is not like that; people can easily forget to configure resource usage, or hackers may set requests and limits that exceed the actual capabilities of the infrastructure. To prevent the development of such scenarios, you can configure resource quotas using ResourceQuota and limit ranges using LimitRange.
After creating a namespace, it can be locked with quotas. For example, if you have prod and dev namespaces, a template can be used where there are no quotas for production at all, while development quotas are very strict. This allows prod to take all available resources in the event of a sudden traffic spike, completely blocking dev.
A resource quota may look like this. In this example, there are 4 sections – these are the 4 bottom lines of code.
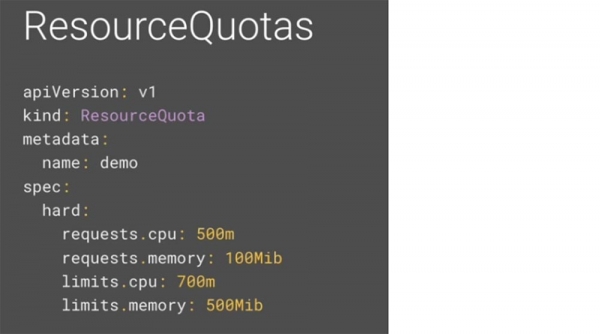
Let's consider each of them. Requests.cpu is the maximum number of total CPU requests that can come from all containers in a namespace. In this example, you can have 50 containers with requests of 10m, five containers with requests of 100m, or just one container with a request of 500m. As long as the total requests.cpu for this namespace is less than 500m, everything will be fine.
Requested memory requests.memory is the maximum total memory requests that all containers in the namespace can have. Just like in the previous case, you can have 50 containers with 2 MiB, five containers with 20 MiB, or a single container with 100 MiB, as long as the total requested memory in the namespace is less than 100 mebibytes.
Limits.cpu is the maximum combined value of CPU power that all containers in the namespace can use. You can think of it as the ceiling for CPU requests.
Finally, limits.memory is the maximum amount of total memory that all containers in the namespace can use. This is the limit on total memory requests.
By default, containers in a Kubernetes cluster operate with unlimited compute resources. With resource quotas, cluster administrators can limit resource consumption and creation based on namespaces. In a namespace, a pod or container may use as much CPU and memory power as defined by the namespace's resource quota. However, there are concerns that a single pod or container may monopolize all available resources. To prevent this situation, a limit range is used – a policy for resource allocation constraints (for pods or containers) within the namespace.
A limit range provides constraints that can:
- ensure the minimum and maximum usage of compute resources for each pod or container in the namespace;
- enforce the minimum and maximum storage request for each PersistentVolumeClaim in the namespace;
- enforce a ratio between request and limit for a resource in the namespace;
- set default Requests/Limits for compute resources in the namespace and automatically apply them to containers at runtime.
Thus, you can create a limit range in your namespace. Unlike quotas, which apply to the entire namespace, the Limit Range is used for individual containers. This can prevent users from creating very small or, on the contrary, gigantic containers within the namespace. A limit range may look like this.
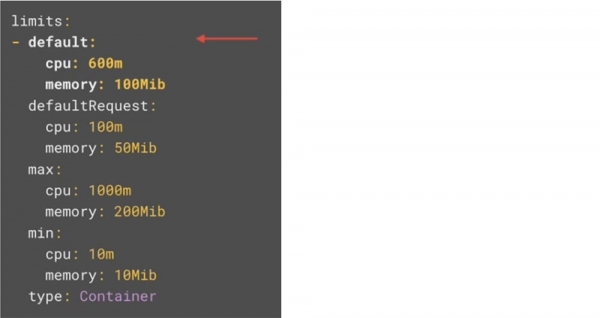
As in the previous case, there are 4 sections to highlight. Let’s examine each one.
In the default section, default limits are set for containers in a pod. If you specify these values in the limit range, any containers for which these values have not been explicitly set will be governed by the default values.
The defaultRequest section configures default requests for the container in a pod. Again, if you set these values within the limit range, any containers for which these parameters are not explicitly defined will use these values as defaults.
The max section specifies the maximum limits that can be set for the container in the pod. The values in the default section and the limits for the container cannot be set above this limit. Importantly, if a max value is set and the default section is missing, the maximum value becomes the default.
The min section specifies the minimum requests that can be set for the container in the pod. The values in the default section and the requests for the container cannot be set below this limit.
Again, it is important to note that if this value is set, and default is not, the minimum value becomes the default request.
Ultimately, these resource requests are utilized by the Kubernetes scheduler to execute your workloads. To properly configure your containers, it is crucial to understand how this works. Suppose you want to run several modules in your cluster. Assuming the pod specifications are valid, Kubernetes scheduling will use round-robin to select a node for executing the workload.
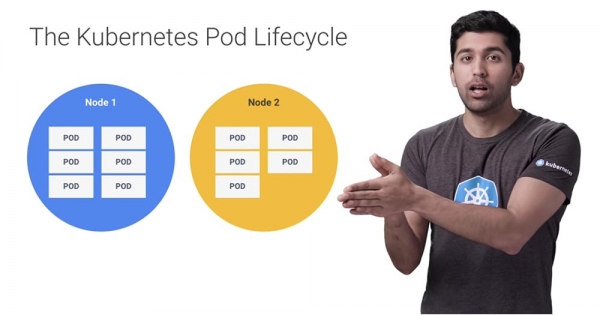
Kubernetes will check if Node 1 has enough resources to meet the pod container requests, and if it does not, it will move on to the next node. If none of the nodes in the system can satisfy the requests, the pods will enter a Pending state. Utilizing features like node autoscaling in Google Kubernetes Engine, GKE can automatically identify the pending state and create additional nodes as needed.
If excess node capacity arises later, the autoscaling feature will reduce the number of nodes to save you money. This is why Kubernetes schedules pods based on requests. However, limits can exceed requests, and in some cases, a node may actually run out of resources. This state is referred to as the overcommitment state.
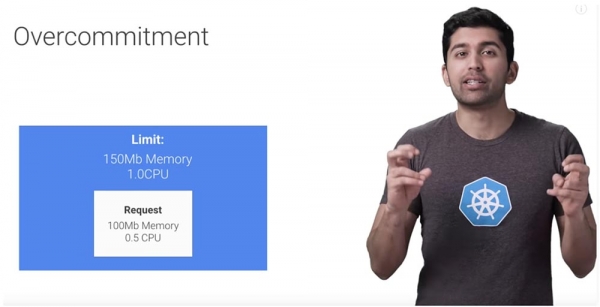
As I mentioned, when it comes to the processor, Kubernetes will begin to limit the pods. Each pod will receive as much as it requested, but if it does not reach the limit, throttling will start to apply.
When it comes to memory resources, Kubernetes is forced to make decisions about which pods to remove and which to keep until you free up system resources; otherwise, the entire system will crash.
Let's imagine a scenario where you have a machine that has exhausted its memory limit — how will Kubernetes react?
Kubernetes will look for pods that are using more resources than they requested. So if your containers have no Requests at all, it means they are using more by default than they asked for simply because they didn’t ask for anything! Such containers become the primary candidates for shutdown. The next candidates are the containers that have met all their requests but are still below the maximum limit.
So if Kubernetes finds several pods that have exceeded their requested parameters, it will sort them by priority and then terminate the lowest priority modules. If all modules have the same priority, Kubernetes will stop the pods that exceeded their requests more than the others.
In very rare cases, Kubernetes may terminate pods that are still within their requests. This can happen when critical system components, such as the Kubelet agent or Docker, start consuming more resources than were reserved for them.
So, at the beginning stages of small companies, a Kubernetes cluster can work well without setting resource requests and limits, but as your teams and projects grow in size, you risk encountering issues in this area. Adding requests and limits to your modules and namespaces requires very little additional effort and can save you from many troubles.
A little advertisement 🙂
Thank you for staying with us. Do you enjoy our articles? Want to see more interesting content? Support us by placing an order or recommending us to your friends, , a unique entry-level server alternative that we have created for you: (options available with RAID1 and RAID10, up to 24 cores and up to 40GB DDR4).
Dell R730xd at half the price in the Equinix Tier IV data center in Amsterdam? Only with us in the Netherlands! Dell R420 — 2x E5-2430 2.2GHz 6C 128GB DDR3 2x960GB SSD 1Gbps 100TB — from $99! Read about how
Source: habr.com
