

Distributed systems can be challenging to manage because they contain many dynamic, mutable components, all of which must function correctly to ensure system functionality. If one of the components fails, the system needs to detect it, bypass it, and fix it, all of which must happen automatically. In this series on 'Kubernetes Best Practices,' we will learn how to configure Readiness and Liveness tests to verify the health of a Kubernetes cluster.
Health Check is a simple way to let the system know whether an instance of your application is running or not. If an instance of your application is not functioning, other services should not access it or send it requests. Instead, the request should be sent to another instance of the application that is already running or will start later. Additionally, the system should return lost availability to your application.
By default, Kubernetes will start sending traffic to a pod when all the containers inside the pods are up and will restart containers when they crash. Initially, this default system behavior may be sufficient, but you can increase the reliability of your product deployment by using custom health checks.
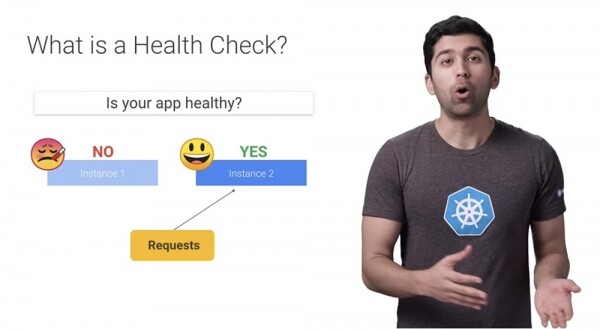
Fortunately, Kubernetes makes this pretty straightforward, so there’s no justification for ignoring such checks. Kubernetes provides two types of Health Check tests, and it's important to understand the differences in their applications.
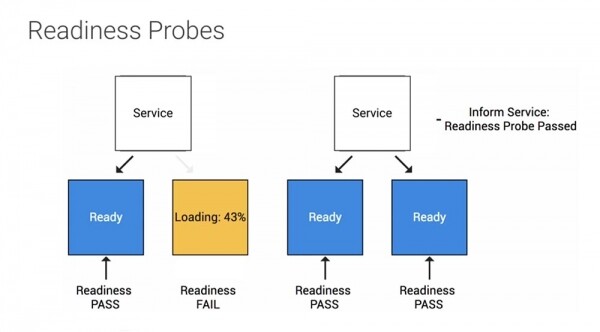
The Readiness test is designed to inform Kubernetes whether your application is ready to serve traffic. Before allowing the service to send traffic to the pod, Kubernetes must ensure the Readiness check is successful. If the Readiness test fails, Kubernetes will stop sending traffic to the pod until the testing passes successfully.
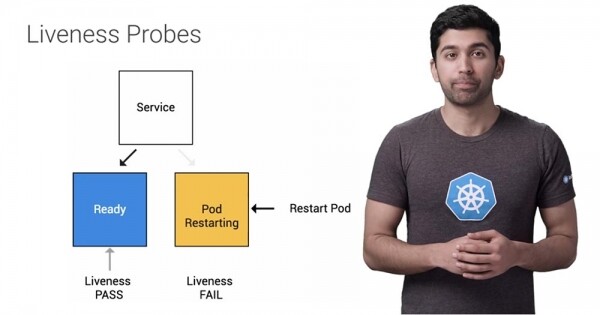
The Liveness probe informs Kubernetes whether your application is alive or dead. In the first case, Kubernetes will leave it alone; in the second, it will remove the dead pod and replace it with a new one.
Let's imagine a scenario where your application requires 1 minute to warm up and start. Your service will not begin working until the application is fully loaded and running, even though the workflow has already started. Additionally, you will face issues if you want to scale this deployment to multiple copies, as these copies must not receive traffic until they are fully ready. However, by default, Kubernetes will start sending traffic as soon as the processes inside the container begin.
When using the Readiness probe, Kubernetes will wait until the application is fully running before allowing the service to send traffic to the new copy.
Let's consider another scenario where the application hangs for a long time, ceasing to handle requests. Since the process continues to run, by default, Kubernetes will consider everything to be fine and continue sending requests to the non-responsive pod. However, with Liveness, Kubernetes will detect that the application is no longer handling requests and will, by default, restart the non-responsive pod.
Let's look at how readiness and liveness are tested. There are three testing methods — HTTP, Command, and TCP. You can use any of them for verification. The most common method for user testing is the HTTP probe.
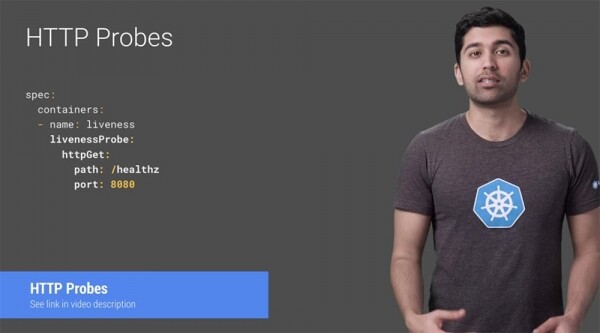
Even if your application is not an HTTP server, you can still create a lightweight HTTP server within your application to interact with the Liveness test. After that, Kubernetes will start pinging the pod, and if the HTTP response is within the range of 200 to 300 ms, it will indicate that the pod is 'healthy.' Otherwise, the module will be marked as 'unhealthy.'
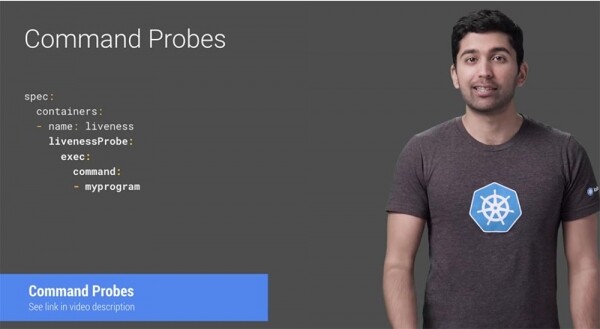
For tests, Kubernetes runs a command inside your container. If the command returns a zero exit code, the container is marked as healthy; otherwise, if the exit status is a number from 1 to 255, the container is marked as 'unhealthy'. This testing method is useful if you cannot or do not want to run an HTTP server but can execute a command to check the 'health' of your application.
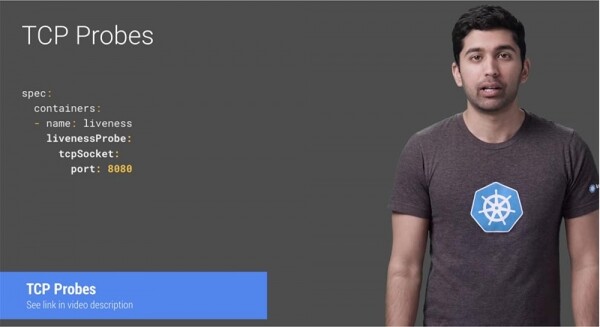
The final check mechanism is a TCP test. Kubernetes attempts to establish a TCP connection on the specified port. If successful, the container is considered healthy; if not, it is deemed unhealthy. This method can be useful if you’re using a scenario where testing via HTTP request or command execution does not work well. For example, the primary services for TCP checks will be gRPC or FTP.
Tests can be configured in various ways with different parameters. You can specify how often they should run, what the success and failure thresholds are, and how long to wait for responses. More detailed information is available in the Readiness and Liveness test documentation. However, one very important point in setting up the Liveness test is the initial delay for testing, initialDelaySeconds. As I mentioned, a failed execution of this test will result in the module being restarted. Therefore, you need to ensure that testing does not start until the application is ready to run, otherwise it will start restarting cyclically. I recommend using the P99 startup time or the average application startup time from the buffer. Remember to adjust this value as your application's startup time gets faster or slower.
Most experts will agree that Health Checks are a must-have for any distributed system, and Kubernetes is no exception. Using health checks for services ensures reliable and fault-tolerant operation of Kubernetes and poses no trouble for users.
Continuation will be available very soon…
A little advertisement 🙂
Thank you for staying with us. Do you enjoy our articles? Want to see more interesting content? Support us by placing an order or recommending us to your friends, , a unique entry-level server alternative that we have created for you: (options available with RAID1 and RAID10, up to 24 cores and up to 40GB DDR4).
Dell R730xd at half the price in the Equinix Tier IV data center in Amsterdam? Only with us in the Netherlands! Dell R420 — 2x E5-2430 2.2GHz 6C 128GB DDR3 2x960GB SSD 1Gbps 100TB — from $99! Read about how
Source: habr.com
