

Hello, Habr! We invite Data Engineers and Machine Learning specialists to a free Demo lesson . We also publish an article by Luca Monno — Head of Financial Analytics at CDP SpA.
One of the most useful and straightforward methods of machine learning is Ensemble Learning. Ensemble Learning is a method underlying XGBoost, Bagging, Random Forest, and many other algorithms.
There are many great articles on Towards Data Science, but I selected two stories ( and ), which I liked the most. So, why write another article about EL? Because I want to show you how it works with a simple example, that helped me realize there's no magic here.
When I first saw EL in action (with several very simple regression models), I couldn't believe my eyes, and I still remember the professor who taught me this method.
I had two different models (two weak learning algorithms) with out-of-sample R² values of 0.90 and 0.93, respectively. Before looking at the result, I thought I would get an R² somewhere between the two original values. In other words, I believed that EL could be used to ensure the model performed no worse than the worst one, but not as well as the best model could perform. To my greatest surprise, the results of simple averaging of predictions yielded an R² of 0.95.
At first, I began to look for an error, but then I thought there might be some magic hidden here!
What is Ensemble Learning
With EL, predictions from two or more models can be combined to create a more reliable and efficient model. There are many methodologies for working with model ensembles. Here, I will cover two of the most useful to provide a general overview.
regression
Using can average the performance of existing models. classification
Using can allow models to vote on labels. The label that was chosen the most often will be the one selected by the new model. Why EL works better
Why EL Works Better
The main reason why ensemble learning (EL) works better is that each prediction has an error (as we know from probability theory). Combining two predictions can help reduce the error and, consequently, improve performance metrics (RMSE, R², etc.).
The following diagram shows how two weak algorithms perform with a dataset. The first algorithm has a higher slope than necessary, while the second one is almost zero (possibly due to over-regularization). But ensemble delivers much better results.
Looking at the R² metric, the first and second training algorithms yield -0.01¹ and 0.22, respectively, while the ensemble achieves 0.73.
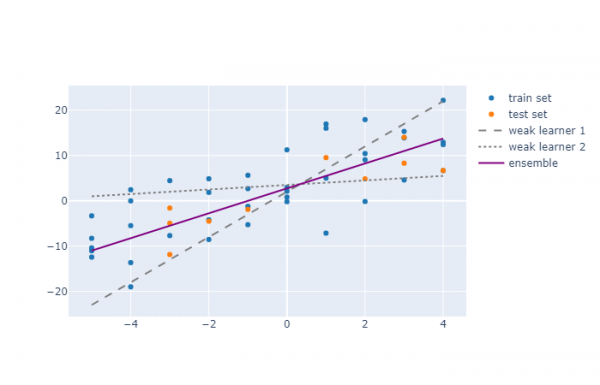
There are many reasons why an algorithm can perform poorly even in a basic example like this: maybe you decided to use regularization to avoid overfitting, or you chose not to exclude certain anomalies, or perhaps you used polynomial regression and selected the wrong degree (for example, using a second-degree polynomial when there is clear asymmetry in the test data better suited to a third degree).
When EL Works Better
Let's consider two training algorithms working with the same data.
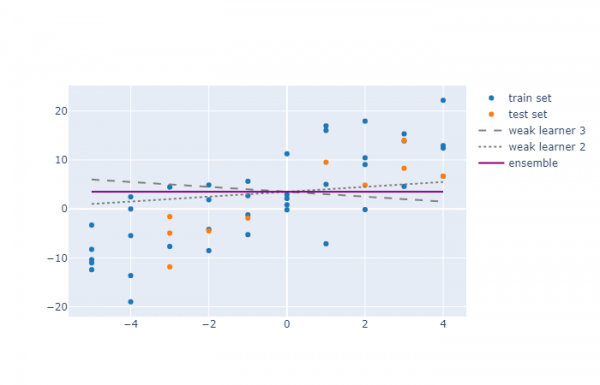
Here it shows that combining the two models did not significantly improve performance. Initially, the R² values for the two training algorithms were -0.37 and 0.22, respectively, while the ensemble resulted in -0.04. So the EL model got an average of the metrics.
However, there is a significant difference between these two examples: in the first case, the model errors were negatively correlated, while in the second they were positively correlated (the coefficients of the three models were not estimated but simply chosen by the author as an example).
Therefore, Ensemble Learning can be used to improve the bias/variance balance in any cases, but when model errors are not positively correlated, using EL can lead to an increase in performance..
Homogeneous and heterogeneous models
Ensemble Learning (EL) is often used with homogeneous models (like in this example or in random forests), but you can actually combine different models (linear regression + neural network + XGBoost) with various sets of explanatory variables. This is likely to lead to uncorrelated errors and improved performance.
Comparison with portfolio diversification
EL works similarly to diversification in portfolio theory, which is better for us.
In diversification, you try to reduce the variance of your metrics by investing in uncorrelated stocks. A well-diversified stock portfolio will typically perform better than the worst-performing individual stock, but never better than the best one.
Quoting Warren Buffett:
“Diversification is a protection against ignorance. It makes very little sense for those who know what they are doing.”
In machine learning, EL helps reduce the variance of your model, but this may lead to creating a model with overall performance better than the best initial model.
In conclusion
Combining multiple models into one is a relatively straightforward method that can address the bias-variance tradeoff and enhance performance.
If you have two or more models that work well, do not choose between them: use them all (but with caution)!
Interested in developing in this direction? Sign up for a free demo lesson and participate in — Machine Learning Engineer at Mail.ru Group.
Source: habr.com
