

Ding! It's 3 AM, you’re enjoying a wonderful dream, and suddenly — the phone rings. This week it's your turn, and apparently something has happened. The automated system is calling for you to sort it out. This is a crucial aspect of managing modern computer systems, but let's see how to make notifications more user-friendly.
Meet the monitoring philosophy that was born from my decades of duty in various monitoring teams. It has been heavily influenced by the true bible from Rob Ewaschuk. (My philosophy of notifications), included in the book on , and the book by John Allspaw. (Considerations for alert setup).
, and — thank you for your help in editing the post.
What is CASE?
I decided to come up with a nice acronym, similar to or . I call it the CASE method.It describes four key aspects to consider when working with automated monitoring:
- (contextual relevance)
- (actionable value)
- (symptom-focused)
- (evaluation).
If you use CASE, you treat notifications with a healthy indifference and won’t wake people up at night. It's essential to regularly assess monitoring for usefulness and effectiveness. When a person receives a notification, they will have better mental models and more confidence.
To make it easier to remember, imagine needing a CASE [that is, a case or reason — translator's note] to justify each alert. :sunglasses:
And why all this?
For many reasons. And CASE won't eliminate them all. But with it, you'll wake up to higher quality notifications at night. This method encompasses various organizational processes that will also help in this matter.
The beauty of the RED and USE methods is that they enable us not only to know how to work but also to communicate with each other in a common language. I hope that the CASE method will make it easier to discuss alerts that protect our systems without disturbing our colleagues.
The essence is to create a culture within the organization where notifications are treated with a healthy indifference. Notifications may be created for a reason, but there's no guarantee that their value will not diminish later. Why did we set up this notification? How recently were its criteria reviewed? The CASE method can help find answers to these questions.
Context-Heavy — contextual binding
3 AM is not the best time to read messages filled with complex terminology. To react effectively, clear information is needed. Ideally, it should be information about a specific issue that makes the context immediately clear, and notifications should be set up to facilitate this. This is the 'observation' and 'orientation' from This setup is worth the time because constantly distracting a person is even more costly. Let’s respect each other.
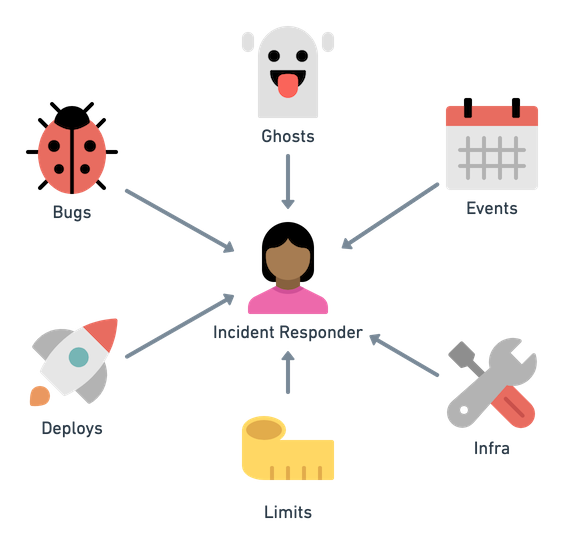
Problems have many sources. Especially ghosts.
How can we assist the on-call officer? First and foremost, the officer sees the notification, so all hypotheses are built upon it. Then they check instructions and dashboards, but are there always data relevant to that specific notification, rather than just general information? Olspo advises to think about 'how to interpret the notification or respond to it' (slide 29).A good notification is focused on the on-call officer, not just set based on threshold values.
Here are some ideas on how to enhance the context of notifications:
- Show the user something useful and tailor-made, not just ordinary instructions or dashboards. Earlier, we used dashboards for investigations tailored to specific notifications. This helps if the issue is known, but can confuse in other cases. Finding a balance is essential here.
- Share the notification's history: is it new? Does it trigger often? Is it seasonal?
- Show recent changes in system status. Has anything changed recently? (For example, a deployment or activation/deactivation of functionality.)
- Illustrate relationships and provide information for a mental model: system dependencies must be clearly visible, preferably indicating their operability.
- Quickly connect the user with the team: do they see current incidents or can they find out who else in the company received the notification? The incident management activated?
Ideally, the incident management program provides advice on how to enhance the context of notifications during incident investigations. There is always room for improvement!
Actionable — practical value
Should the on-call person do something in response to the notification? If nothing needs to be done or it's unclear what to do, why wake them up? It's important to avoid notifications that annoy the on-call staff without requiring action.
What should be done? What is needed?
In the past, when systems were simple and teams were small, we set up monitoring just to stay informed. A notification indicating that the load on a cluster has increased provides context if the service later encounters issues. At a larger scale, such notifications can cause confusion because our systems always operate under varying degrees of degradation. This quickly leads to and, of course, a loss of sensitivity. Consequently, the on-call person ignores or even filters out such notifications and does not always respond as necessary. Don't fall into this trap! Avoid setting up all notifications indiscriminately just to send them to some forgotten email folder.
Here's what a notification with practical value looks like:
- The notification requires action, not just delivers news.
- This action is complex or risky to automate. If it can be automated, then go ahead and automate it; stop bothering people!
- The notification includes urgent recommendations in the form of (SLA) or (RTO). Then the on-call person can engage the incident management program within the organization.
I want to clarify: I'm not saying that notifications should only come for the most critical SLOs (service-level objectives) for APIs. SLO monitoring is constantly fragmented and divided, requiring a consistent approach across all services. It’s clear that you'll monitor the most important SLOs for paying customers. However, infrastructure SLOs, such as databases, also need monitoring. Soon you'll have to focus on internal clients and support them. And so on, ad infinitum.
Symptom-based — focus on symptoms
Like it or not, you are working in a distributed system (Kawadji). As a result, you use different tactics to isolate services and protect them from failures (Trainor et al.) 3. And although a prolonged garbage collection or a stalled database query indicates issues, you shouldn’t rush to fix them if users aren’t experiencing problems in the near term.
These are important signals, and they can be practically valuable, but if they aren't affecting users, they are not urgent enough to distract the on-call engineer. Cause-based notifications are snapshots of our mental models about system failures. It’s better to track critical symptoms than to try to list all potential causes of the failure.
To make notifications practically valuable, focus on , which are important to users. Evashchuk refers to this as “monitoring for users.” Remember that this philosophy needs to be applied organization-wide. If urgent problems arise with a service deep within the infrastructure, the appropriate team will address them. Protecting systems from such failures is an entirely different matter (Trainor et al., section on strategies for minimizing critical dependencies).
Symptoms are not that volatile
Richard Cook reminds us that in complex systems, there are plenty of flaws, deficiencies, and issues. Trying to list all possible causes is a Sisyphean task. You are trying to describe issues, and they are constantly changing. Cindy Sridharan believes that “systems don’t necessarily have to be in a perfect state every second,” and it is better to use a more human approach ( (“Observability of Distributed Systems”), 7).
Avoid notifications based on incident occurrence
Typically, notifications are set up for causes to address incidents. However, these limited notifications about the fact that an incident occurred create a false sense of security, as the system continually invents new ways to fail.
Don’t deceive yourself with cause-based notifications. Instead, consider:
- Why did the symptom-based notification miss the problem?
- Would it be helpful to enhance the context for the user?
- How to improve monitoring tools to diagnose faster rather than accumulating notification alerts about incidents?
Monitoring tools for diagnosis will only help if you view them as a way to transition from symptoms to solutions. Without this feedback, you will be overwhelmed by late notifications and graphs of past failures — with no insight into future issues. This presents a great opportunity for an organization to shift from defense to offense. Developers and product managers will share clear expectations and goals. The case — CASE (:wink:) — for each notification is clear.
Cause-based notifications are tolerable in moderate quantities.
Sometimes our system leaves us little choice regarding cause-based notifications. At other times, on-call staff understand perfectly that a symptom will inevitably lead to a failure, hence it carries practical value. Perhaps you are just unsure about what is happening and are setting notifications for precaution. Hopefully, this action is required only temporarily until we change the system to address performance issues.
Keep other CASE components in mind when dealing with such situations. Just because it's temporary doesn't mean you shouldn't think critically.
Evaluated — evaluation
Any changes in the system (new code, new infrastructure, or anything new) expand the range of failures (Cook, 3). Is this notification still functioning as expected? Clear and relevant mental models of systems and experiences in responding to certain alerts support — are key features Defects in systems are continuously evolving, and we must keep pace with them.
It's essential to regularly assess the quality of each notification to ensure they function as intended. Dear leaders! It will be much easier for your teams if you help them streamline this process! Here are a few ideas for assessment:
- Use , or other notification testing methods. The team can handle this themselves without needing a heavyweight incident management system!
- Enable data collection on all incidents-related notifications in the incident management program. Mark useful, harmful, irrelevant, unclear, etc. Use them as feedback.
- Proper notifications trigger infrequently and are thoroughly checked. Ensure all links work and point to the correct context, etc.
- If a notification never triggers or triggers too often, something is wrong with it. Fix it or remove it. Beware of excessive passivity or activity!
- Set expiration timestamps for notifications. If the expiration date has passed, evaluate the notification using the CASE method and update the timestamp. Regularly check expiration, just like food.
- Streamline the process of improving notifications. Use code-based monitoring and store notifications in a Git repository. Pull requests help engage the team, and you'll have a history of past notifications. This way, you won't be afraid to change notifications or ask for permission from those responsible for them.
- Establish feedback for notifications, even if it's just a , so on-call staff can mark notifications as useless or intrusive. Embed a link or call to action within the notification and regularly review the feedback.
- Set a team rule — let on-call staff work on simplifying on-call duties when there's little work. Make sure everything gets slightly better after you than it was before.
Conclusion
I believe the CASE method helps developers and organizations discuss the configuration and sending of automated notifications. A developer can start evaluating notifications using the CASE method, and then the entire organization can join with other developers, management, and incident management programs to keep notifications in good shape. No special tools or complex processes are needed for this.
The entire industry should consider the human factor during on-call duty without sacrificing top-notch customer service. All these tools and practices can and should be improved. I hope the CASE method helps with this.
Enjoy enhanced notifications!
Source: habr.com
