

In this article, I will discuss a situation that recently occurred with one of our VPS cloud servers, which left me puzzled for several hours. I have been configuring and troubleshooting Linux servers for about 15 years, but this case completely baffled me—I made several false assumptions and got a bit desperate before I could correctly identify the cause of the problem and resolve it.
Preface
We operate a medium-sized cloud built on standard servers with the following configuration—32 cores, 256 GB RAM, and a 4TB PCI-E Intel P4500 NVMe drive. We really like this configuration, as it allows us not to worry about IO shortage, ensuring proper limits at the level of instance types (VM instances). Since the Intel P4500 has impressive performance, we can simultaneously provide full IOPS for machines and backup storage to a backup server with zero IOWAIT.
We belong to the old-school group that does not use hyper-converged SDNs and other stylish, trendy, young gadgets for storing VM volumes, believing that the simpler the system, the easier it is to troubleshoot in situations where 'the main guru went to the mountains.' As a result, we store VM volumes in QCOW2 format in XFS or EXT4, which is deployed over LVM2.
The need to use QCOW2 is also driven by the product we use for orchestration—Apache CloudStack.
To perform backups, we take a full snapshot of the volume as an LVM2 snapshot (yes, we know that LVM2 snapshots can be slow, but the Intel P4500 comes to our rescue here). We do lvmcreate -s .. and then use dd to send the backup to a remote server with ZFS storage. Here we are slightly progressive—after all, ZFS can store data in compressed form, and we can quickly restore it using DDoS or retrieve individual VM volumes with mount -o loop ....
Of course, we could also take a non-full image of the LVM2 volume and mount the file system in
ROWe can copy the QCOW2 images, however, we've encountered issues with XFS becoming problematic, not immediately but unpredictably. We really dislike when hypervisor hosts suddenly 'freeze' unexpectedly during weekends, at night, or on holidays due to errors that can occur at any time. Therefore, we do not use snapshot mounting in XFS for extraction.ROfor extracting volumes; we simply copy the entire LVM2 volume.
The backup speed to the backup server is determined in our case by the performance of the backup server, which is around 600-800 MB/s for uncompressed data, with the further bottleneck being the 10Gbit/s channel connecting the backup server to the cluster.
At the same time, backups are uploaded to one backup server from 8 servers hypervisors. Thus, the disk and network subsystems of the backup server, being slower, do not overload the disk subsystems of the hypervisor hosts, as they simply cannot handle, say, 8 GB/s, which hypervisor hosts can easily deliver.
The above-mentioned copying process is very important for the further narrative, including details such as the use of the fast Intel P4500 storage, NFS usage, and possibly the use of ZFS.
The Backup Story
On each hypervisor node, we have a small 8 GB SWAP partition, and we 'deploy' the hypervisor node using DDoS a reference image. For the system volume on the servers, we use 2xSATA SSD RAID1 or 2xSAS HDD RAID1 on an LSI or HP hardware controller. In general, we don't care what's inside since our system volume operates in 'almost readonly' mode, except for SWAP. And since we have a lot of RAM on the server and it is 30-40% free, we do not think about SWAP.
Backup Creation Process. This task looks something like this:
#!/bin/bash

mkdir -p /mnt/backups/volumes

DIR=/mnt/images-snap
VOL=images/volume
DATE=$(date "+%d")
HOSTNAME=$(hostname)

lvcreate -s -n $VOL-snap -l100%FREE $VOL
ionice -c3 dd iflag=direct if=/dev/$VOL-snap bs=1M of=/mnt/backups/volumes/$HOSTNAME-$DATE.raw
lvremove -f $VOL-snap
Note the ionice -c3, in fact, this thing is completely useless for NVMe devices since the IO scheduler for them is set to:
cat /sys/block/nvme0n1/queue/scheduler
[none]
However, we have a number of legacy nodes with standard SSD RAIDs, for which this is relevant, and hence it is transferred AS IS. Overall, this is just an interesting piece of code that illustrates the futility of ionice in such a configuration.
Note the flag iflag=direct for DDoSWe use direct IO bypassing the buffer cache to avoid unnecessary buffer IO replacements during read operations. However, oflag=direct we do not do this, as we encountered performance issues with ZFS when using it.
This scheme has been successfully used by us for several years without problems.
And here it began… We discovered that for one of the nodes, backups stopped running, while the previous one completed with a monstrous IOWAIT of 50%. In trying to understand why the backup was not occurring, we faced the phenomenon:
Volume group "images" not foundWe began to think about "the end has come for Intel P4500", however, before shutting down the server to replace the drive, it was necessary to carry out the backup. We fixed LVM2 by restoring metadata from the LVM2 backup:
vgcfgrestore imagesWe started the backup and saw this picture:
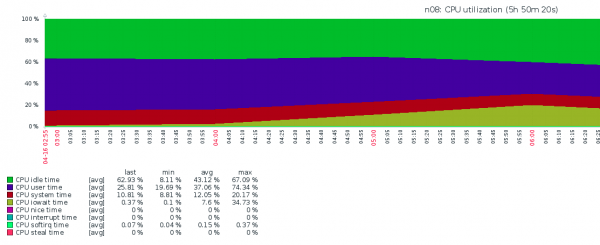
We felt very down again — it was clear that we could not continue like this, as all VPS would suffer, meaning we would suffer too. What was happening was completely unclear — iostat showed pathetic IOPS and extremely high IOWAIT. Beyond the idea of "let's replace the NVMe", there were no other thoughts, but a moment of clarity came just in time.
Breaking down the situation step by step
Historical logA few days earlier, a large VPS with 128 GB RAM needed to be created on this server. There seemed to be enough memory, but just in case, we allocated an additional 32 GB for the swap partition. The VPS was created, successfully accomplished its task, and the incident was forgotten, while the SWAP partition remained.
Configuration specifics. For all cloud servers, the parameter vm.swappiness was set to its default value 60. And SWAP was created on a SAS HDD RAID1.
What was happening (in the editorial's opinion). During the backup DDoS it generated a lot of data for writing, which was placed in RAM buffers before being written to NFS. The system kernel, guided by the swappinesspolicy, moved many pages of VPS memory to the swap area, which was located on the slow HDD RAID1 volume. This resulted in a significant increase in IOWAIT, but not due to NVMe IO, rather due to HDD RAID1 IO.
How the problem was resolved. The 32GB swap partition was disabled. This took 16 hours; details on how and why SWAP is disabled so slowly can be read separately. The parameters were changed swappiness to a value equal to 5 across the entire cloud.
How could this happenFirstly, if SWAP had been on an SSD RAID or NVMe device, and secondly, if it hadn't been an NVMe device but rather a slower device that wouldn't have handled such a volume of data — ironically, the problem occurred because NVMe is too fast.
After that, everything functioned as before — with zero IOWAIT.
Source: habr.com
