

I want to share with you my first successful experience in restoring the full functionality of a Postgres database. I got acquainted with the Postgres DBMS six months ago, and I had no prior experience in database administration.
I work as a semi-DevOps engineer in a large IT company. Our company develops software for high-load services, and I am responsible for system performance, maintenance, and deployment. I was tasked with a standard job: updating an application on one server. The application is written in Django, and during the update, migrations (changes to the database structure) occur, and before this process, we take a full database dump using the standard pg_dump tool, just in case.
During the dump process, an unexpected error occurred (Postgres version – 9.5):
pg_dump: Dumping the contents of table "ws_log_smevlog" failed: PQgetResult() failed.
pg_dump: Error message from server: ERROR: invalid page in block 4123007 of relation base/16490/21396989
pg_dump: The command was: COPY public.ws_log_smevlog [...]
pg_dump: [parallel archiver] a worker process died unexpectedly
Error "invalid page in block" indicates problems at the file system level, which is very bad. Various forums suggested performing FULL VACUUM (see section 6g above there). zero_damaged_pages to resolve this issue. Well, let's give it a try…
Preparing for recovery
WARNING! Make sure to back up Postgres before any attempt to restore the database. If you have a virtual machine, stop the database and take a snapshot. If it's not possible to take a snapshot, stop the database and copy the contents of the Postgres directory (including WAL files) to a secure location. The main thing in our case is to avoid making things worse. Read .
Since the database was generally functional, I limited myself to the usual database dump but excluded the table with damaged data (the option -T, --exclude-table=TABLE in pg_dump).
The server was physical, so taking a snapshot was impossible. Backup completed, moving on.
Checking the file system
Before attempting to restore the database, you need to ensure that everything is okay with the file system. If there are any errors, fix them, as otherwise, you could make things worse.
In my case, the file system with the database was mounted at "/srv" and the type was ext4.
Stopping the database: systemctl stop postgresql@9.5-main.service and we check that the file system is not being used by anyone and can be unmounted with the command lsof:
lsof +D /srv
I also had to stop the Redis database since it was also being used "/srv". Then I unmounted /srv (umount).
The file system check was performed using the utility e2fsck with the -f option (Force checking even if filesystem is marked clean):
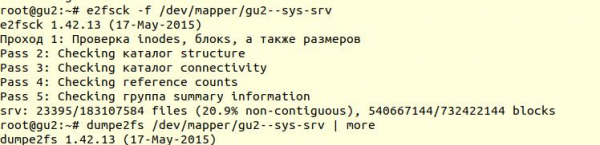
. Next, using the utility dumpe2fs (sudo dumpe2fs /dev/mapper/gu2—sys-srv | grep checked) you can verify that the check actually took place:
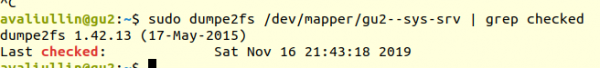
e2fsck it indicates that no issues were found at the ext4 filesystem level, meaning we can continue attempting to recover the database, specifically returning to vacuum full (of course, the file system needs to be mounted back and the database started).
If you have a physical server, make sure to check the status of the disks (via smartctl -a /dev/XXX) or RAID controller, to ensure that the problem is not hardware-related. In my case, the RAID turned out to be 'hardware', so I asked a local admin to check the RAID status (the server was several hundred kilometers away from me). He said that there were no errors, which means we can definitely start recovery.
Attempt 1: zero_damaged_pages
Connect to the database via psql with an account that has superuser privileges. We specifically need a superuser because the option zero_damaged_pages can only be changed by them. In my case, it's postgres:
psql -h 127.0.0.1 -U postgres -s [database_name]
Option zero_damaged_pages is necessary to ignore read errors (from the postgrespro site):
Upon detecting a corrupted page header, Postgres Pro typically reports an error and interrupts the current transaction. If the zero_damaged_pages parameter is enabled, the system instead issues a warning, zeros out the corrupted page in memory, and continues processing. This behavior destroys data, specifically all rows in the corrupted page.
Enable the option and try to do a full vacuum of the table:
VACUUM FULL VERBOSE 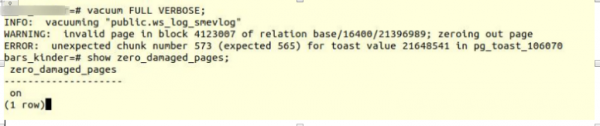
Unfortunately, it failed.
We encountered a similar error:
INFO: vacuuming "“public.ws_log_smevlog”
WARNING: invalid page in block 4123007 of relation base/16400/21396989; zeroing out page
ERROR: unexpected chunk number 573 (expected 565) for toast value 21648541 in pg_toast_106070– the mechanism for storing 'long data' in Postgres when they do not fit into one page (default 8kb).
Attempt 2: reindex
The first suggestion from Google did not help. After a few minutes of searching, I found the second suggestion – to perform a reindex corrupted table. I have encountered this advice in many places, but it was not trustworthy. Let's do a reindex:
reindex table ws_log_smevlog 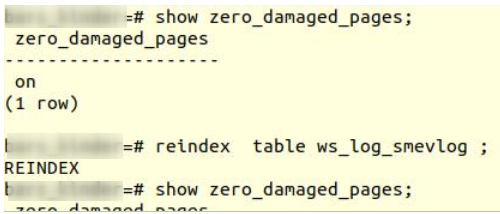
reindex completed without issues.
However, that did not help, VACUUM FULL crashed with a similar error. Since I was used to failures, I began looking for advice online and stumbled upon a rather interesting .
Attempt 3: SELECT, LIMIT, OFFSET
The article above suggested looking at the table row by row and deleting problematic data. First, it was necessary to review all rows:
for ((i=0; i/dev/null || echo $i; doneIn my case, the table contained 1 628 991 rows! Ideally, one should have taken care of , but that is a topic for another discussion. It was Saturday, I ran this command in tmux and went to sleep:
for ((i=0; i/dev/null || echo $i; doneBy morning, I decided to check how things were going. To my surprise, I found that only 2% of the data had been scanned in 20 hours! I did not want to wait 50 days. Another complete failure.
But I did not give up. I became curious why the scanning was taking so long. From the documentation (again on postgrespro), I learned:
OFFSET specifies how many rows to skip before starting to return rows.
If both OFFSET and LIMIT are specified, the system first skips the OFFSET rows, then starts counting rows for the LIMIT.When using LIMIT, it is important to also use an ORDER BY clause so that the result rows are returned in a specific order. Otherwise, unpredictable subsets of rows will be returned.
It is clear that the command written above was incorrect: first of all, there was no order by, the result could have been erroneous. Secondly, Postgres would first need to scan and skip the OFFSET rows, and as the OFFSET number increased, the performance would drop even further.
Attempt 4: take a dump in text format
Then I came up with what seemed like a brilliant idea: to take a dump in text format and analyze the last written row.
But first, let's familiarize ourselves with the structure of the table ws_log_smevlog:
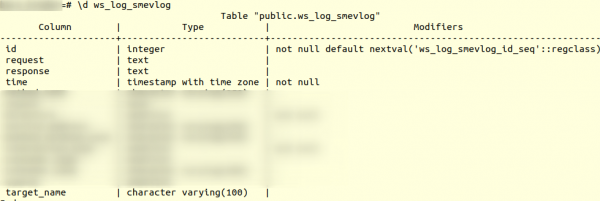
In our case, we have a column "id", which contained a unique identifier (counter) for the row. The plan was as follows:
- Let's start taking a dump in text format (as SQL commands)
- At a certain point, the dump extraction was interrupted due to an error, but the text file would still be saved on the disk.
- We look at the end of the text file, thereby finding the identifier (id) of the last line that was successfully extracted.
I started extracting the dump in text format:
pg_dump -U my_user -d my_database -F p -t ws_log_smevlog -f ./my_dump.dumpThe dump extraction, as expected, was interrupted with the same error:
pg_dump: Error message from server: ERROR: invalid page in block 4123007 of relation base/16490/21396989 Next, through tail I checked the end of the dump (tail -5 ./my_dump.dump) and found that the dump was interrupted on the line with id 186 525. "So, the problem is with the line with id 186 526, it's corrupted, and that one needs to be deleted!" – I thought. But, after querying the database:
«select * from ws_log_smevlog where id=186529it turned out that everything was fine with that line... The lines with indices 186 530 — 186 540 also worked without issues. Another 'brilliant idea' failed. Later, I understood why this happened: when deleting or changing data from a table, they are not physically removed but marked as 'dead tuples', then comes autovacuum and marks these rows as deleted and allows these rows to be reused. To clarify, if data in the table changes and autovacuum is enabled, then they are not stored sequentially.
Attempt 5: SELECT, FROM, WHERE id=
Failures make us stronger. You should never give up; you need to push through and believe in yourself and your abilities. So I decided to try another option: just to see all the records in the database one by one. Knowing the structure of my table (see above), we have an id field, which is unique (the primary key). In the table, we have 1,628,991 rows and id they are sequential, which means that we can simply iterate through them one by one:
for ((i=1; i/dev/null || echo $i; doneFor those who don't understand, the command works as follows: it scans the table line by line and sends stdout to /dev/null, but if the SELECT command fails, an error message is output (stderr is sent to the console) and the line containing the error is displayed (thanks to ||, which means that there were issues with the select command (exit code is not 0)).
I was lucky; I had indexes created on the field id:
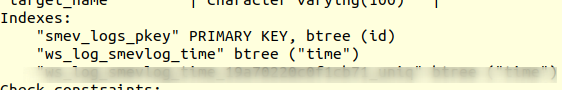
And this means that finding the row with the required id shouldn't take much time. In theory, it should work. So, let's run the command in tmux and we go to sleep.
By morning, I discovered that about 90,000 records had been processed, which is just over 5%. A great result compared to the previous method (2%)! But I didn't want to wait 20 days...
Attempt 6: SELECT, FROM, WHERE id >= and id <
The client had an excellent server allocated for the database: a dual-processor Intel Xeon E5-2697 v2, in our setup there were a total of 48 threads! The server load was average, and we could easily handle about 20 threads. There was also plenty of RAM: a whopping 384 gigabytes!
Therefore, the team needed to be parallelized:
for ((i=1; i/dev/null || echo $i; doneI could have written a nice and elegant script, but I chose the fastest way to parallelize: manually breaking the range 0-1628991 into intervals of 100,000 records and running 16 commands of the following type:
for ((i=N; i/dev/null || echo $i; doneBut that’s not all. Ideally, connecting to the database also takes some time and system resources. It wasn't very reasonable to connect 1,628,991 records, agree? So let's retrieve 1,000 rows at a time instead of one with a single connection. In the end, the command transformed into this:
for ((i=N; i=$i and id/dev/null || echo $i; doneWe open 16 windows in a tmux session and run the commands:
1) for ((i=0; i=$i and id/dev/null || echo $i; done
2) for ((i=100000; i=$i and id/dev/null || echo $i; done
…
15) for ((i=1400000; i=$i and id/dev/null || echo $i; done
16) for ((i=1500000; i=$i and id/dev/null || echo $i; done
A day later, I received the first results! Namely (the values XXX and ZZZ have already been lost):
ERROR: missing chunk number 0 for toast value 37837571 in pg_toast_106070
829000
ERROR: missing chunk number 0 for toast value XXX in pg_toast_106070
829000
ERROR: missing chunk number 0 for toast value ZZZ in pg_toast_106070
146000
This means that we have three rows containing errors. The IDs of the first and second problematic records were between 829,000 and 830,000, and the ID of the third was between 146,000 and 147,000. Next, we simply needed to locate the exact IDs of the problematic records. For this, we review our range with the problematic records in steps of 1 and identify the IDs:
for ((i=829000; i/dev/null || echo $i; done
829417
ERROR:  unexpected chunk number 2 (expected 0) for toast value 37837843 in pg_toast_106070
829449
for ((i=146000; i/dev/null || echo $i; done
829417
ERROR:  unexpected chunk number ZZZ (expected 0) for toast value XXX in pg_toast_106070
146911
Happy Ending
We found problematic entries. Let's access the database via psql and try to delete them:
my_database=# delete from ws_log_smevlog where id=829417;
DELETE 1
my_database=# delete from ws_log_smevlog where id=829449;
DELETE 1
my_database=# delete from ws_log_smevlog where id=146911;
DELETE 1
To my surprise, the records were deleted without any issues even without the option zero_damaged_pages.
Then I connected to the database and made VACUUM FULL (I think it was unnecessary), and finally successfully took a backup using pg_dump. The dump completed without any errors! The problem was solved in such a simple way. I was beyond happy after so many failures to finally find a solution!
Acknowledgments and Conclusion
This is how my first experience of restoring a real Postgres database turned out. I will remember this experience for a long time.
Lastly, I would like to thank PostgresPro for the translated documentation into Russian and for , which were very helpful during the problem analysis.
Source: habr.com
