

Hello, Habr!
In In this article, we discussed why it may be necessary to generate random numbers for participants who do not trust each other, the requirements for such random number generators, and we examined two approaches to their implementation.
In this section, we will take a detailed look at another approach that utilizes threshold signatures.
A bit of cryptography
To understand how threshold signatures work, one must grasp a bit of basic cryptography. We will use two concepts: scalars, or simply numbers, which we will denote with lowercase letters (x, y) and points on an elliptic curve, which we will denote with uppercase letters.
To understand the basics of threshold signatures, it is not necessary to know how elliptic curves function, apart from a few fundamental things:
Points on an elliptic curve can be added and multiplied by a scalar (multiplication by a scalar will be denoted as xG, although the notation Gx is also frequently used in the literature). The result of addition and multiplication by a scalar is a point on the elliptic curve.
Knowing only the point G and its product with a scalar xG does not allow one to compute x.
We will also use the concept of a polynomial p(x) of degree k-1. In particular, we will use the following property of polynomials: if we know the value p(x) for any k distinct x (and have no further information about p(x)), we can compute p(x) for any other x.
Interestingly, for any polynomial p(x) and a certain point on the curve G, knowing the value p(x)G for any k of various values x, one can also compute p(x)G for any x.
This information is sufficient to delve into the details of how threshold signatures work and how to use them for generating random numbers.
Random number generator based on threshold signatures
Let’s assume that n participants want to generate a random number, and we want the participation of any k of them to be enough to generate the number, but for malicious actors, who control k-1 or fewer participants, to be unable to predict or influence the generated number.
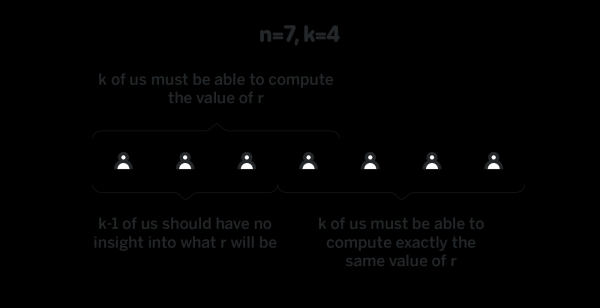
Assume there exists such a polynomial p(x) of degree k-1, such that the first participant knows p(1), the second knows p(2), and so on (nn-th knows p(n)). Also, assume that for some predetermined point G , everyone knows p(x)G for all values x. We will refer to it as p(i) "private component" i-th participant (because only i-th participant knows it), and p(i)G "public component" i-th participant (because all participants know it). As you remember, knowledge p(i)G is not enough to recover p(i).
Creating such a polynomial so that only i-thparticipant and no one else knows their private component — is the most complex and interesting part of the protocol, and we will discuss it below. For now, let's assume we have such a polynomial, and all participants know their private components.
How can we use such a polynomial to generate a random number? First, we need a string that has not been used before as input for the generator. In the case of the blockchain, the hash of the last block h is a good candidate for such a string. Let participants want to create a random number using h as seed. First, participants convert h to a point on the curve using any predefined function:
H = scalarToPoint(h)
Then each participant i calculates and publishes Hi = p(i)H, which they can do because they know p(i) and H. Revealing Hi does not allow other participants to recover the private component i-th participant, and therefore one set of private components can be used from block to block. Thus, the costly polynomial creation algorithm described below needs to be performed only once.
Once k participants revealed Hi = p(i)H, everyone can compute Hx = p(x)H for everyone x due to the property of polynomials, which we discussed in the previous section. At this point, all participants compute H0 = p(0)H, and this is the resulting random number. Note that no one knows p(0), and therefore the only way to calculate p(0)H — is interpolation p(x)H, which is only possible when k values p(i)H are known. Revealing any smaller number p(i)H does not provide any information about p(0)H.
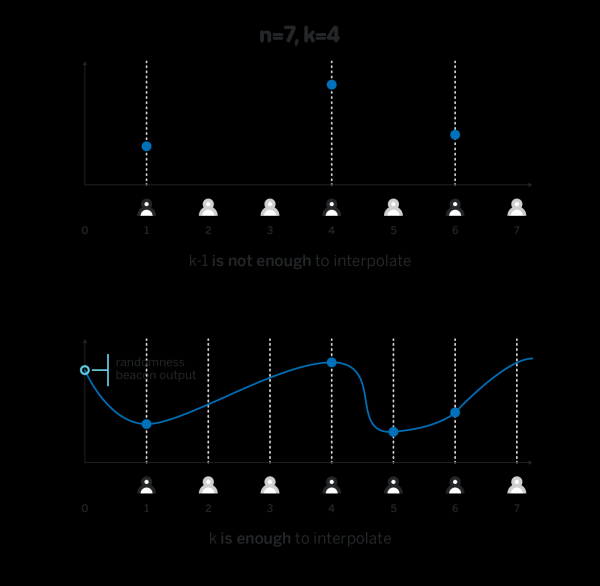
The above generator has all the properties we want: attackers controlling only k-1 participants, or fewer, have no information or influence on the output, while any k participants can compute the resulting number, and any subset of k participants will always arrive at the same result for the same seed.
There is one problem that we carefully sidestepped above. For the interpolation to work, it is important that the value Hi published by each participant i actually equals p(i)H. Since no one other than the i-th participant knows p(i), no one other than i-ththe participant can verify that Hi has been correctly calculated, and without some cryptographic proof of correctness, Hi an attacker can publish any value as Hi, and arbitrarily influence the output of the random number generator.:
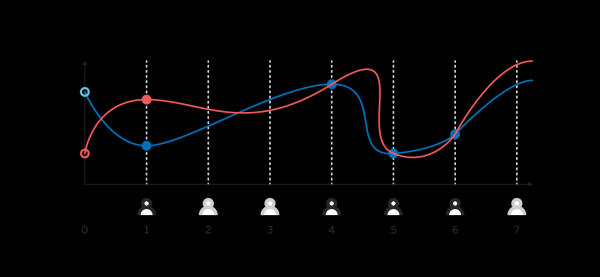 Different values H_1 sent by the first participant lead to different resulting H_0.
There are at least two ways to prove the correctness Hi, we will cover them after we discuss polynomial generation.
Polynomial Generation
In the previous section, we assumed that we have such a polynomial p(x) of degree k-1 that the participant i knows p(i), and no one else has any information about this value. In the next section, we will need some predetermined point G to be known by everyone. p(x)G for everyone x.
In this section, we will assume that each participant has some private key locally xi, such that the corresponding public key Xi is known to all.
One possible protocol for generating the polynomial is as follows:
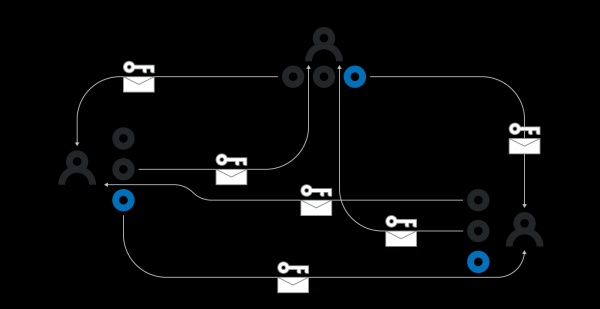
Each participant i locally creates an arbitrary polynomial pi(x) of degree k-1. They then send to each participant j the value pi(j), encrypted with the public key Xj. Thus, only i-ththe j-th participant knows and i(j). The participantthe j-th participant knows also publicly announces ppi(j)G i inclusive. All participants use some consensus to select for everyone j from 1 up to k participants whose polynomials will be used. Since some participants may be offline, we cannot wait for all
participants to publish their polynomials. The result of this step is a set k comprising at least n the polynomials created in step (1). Z Participants ensure that the values known to them k i(j) correspond to the publicly announced.
pi(j)G. pAfter this step, only the polynomials should remain for which the privately transmitted calculates its private component p(j) Z as the sum of pAfter this step, only the polynomials should remain for which the privately transmitted calculates its private component
Each participant j i(j) for all . Each participant also calculates all values pi(x)G for all i. pp(x) – i downward API support (simultaneously with this in Zis truly a polynomial of degree p(x)G pi(x)G for all i. k-1, downward API support (simultaneously with this in Z.
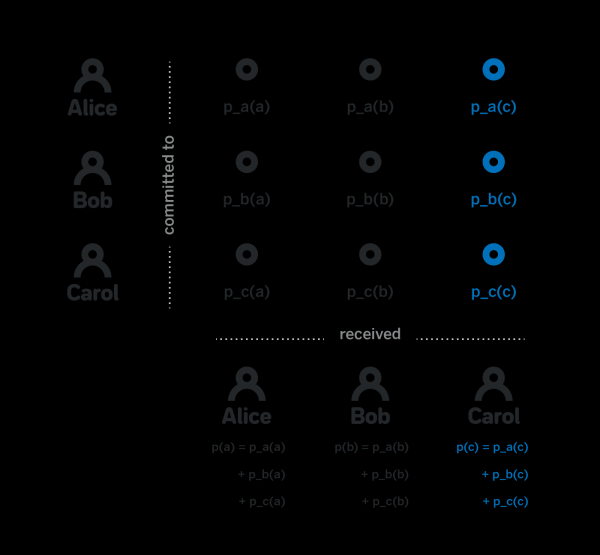
Note that because it is the sum of individual i(x), each of which is a polynomial of degree. k-1, because this is the sum of individual pi(x), each of which is a polynomial of degree k-1. Then, note that while each participant j knows p(j), they have no information about p(x) for x ≠ j. Indeed, to compute this value, they need to know all pi(x), and as long as the participant j does not know at least one of the selected polynomials, they do not have sufficient information about p(x).
This is the entire process of polynomial generation that was necessary in the previous section. Steps 1, 2, and 4 above have a fairly obvious implementation. However, step 3 is not so trivial.
Specifically, we need to be able to prove that the encrypted pi(j) indeed corresponds to the published calculates its private component If we cannot prove this, an attacker i can send garbage instead of pi(j) to the participant j, and the participant j will not be able to obtain the actual value pi(j), and will be unable to compute their private component.
There is a cryptographic protocol that allows for creating an additional message proofi(j), such that any participant, having some value e, along with proofi(j) and pi(j)G, can locally verify that e – this is indeed pi(j), encrypted with participant's key j. Unfortunately, the size of such a proof is incredibly large, and given that it is necessary to publish O(nk) such proofs, using them for this purpose will not be feasible.
Instead of proving that pi(j) corresponds to pi(j)G we can allocate a very large timeframe in the polynomial generation protocol, during which all participants verify the received encrypted pi(j), and if the decrypted message does not match the public pi(j)G, they publish a cryptographic proof that the encrypted message they received is incorrect. Proving that the message do not corresponds to pi(G) is much easier than proving its correspondence. It should be noted that this requires each participant to appear in the network at least once during the time allocated for creating such proofs, and relies on the assumption that if they published such a proof, it will reach all other participants within that same allotted time.
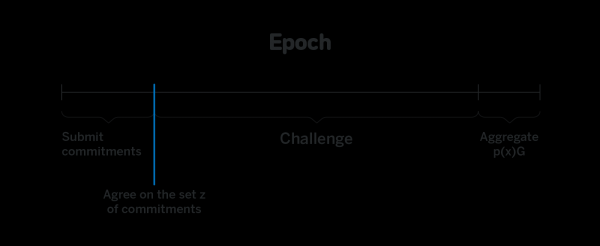
If a participant did not appear in the network during this timeframe, and they indeed had at least one incorrect component, then this particular participant will not be able to participate in further number generation. The protocol, however, will still function if there is at least k participants who have either just received correct components or managed to leave evidence of the incorrectness within the allotted time.
Proofs of correctness H_i
The last part to discuss is how to prove the correctness of those published Hi, namely that Hi = p(i)H, without revealing p(i).
Let's recall that the values H, G, p(i)G are public and known to everyone. The operation of obtaining p(i) knowing p(i)G and G is called discrete logarithm, or dlog, and we want to prove that:
dlog(p(i)G, G) = dlog(Hi, H)
without disclosure p(i). Constructions for such proofs exist, for instance.
With such a construction, each participant together with Hi sends proof of correctness according to the construction.
When a random number is generated, it often needs to be used by participants other than those who generated it. Such participants need to send all Hi and accompanying proofs along with the number.
The curious reader may ask: since the final random number is H0, and p(0)G – is public information, why is proof needed for each individual Hi, why not just send proof that
dlog(p(0)G, G) = dlog(H0, H)
The problem is that with the Schnorr Protocol, such a proof cannot be created because no one knows the value p(0), necessary for creating the proof, and moreover, the entire random number generator is based on the fact that no one knows this value. Therefore, it is necessary to have all values Hi and their individual proofs to prove correctness. H0.
However, if there were some operation at points on elliptic curves that semantically resembles multiplication, the proof of correctness H0 would be trivial, we would simply verify that
H0 × G = p(0)G × H
If the chosen curve supports , such a proof works. In this case H0 is not only the output of the random number generator that any participant who knows G, H and p(0)G. H0 is also a signature on the message that was used as the seed, confirming that k and n the participants signed this message. Thus, if the seed is the hash of the block in the blockchain protocol, then H0 it is at the same time a multi-signature on the block and a very good random number.
In conclusion
This article is part of a series of technical articles in the blog. NEAR is a blockchain protocol and platform for developing decentralized applications with a focus on ease of development and user-friendliness.
The protocol code is open, and our implementation is written in Rust, which can be found at .
You can see what development looks like on NEAR and experiment in the online IDE .
You can follow all the news in Russian in the and in , and in English in the official .
See you soon!
Source: habr.com
