

Hello everyone! My name is Nikolai Golov. I previously worked at Avito and led the Data Platform for six years, managing all databases: analytical (Vertica, ClickHouse), streaming, and OLTP (Redis, Tarantool, VoltDB, MongoDB, PostgreSQL). During this time, I dealt with a large number of databases—ranging from conventional to unusual, and with non-standard use cases.
Currently, I work at ManyChat. Essentially, it’s a startup—new, ambitious, and rapidly growing. When I first joined the company, I faced the classic question: 'What database and DBMS should a young startup consider from the current market?'
In this article, based on my presentation at , I will answer this question. The video version of the presentation is available on .
Well-known databases of 2020
It's now 2020, and I surveyed the landscape and observed three types of databases.
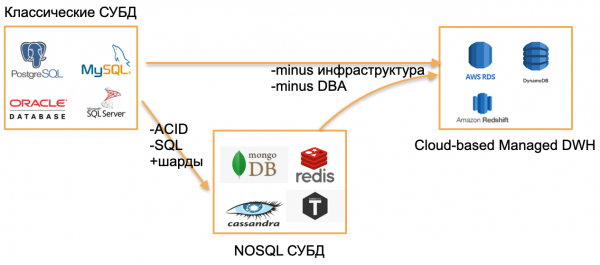
The first type is traditional OLTP databases: PostgreSQL, SQL Server, Oracle, MySQL. They were created long ago, yet they remain relevant because developers are well acquainted with them.
The second type is databases from the 'noughties'.They attempted to move away from traditional models by discarding SQL, conventional structures, and ACID, adding built-in sharding and other appealing features. Examples include Cassandra, MongoDB, Redis, and Tarantool. All these solutions aimed to offer something fundamentally new to the market and found their niche, proving extremely convenient for certain tasks. I will refer to these databases by the umbrella term NOSQL.
'Noughties' have ended, and the world has become accustomed to NOSQL databases, making what I believe is the next leap—towards managed databases.These databases have the same core as traditional OLTP databases or new NoSQLs. However, they do not require DBAs or DevOps and operate on managed hardware in the cloud. For the developer, it’s 'just a database' that works somewhere, without concern for server installation, who configured it, or who maintains it.
Examples of such databases include:
- AWS RDS—a managed layer over PostgreSQL/MySQL.
- DynamoDB—an AWS alternative to a document-based database, akin to Redis and MongoDB.
- Amazon Redshift—a managed analytical database.
At their core, these are old databases, but they are elevated in a managed environment, with no need for hardware interaction.
Note: The examples are taken from the AWS environment, but their counterparts also exist in Microsoft Azure, Google Cloud, or Yandex.Cloud.
So, what's new about this? In 2020, none of this is.
The concept of Serverless
Something truly new in the market in 2020 is serverless solutions.
I will try to explain what this means by using a typical service or backend application as an example.
To deploy a regular backend application, we buy or rent a server, copy the code to it, publish an endpoint externally, and regularly pay for the rent, electricity, and data center services. This is the standard scheme.
Is there another way? With serverless services, there is.
The focus of this approach is: no server, not even renting a virtual instance in the cloud. To deploy the service, we copy the code (functions) to a repository and publish an external endpoint. Then we simply pay for each call to that function, completely ignoring the hardware on which it runs.
I will try to illustrate this approach with images.
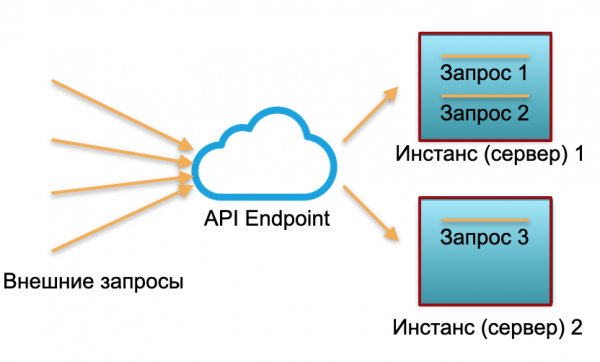
Classic deployment. We have a service with a certain load. We spin up two instances: physical servers or instances in AWS. External requests are directed to these instances, which process them.
As seen in the picture, the servers are utilized differently. One is utilized at 100%, handling two requests, while another is only at 50% — partially idle. If there are not three requests but 30, then the entire system will not cope with the load and will start to lag.
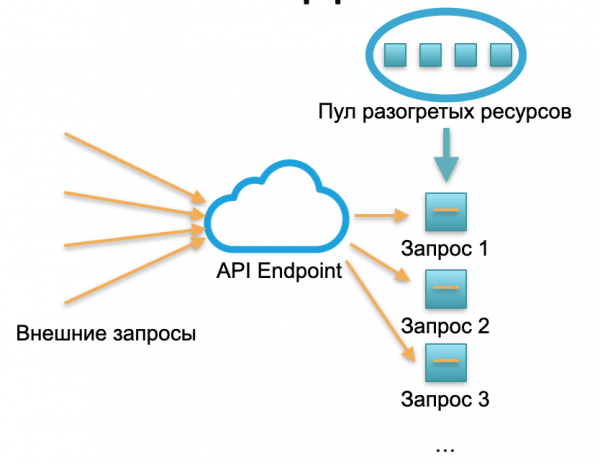
Serverless deployment. In a serverless environment, such a service has no instances or servers. There is a pool of warmed-up resources — small prepared Docker containers with the deployed function code. The system receives external requests, and for each one, the serverless framework spins up a small container with the code: it processes that specific request and then kills the container.
One request — one container spun up, 1000 requests — 1000 containers. And the deployment on physical servers is already the cloud provider's responsibility. It is completely hidden by the serverless framework. In this concept, we pay for each call. For example, if one call comes in a day — we pay for one call, if a million in a minute — we pay for a million. Or per second, that happens too.
The concept of publishing a serverless function is suitable for a stateless service. However, if you require a stateful service, you would add a database to the service. In this case, when it comes to working with state, each stateful function simply reads from and writes to the database. Moreover, it can use any of the three types of databases described at the beginning of the article.
What is the common limitation for all these databases? It's the costs associated with a constantly running cloud or physical server (or multiple servers). Regardless of whether we use a classic or managed database, whether there’s a DevOps engineer and an admin or not, we still pay for hardware, electricity, and data center rent 24/7. If we have a classic database, we pay for the master and slave. If it’s a highly-loaded sharded database, we pay for 10, 20, or 30 servers, and this expense is ongoing.
The presence of permanently reserved servers in the expense structure was previously perceived as an unavoidable evil. There are also other complexities with traditional databases, such as limits on the number of connections, scaling restrictions, and geo-distributed consensus—these can be addressed in certain databases, but not all at once or perfectly.
Serverless Database — A Theory
The question of 2020: can we also make a database serverless? Everyone has heard about serverless backends… so why not try to create a serverless database as well?
This sounds strange because a database is a stateful service, which isn't typically suited for a serverless infrastructure. Additionally, the state of a database is often quite large: gigabytes, terabytes, and even petabytes in analytical databases. It’s not easy to run such a large state in lightweight Docker containers.
On the other hand, almost all modern databases involve a vast amount of logic and components: transactions, integrity consensus, procedures, relational dependencies, and much more logic. A significant portion of the logic in a database requires relatively small state. Gigabytes and terabytes are primarily used only by a small part of the database logic that is directly related to executing queries.
Accordingly, the idea is: if part of the logic allows for stateless execution, why not split the database into Stateful and Stateless parts?
Serverless for OLAP Solutions
Let’s take a look at how a database can be partitioned into Stateful and Stateless components in practical examples.
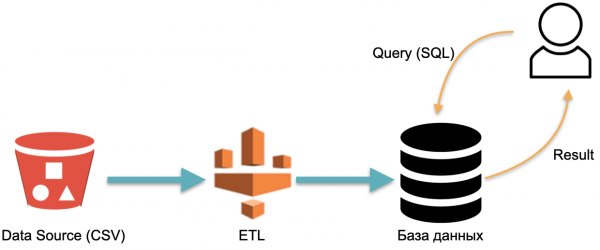
For example, we have an analytical database.: external data (red cylinder on the left), an ETL process that loads data into the database, and an analyst who sends SQL queries to the database. This is a classic data warehouse workflow.
In this scheme, the ETL is executed conditionally only once. After that, you must continually pay for the servers on which the data-rich database operates so that there’s something to send queries to.
Let's consider an alternative approach implemented in the AWS Athena Serverless database. Here, there is no permanently allocated hardware that stores the loaded data. Instead:
- The user sends an SQL query to Athena. The Athena optimizer analyzes the SQL query and searches the metadata store for the specific data needed to execute the query.
- Based on the collected data, the optimizer retrieves the necessary data from external sources into a temporary storage (temporary database).
- In the temporary storage, the user’s SQL query is executed, and the result is returned to the user.
- The temporary storage is cleared, and resources are released.
In this architecture, we only pay for the query execution process. No queries mean no costs.
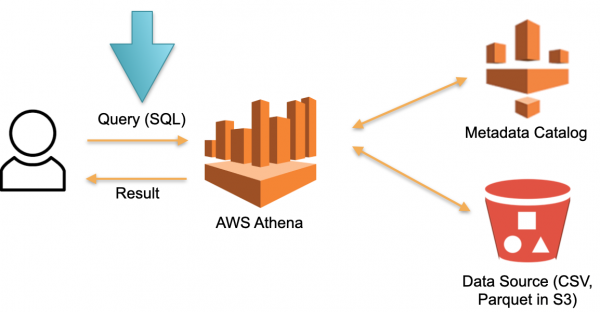
This is a working approach, and it is implemented not only in Athena Serverless but also in Redshift Spectrum (in AWS).
From the example of Athena, it is clear that the Serverless database operates on real queries with tens and hundreds of terabytes of data. For hundreds of terabytes, hundreds of servers would be needed, but we don’t have to pay for them — we pay for the queries. The speed of each query is (very) low compared to specialized analytical databases like Vertica, but we do not pay for downtime.
Such a database is applicable for rare analytical ad-hoc queries. For example, when we spontaneously decide to test a hypothesis on a huge volume of data. For these cases, Athena is perfect. For regular queries, such a system becomes expensive. In this case, cache the data in some specialized solution.
Serverless for OLTP solutions.
In the previous example, OLAP tasks (analytical) were considered. Now, let's look at OLTP tasks.
Let's consider a scalable PostgreSQL or MySQL. We can start a typical managed instance of PostgreSQL or MySQL with minimal resources. As the instance experiences more load, we’ll connect additional replicas to distribute part of the read load. If there are no requests or load, we will turn off the replicas. The first instance is the master, while the others are replicas.
This concept is implemented in a database called Aurora Serverless AWS. The principle is simple: requests from external applications are handled by a proxy fleet. When it detects an increase in load, it allocates computing resources from pre-warmed minimal instances—connections are made as quickly as possible. Instances can also be shut down similarly.
Within Aurora, there is a notion of Aurora Capacity Unit, or ACU. This is essentially an instance (server). Each specific ACU can be a master or a slave. Each Capacity Unit has its own memory, CPU, and minimum disk space. Thus, one master and the others are read-only replicas.
The number of active Aurora Capacity Units is a configurable parameter. The minimum can be one or zero (in which case the database does not operate if there are no requests).
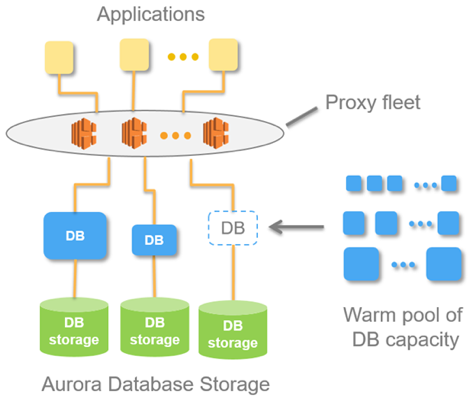
When the database receives requests, the proxy fleet activates Aurora Capacity Units, increasing the system's processing resources. The ability to scale resources up and down allows the system to 'juggle' resources: automatically terminating specific ACUs (replacing them with new ones) and applying all relevant updates to the terminated resources.
Aurora Serverless can scale its read load. However, this is not explicitly stated in the documentation. One might get the impression that they can establish a multi-master setup. Yet, there is no real magic to it.
This database is well-suited for avoiding large expenses on systems with unpredictable access. For example, when creating an MVP or marketing landing pages, we usually do not expect a stable load. Consequently, when access is not needed, we do not pay for instances. When unexpected traffic occurs, such as after a conference or an advertising campaign, large numbers of people visit the site and the load spikes, Aurora Serverless automatically handles this load and quickly connects the necessary resources (ACU). Once the conference is over and everyone forgets about the prototype, the servers (ACU) power down, and expenses drop to zero — convenient.
This solution is not suitable for stable high-load scenarios because it cannot scale the write load. All these connections and disconnections of resources occur at the so-called 'scale point' — a moment in time when the database is not occupied by a transaction or temporary tables. For instance, during the week, a scale point might not occur, and the database operates on the same resources, simply unable to scale up or down.
There's no magic — this is just ordinary PostgreSQL. However, the process of adding machines and disconnecting them is partially automated.
Serverless by design
Aurora Serverless is an older database rewritten for the cloud to leverage the unique advantages of serverless architectures. Now, let me tell you about a database that was originally designed for the cloud, embracing the serverless approach — serverless-by-design. It was developed without any assumptions about operating on physical servers.
This database is called Snowflake. It has three key components.
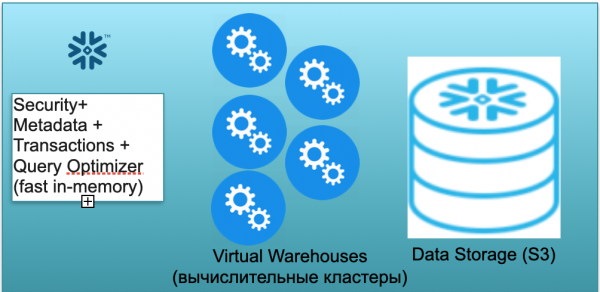
The first is the metadata block. This is a fast in-memory service that addresses security, metadata, transactions, and query optimization issues (as shown on the left illustration).
The second block consists of multiple virtual compute clusters for calculations (as illustrated by a set of blue circles).
The third block is the data storage system based on S3. S3 is a virtually limitless object storage service in AWS, akin to an infinitely scalable Dropbox for businesses.
Let's see how Snowflake operates, assuming a cold start. That is, the database exists, data is loaded into it, but there are no active queries. Therefore, if there are no queries to the database, we have a fast in-memory Metadata service running (the first block). We also have an S3 storage where the table data is stored, divided into so-called micro-partitions. For simplicity, if the table contains transactions, the micro-partitions represent transaction days. Each day is a separate micro-partition, a separate file. When the database operates in this mode, you only pay for the space occupied by the data. Moreover, the rate for space is very low (especially considering the significant compression). The metadata service also runs continuously, but it doesn't require many resources for query optimization, and can be considered conditionally free.
Now let's imagine that a user comes to our database and submits an SQL query. The SQL query is immediately sent for processing to the Metadata service. Consequently, upon receiving the query, this service analyzes it, the available data, the user's permissions, and if everything is in order, it creates an execution plan for the query.
Next, the service initiates the launch of the compute cluster. The compute cluster is a cluster of servers performing computations. This means it can contain 1 server, 2 servers, 4, 8, 16, 32 — however many you want. You submit the query and the launch of this cluster begins instantly for it. This really takes just a few seconds.
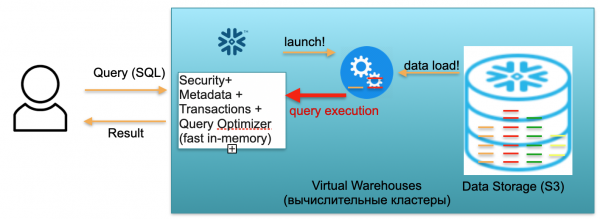
Next, after the cluster has started, micro-partitions needed for processing your specific request begin to copy from S3 to the cluster. For example, if executing an SQL query requires two partitions from one table and one from another, only those three necessary partitions will be copied to the cluster, rather than all tables in their entirety. This is why, and precisely because everything is within the same data center and connected by very fast channels, the entire data transfer process is very quick: within seconds, very rarely — within minutes, unless it involves some monstrous queries. Accordingly, micro-partitions are copied to the compute cluster, and upon completion, the SQL query is executed on that compute cluster. The result of this query can be a single line, multiple lines, or a table — these are sent back to the user for download, display in their BI tool, or any other use.
Each SQL query can not only aggregate data from previously loaded records but also load/formulate new data in the database. This means it can be a query that, for example, inserts new records into another table, leading to the creation of a new partition in the compute cluster, which, in turn, is automatically saved in the unified S3 storage.
The scenario described above, from the user's request to the raising of the cluster, loading data, executing queries, and obtaining results, is charged at a rate for the minutes of use of the deployed virtual compute cluster, the virtual warehouse. Rates vary depending on the AWS zone and cluster size, but on average, it is a few dollars per hour. A cluster of four machines costs twice as much as one with two machines, and a cluster of eight machines costs twice as much again. Options for 16, 32 machines are available depending on the complexity of the queries. However, you only pay for the minutes when the cluster is actually running, because when there are no queries, you essentially take your hands off, and after 5-10 minutes of waiting (a configurable parameter), it will turn itself off, free up resources, and become free.
It is entirely plausible to have a scenario where you submit a request, a cluster spins up, so to speak, in about a minute, takes another minute to process, then five minutes to shut down, and you end up paying for just seven minutes of the cluster's operation, rather than for months or years.
The first scenario described the use of Snowflake in a single-user context. Now let's consider a situation with multiple users, which is closer to a real-world scenario.
Let's assume we have many analysts and Tableau reports that continuously bombard our database with a large volume of simple analytical SQL queries.
In addition to this, let's say we have inventive Data Scientists who are trying to perform monstrous tasks with data, handling tens of Terabytes, analyzing billions and trillions of rows.
For the two types of workloads described above, Snowflake allows the deployment of multiple independent compute clusters of different sizes. These compute clusters operate independently but share consistent underlying data.
For a large number of lightweight queries, you can spin up 2-3 small clusters, each roughly the size of 2 machines. This behavior can also be implemented through automated settings. That is, you instruct, 'Snowflake, spin up a small cluster. If the load exceeds a certain threshold, spin up a similar second, third one. When the load starts to decrease, shut down the excess.' This ensures that no matter how many analysts come in and start looking at reports, there will be enough resources for everyone.
Additionally, if the analysts are not active and no one is viewing reports, the clusters can be completely shut down, and you stop paying for them.
At the same time, for heavy queries (from Data Scientists), you can deploy one very large cluster with roughly 32 machines. This cluster will also only be billed for the minutes and hours when your massive query is running.
The capability described above allows you to segregate not only two but multiple types of workloads across clusters (ETL, monitoring, report materialization, etc.).
Let's summarize Snowflake. The platform combines a beautiful concept and a functional implementation. At ManyChat, we use Snowflake for analytics on all available data. We have not three clusters as in the example, but between 5 and 9, of various sizes. We have conditional 16-machine, 2-machine, and even super-small 1-machine clusters for certain tasks. They successfully distribute the load and allow us to save significantly.
The platform successfully scales read and write loads. This is a huge distinction and a significant breakthrough compared to Aurora, which only handled read loads. Snowflake allows scaling write loads with these computing clusters. As I mentioned, we at ManyChat use several clusters; small and super-small clusters are mainly used for ETL processes, for data loading. Meanwhile, analysts work on medium clusters that are completely unaffected by ETL loads and therefore operate very quickly.
Accordingly, the platform is well-suited for OLAP tasks. Unfortunately, it is not yet applicable for OLTP loads. Firstly, this is a columnar database, with all the ensuing consequences. Secondly, the approach of spinning up a computing cluster for each query as needed and pouring data into it is, unfortunately, not fast enough for OLTP loads. Seconds of waiting for OLAP tasks is acceptable, but for OLTP tasks, it's not, ideally it should be 100 ms, and even better — 10 ms.
Summary
A serverless database is possible due to the separation of the database into Stateless and Stateful parts. You may have noticed that in all the examples provided, the Stateful part is, conditionally speaking, the storage of micro-partitions in S3, while the Stateless part consists of the optimizer, working with metadata, and handling security issues that can be elevated as independent lightweight Stateless services.
Executing SQL queries can also be perceived as lightweight state services that can pop up in serverless mode, like Snowflake computing clusters, downloading only the needed data, executing the query, and "extinguishing".
Production-level serverless databases are now available for use; they are operational. These serverless databases are already capable of handling OLAP tasks. Unfortunately, for OLTP tasks, they come with nuances due to certain limitations. On one hand, this is a downside. On the other hand, it presents an opportunity. Perhaps some of the readers will find a way to make an OLTP database completely serverless, without the restrictions of Aurora.
I hope you found this interesting. Here's to the serverless future 🙂
Source: habr.com
