

Note: translation.: adapting Kubernetes in GitLab is considered one of the two main factors contributing to the company’s growth. However, until recently, the infrastructure of the online service GitLab.com was built on virtual machines, and only about a year ago did the migration to K8s begin, which is still ongoing. We are pleased to present a translation of a recent article by a GitLab SRE engineer about how this is happening and what conclusions the engineers involved in the project are making.
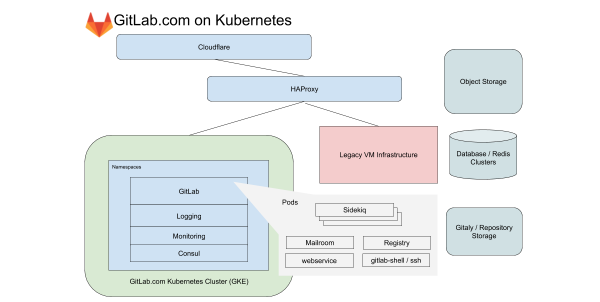
For almost a year, our infrastructure team has been working on migrating all the services running on GitLab.com to Kubernetes. During this time, we faced challenges not only related to moving services to Kubernetes but also managing hybrid deployment during the transition. This article will discuss the valuable lessons we've learned.
From the very beginning, GitLab.com servers operated in the cloud on virtual machines. These virtual machines are managed by Chef, and their installation occurs through our . in case an application needs updating, consists of simply updating the server pool in a coordinated sequential manner using a CI pipeline. This method—though slow and a bit ensures that GitLab.com applies the same installation and configuration methods as users of standalone (self-managed) GitLab installations that use our Linux packages for this purpose.
We use this method because it is crucial to experience all the joys and frustrations that ordinary community members face when installing and configuring their GitLab instances. This approach worked well for a while, but when the number of projects on GitLab exceeded 10 million, we realized it no longer met our needs for scaling and deployment.
First Steps Towards Kubernetes and Cloud-Native GitLab
In 2017, the to prepare GitLab for deployment in the cloud, as well as to allow users to install GitLab in Kubernetes clusters. At that time, we knew that migrating GitLab to Kubernetes would enhance the scalability of the SaaS platform, simplify deployments, and improve computational resource efficiency. However, many functions of our application depended on mounted NFS volumes, which slowed the transition from virtual machines.
The push towards cloud-native and Kubernetes enabled our engineers to plan a gradual transition, during which we eliminated some of the application’s dependencies on network storage while simultaneously continuing to develop new features. Since we began planning the migration in the summer of 2019, many of these constraints have been addressed, and the process of transitioning GitLab.com to Kubernetes is now in full swing!
Features of GitLab.com running on Kubernetes
For GitLab.com, we use a single regional GKE cluster that handles all application traffic. To minimize the complexity of the already convoluted migration, we focus on services that do not rely on local storage or NFS. GitLab.com primarily uses a monolithic Rails codebase, and we route traffic based on workload characteristics to different endpoints, isolated within their own node pools.
For the frontend, these types are divided into requests to web, API, Git SSH/HTTPS, and Registry. For the backend, we break jobs in the queue based on various characteristics depending on , which allow us to set Service Level Objectives (SLOs) for various loads.
All these services for GitLab.com are configured using an unmodified GitLab Helm chart. Configuration is done in sub-charts that can be selectively included as we gradually migrate services to the cluster. Even though it was decided not to include some of our stateful services, such as Redis, Postgres, GitLab Pages, and Gitaly, in the migration, using Kubernetes drastically reduces the number of VMs currently managed by Chef.
Transparency and configuration management of Kubernetes
All settings are managed by GitLab itself. Three configuration projects based on Terraform and Helm are used for this purpose. We strive to use GitLab to launch GitLab wherever possible, but we also have a separate GitLab installation functioning for operational tasks. This is necessary to avoid dependence on the availability of GitLab.com during deployments and updates to GitLab.com.
Although our pipelines for the Kubernetes cluster operate on a separate GitLab installation, the code repositories have mirrors publicly accessible at the following addresses:
- — the configuration wrapper for GitLab.com for the GitLab Helm chart;
- — contains configurations for services that are not directly related to the GitLab application. These include configurations for logging and monitoring the cluster, as well as for integrated tools like PlantUML;
- — the Terraform configuration for Kubernetes and the old (legacy) VM infrastructure. Here, all resources necessary for launching the cluster are configured, including the cluster itself, node pools, service accounts, and IP address reservations.

When changes are made, a public is displayed with a link to a detailed diff, which the SRE analyzes before making changes to the cluster.
For SRE, the link leads to a detailed diff in the GitLab installation used for operations, which is access-restricted. This enables employees and the community without access to the operational project (which is open only to SRE) to view the proposed configuration changes. By combining a public GitLab instance for the code with a private instance for CI pipelines, we maintain a unified workflow while ensuring independence from GitLab.com during configuration updates.
What we learned during the migration
During the relocation process, we accumulated experience that we apply to new migrations and deployments in Kubernetes.
1. Increased costs due to traffic between availability zones
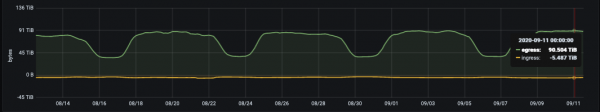
Daily egress statistics (bytes per day) for the Git repositories on GitLab.com
Google divides its network into regions, which in turn are broken down into availability zones (AZ). Git hosting is tied to large data volumes, so it's crucial for us to control network egress. For internal traffic, egress is free only if it remains within the boundaries of a single availability zone. At the time of writing this article, we deliver approximately 100 TB of data on a typical workday (and that's just for Git repositories). Services that in our old VM-based topology were on the same virtual machines now operate in different Kubernetes pods. This means that some of the traffic that was previously local to the VM could potentially cross the boundaries of availability zones.
Regional GKE clusters allow spanning multiple availability zones for redundancy. We are considering for services that generate large volumes of traffic. This will help reduce egress costs while maintaining cluster-level redundancy.
2. Resource limits, requests, and scaling
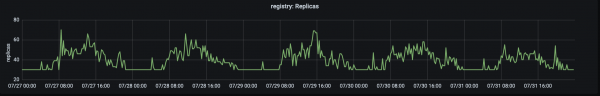
The number of replicas handling production traffic on registry.gitlab.com. Traffic peaks around ~15:00 UTC.
Our migration story began in August 2019 when we moved our first service—the GitLab Container Registry—into Kubernetes. This critical, high-traffic service was well suited for the initial migration, as it is a stateless application with few external dependencies. The first issue we encountered was the high number of pod evictions due to memory shortages on the nodes, which forced us to adjust requests and limits.
It was found that for an application whose memory consumption grows over time, low values for requests (reserving memory for each pod) combined with a "generous" hard limit on usage led to saturation (saturation) of the nodes and a high eviction rate. To resolve this issue, we decided to increase requests and lower limits. This relieved pressure on the nodes and ensured a pod lifecycle that did not exert too much pressure on the node. Now we are starting migrations with generous (and almost identical) request and limit values, adjusting them as necessary.
3. Metrics and Logs
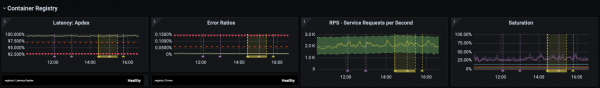
The infrastructure department focuses on latencies, error percentages, and saturation against set (SLOs) tied to .
Over the past year, one of the key events in the infrastructure department has been improvements in monitoring and working with SLOs. SLOs allowed us to set targets for individual services, which we closely monitored during the migration. But even with this improved observability, it is not always possible to immediately see problems using metrics and alerts. For example, by focusing on latencies and error percentages, we do not fully cover all scenarios of the service undergoing migration.
This issue was discovered almost immediately after transferring part of the workloads to the cluster. It became particularly acute when verifying functions with a low number of requests but very specific configuration dependencies. One of the key lessons learned from the migration was the need to consider not only metrics in monitoring but also logs and the 'long tail' (referring to on the graph - translator's note) of errors. Now for each migration, we include a detailed list of log queries (log queries) and plan clear rollback procedures that can be handed from one shift to another in case of issues.
Parallel servicing of the same requests on the old VM infrastructure and the new Kubernetes-based one presented a unique challenge. Unlike a lift-and-shift migration (quickly moving applications 'as is' to new infrastructure; more details can be read, for example, - translator's note), running parallel on "old" VMs and Kubernetes requires monitoring tools to be compatible with both environments and capable of combining metrics into a single view. It's essential that we use the same dashboards and log queries to achieve consistent observability during the transition period.
4. Switching traffic to the new cluster
For GitLab.com, part of the servers is allocated for . The canary cluster serves our internal projects and can also be . However, it is primarily designed to test changes made to the infrastructure and application. The first migrated service started by handling a limited amount of internal traffic, and we continue to use this method to ensure SLO compliance before directing all traffic to the cluster.
In the case of migration, this means that initially requests to internal projects are directed to Kubernetes, and then we gradually switch the remaining traffic to the cluster by adjusting the weight for the backend through HAProxy. During the transition from VMs to Kubernetes, it became clear that having a straightforward method for redirecting traffic between the old and new infrastructure was highly beneficial, allowing us to keep the old infrastructure ready for a rollback in the first few days after migration.
5. Backup capacities of pods and their utilization
Almost immediately, the following issue was identified: pods for the Registry service started quickly, but starting the pods for Sidekiq took up to The prolonged startup of pods for Sidekiq became problematic when we began migrating workloads to Kubernetes for workers that need to process jobs rapidly and scale quickly.
In this case, the lesson learned was that although the Horizontal Pod Autoscaler (HPA) in Kubernetes handles traffic growth well, it is important to consider the characteristics of workloads and allocate backup capacities for pods (especially in conditions of uneven demand distribution). In our case, there was a sudden spike in jobs, leading to rapid scaling, which resulted in CPU resource saturation before we could scale the node pool.
There is always a temptation to extract as much as possible from the cluster, however, after initially facing performance issues, we now start with a generous pod budget and later reduce it, closely monitoring the SLO. The launch of pods for the Sidekiq service has significantly accelerated and now takes an average of about 40 seconds. both GitLab.com and our self-managed installation users working with the official GitLab Helm chart have benefited.
Conclusion
After migrating each service, we rejoiced in the advantages of using Kubernetes in production: faster and more secure application deployment, scaling, and more efficient resource allocation. Moreover, the benefits of migration extend beyond the GitLab.com service. Users also benefit from each improvement to the official Helm chart.
I hope you enjoyed the story of our adventures with migrating to Kubernetes. We continue to migrate more and more services into the cluster. Additional information can be gleaned from the following publications:
- «»;
- «»;
- .
P.S. from the translator
Also read in our blog:
- «»;
- «»;
- «»;
- «».
Source: habr.com
