

Preface
Users, developers, and database administrators of MS SQL Server often encounter performance issues with databases or the DBMS as a whole, making monitoring MS SQL Server highly relevant.
This article serves as a supplement to the article and it will cover some aspects of monitoring MS SQL Server, specifically: how to quickly determine which resources are lacking, as well as recommendations for configuring trace flags.
To run the following scripts, you need to create the inf schema in the required database as follows:
Creating the inf schema
use ;
go
create schema inf;
Method for identifying insufficient RAM
The first indicator of RAM shortage is when the MS SQL Server instance consumes all the allocated RAM.
To do this, let's create the following view inf.vRAM:
Creating the view inf.vRAM
CREATE view [inf].[vRAM] as
select a.[TotalAvailOSRam_Mb]                  -- Amount of free RAM on the server in MB
		 , a.[RAM_Avail_Percent]                     -- Percentage of free RAM on the server
		 , a.[Server_physical_memory_Mb]              -- Total RAM on the server in MB
		 , a.[SQL_server_committed_target_Mb]        -- Total RAM allocated to MS SQL Server in MB
		 , a.[SQL_server_physical_memory_in_use_Mb]  -- Total RAM being consumed by MS SQL Server at the moment in MB
		 , a.[SQL_RAM_Avail_Percent]                  -- Percentage of free RAM for MS SQL Server relative to all allocated RAM for MS SQL Server
		 , a.[StateMemorySQL]                          -- Whether there is enough RAM for MS SQL Server
		 , a.[SQL_RAM_Reserve_Percent]                -- Percentage of reserved RAM for MS SQL Server relative to the total system RAM
		 -- Whether there is enough RAM for the server
		, (case when a.[RAM_Avail_Percent]5 and a.[TotalAvailOSRam_Mb]<8192 then 'Warning' when a.[RAM_Avail_Percent]<=5 and a.[TotalAvailOSRam_Mb]<2048 then 'Danger' else 'Normal' end) as [StateMemoryServer]
	from
	(
		select cast(a0.available_physical_memory_kb/1024.0 as int) as TotalAvailOSRam_Mb
			 , cast((a0.available_physical_memory_kb/casT(a0.total_physical_memory_kb as float))*100 as numeric(5,2)) as [RAM_Avail_Percent]
			 , a0.system_low_memory_signal_state
			 , ceiling(b.physical_memory_kb/1024.0) as [Server_physical_memory_Mb]
			 , ceiling(b.committed_target_kb/1024.0) as [SQL_server_committed_target_Mb]
			 , ceiling(a.physical_memory_in_use_kb/1024.0) as [SQL_server_physical_memory_in_use_Mb]
			 , cast(((b.committed_target_kb-a.physical_memory_in_use_kb)/casT(b.committed_target_kb as float))*100 as numeric(5,2)) as [SQL_RAM_Avail_Percent]
			 , cast((b.committed_target_kb/casT(a0.total_physical_memory_kb as float))*100 as numeric(5,2)) as [SQL_RAM_Reserve_Percent]
			 , (case when (ceiling(b.committed_target_kb/1024.0)-1024)<ceiling(a.physical_memory_in_use_kb/1024.0) then 'Warning' else 'Normal' end) as [StateMemorySQL]
		from sys.dm_os_sys_memory as a0
		cross join sys.dm_os_process_memory as a
		cross join sys.dm_os_sys_info as b
		cross join sys.dm_os_sys_memory as v
	) as a;
To determine that the MS SQL Server instance is consuming all of its allocated memory, you can use the following query:
select SQL_server_physical_memory_in_use_Mb, SQL_server_committed_target_Mb
from [inf].[vRAM];
If the SQL_server_physical_memory_in_use_Mb reading is consistently not less than SQL_server_committed_target_Mb, you should check the wait statistics.
To identify memory shortage through wait statistics, we will create the view inf.vWaits:
Creating the view inf.vWaits
CREATE view [inf].[vWaits] as
WITH [Waits] AS
    (SELECT
        [wait_type], --name of the wait type
        [wait_time_ms] / 1000.0 AS [WaitS],--Total wait time for this type in milliseconds. This includes signal_wait_time_ms
        ([wait_time_ms] - [signal_wait_time_ms]) / 1000.0 AS [ResourceS],--Total wait time for this type in milliseconds excluding signal_wait_time_ms
        [signal_wait_time_ms] / 1000.0 AS [SignalS],--Difference between the signaling time of the waiting thread and the start time of its execution
        [waiting_tasks_count] AS [WaitCount],--Number of waits of this type. This counter increments each time a wait begins
        100.0 * [wait_time_ms] / SUM ([wait_time_ms]) OVER() AS [Percentage],
        ROW_NUMBER() OVER(ORDER BY [wait_time_ms] DESC) AS [RowNum]
    FROM sys.dm_os_wait_stats
    WHERE [waiting_tasks_count]>0
		and [wait_type] NOT IN (
        N'BROKER_EVENTHANDLER',         N'BROKER_RECEIVE_WAITFOR',
        N'BROKER_TASK_STOP',            N'BROKER_TO_FLUSH',
        N'BROKER_TRANSMITTER',          N'CHECKPOINT_QUEUE',
        N'CHKPT',                       N'CLR_AUTO_EVENT',
        N'CLR_MANUAL_EVENT',            N'CLR_SEMAPHORE',
        N'DBMIRROR_DBM_EVENT',          N'DBMIRROR_EVENTS_QUEUE',
        N'DBMIRROR_WORKER_QUEUE',       N'DBMIRRORING_CMD',
        N'DIRTY_PAGE_POLL',             N'DISPATCHER_QUEUE_SEMAPHORE',
        N'EXECSYNC',                    N'FSAGENT',
        N'FT_IFTS_SCHEDULER_IDLE_WAIT', N'FT_IFTSHC_MUTEX',
        N'HADR_CLUSAPI_CALL',           N'HADR_FILESTREAM_IOMGR_IOCOMPLETION',
        N'HADR_LOGCAPTURE_WAIT',        N'HADR_NOTIFICATION_DEQUEUE',
        N'HADR_TIMER_TASK',             N'HADR_WORK_QUEUE',
        N'KSOURCE_WAKEUP',              N'LAZYWRITER_SLEEP',
        N'LOGMGR_QUEUE',                N'ONDEMAND_TASK_QUEUE',
        N'PWAIT_ALL_COMPONENTS_INITIALIZED',
        N'QDS_PERSIST_TASK_MAIN_LOOP_SLEEP',
        N'QDS_CLEANUP_STALE_QUERIES_TASK_MAIN_LOOP_SLEEP',
        N'REQUEST_FOR_DEADLOCK_SEARCH', N'RESOURCE_QUEUE',
        N'SERVER_IDLE_CHECK',           N'SLEEP_BPOOL_FLUSH',
        N'SLEEP_DBSTARTUP',             N'SLEEP_DCOMSTARTUP',
        N'SLEEP_MASTERDBREADY',         N'SLEEP_MASTERMDREADY',
        N'SLEEP_MASTERUPGRADED',        N'SLEEP_MSDBSTARTUP',
        N'SLEEP_SYSTEMTASK',            N'SLEEP_TASK',
        N'SLEEP_TEMPDBSTARTUP',         N'SNI_HTTP_ACCEPT',
        N'SP_SERVER_DIAGNOSTICS_SLEEP', N'SQLTRACE_BUFFER_FLUSH',
        N'SQLTRACE_INCREMENTAL_FLUSH_SLEEP',
        N'SQLTRACE_WAIT_ENTRIES',       N'WAIT_FOR_RESULTS',
        N'WAITFOR',                     N'WAITFOR_TASKSHUTDOWN',
        N'WAIT_XTP_HOST_WAIT',          N'WAIT_XTP_OFFLINE_CKPT_NEW_LOG',
        N'WAIT_XTP_CKPT_CLOSE',         N'XE_DISPATCHER_JOIN',
        N'XE_DISPATCHER_WAIT',          N'XE_TIMER_EVENT')
    )
, ress as (
	SELECT
	    [W1].[wait_type] AS [WaitType],
	    CAST ([W1].[WaitS] AS DECIMAL (16, 2)) AS [Wait_S],--Total wait time for this type in milliseconds. This includes signal_wait_time_ms
	    CAST ([W1].[ResourceS] AS DECIMAL (16, 2)) AS [Resource_S],--Total wait time for this type in milliseconds excluding signal_wait_time_ms
	    CAST ([W1].[SignalS] AS DECIMAL (16, 2)) AS [Signal_S],--Difference between the signaling time of the waiting thread and the start time of its execution
	    [W1].[WaitCount] AS [WaitCount],--Number of waits of this type. This counter increments each time a wait begins
	    CAST ([W1].[Percentage] AS DECIMAL (5, 2)) AS [Percentage],
	    CAST (([W1].[WaitS] / [W1].[WaitCount]) AS DECIMAL (16, 4)) AS [AvgWait_S],
	    CAST (([W1].[ResourceS] / [W1].[WaitCount]) AS DECIMAL (16, 4)) AS [AvgRes_S],
	    CAST (([W1].[SignalS] / [W1].[WaitCount]) AS DECIMAL (16, 4)) AS [AvgSig_S]
	FROM [Waits] AS [W1]
	INNER JOIN [Waits] AS [W2]
	    ON [W2].[RowNum] <= [W1].[RowNum]
	GROUP BY [W1].[RowNum], [W1].[wait_type], [W1].[WaitS],
	    [W1].[ResourceS], [W1].[SignalS], [W1].[WaitCount], [W1].[Percentage]
	HAVING SUM ([W2].[Percentage]) - [W1].[Percentage] < 95 -- percentage threshold
)
SELECT [WaitType]
      ,MAX([Wait_S]) as [Wait_S]
      ,MAX([Resource_S]) as [Resource_S]
      ,MAX([Signal_S]) as [Signal_S]
      ,MAX([WaitCount]) as [WaitCount]
      ,MAX([Percentage]) as [Percentage]
      ,MAX([AvgWait_S]) as [AvgWait_S]
      ,MAX([AvgRes_S]) as [AvgRes_S]
      ,MAX([AvgSig_S]) as [AvgSig_S]
  FROM ress
  group by [WaitType];
In this case, you can determine the lack of RAM with the following query:
SELECT [Percentage]
      ,[AvgWait_S]
  FROM [inf].[vWaits]
  where [WaitType] in (
    'PAGEIOLATCH_XX',
    'RESOURCE_SEMAPHORE',
    'RESOURCE_SEMAPHORE_QUERY_COMPILE'
  );
Here, you need to pay attention to the Percentage and AvgWait_S metrics. If they are significant together, there is a high probability that the instance of MS SQL Server is running low on memory. Significant values are determined individually for each system. However, you can start with the following indicators: Percentage >= 1 and AvgWait_S >= 0.005.
To output metrics to the monitoring system (for example, Zabbix), you can create the following two queries:
- what percentage of waiting types are using RAM (sum of all such waiting types):
select coalesce(sum([Percentage]), 0.00) as [Percentage] from [inf].[vWaits] where [WaitType] in ( 'PAGEIOLATCH_XX', 'RESOURCE_SEMAPHORE', 'RESOURCE_SEMAPHORE_QUERY_COMPILE' ); - how many milliseconds are consumed by waiting types for RAM (maximum value of all average delays for all such waiting types):
select coalesce(max([AvgWait_S])*1000, 0.00) as [AvgWait_MS]
from [inf].[vWaits]
       where [WaitType] in (
           'PAGEIOLATCH_XX',
           'RESOURCE_SEMAPHORE',
            'RESOURCE_SEMAPHORE_QUERY_COMPILE'
  );
Based on the dynamics of the obtained values for these two metrics, you can conclude whether there is enough RAM for the MS SQL Server instance.
Method for identifying excessive CPU load
To identify the lack of CPU time, you can simply use the system view sys.dm_os_schedulers. Here, if the runnable_tasks_count metric is consistently greater than 1, there is a high likelihood that the number of cores is insufficient for the MS SQL Server instance.
To output the metric to the monitoring system (for example, Zabbix), you can create the following query:
select max([runnable_tasks_count]) as [runnable_tasks_count]
from sys.dm_os_schedulers
where scheduler_id < 255;
Based on the dynamics of the obtained values for this metric, you can conclude whether there is enough CPU time (number of CPU cores) for the MS SQL Server instance.
However, it is important to remember that the queries themselves can request multiple threads at once. Sometimes, the optimizer cannot accurately assess the complexity of the query. As a result, the query may be allocated too many threads that cannot be processed simultaneously at that moment. This also causes a type of wait related to a lack of processor time and an increase in the queue for schedulers that use specific CPU cores, meaning the runnable_tasks_count metric will rise under such conditions.
In this case, before increasing the number of CPU cores, it is necessary to properly configure the parallelism properties of the MS SQL Server instance itself, and from version 2016, correctly configure the parallelism properties for the necessary databases:
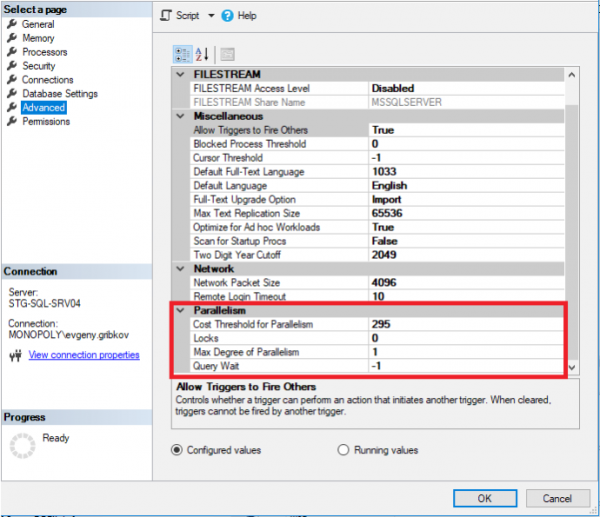
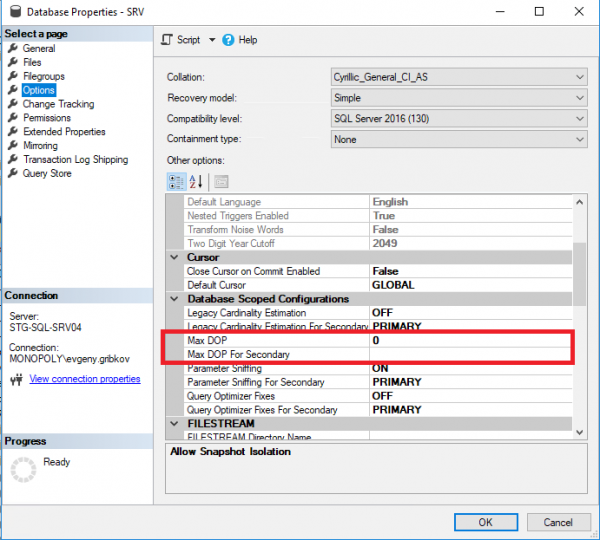
Attention should be paid to the following parameters:
- Max Degree of Parallelism - sets the maximum number of threads that can be allocated to each query (default is 0 - limited only by the operating system and the edition of MS SQL Server)
- Cost Threshold for Parallelism - the estimated cost for parallelism (default is 5)
- Max DOP - sets the maximum number of threads that can be allocated to each query at the database level (but not more than the value of the ‘Max Degree of Parallelism’ property) (default is 0 - limited only by the operating system and the edition of MS SQL Server, as well as the ‘Max Degree of Parallelism’ property of the entire MS SQL Server instance)
Here, it is impossible to provide a universally good recipe for all cases, meaning it is necessary to analyze heavy queries.
Based on my experience, I recommend the following algorithm for OLTP systems to set the parallelism properties:
- first, disable parallelism by setting the Max Degree of Parallelism at the instance level to 1
- analyze the heaviest queries and find the optimal number of threads for them
- set the Max Degree of Parallelism to the optimal number of threads obtained from point 2, and also set the Max DOP value for specific databases based on the value obtained from point 2 for each database
- analyze the heaviest queries and identify any negative effects from multithreading. If there are any, increase the Cost Threshold for Parallelism.
For systems such as 1C, Microsoft CRM, and Microsoft NAV, it is often suitable to disable multithreading.
If the Standard edition is set, usually, disabling multithreading is sufficient due to the fact that this edition is limited in terms of the number of CPU cores.
The algorithm described above is not suitable for OLAP systems.
Based on my experience, I recommend the following action plan for configuring the parallelism properties of OLAP systems:
- analyze the heaviest queries and find the optimal number of threads for them
- set the Max Degree of Parallelism to the optimal number of threads found in step 1, and for specific databases, set the Max DOP value obtained from step 1 for each database.
- analyze the heaviest queries and identify any negative effects from limiting parallelism. If there are any, either lower the Cost Threshold for Parallelism value or repeat steps 1-2 of this algorithm.
Thus, for OLTP systems, we move from single-threading to multi-threading, and for OLAP systems, we move from multi-threading to single-threading. This way, optimal parallelism settings can be found for both specific databases and the entire MS SQL Server instance.
It is also important to understand that the parallelism property settings need to be adjusted over time based on the performance monitoring results of MS SQL Server.
Recommendations for configuring trace flags
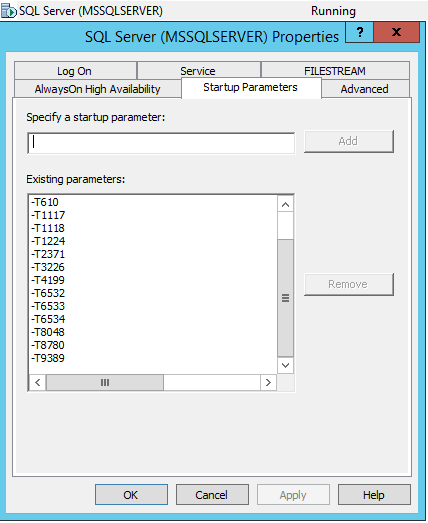
From my own experience and that of my colleagues, for optimal performance, I recommend setting the following trace flags at the MS SQL Server service startup level for versions 2008-2016:
- 610 — Reduces logging of inserts into indexed tables. Can help with inserts into tables with a large number of records and many transactions, during frequent long waits for WRITELOG due to changes in indexes.
- 1117 — If a file in the file group meets the automatic growth threshold requirements, all files in the file group are increased.
- 1118 — Forces all objects to be placed in different extents (prevents mixed extents), minimizing the need to scan the SGAM page, which is used to track mixed extents.
- 1224 — Disables lock escalation based on the number of locks. However, excessive memory usage may trigger lock escalation.
- 2371 — Changes the threshold for fixed automatic statistics updates to the threshold for dynamic automatic statistics updates. This is important for updating query plans regarding large tables, where incorrect determination of the number of records leads to erroneous execution plans.
- 3226 — Suppresses messages about successful backup execution in the error log.
- 4199 — Includes changes to the query optimizer released in cumulative updates and SQL Server update packages.
- 6532-6534 — Enables performance improvements for query operations with spatial data types.
- 8048 — Converts NUMA-allocated memory objects to CPU-allocated objects.
- 8780 — Allows for additional time allocation for query plan compilation. Some queries without this flag may be rejected due to lacking a query plan (a very rare error).
- 8780 — 9389 — Enables additional dynamic memory buffers for batch mode operators, allowing batch mode operators to request extra memory and avoid spilling to tempdb if additional memory is available.
Also, up to version 2016, it is useful to enable trace flag 2301, which incorporates advanced decision support optimization, thus aiding in the selection of more accurate query plans. However, starting from version 2016, it often has a negative effect on the total execution time of queries.
Additionally, for systems with a large number of indexes (for example, for 1C databases), I recommend enabling trace flag 2330, which disables index usage collection, positively impacting the system overall.
You can learn more about trace flags.
In the provided link, it is also important to consider the versions and builds of MS SQL Server, as for newer versions some trace flags are enabled by default or have no effect.
You can enable and disable trace flags using the DBCC TRACEON and DBCC TRACEOFF commands, respectively. See more details.
You can get the status of trace flags using the DBCC TRACESTATUS command:
To enable trace flags on the startup of the MS SQL Server service, go to SQL Server Configuration Manager and add the trace flags in the service properties using -T:
Summary
This article discussed some aspects of monitoring MS SQL Server that can promptly identify insufficient RAM and CPU idle time, as well as several other less obvious issues. The most commonly used trace flags were reviewed.
Sources:
»
»
»
»
»
»
»
Source: habr.com
