

We developed DevOps as best as we could. There were eight of us, and Vasya was the best when it came to Windows. Suddenly, Vasya left, and I was tasked with launching a new project that delivers Windows development. When I laid out the entire stack of Windows development on the table, I realized that the situation was painful...
This is how the story begins Alexander Sinchinov to . When the lead Windows specialist left the company, Alexander was faced with the question of what to do next. Transitioning to Linux, of course! Alexander will share how he managed to set a precedent and transfer part of the Windows development to Linux using the example of a project implemented for 100,000 end users.
How to easily and effortlessly deliver a project in RPM, using TFS, Puppet, Linux .NET Core? How to maintain the versioning of the project's database when the developers hear the words Postgres and Flyway for the first time and the deadline is the day after tomorrow? How to integrate with Docker? How to motivate .NET developers to abandon Windows and smoothies in favor of Puppet and Linux? How to resolve ideological conflicts when there is no strength, desire, or resources to support Windows in production? This, as well as Web Deploy, testing, CI, the practices of using TFS in existing projects, and of course, the broken crutches and working solutions will be discussed in Alexander's presentation.
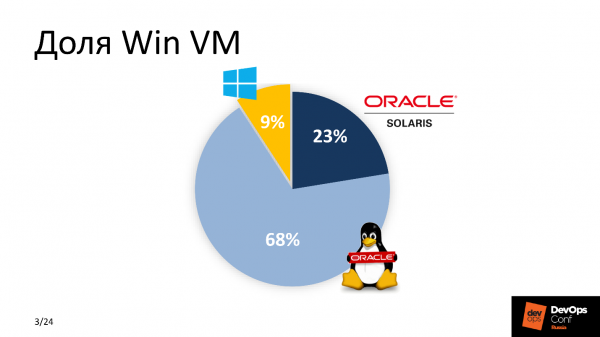
So, Vasya left, the task is on me, and the developers are waiting with forks in hand. When I finally realized that I couldn't bring Vasya back, I got down to business. First, I assessed the percentage of Windows VMs in our park. The score was not in favor of Windows.
Since we are actively developing DevOps, I realized that something needed to change in the approach to deploying the new application. The decision was clear - to migrate everything to Linux whenever possible. Google helped me - at that time, .NET had already been ported to Linux, and I understood that this was the solution!
Why .NET Core in conjunction with Linux?
There were several reasons. Between 'paying money' and 'not paying', most would choose the latter - as did I. A license for MSDB costs about $1,000, and maintaining a fleet of Windows virtual machines can amount to hundreds of dollars. For a large company, these are significant expenses. Therefore, savings — is the first reason.It's not the most important, but it's one of the significant ones.
Windows virtual machines consume more resources than their Linux counterparts - they are heavy. Given the scale of a large company, we chose Linux.
The system seamlessly integrates into the existing CI. We consider ourselves progressive DevOps, using Bamboo, Jenkins, and GitLab CI, so most of our work runs on Linux.
The last reason is convenient support. We needed to lower the entry barrier for the support team—those who understand the technical side, ensure continuity, and maintain services on the second line. They were already familiar with the Linux stack, so it was much easier for them to understand the new product, support, and maintain it than to spend additional resources to figure out similar functionality in Windows-based software.
Requirements
First and foremost— the convenience of the new solution for developers. Not all of them were ready for change, especially after the mention of Linux. Developers want their beloved Visual Studio, TFS with auto-tests for builds, and smoothies. How delivery to production happens is not important to them. Therefore, we decided not to change the usual process and keep everything unchanged for Windows development.
The new project needs to be integrated into the existing CI. The rails were already in place, and all work needed to be done considering the configuration management parameters, accepted delivery standards, and monitoring systems.
Simplicity in support and operation, as a condition for a minimal entry barrier for all new participants from various departments and the support team.
The deadline was yesterday.
The Windows development group
What was the Windows team working with?
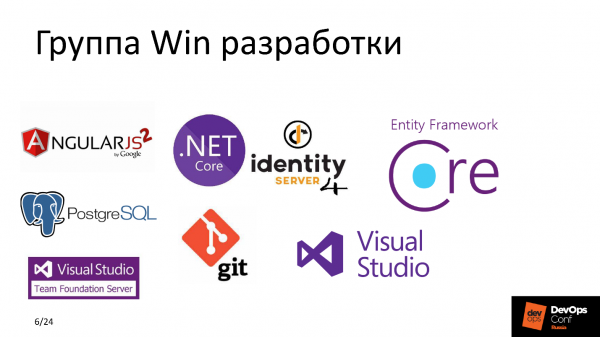
Now I can confidently say that IdentityServer4 is a great free alternative to ADFS with similar capabilities, or that Entity Framework Core is a paradise for developers, allowing them to avoid writing SQL scripts and describe database queries in OOP terms. But back then, during the discussion of the action plan, I looked at this stack like it was Sumerian cuneiform, only recognizing PostgreSQL and Git.
At that time, we were actively using Puppet as a configuration management system. In most of our projects, we applied GitLab CI, Elastic, balancing high-load services with HAProxy, monitoring everything with Zabbix, a stack of Grafana and Prometheus, Jaeger, and all of this ran on hardware HP c ESXi to VMware. Everyone is familiar with it—it's a classic.
Let's take a look and try to understand what happened before we started all these interventions.
What happened
TFS is a quite powerful system that not only delivers code from the developer to the final production machine but also has a set for very flexible integration with different services to ensure CI on a cross-platform level.
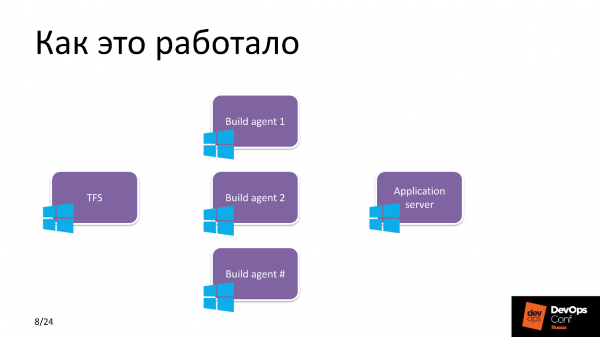
Previously, there were solid windows. TFS used several Build agents, where multiple projects were built. Each agent had 3-4 workers to parallelize tasks and optimize the process. Then, according to the release plans, TFS delivered the freshly baked Build to the Windows application server.
What we wanted to achieve
For delivery and development, we use TFS, and we run the application on a Linux Application server, with some magic in between. This Magic Box is the essence of the upcoming work. Before breaking it down into parts, I will step aside and say a few words about the application.
Project
The application provides functionality for managing prepaid cards.
Client
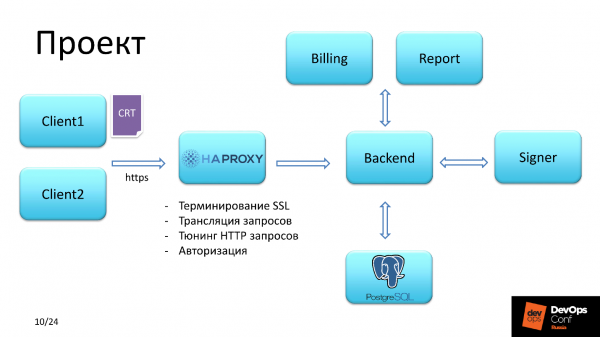
There were two types of users. First accessed through SSL SHA-2 certificate authorization. The the second had access via username and password.
HAProxy
Then the client request went to HAProxy, which solved the following tasks:
- primary authorization;
- SSL termination;
- HTTP request tuning;
- request translation.
Client certificate verification was done through the chain. We are authority and we can afford this because we issue certificates to clients of the service ourselves.
Note the third point; we will return to it shortly.
Backend
The backend was planned to be on Linux. The backend interacts with the database, loads the necessary list of privileges, and then, depending on the privileges that the authorized user has, grants access for signing financial documents and sending them for execution or generating some report.
Savings with HAProxy
In addition to the two contexts through which each client navigated, there was also an identity context. IdentityServer4 which allows for authorization; it is a free and powerful equivalent of ADFS — Active Directory Federation Services.
The request to identity was processed in several steps. The first step - a client was handled by the backend., which exchanged data with this server and checked for the token for the client. If not found, the request was returned to the context it came from, but with a redirect, and that redirect went to identity.
The second step was that the request hit the authorization page in IdentityServer, where the client registered, and the long-awaited token appeared in the IdentityServer database.
The third step was the client redirected back to the context it came from.
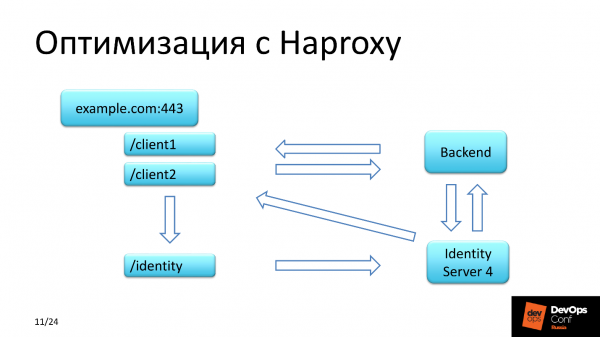
IdentityServer4 has a peculiarity: it returns the response to the reverse request via HTTP. No matter how hard we tried to configure the server or consult the documentation, we always received the original client request with the URL that came via HTTPS, while IdentityServer returned the same context, but with HTTP. We were shocked! And we redirected everything through the identity context via HAProxy, and had to modify the HTTP protocol to HTTPS in the headers.
What is the improvement and where did we save?
We saved money by using a free solution for user group authorization, resources, as we did not deploy IdentityServer4 as a separate node in a separate segment, but used it together with the backend on the same server where the application backend runs.
How it should work
So, as I promised — Magic Box. We already understand that we are guaranteed to move towards Linux. Let’s formulate specific tasks that required solutions.
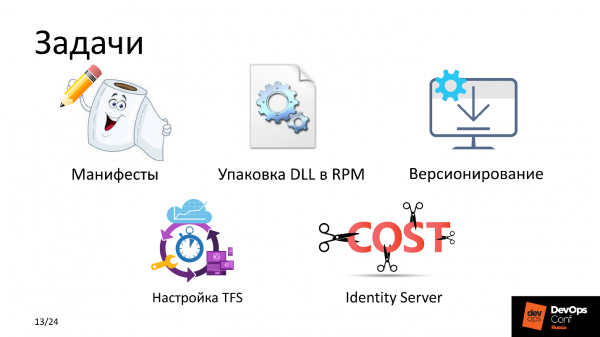
Puppet manifests. To deliver and manage the configuration of the service and application, we needed to write excellent recipes. A roll with a pencil vividly shows how quickly and efficiently this was done.
Delivery method. The standard is RPM. Everyone understands that you can't do without it in Linux, but the project itself, after compilation, consisted of a set of executable DLL files. There were about 150, and the project was quite heavy. The only harmonious solution was to package this binary mess into RPM and deploy the application from it.
Versioning. We needed to release very frequently, and had to decide how to format the package name. This is an integration-level question with TFS. Our Build agent was on Linux. When TFS sends a job to the worker on the Build agent, it also passes a bunch of variables that get into the environment of the handler process. In these environment variables, the Build name, version name, and other variables are passed. More about this in the section 'building RPM packages.'
TFS Configuration was focused on setting up the Pipeline. Previously, we compiled all Windows projects on Windows agents, but now a Linux agent has appeared - a Build agent, which needs to be included in the build group, enriched with some artifacts, specified what types of projects will be built on this Build agent, and how to modify the Pipeline.
IdentityServer. ADFS is not our path, we advocate for Open Source.
Let's go through the components.
Magic Box
It consists of four parts.
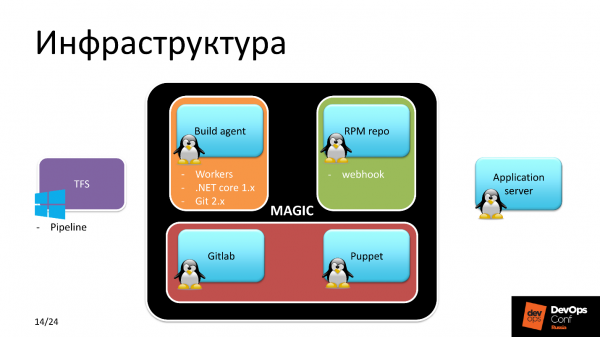
Linux Build agent. Linux, because we are building for it - logically. This part was executed in three steps.
- Set up the workers and not just one, as distributed work on the project was anticipated.
- Install .NET Core 1.x. Why exactly 1.x, when 2.0 is already available in the standard repository? Because when we started development, the stable version was 1.09, and the project was decided to be made under it.
- Git 2.x.
RPM repository. RPM packages needed to be stored somewhere. It was assumed that we would use the same corporate RPM repository available to all Linux hosts. And that’s what we did. The repository server is set up with a webhook that downloaded the required RPM package from the specified location. The version of the package was reported to the webhook by the Build agent.
GitLab. Attention! GitLab is used here not by developers, but by the operations department for version control of the application, package versions, monitoring the status of all Linux machines, and it stores the recipe - all Puppet manifests.
Puppet - resolves all contentious issues and delivers exactly the configuration we want from GitLab.
Let's dive in. How is the delivery of DLLs to RPM done?
Delivery of DLL to RPM
Let's say we have a rock star developer in .NET. He uses Visual Studio and creates a release branch. After that, he uploads it to Git, and Git here is a TFS entity, meaning it is the application repository with which the developer works.
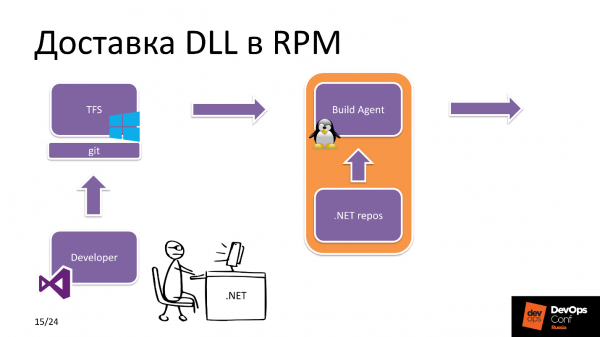
After which TFS sees that a new commit has arrived. Which application? In the TFS settings, there is a label indicating what resources each Build agent possesses. In this case, it sees that we are building a .NET Core project and selects a Linux Build agent from the pool.
The Build agent retrieves the source code, downloads the necessary dependencies from the .NET repository, npm, etc., and after building the application and subsequent packaging, sends the RPM package to the RPM repository.
On the other hand, the following is happening. An operations engineer is directly involved in deploying the project: changing package versions in Hiera in the repository where the application's recipe is stored, after which Puppet triggers Yum, retrieves the new package from the repository, and the new version of the application is ready for use.
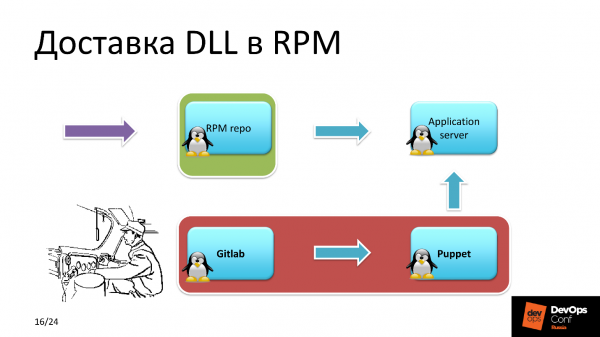
In theory, everything is simple, but what actually happens inside the Build agent?
Packaging DLL RPM
The project sources have been received and the task for building from TFS. The Build agent starts building the project from the sources.The built project is available as a multitude of DLL files, which are packed into a zip archive to reduce the load on the file system.
The ZIP archive is dumped into the RPM package build directory. Next, a Bash script initializes environment variables, finds the Build version, project version, path to the build directory, and starts RPM-build. Upon completion of the build, the package is published to the local repository, which is located on the Build agent.
Then, from the Build agent to the server in the RPM repository a JSON request is sent indicating the version name and build. The webhook I mentioned earlier retrieves this package from the local repository on the Build agent and makes the new build available for installation.
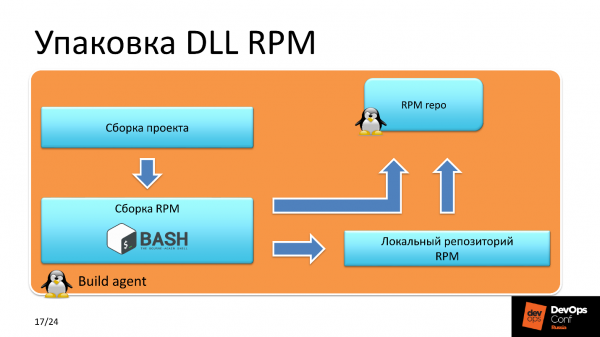
Why this specific scheme for delivering the package to the RPM repository? Why can't we immediately send the built package to the repository? The reason is that this condition ensures security. Such a scenario limits the possibility of unauthorized uploads of RPM packages by outsiders to a server accessible to all Linux machines.
Database versioning
During a meeting with the development team, it turned out that the guys preferred MS SQL, but in most non-Windows projects, we were already fully utilizing PostgreSQL. Since we have decided to move away from all paid options, we started using PostgreSQL here as well.
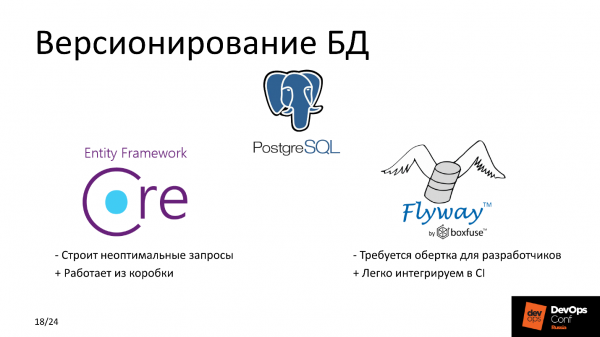
In this section, I want to discuss how we managed database versioning and how we chose between Flyway and Entity Framework Core. Let's look at their pros and cons.
Cons
Flyway only goes in one direction, we cannot roll back — this is a significant downside. Comparing with Entity Framework Core can be done based on other parameters— from the developer's perspective. You remember that we prioritized this, and the main criterion was not to change anything for Windows development.
For Flyway, we needed some wrapper, so that the guys wouldn't have to write SQL queries. It is much closer for them to operate in OOP terms. Instructions for working with database objects were written, an SQL query was formed and executed. The new database version is ready, it has run without issues—everything works fine.
Entity Framework Core has a downside—under heavy loads, it constructs non-optimal SQL queries, and the performance hit on the database can be substantial. But since we don't have a high-load service, we don't measure load by hundreds of RPS; we accepted these risks and delegated the problem to our future selves.
Advantages
Entity Framework Core works out of the box and is convenient for development, while Flyway easily integrates into existing CI. But we are making it convenient for developers :)
The deployment procedure
Puppet sees that a version change of packages comes in, among which is the one responsible for migrations. It first installs the package that contains migration scripts and the functionalities tied to the database. After that, the application that works with the database is restarted. Then the installation of the remaining components proceeds. The sequence of package installations and application launches is described in the Puppet manifest.
Applications use sensitive data such as tokens, database passwords; all this is pulled into the config from the Puppet master, where they are stored in an encrypted form.
TFS Issues
After we determined and understood that everything was indeed working, I decided to take a look at what was happening with the builds in TFS in general for the Windows development department for other projects—whether we are building/releasing quickly or not, and I discovered significant issues with speed.
One of the main projects is built in 12-15 minutes—this is long, we cannot live like this. A quick analysis showed a terrible drop in I/O, and this is on arrays.
Analyzing component by component, I identified three hotspots. The first— “Kaspersky antivirus”, which scans the source code on all Windows Build agents. The second one is Windows Indexer. It was not disabled, and everything was indexed in real time on the Build agents during the deployment process.
The third one is Npm install. It turned out that in most Pipelines we used exactly this script. What’s wrong with it? The Npm install process runs when building the dependency tree in package-lock.json, where the versions of the packages to be used for the project build are recorded. The downside is that Npm install pulls the latest package versions from the internet each time, which can take a significant amount of time for large projects.
Developers sometimes experiment on their local machines to test the operation of a specific part or the entire project. Sometimes it happened that everything worked great locally, but when we built and deployed, nothing worked. We start to figure out what the problem is — ah, different versions of packages with dependencies.
Solution
- Sources for AV exceptions.
- Disabling indexing.
- Switching to npm ci.
The advantages of npm ci are that we build the dependency tree only once, and we get the opportunity to provide the developer with an up-to-date list of packages, which they can experiment with locally as much as they want. This saves time for the developers who write the code.
Configuration
Now let’s talk a bit about the repository configuration. Historically, we use Nexus for managing repositories, including Internal REPO. This internal repository supplies all the components we use for internal purposes, such as custom monitoring tools.
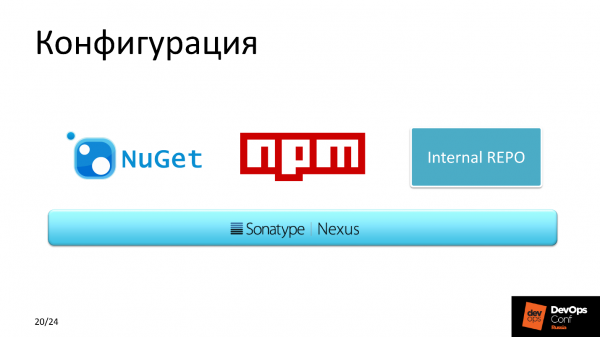
We also use NuGet, as it caches better compared to other package managers.
Result
After we optimized the Build agents, the average build time was reduced from 12 minutes to 7.
If we count all the machines that we could have used for Windows but transitioned to Linux in this project, we saved about $10,000. And that’s just on licenses; if we consider maintenance, it’s even more.
Plans
For the next quarter, we planned to work on optimizing code delivery.
Transition to a pre-built Docker image. TFS is a great tool with many plugins that allow integration into the Pipeline, including building on triggers, for example, Docker images. We want to create this trigger for the very... package-lock.jsonIf the composition of components used to build the project changes in any way, a new Docker image is created. This image is subsequently used to deploy the container with the built application. Currently, this is not in place, but we plan to transition to a microservices architecture in Kubernetes, which is actively being developed in our company and has long been serving production solutions.
Summary
I urge everyone to ditch Windows, but not because I don't know how to prepare it. The reason is that most Open-source solutions are Linux stack.You will save resources well. In my opinion, the future belongs to Open Source solutions on Linux with a strong community.Speaker profile of Alexander Sinchinov
on GitHub. .
At DevOps Conf at RIT++ take your time with the ticket. See you in Skolkovo! We developed DevOps as best we could. There were 8 of us, and Vasya was the top expert in Windows. Suddenly, Vasya left, and I was tasked with launching a new project that delivers Windows development. 🥇.NET Core on Linux, DevOps on the rise | ProHoster
Source: habr.com
