

Hello, Habr! My name is Maxim Vasiliev, and I work as an analyst and project manager at FINCH. Today, I would like to share how, with the help of ElasticSearch, we processed 15 million requests in 6 minutes and optimized the daily load on the website of one of our clients. Unfortunately, we’ll have to go without names, as we have an NDA, but we hope the content of the article will not suffer as a result. Let’s go.
How the Project is Structured
On our backend, we create services that ensure the functionality of our client's websites and mobile applications. The overall structure can be seen in the diagram:
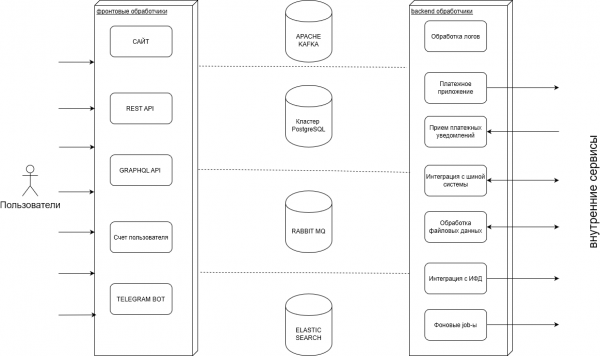
In the process, we handle a large number of transactions: purchases, payouts, user balance operations, for which we store extensive logs, as well as import and export this data to external systems.
There are also reverse processes, where we receive data from the client and pass it on to the users. Additionally, there are processes related to payments and bonus programs.
A Brief Background
Initially, we used PostgreSQL as the sole data storage solution. Its standard advantages for DBMSs—transaction support, advanced data query language, and a wide range of integration tools—along with good performance, satisfied our needs for a considerable time.
We stored absolutely all data in Postgres: from transactions to news. However, the number of users grew, and so did the number of requests.
To put it into perspective, the annual number of sessions in 2017 alone on the desktop site was 131 million. For 2018, it was 125 million. In 2019, it was again 130 million. Add another 100-200 million from the mobile version of the site and the mobile app, and you end up with a colossal number of requests.
As the project grew, Postgres began to struggle with the workload. We couldn't keep up—the volume of diverse requests increased to the point where we couldn't create a sufficient number of indexes.
We realized that there was a need for other data storage solutions that would meet our needs and lighten the load on PostgreSQL. We considered Elasticsearch and MongoDB as potential options. The latter fell short in the following areas:
- Slow indexing speed with the growing volume of data in indexes. With Elastic, speed does not depend on the amount of data.
- No full-text search
Thus, we chose Elastic for ourselves and prepared for the transition.
Transition to Elastic
1. We started the transition with the sales points search service. Our client has a total of about 70,000 sales points, and several types of searches are needed on the site and in the app:
- Text search by the name of the locality
- Geo-search within a specified radius from a point. For example, if a user wants to see which sales points are closest to their home.
- Search within a designated square – the user outlines a square on the map, and all points within this radius are shown.
- Search by additional filters. Sales points differ from each other by assortment.
In terms of organization, we have our data source in Postgres for both maps and news, while in Elastic, snapshots are created from the original data. The thing is that initially, Postgres could not handle searches based on all criteria. Not only were there many indexes, but they could also overlap, so the Postgres planner got lost and did not understand which index to use.
2. Next in line was the news section. New publications appear on the site every day, and to prevent users from getting lost in the flow of information, data needs to be sorted before presentation. This is where search comes in: the site can search for text matches and also use additional filters, as they are also implemented through Elastic.
3. Then we moved on to processing transactions. Users can purchase specific products on the site and participate in prize draws. After such purchases, we process a large amount of data, especially during weekends and holidays. For comparison, on regular days, the number of purchases is around 1.5-2 million, while on holidays it can reach up to 53 million.
At the same time, the data needs to be processed in the shortest time possible — users do not like to wait several days for results. Through Postgres, such timelines are simply unattainable — we often encountered locks, and while we were processing all requests, users could not check whether they had won prizes or not. This is not very pleasant for business, so we moved processing to Elasticsearch.
Frequency
Currently, updates are set based on events under the following conditions:
- Sales Points. As soon as we receive data from an external source, we immediately trigger the update.
- News. As soon as any news item is edited on the site, it is automatically sent to Elastic.
It’s worth mentioning the advantages of Elastic again. In Postgres, when sending a query, you have to wait for it to carefully process all records. In Elastic, you can send 10,000 records and immediately start working without waiting for the records to be distributed across all Shards. Of course, some Shard or Replica may not see the data immediately, but very soon everything will be available.
Integration Methods
There are 2 methods of integration with Elastic:
- Through the native client via TCP. The native driver is gradually becoming obsolete: it is no longer supported, and its syntax is quite inconvenient. Therefore, we hardly use it and strive to completely abandon it.
- Through the HTTP interface, which allows the use of both JSON requests and Lucene syntax. The latter is a text engine used by Elastic. In this option, we gain the ability to perform Batch operations via JSON requests over HTTP. This is the option we prefer to use.
Thanks to the HTTP interface, we can utilize libraries that provide asynchronous HTTP client implementation. We can take advantage of Batch and the asynchronous API, resulting in high performance, which was particularly beneficial during major campaigns (more on this below).
A few numbers for comparison:
- Saving users who received prizes in Postgres with 20 threads without grouping: 460,713 records in 42 seconds.
- Elastic + reactive client on 10 threads + batch of 1000 items: 596,749 records in 11 seconds.
- Elastic + reactive client on 10 threads + batch of 1000 items: 23,801,684 records in 4 minutes.
We have now written an HTTP query manager that constructs JSON for Batch/non-Batch and sends it through any HTTP client regardless of the library. It is also possible to choose to send requests synchronously or asynchronously.
In some integrations, we still use the official transport client, but this is merely a matter of upcoming refactoring. Meanwhile, a custom client built on Spring WebClient is used for processing.
Major Campaign
Once a year, a major event takes place for users — this is the Highload, as during this time we work with tens of millions of users simultaneously.
Typically, traffic peaks occur on holidays, but this event is an entirely different level. In the year before last, on the day of the event, we sold 27,580,890 units of goods. Data processing took over half an hour, which caused inconvenience for users. Users received prizes for participation, but it became clear that the process needed to be accelerated.
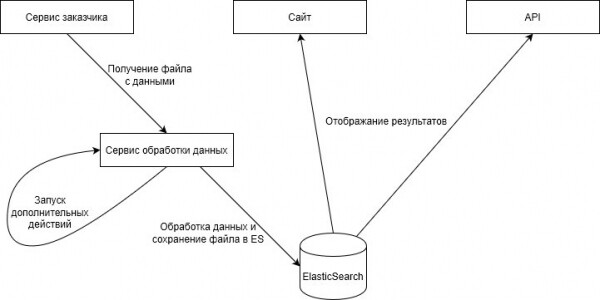
At the beginning of 2019, we decided that we needed ElasticSearch. For a whole year, we organized the processing of incoming data in Elastic and its delivery through the mobile application's API and the website. As a result, the next year during the event, we processed 15,131,783 records in 6 minutes.
Since we have a high demand for purchasing goods and participating in prize draws during events, this is a temporary measure. Currently, we send relevant information to Elastic, but in the future, we plan to transfer archival information from previous months to Postgres as a permanent storage solution. This will prevent clutter in the Elastic index, which also has its limitations.
Conclusions
At this point, we have migrated all the services we wanted to Elastic, and we have paused for now. Currently, we are building an index in Elastic on top of the main persistent storage in Postgres, which handles the user load.
In the future, we plan to migrate services if we find that the data requests become too diverse and are queried across an unlimited number of columns. This is no longer a task for Postgres.
If we need full-text search functionality or if we end up with a variety of search criteria, we already know that this needs to be moved to Elastic.
⌘⌘⌘
Thank you for reading. If your company also uses ElasticSearch and has your own implementation cases, please share. It would be interesting to know how others do it 🙂
Source: habr.com
