

A couple of years ago, Kubernetes in the official GitHub blog. Since then, it has become the standard technology for deploying services. Now, Kubernetes manages a significant portion of internal and public services. As our clusters have grown and performance requirements have become stricter, we have started to notice that some services on Kubernetes occasionally experience delays that cannot be explained by the application's own load.
Essentially, there are seemingly random network delays in applications of up to 100 ms or more, which lead to timeouts or retries. It was expected that services would respond to requests much faster than 100 ms. However, this is impossible if the connection itself takes that long. Separately, we observed very fast MySQL queries that should have taken milliseconds, and MySQL indeed handled them in milliseconds, but from the perspective of the requesting application, the response took 100 ms or more.
It became immediately clear that the problem occurs only when connecting to a Kubernetes node, even if the call was coming from outside of Kubernetes. The easiest way to reproduce the issue is in a test , which runs from any internal host, tests the Kubernetes service on a specific port, and sporadically logs significant delays. In this article, we will explore how we were able to trace the cause of this issue.
Eliminating unnecessary complexity in the failure chain
By reproducing the same example, we wanted to narrow the focus of the problem and eliminate unnecessary layers of complexity. Initially, there were too many elements in the stream between Vegeta and the pods on Kubernetes. To identify a deeper network issue, we need to exclude some of them.
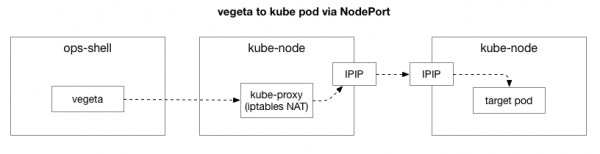
The client (Vegeta) establishes a TCP connection with any node in the cluster. Kubernetes operates as an overlay network (on top of the existing data center network) that uses , which encapsulates IP packets of the overlay network within IP packets of the data center. When connecting to the first node, Network Address Translation is performed. (NAT) with state tracking for translating the Kubernetes node's IP address and port into the overlay network's IP address and port (specifically, the pod with the application). For incoming packets, the reverse sequence of actions is performed. This is a complex system with many states and numerous elements that are constantly updated and changed as services are deployed and moved.
Utility tcpdump in the Vegeta test introduces latency during the TCP handshake (between SYN and SYN-ACK). To eliminate this unnecessary complexity, one can use hping3 for simple "pings" with SYN packets. We check for any delay in the response packet, and then tear down the connection. We can filter the data by including only packets over 100 ms, providing a simpler way to reproduce the issue than a full layer 7 network test in Vegeta. Here are the "pings" from the Kubernetes node using TCP SYN/SYN-ACK on the service's "node port" (30927) with a 10 ms interval, filtered for the slowest responses:
theojulienne@shell ~ $ sudo hping3 172.16.47.27 -S -p 30927 -i u10000 | egrep --line-buffered 'rtt=[0-9]{3}.'
len=46 ip=172.16.47.27 ttl=59 DF id=0 sport=30927 flags=SA seq=1485 win=29200 rtt=127.1 ms
len=46 ip=172.16.47.27 ttl=59 DF id=0 sport=30927 flags=SA seq=1486 win=29200 rtt=117.0 ms
len=46 ip=172.16.47.27 ttl=59 DF id=0 sport=30927 flags=SA seq=1487 win=29200 rtt=106.2 ms
len=46 ip=172.16.47.27 ttl=59 DF id=0 sport=30927 flags=SA seq=1488 win=29200 rtt=104.1 ms
len=46 ip=172.16.47.27 ttl=59 DF id=0 sport=30927 flags=SA seq=5024 win=29200 rtt=109.2 ms
len=46 ip=172.16.47.27 ttl=59 DF id=0 sport=30927 flags=SA seq=5231 win=29200 rtt=109.2 ms
One can immediately make the first observation. By examining the sequence numbers and timings, it is clear that this is not a one-time congestion. The latency often accumulates and ultimately gets processed.
Next, we want to determine which components might be involved in the congestion. Could it be some of the hundreds of iptables rules in NAT? Or some issues with IPIP tunneling in the network? One way to check this is to examine each step of the system by excluding it. What happens if we remove NAT and the firewall logic, leaving only the IPIP part:
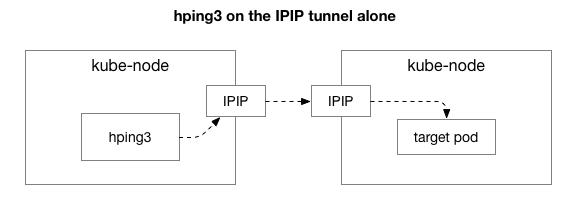
Fortunately, Linux allows direct access to the overlay IP layer if the machine is in the same network:
theojulienne@kube-node-client ~ $ sudo hping3 10.125.20.64 -S -i u10000 | egrep --line-buffered 'rtt=[0-9]{3}.'
len=40 ip=10.125.20.64 ttl=64 DF id=0 sport=0 flags=RA seq=7346 win=0 rtt=127.3 ms
len=40 ip=10.125.20.64 ttl=64 DF id=0 sport=0 flags=RA seq=7347 win=0 rtt=117.3 ms
len=40 ip=10.125.20.64 ttl=64 DF id=0 sport=0 flags=RA seq=7348 win=0 rtt=107.2 ms
According to the results, the problem still persists! This rules out iptables and NAT. So, is the issue with TCP? Let's see how the regular ICMP ping goes:
theojulienne@kube-node-client ~ $ sudo hping3 10.125.20.64 --icmp -i u10000 | egrep --line-buffered 'rtt=[0-9]{3}.'
len=28 ip=10.125.20.64 ttl=64 id=42594 icmp_seq=104 rtt=110.0 ms
len=28 ip=10.125.20.64 ttl=64 id=49448 icmp_seq=4022 rtt=141.3 ms
len=28 ip=10.125.20.64 ttl=64 id=49449 icmp_seq=4023 rtt=131.3 ms
len=28 ip=10.125.20.64 ttl=64 id=49450 icmp_seq=4024 rtt=121.2 ms
len=28 ip=10.125.20.64 ttl=64 id=49451 icmp_seq=4025 rtt=111.2 ms
len=28 ip=10.125.20.64 ttl=64 id=49452 icmp_seq=4026 rtt=101.1 ms
len=28 ip=10.125.20.64 ttl=64 id=50023 icmp_seq=4343 rtt=126.8 ms
len=28 ip=10.125.20.64 ttl=64 id=50024 icmp_seq=4344 rtt=116.8 ms
len=28 ip=10.125.20.64 ttl=64 id=50025 icmp_seq=4345 rtt=106.8 ms
len=28 ip=10.125.20.64 ttl=64 id=59727 icmp_seq=9836 rtt=106.1 ms
The results show that the issue hasn't disappeared. Perhaps it's the IPIP tunnel? Let's simplify the test further:
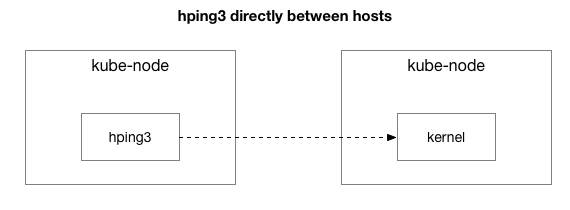
Are all packets being sent between these two hosts?
theojulienne@kube-node-client ~ $ sudo hping3 172.16.47.27 --icmp -i u10000 | egrep --line-buffered 'rtt=[0-9]{3}.'
len=46 ip=172.16.47.27 ttl=61 id=41127 icmp_seq=12564 rtt=140.9 ms
len=46 ip=172.16.47.27 ttl=61 id=41128 icmp_seq=12565 rtt=130.9 ms
len=46 ip=172.16.47.27 ttl=61 id=41129 icmp_seq=12566 rtt=120.8 ms
len=46 ip=172.16.47.27 ttl=61 id=41130 icmp_seq=12567 rtt=110.8 ms
len=46 ip=172.16.47.27 ttl=61 id=41131 icmp_seq=12568 rtt=100.7 ms
len=46 ip=172.16.47.27 ttl=61 id=9062 icmp_seq=31443 rtt=134.2 ms
len=46 ip=172.16.47.27 ttl=61 id=9063 icmp_seq=31444 rtt=124.2 ms
len=46 ip=172.16.47.27 ttl=61 id=9064 icmp_seq=31445 rtt=114.2 ms
len=46 ip=172.16.47.27 ttl=61 id=9065 icmp_seq=31446 rtt=104.2 ms
We simplified the scenario to two Kubernetes nodes sending any packets to each other, even ICMP pings. They still experience latency if the target host is 'bad' (some worse than others).
Now the final question: why does latency occur only on the kube-node servers? And does it happen when kube-node is the sender or the recipient? Fortunately, this is also quite easy to find out by sending a packet from a host outside of Kubernetes, but with the same 'known bad' recipient. As we can see, the issue hasn't disappeared:
theojulienne@shell ~ $ sudo hping3 172.16.47.27 -p 9876 -S -i u10000 | egrep --line-buffered 'rtt=[0-9]{3}.'
len=46 ip=172.16.47.27 ttl=61 DF id=0 sport=9876 flags=RA seq=312 win=0 rtt=108.5 ms
len=46 ip=172.16.47.27 ttl=61 DF id=0 sport=9876 flags=RA seq=5903 win=0 rtt=119.4 ms
len=46 ip=172.16.47.27 ttl=61 DF id=0 sport=9876 flags=RA seq=6227 win=0 rtt=139.9 ms
len=46 ip=172.16.47.27 ttl=61 DF id=0 sport=9876 flags=RA seq=7929 win=0 rtt=131.2 ms
Then we will perform the same requests from the previous source kube-node to the external host (which rules out the source host since ping includes both RX and TX components):
theojulienne@kube-node-client ~ $ sudo hping3 172.16.33.44 -p 9876 -S -i u10000 | egrep --line-buffered 'rtt=[0-9]{3}.
 ^C
 --- 172.16.33.44 hping statistic ---
 22352 packets transmitted, 22350 packets received, 1% packet loss
 round-trip min/avg/max = 0.2/7.6/1010.6 ms
After analyzing the packet captures with latency, we obtained some additional information. Specifically, the sender (below) experiences this timeout, while the receiver (above) does not see it — see the Delta column (in seconds):
Moreover, if we look at the difference in the order of TCP and ICMP packets (by sequence numbers) on the receiver's side, ICMP packets always arrive in the same order they were sent, but with varying timing. Meanwhile, TCP packets may get interleaved, and some may get stuck. In particular, when examining the SYN packet ports, they are in order on the sender's side, but not on the receiver's side.
There is a subtle difference in how of modern servers (like in our data center) handle packets containing TCP or ICMP. When a packet arrives, the network adapter 'hashes it by connection', meaning it attempts to split connections into queues and send each queue to a separate processor core. For TCP, this hash includes both the source and destination IP addresses and ports. In other words, each connection is hashed (potentially) differently. For ICMP, only the IP addresses are hashed, as there are no ports.
Another new observation: during this period, we see ICMP delays on all communications between two hosts, whereas there are none for TCP. This suggests that the cause is likely related to RX queue hashing: it is almost certain that the bottleneck occurs in RX packet processing, not in sending responses.
This eliminates packet sending from the list of possible causes. We now know that the packet processing issue is on the reception side on some kube-node servers.
Investigating packet processing in the Linux kernel
To understand why the issue arises on the receiver side on some kube-node servers, let’s look at how the Linux kernel handles packets.
Returning to the simplest traditional implementation, the network card receives a packet and sends to the Linux kernel indicating that there is a packet to process. The kernel halts other work, switches context to the interrupt handler, processes the packet, and then returns to the current tasks.
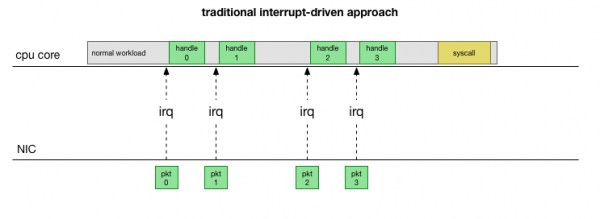
This context switching happens slowly: while the delay might have gone unnoticed on 10 Mbps network cards in the 90s, on modern 10G cards with a maximum throughput of 15 million packets per second, each core of a small eight-core server can be interrupted millions of times a second.
To avoid constantly handling interrupts, Linux introduced years ago : a network API used by all modern drivers to enhance performance at high speeds. At low speeds, the kernel still receives interrupts from the network card using the old method. Once a sufficient number of packets arrives that exceeds a threshold, the kernel disables interrupts and instead starts polling the network adapter to retrieve packets in batches. This processing occurs in softirq, that is, in after system calls and hardware interrupts, when the kernel (unlike user space) is already running.
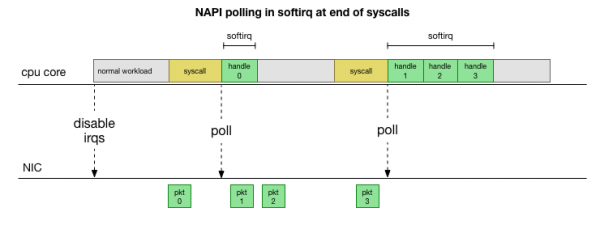
This is much faster, but introduces a different problem. If there are too many packets, all the time is spent processing packets from the network card, and user-space processes fail to adequately clear these queues (reading from TCP connections, etc.). Eventually, the queues fill up, and we start dropping packets. In trying to find a balance, the kernel sets a budget for the maximum number of packets processed in the softirq context. Once this budget is exceeded, a separate thread ksoftirqd (you will see one for ps each core), which processes these softirqs outside the normal syscall/interrupt path. This thread is scheduled using the standard process scheduler, which attempts to distribute resources fairly.
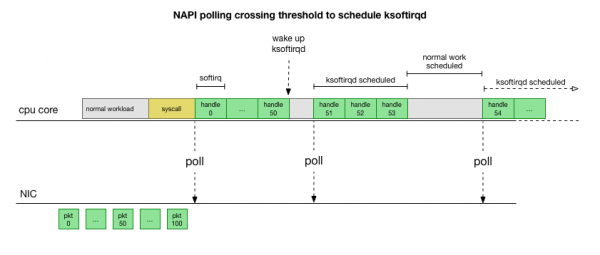
By studying how the kernel handles packets, one can notice that there is a certain probability of congestion. If softirq calls arrive less frequently, packets may have to wait some time for processing in the RX queue on the network card. This could be due to some task blocking the CPU kernel, or something else preventing the kernel from running softirq.
We narrow down the processing to the kernel or method
Softirq delays are currently just a hypothesis. However, it makes sense, and we know that we are observing something quite similar. Therefore, the next step is to confirm this theory. If it is validated, we will find the causes of the delays.
Let's return to our slow packets:
len=46 ip=172.16.53.32 ttl=61 id=29573 icmp_seq=1953 rtt=99.3 ms
len=46 ip=172.16.53.32 ttl=61 id=29574 icmp_seq=1954 rtt=89.3 ms
len=46 ip=172.16.53.32 ttl=61 id=29575 icmp_seq=1955 rtt=79.2 ms
len=46 ip=172.16.53.32 ttl=61 id=29576 icmp_seq=1956 rtt=69.1 ms
len=46 ip=172.16.53.32 ttl=61 id=29577 icmp_seq=1957 rtt=59.1 ms
len=46 ip=172.16.53.32 ttl=61 id=29790 icmp_seq=2070 rtt=75.7 ms
len=46 ip=172.16.53.32 ttl=61 id=29791 icmp_seq=2071 rtt=65.6 ms
len=46 ip=172.16.53.32 ttl=61 id=29792 icmp_seq=2072 rtt=55.5 ms
As discussed earlier, these ICMP packets are hashed into a single NIC RX queue and processed by a single CPU core. If we want to understand how Linux operates, it's useful to know where (on which CPU core) and how (softirq, ksoftirqd) these packets are processed in order to trace the process.
Now it's time to use tools that allow real-time monitoring of the Linux kernel's work. Here we used . This toolkit allows you to write small programs in C that intercept arbitrary functions in the kernel and buffer events into a Python userspace program, which can process them and return results to you. Hooks for arbitrary functions in the kernel are complex, but the utility is designed for maximum safety and aims to track production issues that are difficult to reproduce in a testing or development environment.
The plan here is straightforward: we know that the kernel processes these ICMP pings, so we will set a hook on the kernel function , which handles incoming ICMP "echo request" packets and initiates sending an ICMP "echo response". We can identify the packet by the incrementing icmp_seq number, which indicates hping3 higher.
Code may look complicated, but it is not as scary as it seems. The function icmp_echo reports struct sk_buff *skb: is the packet for the "echo request". We can trace it, extract the sequence echo.sequence which corresponds to icmp_seq from hping3 above), and send it to userspace. It is also convenient to capture the current process name/ID. The results shown below are what we observe directly during packet handling by the kernel:
TGID    PID     PROCESS NAME    ICMP_SEQ
0       0       swapper/11      770
0       0       swapper/11      771
0       0       swapper/11      772
0       0       swapper/11      773
0       0       swapper/11      774
20041   20086   prometheus      775
0       0       swapper/11      776
0       0       swapper/11      777
0       0       swapper/11      778
4512    4542   spokes-report-s  779
It should be noted that in context softirq processes that made system calls will appear as 'processes', although in reality the kernel is safely handling packets in the kernel context.
With this tool, we can establish a connection between specific processes and specific packets that show latency in hping3. We make a simple grep capture for certain values icmp_seq. The packets that correspond to the above-mentioned icmp_seq values were marked along with their RTT, which we observed above (the expected RTT values for the packets filtered out due to RTT values less than 50 ms are in parentheses):
TGID    PID     PROCESS NAME    ICMP_SEQ ** RTT
--
10137   10436   cadvisor        1951
10137   10436   cadvisor        1952
76      76      ksoftirqd/11    1953 ** 99ms
76      76      ksoftirqd/11    1954 ** 89ms
76      76      ksoftirqd/11    1955 ** 79ms
76      76      ksoftirqd/11    1956 ** 69ms
76      76      ksoftirqd/11    1957 ** 59ms
76      76      ksoftirqd/11    1958 ** (49ms)
76      76      ksoftirqd/11    1959 ** (39ms)
76      76      ksoftirqd/11    1960 ** (29ms)
76      76      ksoftirqd/11    1961 ** (19ms)
76      76      ksoftirqd/11    1962 ** (9ms)
--
10137   10436   cadvisor        2068
10137   10436   cadvisor        2069
76      76      ksoftirqd/11    2070 ** 75ms
76      76      ksoftirqd/11    2071 ** 65ms
76      76      ksoftirqd/11    2072 ** 55ms
76      76      ksoftirqd/11    2073 ** (45ms)
76      76      ksoftirqd/11    2074 ** (35ms)
76      76      ksoftirqd/11    2075 ** (25ms)
76      76      ksoftirqd/11    2076 ** (15ms)
76      76      ksoftirqd/11    2077 ** (5ms)
The results tell us several things. First, all these packets are handled by the context ksoftirqd/11. This means that for this specific pair of machines, ICMP packets were hashed to core 11 on the receiving side. We also see that during each congestion, there are packets being processed in the context of a system call cadvisor. Then ksoftirqd takes on the task and processes the accumulated queue: specifically, the number of packets that have accumulated after cadvisor.
The fact that it is always active right before this cadvisor, implies its involvement in the issue. Ironically, its purpose is to 'analyze resource usage and performance characteristics of running containers', not to cause this performance issue.
As with other aspects of container operations, this is highly advanced tooling, from which one can reasonably expect performance issues under certain unforeseen circumstances.
What does cadvisor do that slows down the packet queue?
Now we have a pretty good understanding of how the failure occurs, which process triggers it, and on which CPU. We see that due to a hard lock, the Linux kernel is unable to schedule in time. ksoftirqdAnd we see that packets are processed in the context of cadvisor. It is logical to assume that cadvisor initiates a slow syscall, after which all accumulated packets during this time are processed:
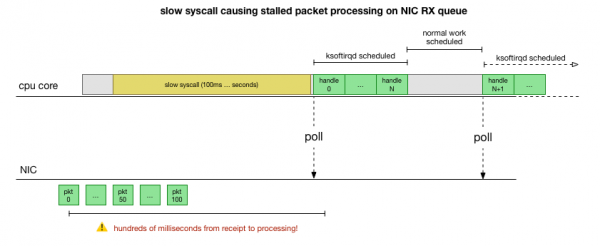
This is the theory, but how can we verify it? What we can do is trace the CPU kernel's activity throughout this process, identify the point where the budget on the number of packets is exceeded and ksoftirqd is invoked, and then look just before that—what exactly was running on the CPU kernel right before that moment. It's like an X-ray of the CPU every few milliseconds. It would look something like this:
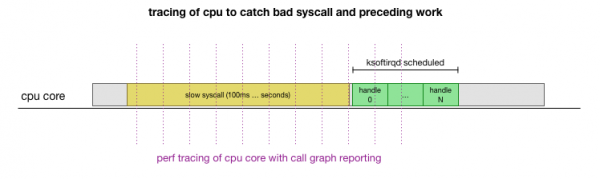
Fortunately, all of this can be accomplished with existing tools. For instance, with a specified frequency checks the designated CPU core and can generate a call graph of the running system, including both user space and the Linux kernel. We can take this record and analyze it using a small fork of the program by Brendan Gregg, which preserves the order of stack traces. We can save single-line stack traces every 1 ms and then extract and preserve a sample for 100 milliseconds before it reaches the trace ksoftirqd:
# record 999 times a second, or every 1ms with some offset so not to align exactly with timers
 sudo perf record -C 11 -g -F 999
 # take that recording and make a simpler stack trace.
 sudo perf script 2>/dev/null | ./FlameGraph/stackcollapse-perf-ordered.pl | grep ksoftir -B 100
Here are the results:
(hundreds of traces that look similar)
cadvisor;[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];entry_SYSCALL_64_after_swapgs;do_syscall_64;sys_read;vfs_read;seq_read;memcg_stat_show;mem_cgroup_nr_lru_pages;mem_cgroup_node_nr_lru_pages cadvisor;[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];entry_SYSCALL_64_after_swapgs;do_syscall_64;sys_read;vfs_read;seq_read;memcg_stat_show;mem_cgroup_nr_lru_pages;mem_cgroup_node_nr_lru_pages cadvisor;[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];entry_SYSCALL_64_after_swapgs;do_syscall_64;sys_read;vfs_read;seq_read;memcg_stat_show;mem_cgroup_iter cadvisor;[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];entry_SYSCALL_64_after_swapgs;do_syscall_64;sys_read;vfs_read;seq_read;memcg_stat_show;mem_cgroup_nr_lru_pages;mem_cgroup_node_nr_lru_pages cadvisor;[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];[cadvisor];entry_SYSCALL_64_after_swapgs;do_syscall_64;sys_read;vfs_read;seq_read;memcg_stat_show;mem_cgroup_nr_lru_pages;mem_cgroup_node_nr_lru_pages ksoftirqd/11;ret_from_fork;kthread;kthread;smpboot_thread_fn;smpboot_thread_fn;run_ksoftirqd;__do_softirq;net_rx_action;ixgbe_poll;ixgbe_clean_rx_irq;napi_gro_receive;netif_receive_skb_internal;inet_gro_receive;bond_handle_frame;__netif_receive_skb_core;ip_rcv_finish;ip_rcv;ip_forward_finish;ip_forward;ip_finish_output;nf_iterate;ip_output;ip_finish_output2;__dev_queue_xmit;dev_hard_start_xmit;ipip_tunnel_xmit;ip_tunnel_xmit;iptunnel_xmit;ip_local_out;dst_output;__ip_local_out;nf_hook_slow;nf_iterate;nf_conntrack_in;generic_packet;ipt_do_table;set_match_v4;ip_set_test;hash_net4_kadt;ixgbe_xmit_frame_ring;swiotlb_dma_mapping_error;hash_net4_test ksoftirqd/11;ret_from_fork;kthread;kthread;smpboot_thread_fn;smpboot_thread_fn;run_ksoftirqd;__do_softirq;net_rx_action;gro_cell_poll;napi_gro_receive;netif_receive_skb_internal;inet_gro_receive;__netif_receive_skb_core;ip_rcv_finish;ip_rcv;ip_forward_finish;ip_forward;ip_finish_output;nf_iterate;ip_output;ip_finish_output2;__dev_queue_xmit;dev_hard_start_xmit;dev_queue_xmit_nit;packet_rcv;tpacket_rcv;sch_direct_xmit;validate_xmit_skb_list;validate_xmit_skb;netif_skb_features;ixgbe_xmit_frame_ring;swiotlb_dma_mapping_error;__dev_queue_xmit;dev_hard_start_xmit;__bpf_prog_run;__bpf_prog_run
There is a lot here, but the main point is that we find the pattern "cadvisor before ksoftirqd" that we have seen before in the ICMP tracer. What does this mean?
Each line represents a CPU trace at a certain point in time. Each call down the stack in the line is separated by a semicolon. Among the lines, we see the invoked syscall: read(): .... ;do_syscall_64;sys_read; .... Thus, cadvisor spends a lot of time on the system call read(), related to the functions mem_cgroup_* (top of the call stack/end of the line).
In the call trace, it's inconvenient to see what exactly is being read, so let's run strace and see what cadvisor is doing, and find system calls longer than 100 ms:
theojulienne@kube-node-bad ~ $ sudo strace -p 10137 -T -ff 2>&1 | egrep '<0.[1-9]'
 [pid 10436]  ) = 0
 [pid 10432]  ) = 0
 [pid 10137]  ) = 0
 [pid 10384]  ) = 0
 [pid 10436]  "cache 154234880nrss 507904nrss_h"..., 4096) = 658
 [pid 10384]  ) = 0
 [pid 10436]  ) = 0
 [pid 10436]  "cache 0nrss 0nrss_huge 0nmapped_"..., 4096) = 577
 [pid 10427]  "cache 0nrss 0nrss_huge 0nmapped_"..., 4096) = 577
 [pid 10411]  ) = 0
 [pid 10382]  ) = 0 (Timeout)
 [pid 10436]  "cache 154234880nrss 507904nrss_h"..., 4096) = 660
 [pid 10417]  ) = 0
 [pid 10436]  ) = 0
 [pid 10417]  ) = 0
 [pid 10417]  "cache 0nrss 0nrss_huge 0nmapped_"..., 4096) = 576
As expected, here we see slow calls read(). From the content of read operations and context mem_cgroup it is clear that these calls read() relate to the file memory.stat, which shows memory usage and cgroup limits (resource isolation technology in Docker). The cadvisor tool queries this file to obtain resource usage information for containers. Let's check if the kernel or cadvisor is doing something unexpected:
theojulienne@kube-node-bad ~ $ time cat /sys/fs/cgroup/memory/memory.stat >/dev/null
real 0m0.153s
user 0m0.000s
sys 0m0.152s
theojulienne@kube-node-bad ~$
Now we can reproduce the bug and understand that the Linux kernel is encountering a pathology.
What causes the read operation to be so slow?
At this stage, it is much easier to find messages from other users about similar issues. It turns out that this bug was reported in the cadvisor tracker as , but no one noticed that the delay also randomly reflected in the network stack. It was indeed noted that cadvisor consumes more CPU time than expected, but it was not given much importance, as our servers have plenty of CPU resources, so the issue was not thoroughly investigated.
The problem is that control groups (cgroups) account for memory usage within the namespace (container). When all processes in this cgroup terminate, Docker releases the memory control group. However, 'memory' is not just the memory of the process. Although the memory of processes is no longer used, it turns out that the kernel assigns cached content, such as dentries and inodes (directory and file metadata), which are cached in the memory cgroup. From the problem description:
zombie cgroups: control groups with no processes that have been removed, but for which memory is still allocated (in my case, from the dentry cache, but it can also be allocated from the page cache or tmpfs).
Checking all pages in the cache by the kernel upon releasing a cgroup can be very slow, therefore a lazy process is chosen: to wait until these pages are requested again, and only then, when memory is actually needed, to finally clean up the cgroup. Until that moment, the cgroup is still taken into account when collecting statistics.
In terms of performance, they sacrificed memory for efficiency: speeding up the initial cleanup by leaving some cached memory. This is acceptable. When the kernel uses the last portion of cached memory, the cgroup eventually cleans itself, so this cannot be called a 'leak.' Unfortunately, the specific implementation of the search mechanism memory.stat in this kernel version (4.9), combined with the vast amount of memory on our servers, means that recovering the last cached data and cleaning up zombie cgroups takes significantly longer.
It turned out that some of our nodes had so many zombie cgroups that the reading and delay exceeded one second.
A workaround for the cadvisor issue is to immediately free the dentries/inodes caches across the system, which instantly mitigates the read delay as well as the network delay on the host, since removing the cache also includes cached pages of zombie cgroups, which are freed too. This is not a solution but confirms the cause of the problem.
It was found that in newer kernel versions (4.19+) the performance of the call improved memory.stat, so switching to this kernel resolved the issue. Meanwhile, we had the tools to detect problematic nodes in the Kubernetes clusters, gracefully drain them, and restart. We scanned all clusters, identified nodes with significantly high latency, and rebooted them. This bought us time to update the OS on the remaining servers.
In summary
Since this bug halted the processing of NIC RX queues for hundreds of milliseconds, it simultaneously caused both high latency on short connections and mid-connection delays, such as between MySQL requests and response packets.
Understanding and supporting the performance of the most fundamental systems like Kubernetes is crucial for the reliability and speed of all services built on them. All running systems benefit from Kubernetes performance improvements.
Source: habr.com
