

The main purpose of Patroni is to ensure High Availability for PostgreSQL. However, Patroni is just a template, not a ready-made tool (as stated in the documentation). At first glance, setting up Patroni in a testing lab shows how great a tool it is and how easily it handles our attempts to crash the cluster. However, in practice, in a production environment, things don't always go as smoothly and elegantly as in a test lab.
Let me tell you a little about myself. I started as a system administrator. I worked in web development. Since 2014, I have been working at Data Egret. The company specializes in consulting in the field of Postgres. We specifically service Postgres and work with it every day, so we have a variety of expertise related to its operation.
By the end of 2018, we gradually started using Patroni. We accumulated some specific experience. We diagnosed it, tuned it, and came up with our best practices. In this presentation, I will be discussing them.
Besides Postgres, I love Linux. I enjoy digging into it and exploring, and I like building kernels. I love virtualization, containers, Docker, and Kubernetes. I’m interested in all of this because of my old administrative habits. I also enjoy working with monitoring systems. And I have a passion for Postgres-related administrative tasks, such as replication and backups. In my spare time, I write in Go. I am not a software engineer; I just write for myself in Go, and I find it enjoyable.
- I think many of you know that Postgres does not have HA (High Availability) out of the box. To achieve HA, you need to install something, configure it, put in some effort, and then you can obtain it.
- There are several tools, and Patroni is one of them that addresses HA quite effectively and impressively. But after installing it in a testing lab and running it, we can see that it works; we can reproduce some issues and observe how Patroni handles them. We will find that it all works wonderfully.
- However, in practice, we have encountered various issues. I will be discussing these problems.
- I will explain how we diagnosed them and what adjustments we made—whether it helped us or not.
- I won't explain how to install Patroni because you can easily find this information online, or you can look at the configuration files to understand how it works and how to configure it. You can familiarize yourself with the schemes and architectures by finding information about them online.
- I won't talk about someone else's experience. I will only discuss the specific issues we faced.
- And I won’t go into the problems outside of Patroni and PostgreSQL. For instance, issues related to load balancing when our cluster broke apart, I won’t cover that.
And a small disclaimer before I start our presentation.
All these problems we encountered happened in the first 6-7-8 months of operation. Over time, we developed our own internal best practices, and the problems disappeared. Therefore, this presentation was proposed about six months ago when everything was still fresh in my mind.
While preparing the presentation, I went through old postmortems and examined logs. Some details might have been forgotten, or some aspects may not have been thoroughly investigated during our problem analysis, so it may seem at times that the issues have not been fully addressed, or there may be some lack of information. I apologize for this.
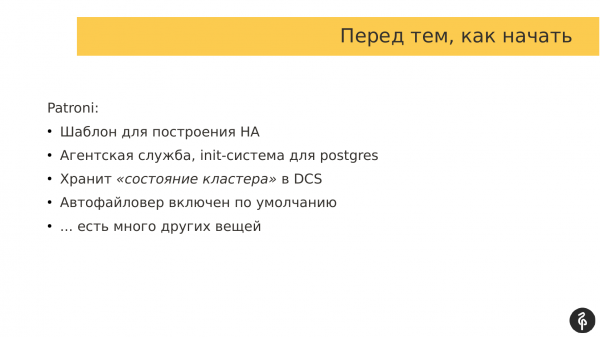
What is Patroni?
- It is a template for building HA. That's what the documentation states. From my perspective, this is a very accurate clarification. Patroni is not a silver bullet that will solve all your problems; you need to put in effort for it to work and bring benefits.
- It is an agent service that is installed on each service with a database and serves as a kind of init system for your Postgres. It starts, stops, restarts, configures, and changes the topology of your cluster.
- Accordingly, to store the state of the cluster, its current representation, as it appears, you need some kind of storage. From this perspective, Patroni chose to store the state in an external system. This is a distributed configuration store. It can be Etcd, Consul, ZooKeeper, or Kubernetes’ Etcd; in other words, one of these options.
- One of the features of Patroni is that you get the auto-failover out of the box, simply by configuring it. In comparison, with Repmgr, the failover comes as part of the package. With Repmgr, we get switchover, but if we want auto-failover, it has to be set up additionally. Patroni already has auto-failover integrated.
- There are many other features as well. For example, configuration management, provisioning new replicas, backups, etc. However, those are beyond this presentation, so I won’t discuss them.
In summary, the primary task of Patroni is to effectively and reliably perform auto-failover, ensuring that the cluster remains operational and the application does not notice changes in the cluster topology.
However, when we start using Patroni, our system becomes a little more complex. If we previously had Postgres, using Patroni introduces not only Patroni itself but also a DCS where the state is stored. Everything needs to work together. So, what could go wrong?
What could go wrong:
- Postgres could fail. This could be either the master or a replica, one of them may fail.
- Patroni itself could fail.
- The DCS where the state is stored could fail.
- And the network might fail.
I will discuss all these issues in the presentation.
I will examine cases as they become more complex, not in terms of the case involving many components, but based on my subjective experience of how challenging it was to analyze a particular case... and conversely, some cases were easier to analyze.
The first case is the simplest. This is when we take a database cluster and deploy our DCS storage on the same cluster. This is the most common mistake. It’s an architectural flaw, i.e., combining different components in one location.
So, a failover occurred; let’s investigate what happened.
Here, we are interested in when the failover occurred, specifically the moment in time when the state change of the cluster happened.
However, the failover is not always instantaneous; it doesn’t take place over a single unit of time, it can take a while. It can be prolonged.
Therefore, it has a start time and end time, meaning it is a long-running event. We divide all events into three intervals: there is time before the failover, during the failover, and after the failover. In other words, we consider all events on this timeline.
First of all, when the failover occurs, we look for the reason behind it, what happened that led to the failover.
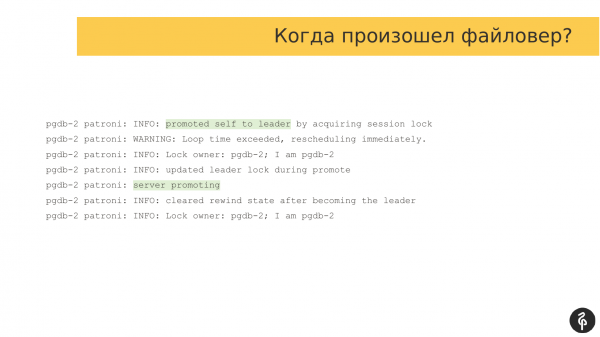
If we look at the logs, we will see the classic Patroni logs. It informs us that the server became the master, and the master's role moved to this node. This is highlighted here.
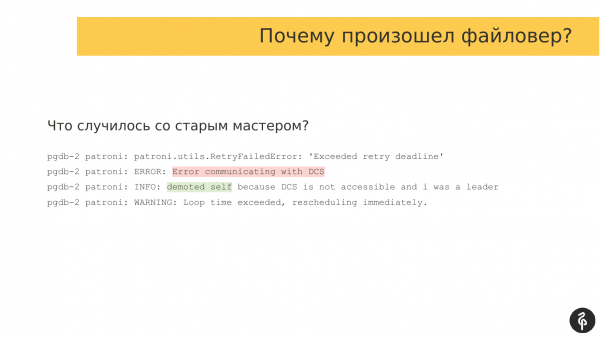
Next, we need to understand why the failover occurred, that is, what events happened that caused the master role to shift from one node to another. In this case, it’s straightforward. We have an interaction error with the storage system. The master realized that it could not work with the DCS, meaning there was some problem with the interaction. It states that it can no longer be the master and relinquishes its authority. The line 'demoted self' refers to this.
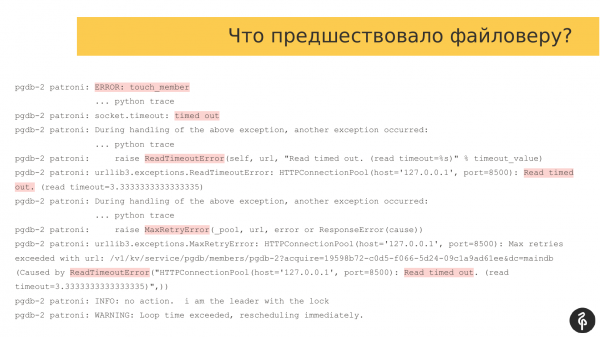
If we look at the events leading up to the failover, we can see the very reasons that caused problems for the continuation of the master's work.
If we check the Patroni logs, we will see a multitude of errors, timeouts, meaning the Patroni agent cannot operate with the DCS. In this case, it is the Consul agent, with which communication is conducted over port 8500.
The problem here is that Patroni and the database are running on the same host. And the Consul servers were also running on this node. By creating a load on the server, we created problems for servers Consul. They could not communicate effectively.
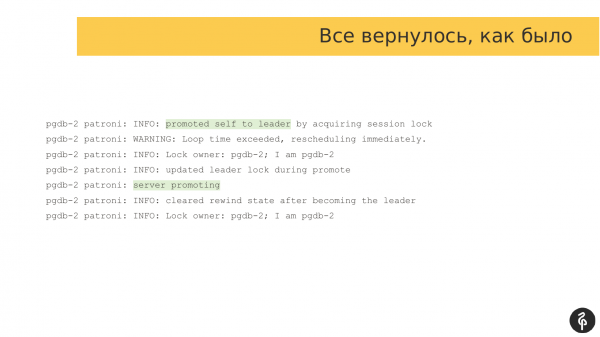
After some time, when the load decreased, our Patroni could communicate with the agents again. Normal operation resumed. The same server Pgdb-2 became the master again. There was a small flip, due to which the node relinquished its master authority and then took it back, meaning everything reverted to how it was.
This can be interpreted as a false alarm, or it can be seen that Patroni acted correctly. That is, it realized it could not maintain the cluster state and relinquished its authority.
The issue arose because the Consul servers are on the same hardware as the databases. Consequently, any load—whether on the disks or on the processors—also affects interaction with the Consul cluster.
We concluded that these should not coexist, so we allocated a separate cluster for Consul. Patroni then operated with a separate Consul, meaning there was a separate Postgres cluster and a separate Consul cluster. This is the basic guideline on how to separate these components to ensure they do not coexist.
One option is to adjust the parameters ttl, loop_wait, and retry_timeout, attempting to manage these temporary load spikes by increasing these settings. However, this is not the best choice, as the load may be prolonged. We may simply exceed the limits of these parameters, which may not be very helpful.
The first problem, as you understand, is straightforward. We placed the DCS alongside the database and encountered a problem.
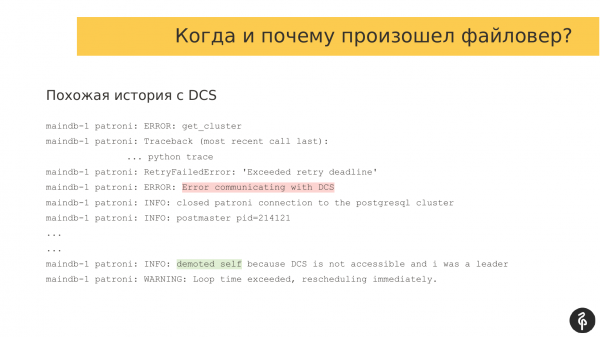
The second problem is similar to the first, as we once again have issues interacting with the DCS system.
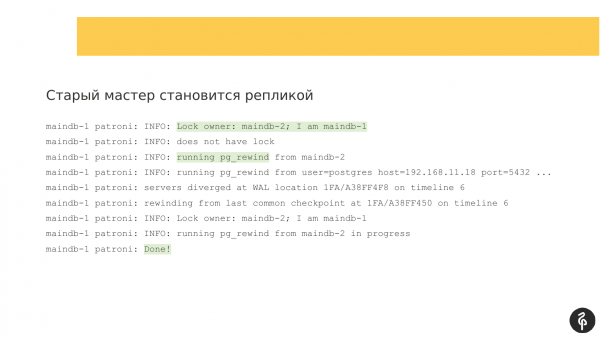
Looking at the logs, we can see that communication errors have occurred again. Patroni indicates that it cannot communicate with the DCS, which leads the current master to enter replica mode.
The old master becomes a replica, and here Patroni functions as intended. It executes pg_rewind to rewind the transaction log and subsequently connects to the new master to catch up with it. Patroni performs as expected in this scenario.
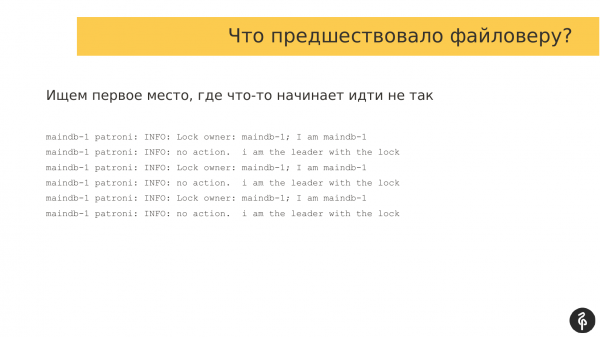
Here we need to find the event that preceded the file error, that is, the errors that caused the file error to occur. In this respect, working with Patroni's logs is quite convenient. It writes the same messages at specific intervals. If we quickly scroll through these logs, we will see that the logs have changed, which indicates that some problems have begun. We quickly return to that point and observe what is happening.
In a normal situation, the logs look something like this. The lock owner is checked, and if the owner has changed, certain events may occur that Patroni should respond to. However, in this case, everything is fine. We are looking for the point at which the errors began.
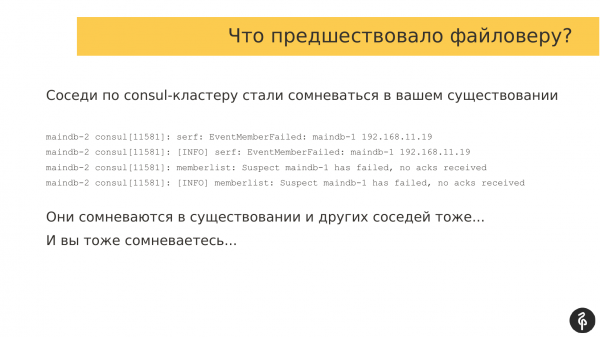
Scrolling back to the point where the errors began to appear, we can see that an auto-failover occurred. Since our errors were related to interactions with the DCS and in our case we used Consul, we also check the Consul logs to see what was happening there.
By roughly aligning the failover time with the time in the Consul logs, we observe that our neighbors in the Consul cluster began to doubt the existence of other Consul cluster participants.
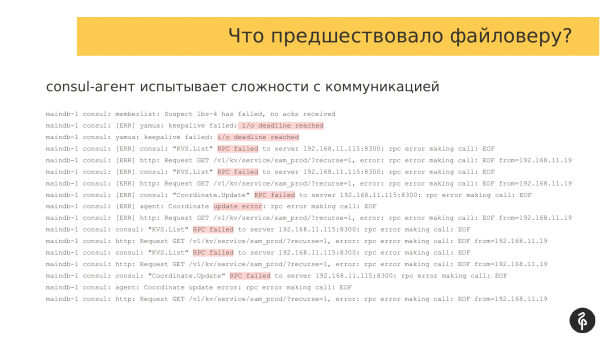
If we also examine the logs of other Consul agents, we can see that some sort of network collapse is happening there as well. All participants in the Consul cluster are questioning each other's existence, which triggered the failover.
Looking at what was happening before these errors, we can see various issues such as deadlines, RPC failures, meaning there was clearly some problem with the interactions between the participants in the Consul cluster.
The simplest answer is to fix the network. However, standing at the podium, it's easy for me to make such a statement. The circumstances often dictate that the client may not always afford to repair the network. They might be in a data center and have no means to fix the network or influence the equipment. Therefore, some other options are necessary.
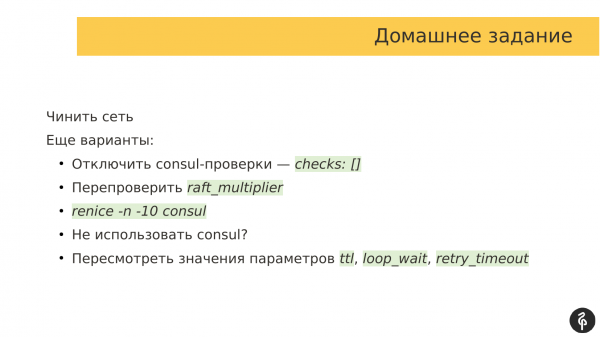
Options include:
- The simplest option, which I believe is even mentioned in the documentation, is to disable Consul checks, i.e., simply pass an empty array. We instruct the Consul agent not to use any checks. By ignoring these checks, we can avoid these network storms and not initiate failover.
- Another option is to recheck the raft_multiplier. This parameter belongs to the Consul server itself. By default, it is set to a value of 5. This value is recommended in the documentation for staging environments. Essentially, it affects the frequency of message exchanges between participants in the Consul network. In essence, this parameter influences the speed of communications among the Consul cluster participants. It is recommended to reduce it for production environments to allow nodes to exchange messages more frequently.
- Another option we've started using is increasing the priority of Consul processes among other processes for the operating system's process scheduler. There's a parameter called 'nice' that defines the priority of processes considered by the OS scheduler during planning. We decreased the nice value for Consul agents, i.e., increased their priority so that the operating system allocates more time for Consul processes to work and execute their code. In our case, this resolved our issue.
- Another alternative is not to use Consul at all. I have a colleague who is a strong advocate for Etcd, and we frequently debate which is better, Etcd or Consul. However, when it comes to which is superior, we usually agree that Consul has an agent that must run on every node with a database. This means that Patroni interacts with the Consul cluster through this agent, which can become a bottleneck. If something happens to the agent, Patroni can no longer work with the Consul cluster, which is a problem. In the case of Etcd, there is no such agent, allowing Patroni to work directly with the list of Etcd servers and communicate with them. So if you're using Etcd in your company, it would likely be a better choice than Consul. However, we are often limited by what the client has chosen and uses. Most of our clients use Consul.
- The last point is to reconsider the parameter values. We can increase these parameters with the hope that our short-term network issues will be brief and won't exceed these parameter intervals. This way, we can reduce Patroni's aggressiveness in executing auto-failover if any network issues arise.
I think many who use Patroni are familiar with this command.
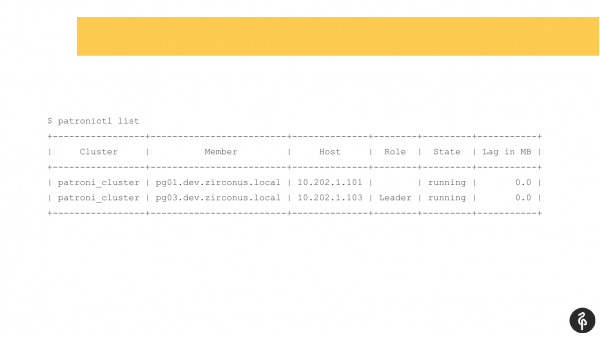
This command shows the current state of the cluster. At first glance, this picture may seem normal. We have a master, a replica, and no replication lag. However, this situation is normal only until we realize that this cluster should have three nodes, not two.
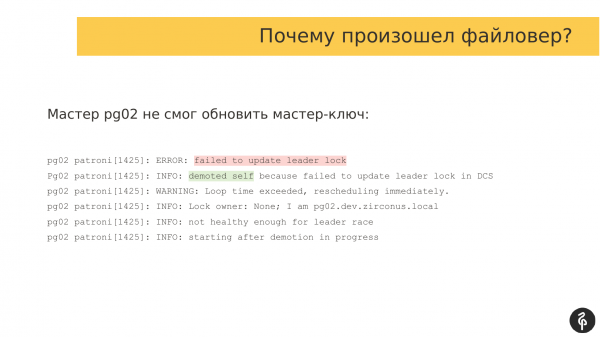
As a result, an auto-failover occurred. After this auto-failover, we lost a replica. We need to determine why it disappeared and restore it. We are going back to the logs to see why the auto-failover happened.
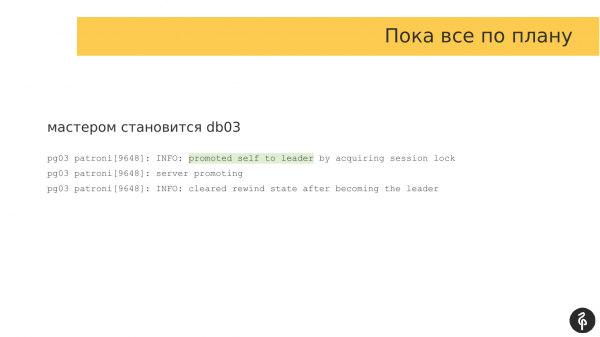
In this case, the second replica became the master. Everything is fine here.
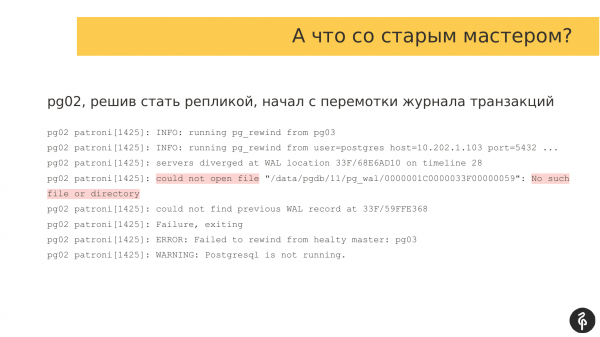
Now, we need to look at the replica that dropped off and is not in the cluster. We open the Patroni logs and check that there was a problem during the connection to the cluster at the pg_rewind stage. To connect to the cluster, we need to rewind the transaction log, request the necessary transaction log from the master, and catch up to the master.
In this case, we do not have the transaction log, and the replica cannot start. Consequently, we stop Postgres with an error. That's why it is not in the cluster.
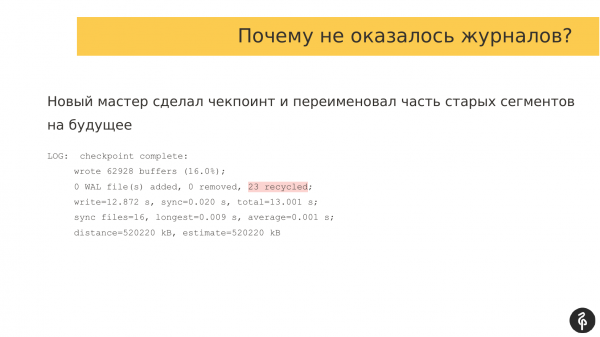
We need to understand why it is not in the cluster and why there are no logs. We go to the new master and check its logs. It turns out that when pg_rewind was executed, a checkpoint occurred. Part of the old transaction logs was simply renamed. When the old master tried to connect to the new master and request these logs, they had already been renamed and were simply not there.
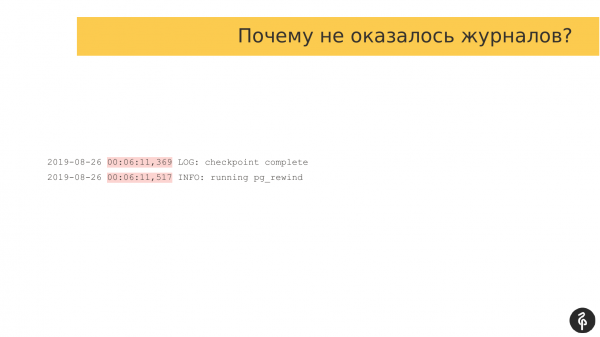
I compared the timestamps of when these events occurred. The difference was just 150 milliseconds, that is, the checkpoint finished in 369 milliseconds, and the WAL segments were renamed. Literally, 517 milliseconds later, after 150 milliseconds, the rewind started on the old replica. So, it took just 150 milliseconds for the replica to fail to connect and function.
What are the options?
Initially, we used replication slots. We thought it was a good idea. However, at the first stage of operation, we disabled the slots. We believed that if the slots accumulated too many WAL segments, we could crash the master. It would go down. We struggled for some time without slots and realized that we needed them, so we brought back the slots.
However, there is a problem: when the master switches to a replica, it deletes slots and along with the slots, it removes WAL segments. To prevent this issue, we decided to increase the wal_keep_segments parameter. By default, it is set to 8 segments. We raised it to 1,000 and checked how much free space we had. We allocated 16 gigabytes for wal_keep_segments. This means that during a switch, we always have 16 gigabytes of transaction logs available on all nodes.
Plus, this is still relevant for prolonged maintenance tasks. For example, if we need to update one of the replicas, and we want to shut it down. We need to update the software, perhaps the operating system, or something else. When we shut down the replica, the slot for that replica is also deleted. If we use a small wal_keep_segments, then during the prolonged absence of the replica, the transaction logs may playback. We will bring up the replica, it will request the transaction logs from where it stopped, but there may not be any left on the master. Consequently, the replica will also be unable to connect. That’s why we maintain a large reserve of logs.
We have a production database. There are already projects running there.
A file error occurred. We logged in and checked – everything is fine, the replicas are in place, and there is no replication lag. There are also no errors in the logs; everything is in order.
The product team says that there should be some data, but we see it in one source, while it is missing from the database. We need to understand what happened to it.
It’s clear that pg_rewind overwrote it. We figured that out right away, but we went to see what had happened.
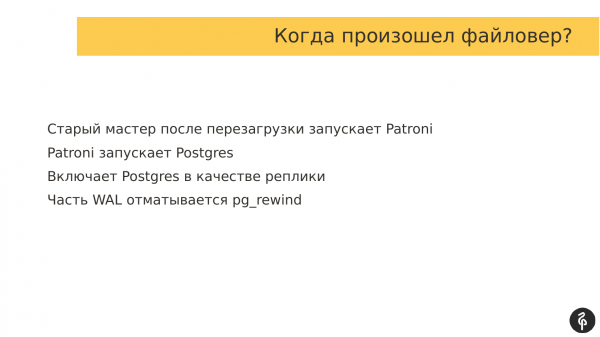
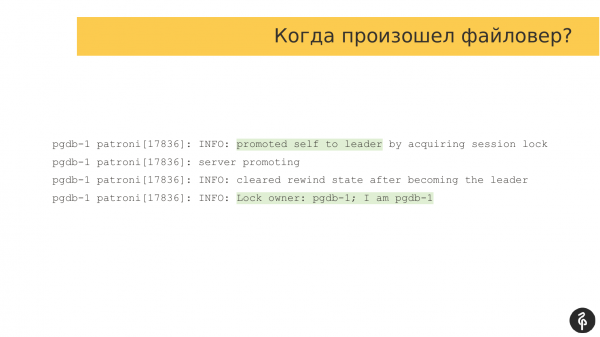
In the logs, we can always find out when the file error occurred, who became the master, and we can identify who the old master was and when it wanted to become a replica. We need these logs to determine the volume of transaction logs that were lost.
Our old master rebooted. The startup was configured with Patroni. Patroni started up. Following that, it started Postgres. More specifically, before launching Postgres and before making it a replica, Patroni executed the pg_rewind process. Consequently, it deleted part of the transaction logs, downloaded new ones, and connected. Here, Patroni performed excellently, just as it was supposed to. Our cluster has recovered. We had 3 nodes, and after the file error, we still have 3 nodes – everything is great.
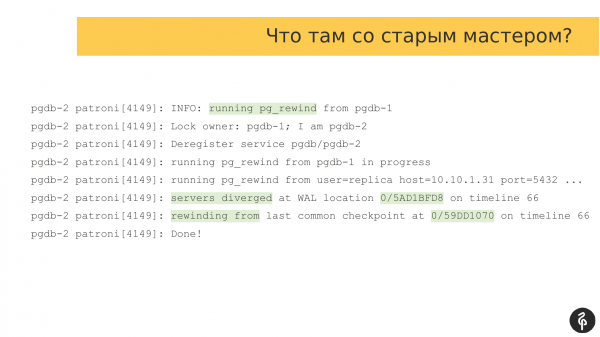
We lost some data, and we need to understand how much we lost. We are looking for the exact moment when the rewind occurred. We can find this in the log records. The rewind started, did something, and then finished.
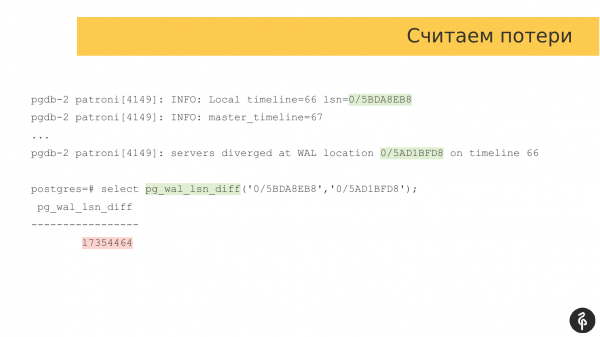
We need to find the position in the transaction log where the old master stopped. In this case, it is this mark. And we need a second mark, that is, the distance by which the old master differs from the new one.
We take the usual pg_wal_lsn_diff and compare these two marks. In this case, we get 17 megabytes. Whether this is a lot or a little is for everyone to decide for themselves. Because for someone, 17 megabytes is not much, while for someone else it is too much and unacceptable. It’s an individual determination based on business needs.
But what have we figured out for ourselves?
First of all, we need to decide whether we always need to automatically start Patroni after a system reboot. More often than not, we have to check the old master to see how far it has gone. Possibly inspect the segments of the transaction log to see what’s there. And determine whether we can lose this data, or if we need to start the old master in standalone mode to retrieve it.
Only after that should we make a decision about whether we can discard this data or if we can restore it and connect this node as a replica in our cluster.
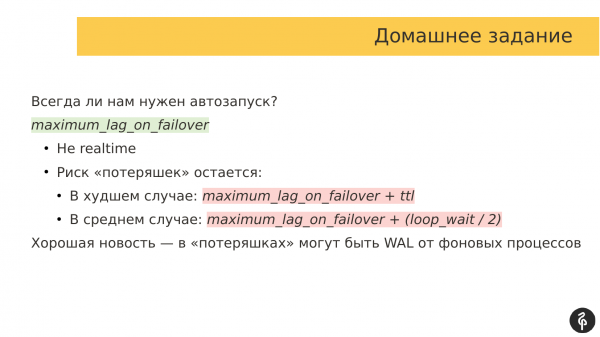
Additionally, there is the parameter ‘maximum_lag_on_failover’. By default, if I am not mistaken, this parameter is set to 1 megabyte.
How does it work? If our replica lags behind by 1 megabyte of data due to replication lag, this replica does not participate in the elections. And if a failover occurs, Patroni checks which replicas are lagging. If they lag behind a large number of transaction logs, they cannot become the master. This is a very good safety feature that helps prevent the loss of a lot of data.
However, there is a problem in that the replication lag in the Patroni cluster and DCS is updated at a certain interval. I believe the default ttl value is 30 seconds.
Accordingly, there may be a situation where the replication lag for replicas in the DCS is one, while in reality, there may be a completely different lag or there might not be any lag at all, meaning this thing is not real-time. And it does not always reflect the true picture. Therefore, it is not worth building complex logic on top of it.
The risk of data loss always remains. In the worst-case scenario, there is one formula, and in the average case, another formula. That is, when we plan to implement Patroni and assess how much data we might lose, we should rely on these formulas and have a rough idea of how much data we could potentially lose.
And there is good news. When the old master moves ahead, it may do so due to some background processes. That is, there was some auto-vacuum, it wrote data, and saved it in the transaction log. We can easily ignore that data and lose it. There is no issue with that.
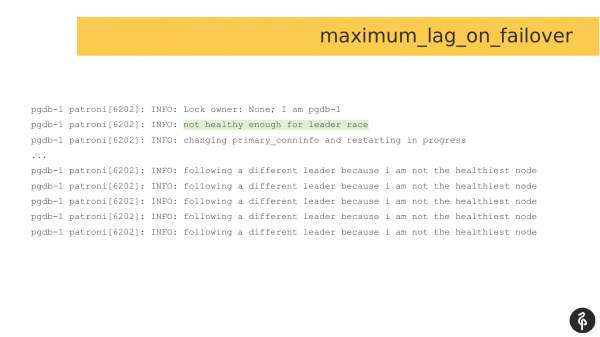
And this is how the logs look if maximum_lag_on_failover is set and a failover occurs, requiring the selection of a new master. The replica assesses itself as unable to participate in the election, and it declines to take part in the leader race. It waits for a new master to be chosen so that it can then connect to it. This is an additional measure against data loss.
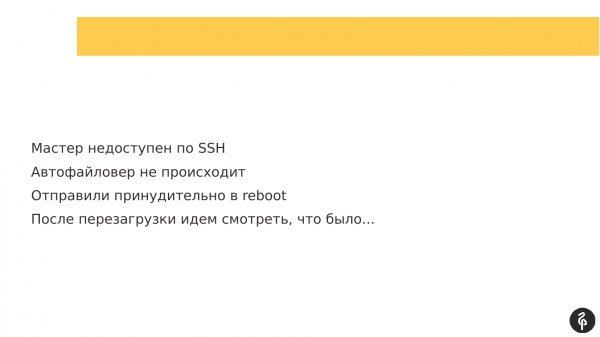
Here, our product team reported that their product is experiencing issues when working with Postgres. Meanwhile, access to the master is not possible, as it is unavailable via SSH. Additionally, an auto-failover is not occurring.
This host was forcibly restarted. Due to the reboot, an auto-failover occurred, although a manual auto-failover could have also been performed, as I understand now. After the reboot, we are already going to check what happened with the current master.
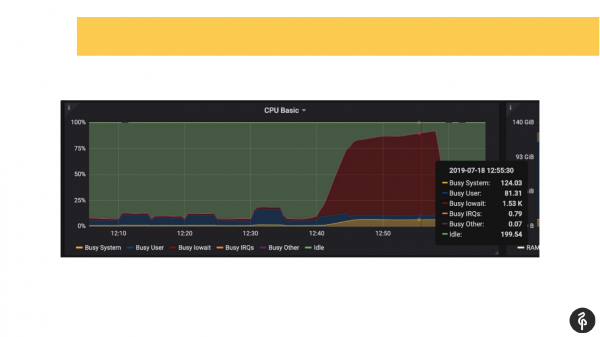
At the same time, we already knew in advance that there were issues with the disks, meaning we already had an idea from monitoring about where to dig and what to search for.
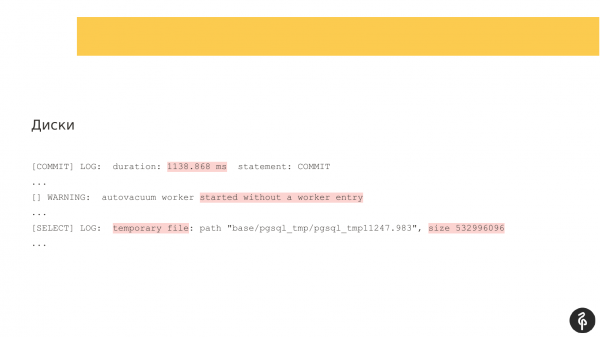
We accessed the postgres log and began to see what was happening. We observed commits lasting one to three seconds, which is quite abnormal. We saw that our auto-vacuum is starting very slowly and strangely. And we noticed temporary files on the disk. These are all indicators of disk issues.
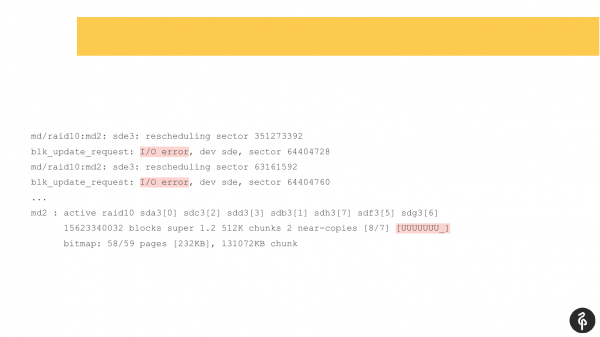
We checked the system dmesg (the kernel message log) and found that we have issues with one of the drives. The disk subsystem was a software RAID. We looked at /proc/mdstat and saw that we were missing one drive. That is, we have a RAID with 8 disks, and we're short one. If you closely examine the slide, you can see in the output that sde is missing. It's as if we lost a disk. This triggered disk issues, and the applications also experienced difficulties when working with the Postgres cluster.
In this case, Patroni wouldn’t have helped us because Patroni isn’t designed to monitor the server's status or the disk's state. We need to monitor such situations with external monitoring. We added disk monitoring to our external monitoring system promptly.
There was a thought—could fencing or a software watchdog help us? We thought it would unlikely to assist in this case because during the issues, Patroni continued to interact with the DCS cluster and didn't see any problems. That is, from the DCS and Patroni's perspective, everything was fine with the cluster, although there were issues with the disk and database availability.
In my opinion, this is one of the strangest problems I've researched for a long time; I've read many logs, dug through them, and labeled it the cluster-simulating issue.
The problem was that the old master couldn't become a proper replica; that is, Patroni started it, and Patroni indicated that this node was present as a replica, but it was not a proper replica. You will now see why. I have records from that issue's analysis.
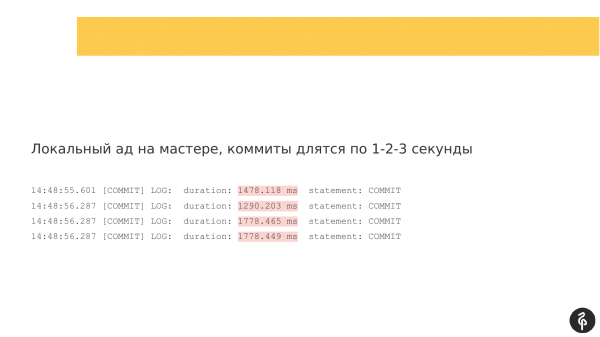
And how did it all start? It began, as in the previous issue, with disk lags. We had commits of one to two per second.
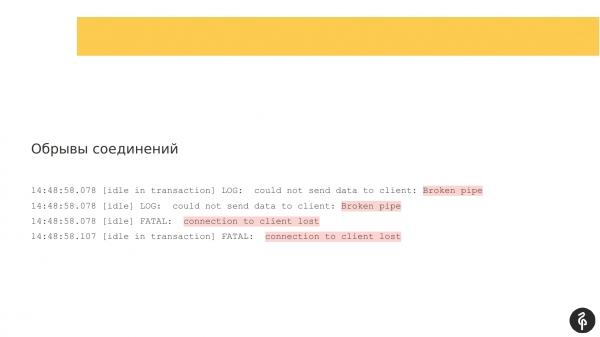
There were connection drops; that is, clients were disconnecting.
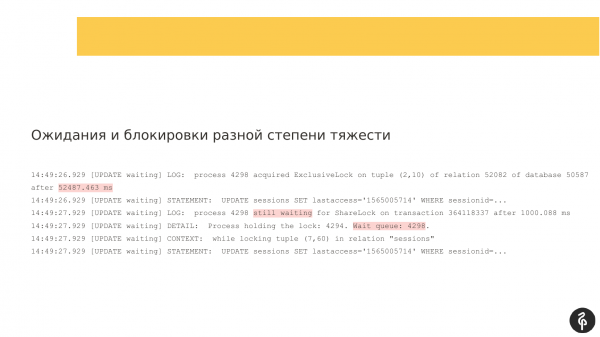
There were various severities of locks.
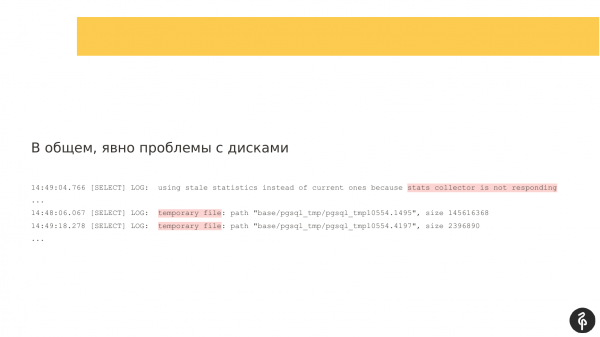
And accordingly, the disk subsystem was not very responsive.
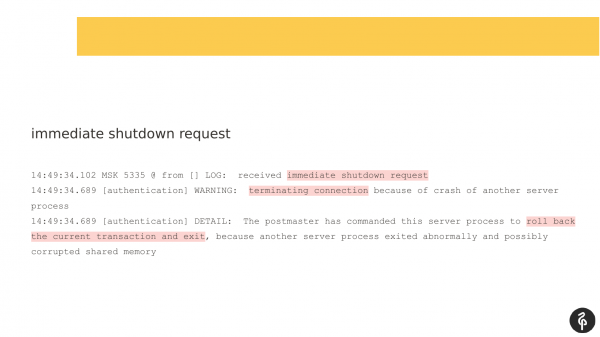
And the most mysterious thing for me was the immediate shutdown request. Postgres has three shutdown modes:
- There is graceful, when we wait for all clients to disconnect on their own.
- There is fast, when we force clients to disconnect because we are shutting down.
- And immediate. In this case, immediate doesn’t even notify clients that they need to disconnect; it just shuts down without warning. All clients receive a RST message from the operating system (a TCP message indicating that the connection has been terminated and there is nothing left for the client).
Who sent this signal? Background processes in Postgres do not send such signals to each other, meaning this is a kill -9. They do not send such signals among themselves; they only react to them, so this is an emergency restart of Postgres. I don’t know who sent it.
I looked at the ‘last’ command and saw one person who also logged into this server with us, but I hesitated to ask. It might have been kill -9. I would have seen kill -9 in the logs since Postgres logs that it received kill -9, but I didn’t see it in the logs.
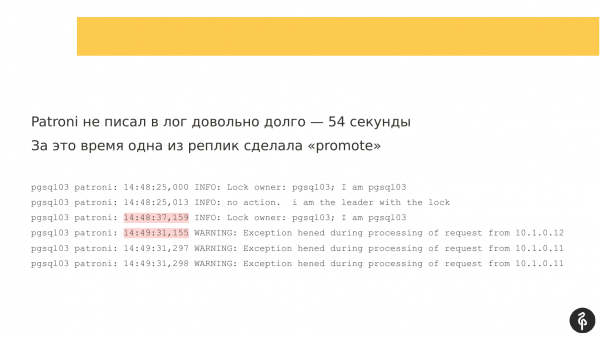
Further investigating, I noticed that Patroni hadn’t written to the log for quite some time – 54 seconds. Comparing the two timestamps, there were about 54 seconds without messages.
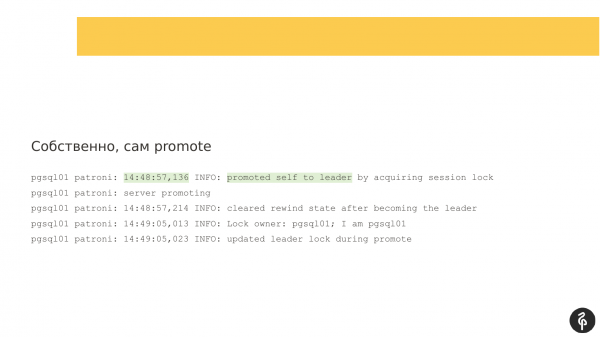
During this time, an auto failover occurred. Patroni worked perfectly again. Our old master was unavailable; something was happening with it. And elections for a new master began. Everything worked out well here. Our pgsql01 became the new leader.
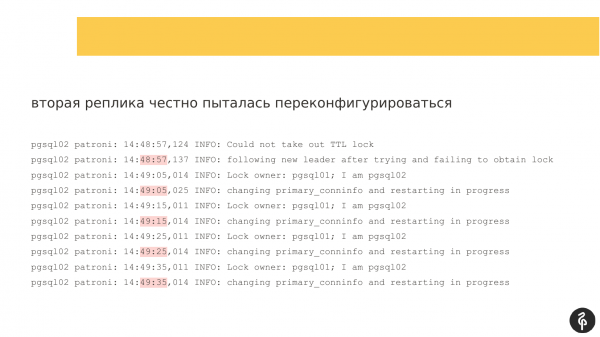
We have a replica that became a master. And there is a second replica. The second replica had issues. It was trying to reconfigure itself. As I understand it, it was trying to change recovery.conf, restart Postgres, and connect to the new master. Every 10 seconds, it logs messages indicating that it’s trying, but has been unsuccessful.
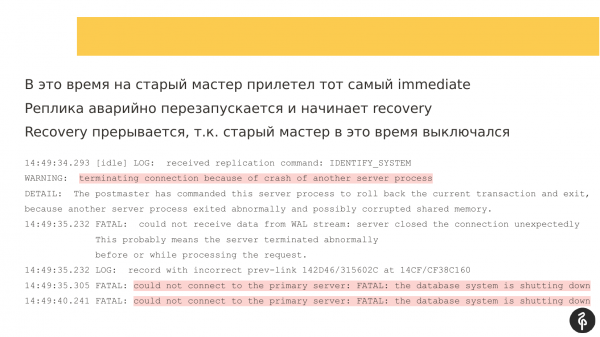
And during these attempts, the old master received an immediate-shutdown signal. The master restarted. Recovery also stopped because the old master was going through a reboot. That is, the replica cannot connect to it because it is in shutdown mode.
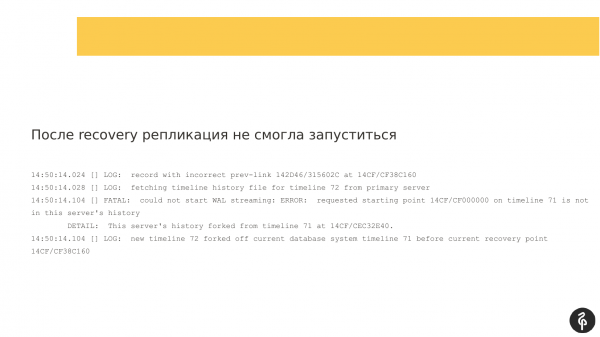
At some point, it started working, but the replication did not start.
I have a single hypothesis that the address of the old master was in recovery.conf. When the new master appeared, the second replica was still trying to connect to the old master.
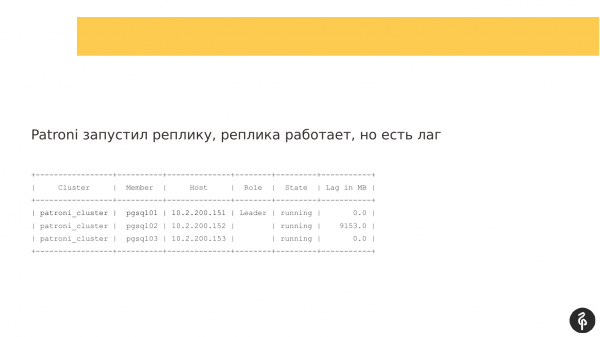
When Patroni started on the second replica, the node came up but was unable to connect for replication. A replication lag was formed that looked roughly like this. That is, all three nodes were present, but the second node was lagging.
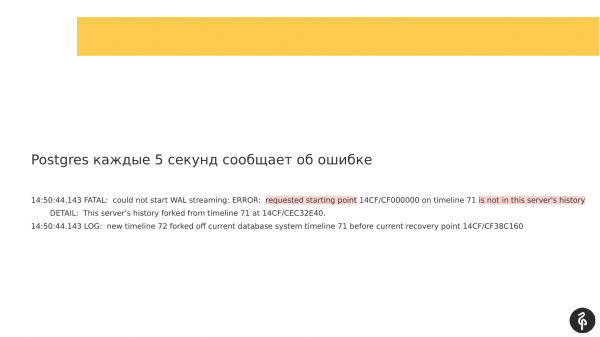
However, if you look at the logs that were recorded, you could see that replication could not start because the transaction logs were different. The transaction logs proposed by the master, as specified in recovery.conf, simply do not match our current node.
And here I made a mistake. I should have checked what was in recovery.conf to verify my hypothesis that we were connecting to the wrong master. But at that time, I was just getting a hang of it, and it didn't occur to me, or I saw that the replica was lagging and thought it would have to be reloaded, so I sort of went through it without much care. That was my oversight.
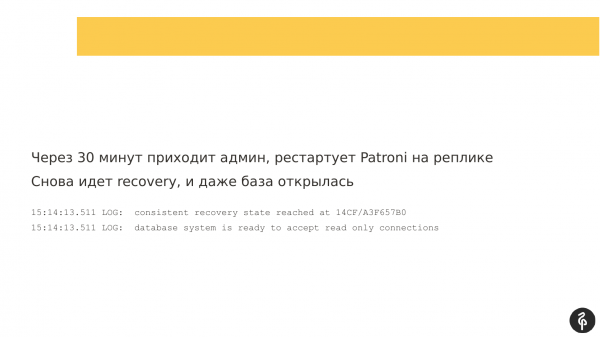
Thirty minutes later, the admin arrived, meaning I restarted Patroni on the replica. I had already given up on it, thinking it would have to be reloaded. And I thought – I'll restart Patroni, maybe something good will come of it. Recovery started. And the database even opened up, it was ready to accept connections.
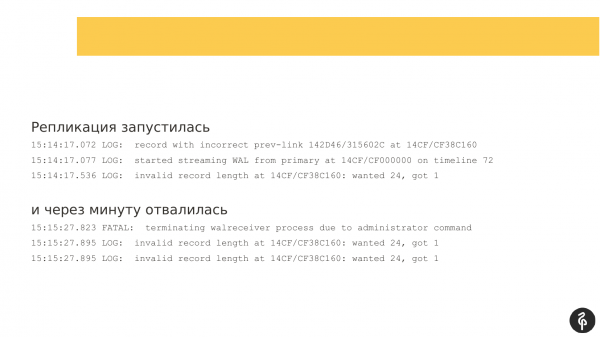
Replication started. But a minute later, it failed with an error that the transaction logs were incompatible.
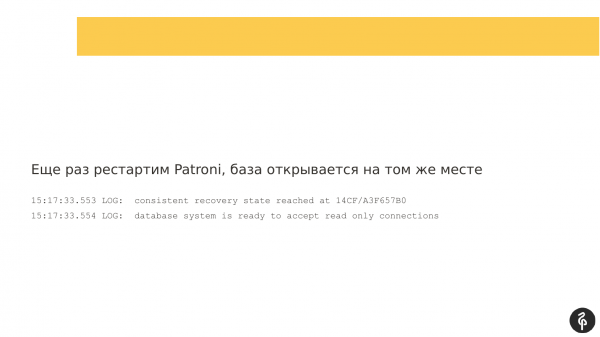
I thought I'd try restarting it once more. I restarted Patroni again, and I didn't restart Postgres, but specifically Patroni, hoping it would magically start the database.
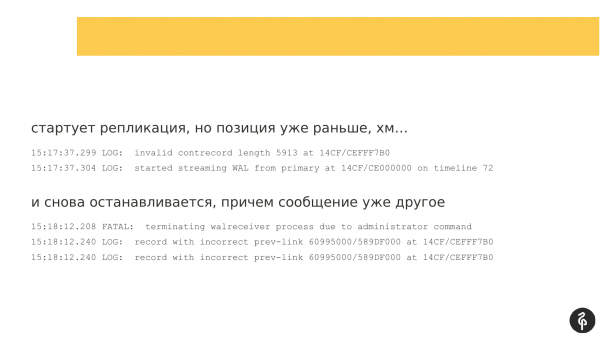
Replication started again, but the marks in the transaction log differed; they were not the same as those during the previous start attempt. Replication stopped again. And the message was slightly different. It wasn't particularly informative for me.
And then it occurred to me – what if I restart Postgres, and at that time do a checkpoint on the current master to push the point in the transaction log a little forward so that recovery starts from a different moment? Plus, we still had some WAL reserves.
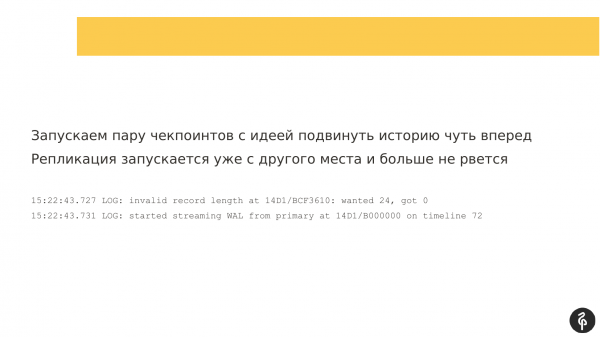
I restarted Patroni, created a couple of checkpoints on the master, a couple of restart points on the replica when it opened. And that helped. I thought for a long time about why that helped and how it worked. And the replica started. And the replication no longer broke.
This issue is one of the more puzzling ones for me, one that I still scratch my head over, trying to figure out what was actually happening.
What conclusions can we draw here? Patroni can function as intended and without any errors. However, this does not guarantee that everything is fine. A replica may start, but it could be in a semi-operational state, and the application cannot work with such a replica because it will contain outdated data.
And after a failover, it is always necessary to check that everything is in order with the cluster, i.e., there is the required number of replicas and no replication lag.
As I discuss these issues, I will formulate recommendations. I tried to consolidate them into two slides. Perhaps all stories could have been combined into two slides and only those told.
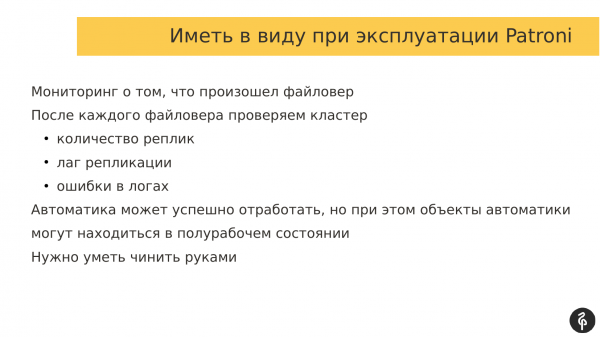
When using Patroni, you must have monitoring in place. You should always know when a failover occurred; if you don’t know that a failover happened, you cannot manage the cluster. And that's a problem.
After each failover, we must always manually check the cluster. We need to ensure that we always have the correct number of replicas, no replication lag, and that there are no errors in the logs related to streaming replication, Patroni, or the DCS system.
Automation can work successfully; Patroni is a very good tool. It can function, but that does not lead the cluster to the desired state. If we do not recognize this, we will encounter problems.
And Patroni is not a silver bullet. We still need to understand how Postgres works, how replication functions, and how Patroni interacts with Postgres and facilitates communication between nodes. This is necessary to be able to manually fix emerging issues.
How do I approach the issue of diagnostics? It so happens that we work with different clients, and no one has the ELK stack, so we have to dig through logs, opening 6 consoles and 2 tabs. In one tab are Patroni logs for each node, and in the other tab are Consul logs or Postgres logs when necessary. Diagnosing this is quite difficult.
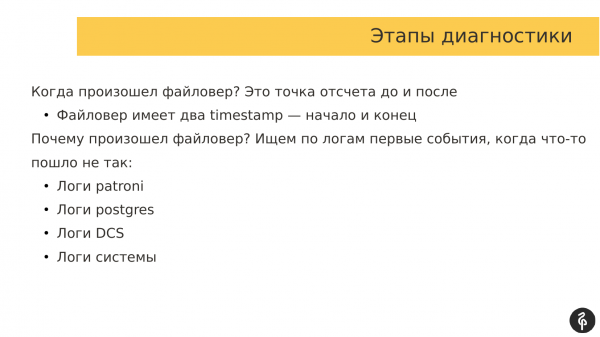
What approaches have I developed? First, I always check when the failover occurred. For me, this is a critical point. I look at what happened before the failover, during the failover, and after the failover. A failover has two timestamps: the start time and the end time.
Next, I check the logs for events leading up to the failover, that is, I look for the reasons why the failover occurred.
This gives me an understanding of what happened and what can be done in the future to prevent similar circumstances (and consequently prevent a failover).
And where do we usually look? I look at:
- First, I check the Patroni logs.
- Next, I check the Postgres logs or the DCS logs, depending on what I found in the Patroni logs.
- System logs can also sometimes provide insight into what caused the failover.
What is my opinion on Patroni? I have a very positive view of Patroni. In my opinion, it is the best option available today. I know many other products: Stolon, Repmgr, Pg_auto_failover, PAF. Four tools. I have tried them all. I liked Patroni the most.
If I'm asked, "Do I recommend Patroni?" I will say yes, because I like Patroni. And I believe I have learned how to set it up properly.
If you’re interested in seeing what other issues can arise with Patroni, aside from the ones I mentioned, you can always visit the page on GitHub. There are many different stories and interesting problems discussed there. Ultimately, some bugs have been reported and resolved; it's interesting reading.
There are intriguing stories of people shooting themselves in the foot. Very educational. You read and understand that you shouldn't do that. I marked it down.
I would like to extend a big thank you to Zalando for developing this project, particularly to Alexander Kukushkin and Alexey Klyukin. Alexey Klyukin is one of the co-authors; he no longer works at Zalando, but these are the two individuals who began working on this product.
I believe that Patroni is an incredibly cool tool. I’m glad it exists; it’s interesting to work with. And a big thank you to all the contributors who write patches for Patroni. I hope that Patroni will become more mature, impressive, and functional with time. It is already functional, but I hope it gets even better. So if you plan to implement Patroni, don't hesitate. It’s a good solution that can be deployed and used.
That’s all. If you have any questions, please ask.
Questions
Thank you for the presentation! If we still need to examine it carefully after a failover, then why do we need an automated failover?
Because this is a new thing. We've only been working with it for a year. It's better to be cautious. We want to go in and see that everything has really worked as it should. This is a level of adult distrust – better to double-check and look.
For example, we checked in the morning, right?
Not in the morning, we usually find out about the auto-failover almost immediately. We receive notifications, we see that the auto-failover has occurred. We check in almost right away. But all these checks should be elevated to the monitoring level. When referring to Patroni via REST API, there is history. From history, you can view the timestamps when the failover occurred. Based on this, monitoring can be set up. You can check history to see how many events there have been. If there are more events, it means an auto-failover has occurred. We can go and check. Or our automation in monitoring verified that all replicas are in place, there is no lag, and everything is fine.
Thank you!
Thank you very much for the great talk! If we move the DCS cluster far away from the Postgres cluster, does this cluster also need periodic maintenance? What are the best practices regarding which pieces of the DCS cluster should be shut down, what should be done with them, etc.? How does the entire setup function in this process? And how to perform these tasks?
For one company, it was necessary to create a matrix of problems, what happens if any of the components or several components fail. Based on this matrix, we go through all the components sequentially and build scenarios in case of these components' failure. Accordingly, for each failure scenario, there can be an action plan for recovery. In the case of DCS, this is part of the standard infrastructure. The admin manages this, and we rely on the administrators who oversee it and their ability to fix it in case of an emergency. If DCS is not available, we deploy it, but we do not monitor it closely because we are not responsible for the infrastructure, but we provide recommendations on what and how to monitor.
So, is it correct that I need to disable Patroni, turn off the failover, and disable everything before doing anything with the hosts?
It depends on how many nodes we have in the DCS cluster. If there are many nodes and we disable only one of the nodes (a replica), the quorum remains in the cluster. And Patroni remains operational. Nothing gets triggered. If we have some complex operations that involve more nodes, the absence of which can break the quorum, then yes, it might make sense to pause Patroni. It has a corresponding command – patronictl pause, patronictl resume. We simply pause it, and the auto-failover does not trigger during this time. We perform maintenance on the DCS cluster, then resume and continue as usual.
Thank you very much!
Thank you very much for the presentation! How does the product team feel about the possibility of data loss?
The product teams don't care, but the team leads are worried.
What guarantees are there?
Guarantees are very difficult. There is a presentation by Alexander Kukushkin titled 'How to Calculate RPO and RTO', i.e., recovery time and how much data we can lose. I think we need to find those slides and study them. As far as I remember, there are specific steps on how to calculate these things. How many transactions we can lose, how much data we can lose. As an option, we can use synchronous replication at the Patroni level, but that’s a double-edged sword: we either have data reliability or lose speed. Synchronous replication is available, but it also does not guarantee 100% protection against data loss.
Aleksey, thank you for the excellent presentation! Do you have experience using Patroni for zero level protection? That is, in conjunction with synchronous standby? That’s the first question. And the second question. You have used different solutions. We used Repmgr, but without auto-failover, and we are now planning to implement auto-failover. We are considering Patroni as an alternative solution. What can you say about the advantages specifically compared to Repmgr?
The first question was about synchronous replicas. No one is using synchronous replication because everyone is afraid (Some clients already use it, and we haven't noticed any performance issues in principle – Speaker's note). However, we have established a rule that there must be a minimum of three nodes in a synchronous replication cluster, because if we have two nodes and either the master or the replica fails, Patroni will switch that node to Standalone mode to keep the application running. In this case, there is a risk of data loss.
Regarding the second question, we used Repmgr and still use it for some clients due to historical reasons. What can I say? In Patroni, auto-failover comes out of the box, while in Repmgr, auto-failover is an additional feature that needs to be enabled. You need to run the Repmgr daemon on each node, and then we can configure auto-failover.
Repmgr checks whether the Postgres nodes are alive. The Repmgr processes check the existence of each other; this is not a very efficient approach, as there can be complicated cases of network isolation where a large Repmgr cluster may split into several smaller ones and continue to operate. I haven't kept track of Repmgr for a while; they might have fixed this... or maybe not. However, the method of exporting cluster status information to DCS, as Stolon and Patroni do, is the most viable option.
Alexey, I have a question that might seem naive. In one of the first DCS examples, you moved from a local machine to a remote node. We understand that the network is a thing with its own peculiarities; it exists independently. What happens if, for some reason, the DCS cluster becomes unavailable? I won't discuss the reasons; they can vary widely: from the network team's misconfigurations to real issues.
I didn't say this out loud, but the DCS cluster must also be fault-tolerant, i.e., it should have an odd number of nodes so that a quorum can be reached. What happens if the DCS cluster becomes unavailable or cannot reach a quorum, e.g., due to a network split or node failure? In this case, the Patroni cluster switches to read-only mode. The Patroni cluster cannot determine the state of the cluster and what to do. It cannot communicate with DCS to save the new state of the cluster, so the whole cluster switches to read-only mode and waits for either manual intervention from the operator or for DCS to recover.
In simple terms, does DCS become as critical a service for us as the database itself?
Yes, indeed. In many modern companies, Service Discovery is an integral part of the infrastructure. It is implemented even before a database appears in the infrastructure. To put it simply, the infrastructure is launched, set up in the data center, and we immediately have Service Discovery in place. If it’s Consul, DNS can be built on it. If it’s Etcd, it might be part of a Kubernetes cluster where everything else will be deployed. I believe that Service Discovery is now an essential component of modern infrastructures. It's considered long before databases are even thought of.
Thank you!
Source: habr.com
